diff --git a/.agents/skills/writing-skills/SKILL.md b/.agents/skills/writing-skills/SKILL.md
new file mode 100644
index 000000000..c3b73d8b1
--- /dev/null
+++ b/.agents/skills/writing-skills/SKILL.md
@@ -0,0 +1,655 @@
+---
+name: writing-skills
+description: Use when creating new skills, editing existing skills, or verifying skills work before deployment
+---
+
+# Writing Skills
+
+## Overview
+
+**Writing skills IS Test-Driven Development applied to process documentation.**
+
+**Personal skills live in agent-specific directories (`~/.claude/skills` for Claude Code, `~/.agents/skills/` for Codex)**
+
+You write test cases (pressure scenarios with subagents), watch them fail (baseline behavior), write the skill (documentation), watch tests pass (agents comply), and refactor (close loopholes).
+
+**Core principle:** If you didn't watch an agent fail without the skill, you don't know if the skill teaches the right thing.
+
+**REQUIRED BACKGROUND:** You MUST understand superpowers:test-driven-development before using this skill. That skill defines the fundamental RED-GREEN-REFACTOR cycle. This skill adapts TDD to documentation.
+
+**Official guidance:** For Anthropic's official skill authoring best practices, see anthropic-best-practices.md. This document provides additional patterns and guidelines that complement the TDD-focused approach in this skill.
+
+## What is a Skill?
+
+A **skill** is a reference guide for proven techniques, patterns, or tools. Skills help future Claude instances find and apply effective approaches.
+
+**Skills are:** Reusable techniques, patterns, tools, reference guides
+
+**Skills are NOT:** Narratives about how you solved a problem once
+
+## TDD Mapping for Skills
+
+| TDD Concept | Skill Creation |
+|-------------|----------------|
+| **Test case** | Pressure scenario with subagent |
+| **Production code** | Skill document (SKILL.md) |
+| **Test fails (RED)** | Agent violates rule without skill (baseline) |
+| **Test passes (GREEN)** | Agent complies with skill present |
+| **Refactor** | Close loopholes while maintaining compliance |
+| **Write test first** | Run baseline scenario BEFORE writing skill |
+| **Watch it fail** | Document exact rationalizations agent uses |
+| **Minimal code** | Write skill addressing those specific violations |
+| **Watch it pass** | Verify agent now complies |
+| **Refactor cycle** | Find new rationalizations → plug → re-verify |
+
+The entire skill creation process follows RED-GREEN-REFACTOR.
+
+## When to Create a Skill
+
+**Create when:**
+- Technique wasn't intuitively obvious to you
+- You'd reference this again across projects
+- Pattern applies broadly (not project-specific)
+- Others would benefit
+
+**Don't create for:**
+- One-off solutions
+- Standard practices well-documented elsewhere
+- Project-specific conventions (put in CLAUDE.md)
+- Mechanical constraints (if it's enforceable with regex/validation, automate it—save documentation for judgment calls)
+
+## Skill Types
+
+### Technique
+Concrete method with steps to follow (condition-based-waiting, root-cause-tracing)
+
+### Pattern
+Way of thinking about problems (flatten-with-flags, test-invariants)
+
+### Reference
+API docs, syntax guides, tool documentation (office docs)
+
+## Directory Structure
+
+
+```
+skills/
+ skill-name/
+ SKILL.md # Main reference (required)
+ supporting-file.* # Only if needed
+```
+
+**Flat namespace** - all skills in one searchable namespace
+
+**Separate files for:**
+1. **Heavy reference** (100+ lines) - API docs, comprehensive syntax
+2. **Reusable tools** - Scripts, utilities, templates
+
+**Keep inline:**
+- Principles and concepts
+- Code patterns (< 50 lines)
+- Everything else
+
+## SKILL.md Structure
+
+**Frontmatter (YAML):**
+- Two required fields: `name` and `description` (see [agentskills.io/specification](https://agentskills.io/specification) for all supported fields)
+- Max 1024 characters total
+- `name`: Use letters, numbers, and hyphens only (no parentheses, special chars)
+- `description`: Third-person, describes ONLY when to use (NOT what it does)
+ - Start with "Use when..." to focus on triggering conditions
+ - Include specific symptoms, situations, and contexts
+ - **NEVER summarize the skill's process or workflow** (see CSO section for why)
+ - Keep under 500 characters if possible
+
+```markdown
+---
+name: Skill-Name-With-Hyphens
+description: Use when [specific triggering conditions and symptoms]
+---
+
+# Skill Name
+
+## Overview
+What is this? Core principle in 1-2 sentences.
+
+## When to Use
+[Small inline flowchart IF decision non-obvious]
+
+Bullet list with SYMPTOMS and use cases
+When NOT to use
+
+## Core Pattern (for techniques/patterns)
+Before/after code comparison
+
+## Quick Reference
+Table or bullets for scanning common operations
+
+## Implementation
+Inline code for simple patterns
+Link to file for heavy reference or reusable tools
+
+## Common Mistakes
+What goes wrong + fixes
+
+## Real-World Impact (optional)
+Concrete results
+```
+
+
+## Claude Search Optimization (CSO)
+
+**Critical for discovery:** Future Claude needs to FIND your skill
+
+### 1. Rich Description Field
+
+**Purpose:** Claude reads description to decide which skills to load for a given task. Make it answer: "Should I read this skill right now?"
+
+**Format:** Start with "Use when..." to focus on triggering conditions
+
+**CRITICAL: Description = When to Use, NOT What the Skill Does**
+
+The description should ONLY describe triggering conditions. Do NOT summarize the skill's process or workflow in the description.
+
+**Why this matters:** Testing revealed that when a description summarizes the skill's workflow, Claude may follow the description instead of reading the full skill content. A description saying "code review between tasks" caused Claude to do ONE review, even though the skill's flowchart clearly showed TWO reviews (spec compliance then code quality).
+
+When the description was changed to just "Use when executing implementation plans with independent tasks" (no workflow summary), Claude correctly read the flowchart and followed the two-stage review process.
+
+**The trap:** Descriptions that summarize workflow create a shortcut Claude will take. The skill body becomes documentation Claude skips.
+
+```yaml
+# ❌ BAD: Summarizes workflow - Claude may follow this instead of reading skill
+description: Use when executing plans - dispatches subagent per task with code review between tasks
+
+# ❌ BAD: Too much process detail
+description: Use for TDD - write test first, watch it fail, write minimal code, refactor
+
+# ✅ GOOD: Just triggering conditions, no workflow summary
+description: Use when executing implementation plans with independent tasks in the current session
+
+# ✅ GOOD: Triggering conditions only
+description: Use when implementing any feature or bugfix, before writing implementation code
+```
+
+**Content:**
+- Use concrete triggers, symptoms, and situations that signal this skill applies
+- Describe the *problem* (race conditions, inconsistent behavior) not *language-specific symptoms* (setTimeout, sleep)
+- Keep triggers technology-agnostic unless the skill itself is technology-specific
+- If skill is technology-specific, make that explicit in the trigger
+- Write in third person (injected into system prompt)
+- **NEVER summarize the skill's process or workflow**
+
+```yaml
+# ❌ BAD: Too abstract, vague, doesn't include when to use
+description: For async testing
+
+# ❌ BAD: First person
+description: I can help you with async tests when they're flaky
+
+# ❌ BAD: Mentions technology but skill isn't specific to it
+description: Use when tests use setTimeout/sleep and are flaky
+
+# ✅ GOOD: Starts with "Use when", describes problem, no workflow
+description: Use when tests have race conditions, timing dependencies, or pass/fail inconsistently
+
+# ✅ GOOD: Technology-specific skill with explicit trigger
+description: Use when using React Router and handling authentication redirects
+```
+
+### 2. Keyword Coverage
+
+Use words Claude would search for:
+- Error messages: "Hook timed out", "ENOTEMPTY", "race condition"
+- Symptoms: "flaky", "hanging", "zombie", "pollution"
+- Synonyms: "timeout/hang/freeze", "cleanup/teardown/afterEach"
+- Tools: Actual commands, library names, file types
+
+### 3. Descriptive Naming
+
+**Use active voice, verb-first:**
+- ✅ `creating-skills` not `skill-creation`
+- ✅ `condition-based-waiting` not `async-test-helpers`
+
+### 4. Token Efficiency (Critical)
+
+**Problem:** getting-started and frequently-referenced skills load into EVERY conversation. Every token counts.
+
+**Target word counts:**
+- getting-started workflows: <150 words each
+- Frequently-loaded skills: <200 words total
+- Other skills: <500 words (still be concise)
+
+**Techniques:**
+
+**Move details to tool help:**
+```bash
+# ❌ BAD: Document all flags in SKILL.md
+search-conversations supports --text, --both, --after DATE, --before DATE, --limit N
+
+# ✅ GOOD: Reference --help
+search-conversations supports multiple modes and filters. Run --help for details.
+```
+
+**Use cross-references:**
+```markdown
+# ❌ BAD: Repeat workflow details
+When searching, dispatch subagent with template...
+[20 lines of repeated instructions]
+
+# ✅ GOOD: Reference other skill
+Always use subagents (50-100x context savings). REQUIRED: Use [other-skill-name] for workflow.
+```
+
+**Compress examples:**
+```markdown
+# ❌ BAD: Verbose example (42 words)
+your human partner: "How did we handle authentication errors in React Router before?"
+You: I'll search past conversations for React Router authentication patterns.
+[Dispatch subagent with search query: "React Router authentication error handling 401"]
+
+# ✅ GOOD: Minimal example (20 words)
+Partner: "How did we handle auth errors in React Router?"
+You: Searching...
+[Dispatch subagent → synthesis]
+```
+
+**Eliminate redundancy:**
+- Don't repeat what's in cross-referenced skills
+- Don't explain what's obvious from command
+- Don't include multiple examples of same pattern
+
+**Verification:**
+```bash
+wc -w skills/path/SKILL.md
+# getting-started workflows: aim for <150 each
+# Other frequently-loaded: aim for <200 total
+```
+
+**Name by what you DO or core insight:**
+- ✅ `condition-based-waiting` > `async-test-helpers`
+- ✅ `using-skills` not `skill-usage`
+- ✅ `flatten-with-flags` > `data-structure-refactoring`
+- ✅ `root-cause-tracing` > `debugging-techniques`
+
+**Gerunds (-ing) work well for processes:**
+- `creating-skills`, `testing-skills`, `debugging-with-logs`
+- Active, describes the action you're taking
+
+### 4. Cross-Referencing Other Skills
+
+**When writing documentation that references other skills:**
+
+Use skill name only, with explicit requirement markers:
+- ✅ Good: `**REQUIRED SUB-SKILL:** Use superpowers:test-driven-development`
+- ✅ Good: `**REQUIRED BACKGROUND:** You MUST understand superpowers:systematic-debugging`
+- ❌ Bad: `See skills/testing/test-driven-development` (unclear if required)
+- ❌ Bad: `@skills/testing/test-driven-development/SKILL.md` (force-loads, burns context)
+
+**Why no @ links:** `@` syntax force-loads files immediately, consuming 200k+ context before you need them.
+
+## Flowchart Usage
+
+```dot
+digraph when_flowchart {
+ "Need to show information?" [shape=diamond];
+ "Decision where I might go wrong?" [shape=diamond];
+ "Use markdown" [shape=box];
+ "Small inline flowchart" [shape=box];
+
+ "Need to show information?" -> "Decision where I might go wrong?" [label="yes"];
+ "Decision where I might go wrong?" -> "Small inline flowchart" [label="yes"];
+ "Decision where I might go wrong?" -> "Use markdown" [label="no"];
+}
+```
+
+**Use flowcharts ONLY for:**
+- Non-obvious decision points
+- Process loops where you might stop too early
+- "When to use A vs B" decisions
+
+**Never use flowcharts for:**
+- Reference material → Tables, lists
+- Code examples → Markdown blocks
+- Linear instructions → Numbered lists
+- Labels without semantic meaning (step1, helper2)
+
+See @graphviz-conventions.dot for graphviz style rules.
+
+**Visualizing for your human partner:** Use `render-graphs.js` in this directory to render a skill's flowcharts to SVG:
+```bash
+./render-graphs.js ../some-skill # Each diagram separately
+./render-graphs.js ../some-skill --combine # All diagrams in one SVG
+```
+
+## Code Examples
+
+**One excellent example beats many mediocre ones**
+
+Choose most relevant language:
+- Testing techniques → TypeScript/JavaScript
+- System debugging → Shell/Python
+- Data processing → Python
+
+**Good example:**
+- Complete and runnable
+- Well-commented explaining WHY
+- From real scenario
+- Shows pattern clearly
+- Ready to adapt (not generic template)
+
+**Don't:**
+- Implement in 5+ languages
+- Create fill-in-the-blank templates
+- Write contrived examples
+
+You're good at porting - one great example is enough.
+
+## File Organization
+
+### Self-Contained Skill
+```
+defense-in-depth/
+ SKILL.md # Everything inline
+```
+When: All content fits, no heavy reference needed
+
+### Skill with Reusable Tool
+```
+condition-based-waiting/
+ SKILL.md # Overview + patterns
+ example.ts # Working helpers to adapt
+```
+When: Tool is reusable code, not just narrative
+
+### Skill with Heavy Reference
+```
+pptx/
+ SKILL.md # Overview + workflows
+ pptxgenjs.md # 600 lines API reference
+ ooxml.md # 500 lines XML structure
+ scripts/ # Executable tools
+```
+When: Reference material too large for inline
+
+## The Iron Law (Same as TDD)
+
+```
+NO SKILL WITHOUT A FAILING TEST FIRST
+```
+
+This applies to NEW skills AND EDITS to existing skills.
+
+Write skill before testing? Delete it. Start over.
+Edit skill without testing? Same violation.
+
+**No exceptions:**
+- Not for "simple additions"
+- Not for "just adding a section"
+- Not for "documentation updates"
+- Don't keep untested changes as "reference"
+- Don't "adapt" while running tests
+- Delete means delete
+
+**REQUIRED BACKGROUND:** The superpowers:test-driven-development skill explains why this matters. Same principles apply to documentation.
+
+## Testing All Skill Types
+
+Different skill types need different test approaches:
+
+### Discipline-Enforcing Skills (rules/requirements)
+
+**Examples:** TDD, verification-before-completion, designing-before-coding
+
+**Test with:**
+- Academic questions: Do they understand the rules?
+- Pressure scenarios: Do they comply under stress?
+- Multiple pressures combined: time + sunk cost + exhaustion
+- Identify rationalizations and add explicit counters
+
+**Success criteria:** Agent follows rule under maximum pressure
+
+### Technique Skills (how-to guides)
+
+**Examples:** condition-based-waiting, root-cause-tracing, defensive-programming
+
+**Test with:**
+- Application scenarios: Can they apply the technique correctly?
+- Variation scenarios: Do they handle edge cases?
+- Missing information tests: Do instructions have gaps?
+
+**Success criteria:** Agent successfully applies technique to new scenario
+
+### Pattern Skills (mental models)
+
+**Examples:** reducing-complexity, information-hiding concepts
+
+**Test with:**
+- Recognition scenarios: Do they recognize when pattern applies?
+- Application scenarios: Can they use the mental model?
+- Counter-examples: Do they know when NOT to apply?
+
+**Success criteria:** Agent correctly identifies when/how to apply pattern
+
+### Reference Skills (documentation/APIs)
+
+**Examples:** API documentation, command references, library guides
+
+**Test with:**
+- Retrieval scenarios: Can they find the right information?
+- Application scenarios: Can they use what they found correctly?
+- Gap testing: Are common use cases covered?
+
+**Success criteria:** Agent finds and correctly applies reference information
+
+## Common Rationalizations for Skipping Testing
+
+| Excuse | Reality |
+|--------|---------|
+| "Skill is obviously clear" | Clear to you ≠ clear to other agents. Test it. |
+| "It's just a reference" | References can have gaps, unclear sections. Test retrieval. |
+| "Testing is overkill" | Untested skills have issues. Always. 15 min testing saves hours. |
+| "I'll test if problems emerge" | Problems = agents can't use skill. Test BEFORE deploying. |
+| "Too tedious to test" | Testing is less tedious than debugging bad skill in production. |
+| "I'm confident it's good" | Overconfidence guarantees issues. Test anyway. |
+| "Academic review is enough" | Reading ≠ using. Test application scenarios. |
+| "No time to test" | Deploying untested skill wastes more time fixing it later. |
+
+**All of these mean: Test before deploying. No exceptions.**
+
+## Bulletproofing Skills Against Rationalization
+
+Skills that enforce discipline (like TDD) need to resist rationalization. Agents are smart and will find loopholes when under pressure.
+
+**Psychology note:** Understanding WHY persuasion techniques work helps you apply them systematically. See persuasion-principles.md for research foundation (Cialdini, 2021; Meincke et al., 2025) on authority, commitment, scarcity, social proof, and unity principles.
+
+### Close Every Loophole Explicitly
+
+Don't just state the rule - forbid specific workarounds:
+
+
+```markdown
+Write code before test? Delete it.
+```
+
+
+
+```markdown
+Write code before test? Delete it. Start over.
+
+**No exceptions:**
+- Don't keep it as "reference"
+- Don't "adapt" it while writing tests
+- Don't look at it
+- Delete means delete
+```
+
+
+### Address "Spirit vs Letter" Arguments
+
+Add foundational principle early:
+
+```markdown
+**Violating the letter of the rules is violating the spirit of the rules.**
+```
+
+This cuts off entire class of "I'm following the spirit" rationalizations.
+
+### Build Rationalization Table
+
+Capture rationalizations from baseline testing (see Testing section below). Every excuse agents make goes in the table:
+
+```markdown
+| Excuse | Reality |
+|--------|---------|
+| "Too simple to test" | Simple code breaks. Test takes 30 seconds. |
+| "I'll test after" | Tests passing immediately prove nothing. |
+| "Tests after achieve same goals" | Tests-after = "what does this do?" Tests-first = "what should this do?" |
+```
+
+### Create Red Flags List
+
+Make it easy for agents to self-check when rationalizing:
+
+```markdown
+## Red Flags - STOP and Start Over
+
+- Code before test
+- "I already manually tested it"
+- "Tests after achieve the same purpose"
+- "It's about spirit not ritual"
+- "This is different because..."
+
+**All of these mean: Delete code. Start over with TDD.**
+```
+
+### Update CSO for Violation Symptoms
+
+Add to description: symptoms of when you're ABOUT to violate the rule:
+
+```yaml
+description: use when implementing any feature or bugfix, before writing implementation code
+```
+
+## RED-GREEN-REFACTOR for Skills
+
+Follow the TDD cycle:
+
+### RED: Write Failing Test (Baseline)
+
+Run pressure scenario with subagent WITHOUT the skill. Document exact behavior:
+- What choices did they make?
+- What rationalizations did they use (verbatim)?
+- Which pressures triggered violations?
+
+This is "watch the test fail" - you must see what agents naturally do before writing the skill.
+
+### GREEN: Write Minimal Skill
+
+Write skill that addresses those specific rationalizations. Don't add extra content for hypothetical cases.
+
+Run same scenarios WITH skill. Agent should now comply.
+
+### REFACTOR: Close Loopholes
+
+Agent found new rationalization? Add explicit counter. Re-test until bulletproof.
+
+**Testing methodology:** See @testing-skills-with-subagents.md for the complete testing methodology:
+- How to write pressure scenarios
+- Pressure types (time, sunk cost, authority, exhaustion)
+- Plugging holes systematically
+- Meta-testing techniques
+
+## Anti-Patterns
+
+### ❌ Narrative Example
+"In session 2025-10-03, we found empty projectDir caused..."
+**Why bad:** Too specific, not reusable
+
+### ❌ Multi-Language Dilution
+example-js.js, example-py.py, example-go.go
+**Why bad:** Mediocre quality, maintenance burden
+
+### ❌ Code in Flowcharts
+```dot
+step1 [label="import fs"];
+step2 [label="read file"];
+```
+**Why bad:** Can't copy-paste, hard to read
+
+### ❌ Generic Labels
+helper1, helper2, step3, pattern4
+**Why bad:** Labels should have semantic meaning
+
+## STOP: Before Moving to Next Skill
+
+**After writing ANY skill, you MUST STOP and complete the deployment process.**
+
+**Do NOT:**
+- Create multiple skills in batch without testing each
+- Move to next skill before current one is verified
+- Skip testing because "batching is more efficient"
+
+**The deployment checklist below is MANDATORY for EACH skill.**
+
+Deploying untested skills = deploying untested code. It's a violation of quality standards.
+
+## Skill Creation Checklist (TDD Adapted)
+
+**IMPORTANT: Use TodoWrite to create todos for EACH checklist item below.**
+
+**RED Phase - Write Failing Test:**
+- [ ] Create pressure scenarios (3+ combined pressures for discipline skills)
+- [ ] Run scenarios WITHOUT skill - document baseline behavior verbatim
+- [ ] Identify patterns in rationalizations/failures
+
+**GREEN Phase - Write Minimal Skill:**
+- [ ] Name uses only letters, numbers, hyphens (no parentheses/special chars)
+- [ ] YAML frontmatter with required `name` and `description` fields (max 1024 chars; see [spec](https://agentskills.io/specification))
+- [ ] Description starts with "Use when..." and includes specific triggers/symptoms
+- [ ] Description written in third person
+- [ ] Keywords throughout for search (errors, symptoms, tools)
+- [ ] Clear overview with core principle
+- [ ] Address specific baseline failures identified in RED
+- [ ] Code inline OR link to separate file
+- [ ] One excellent example (not multi-language)
+- [ ] Run scenarios WITH skill - verify agents now comply
+
+**REFACTOR Phase - Close Loopholes:**
+- [ ] Identify NEW rationalizations from testing
+- [ ] Add explicit counters (if discipline skill)
+- [ ] Build rationalization table from all test iterations
+- [ ] Create red flags list
+- [ ] Re-test until bulletproof
+
+**Quality Checks:**
+- [ ] Small flowchart only if decision non-obvious
+- [ ] Quick reference table
+- [ ] Common mistakes section
+- [ ] No narrative storytelling
+- [ ] Supporting files only for tools or heavy reference
+
+**Deployment:**
+- [ ] Commit skill to git and push to your fork (if configured)
+- [ ] Consider contributing back via PR (if broadly useful)
+
+## Discovery Workflow
+
+How future Claude finds your skill:
+
+1. **Encounters problem** ("tests are flaky")
+3. **Finds SKILL** (description matches)
+4. **Scans overview** (is this relevant?)
+5. **Reads patterns** (quick reference table)
+6. **Loads example** (only when implementing)
+
+**Optimize for this flow** - put searchable terms early and often.
+
+## The Bottom Line
+
+**Creating skills IS TDD for process documentation.**
+
+Same Iron Law: No skill without failing test first.
+Same cycle: RED (baseline) → GREEN (write skill) → REFACTOR (close loopholes).
+Same benefits: Better quality, fewer surprises, bulletproof results.
+
+If you follow TDD for code, follow it for skills. It's the same discipline applied to documentation.
diff --git a/.agents/skills/writing-skills/anthropic-best-practices.md b/.agents/skills/writing-skills/anthropic-best-practices.md
new file mode 100644
index 000000000..9f3f6ecfd
--- /dev/null
+++ b/.agents/skills/writing-skills/anthropic-best-practices.md
@@ -0,0 +1,1150 @@
+# Skill authoring best practices
+
+> Learn how to write effective Skills that Claude can discover and use successfully.
+
+Good Skills are concise, well-structured, and tested with real usage. This guide provides practical authoring decisions to help you write Skills that Claude can discover and use effectively.
+
+For conceptual background on how Skills work, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview).
+
+## Core principles
+
+### Concise is key
+
+The [context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) is a public good. Your Skill shares the context window with everything else Claude needs to know, including:
+
+* The system prompt
+* Conversation history
+* Other Skills' metadata
+* Your actual request
+
+Not every token in your Skill has an immediate cost. At startup, only the metadata (name and description) from all Skills is pre-loaded. Claude reads SKILL.md only when the Skill becomes relevant, and reads additional files only as needed. However, being concise in SKILL.md still matters: once Claude loads it, every token competes with conversation history and other context.
+
+**Default assumption**: Claude is already very smart
+
+Only add context Claude doesn't already have. Challenge each piece of information:
+
+* "Does Claude really need this explanation?"
+* "Can I assume Claude knows this?"
+* "Does this paragraph justify its token cost?"
+
+**Good example: Concise** (approximately 50 tokens):
+
+````markdown theme={null}
+## Extract PDF text
+
+Use pdfplumber for text extraction:
+
+```python
+import pdfplumber
+
+with pdfplumber.open("file.pdf") as pdf:
+ text = pdf.pages[0].extract_text()
+```
+````
+
+**Bad example: Too verbose** (approximately 150 tokens):
+
+```markdown theme={null}
+## Extract PDF text
+
+PDF (Portable Document Format) files are a common file format that contains
+text, images, and other content. To extract text from a PDF, you'll need to
+use a library. There are many libraries available for PDF processing, but we
+recommend pdfplumber because it's easy to use and handles most cases well.
+First, you'll need to install it using pip. Then you can use the code below...
+```
+
+The concise version assumes Claude knows what PDFs are and how libraries work.
+
+### Set appropriate degrees of freedom
+
+Match the level of specificity to the task's fragility and variability.
+
+**High freedom** (text-based instructions):
+
+Use when:
+
+* Multiple approaches are valid
+* Decisions depend on context
+* Heuristics guide the approach
+
+Example:
+
+```markdown theme={null}
+## Code review process
+
+1. Analyze the code structure and organization
+2. Check for potential bugs or edge cases
+3. Suggest improvements for readability and maintainability
+4. Verify adherence to project conventions
+```
+
+**Medium freedom** (pseudocode or scripts with parameters):
+
+Use when:
+
+* A preferred pattern exists
+* Some variation is acceptable
+* Configuration affects behavior
+
+Example:
+
+````markdown theme={null}
+## Generate report
+
+Use this template and customize as needed:
+
+```python
+def generate_report(data, format="markdown", include_charts=True):
+ # Process data
+ # Generate output in specified format
+ # Optionally include visualizations
+```
+````
+
+**Low freedom** (specific scripts, few or no parameters):
+
+Use when:
+
+* Operations are fragile and error-prone
+* Consistency is critical
+* A specific sequence must be followed
+
+Example:
+
+````markdown theme={null}
+## Database migration
+
+Run exactly this script:
+
+```bash
+python scripts/migrate.py --verify --backup
+```
+
+Do not modify the command or add additional flags.
+````
+
+**Analogy**: Think of Claude as a robot exploring a path:
+
+* **Narrow bridge with cliffs on both sides**: There's only one safe way forward. Provide specific guardrails and exact instructions (low freedom). Example: database migrations that must run in exact sequence.
+* **Open field with no hazards**: Many paths lead to success. Give general direction and trust Claude to find the best route (high freedom). Example: code reviews where context determines the best approach.
+
+### Test with all models you plan to use
+
+Skills act as additions to models, so effectiveness depends on the underlying model. Test your Skill with all the models you plan to use it with.
+
+**Testing considerations by model**:
+
+* **Claude Haiku** (fast, economical): Does the Skill provide enough guidance?
+* **Claude Sonnet** (balanced): Is the Skill clear and efficient?
+* **Claude Opus** (powerful reasoning): Does the Skill avoid over-explaining?
+
+What works perfectly for Opus might need more detail for Haiku. If you plan to use your Skill across multiple models, aim for instructions that work well with all of them.
+
+## Skill structure
+
+
+ **YAML Frontmatter**: The SKILL.md frontmatter requires two fields:
+
+ * `name` - Human-readable name of the Skill (64 characters maximum)
+ * `description` - One-line description of what the Skill does and when to use it (1024 characters maximum)
+
+ For complete Skill structure details, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#skill-structure).
+
+
+### Naming conventions
+
+Use consistent naming patterns to make Skills easier to reference and discuss. We recommend using **gerund form** (verb + -ing) for Skill names, as this clearly describes the activity or capability the Skill provides.
+
+**Good naming examples (gerund form)**:
+
+* "Processing PDFs"
+* "Analyzing spreadsheets"
+* "Managing databases"
+* "Testing code"
+* "Writing documentation"
+
+**Acceptable alternatives**:
+
+* Noun phrases: "PDF Processing", "Spreadsheet Analysis"
+* Action-oriented: "Process PDFs", "Analyze Spreadsheets"
+
+**Avoid**:
+
+* Vague names: "Helper", "Utils", "Tools"
+* Overly generic: "Documents", "Data", "Files"
+* Inconsistent patterns within your skill collection
+
+Consistent naming makes it easier to:
+
+* Reference Skills in documentation and conversations
+* Understand what a Skill does at a glance
+* Organize and search through multiple Skills
+* Maintain a professional, cohesive skill library
+
+### Writing effective descriptions
+
+The `description` field enables Skill discovery and should include both what the Skill does and when to use it.
+
+
+ **Always write in third person**. The description is injected into the system prompt, and inconsistent point-of-view can cause discovery problems.
+
+ * **Good:** "Processes Excel files and generates reports"
+ * **Avoid:** "I can help you process Excel files"
+ * **Avoid:** "You can use this to process Excel files"
+
+
+**Be specific and include key terms**. Include both what the Skill does and specific triggers/contexts for when to use it.
+
+Each Skill has exactly one description field. The description is critical for skill selection: Claude uses it to choose the right Skill from potentially 100+ available Skills. Your description must provide enough detail for Claude to know when to select this Skill, while the rest of SKILL.md provides the implementation details.
+
+Effective examples:
+
+**PDF Processing skill:**
+
+```yaml theme={null}
+description: Extract text and tables from PDF files, fill forms, merge documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
+```
+
+**Excel Analysis skill:**
+
+```yaml theme={null}
+description: Analyze Excel spreadsheets, create pivot tables, generate charts. Use when analyzing Excel files, spreadsheets, tabular data, or .xlsx files.
+```
+
+**Git Commit Helper skill:**
+
+```yaml theme={null}
+description: Generate descriptive commit messages by analyzing git diffs. Use when the user asks for help writing commit messages or reviewing staged changes.
+```
+
+Avoid vague descriptions like these:
+
+```yaml theme={null}
+description: Helps with documents
+```
+
+```yaml theme={null}
+description: Processes data
+```
+
+```yaml theme={null}
+description: Does stuff with files
+```
+
+### Progressive disclosure patterns
+
+SKILL.md serves as an overview that points Claude to detailed materials as needed, like a table of contents in an onboarding guide. For an explanation of how progressive disclosure works, see [How Skills work](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work) in the overview.
+
+**Practical guidance:**
+
+* Keep SKILL.md body under 500 lines for optimal performance
+* Split content into separate files when approaching this limit
+* Use the patterns below to organize instructions, code, and resources effectively
+
+#### Visual overview: From simple to complex
+
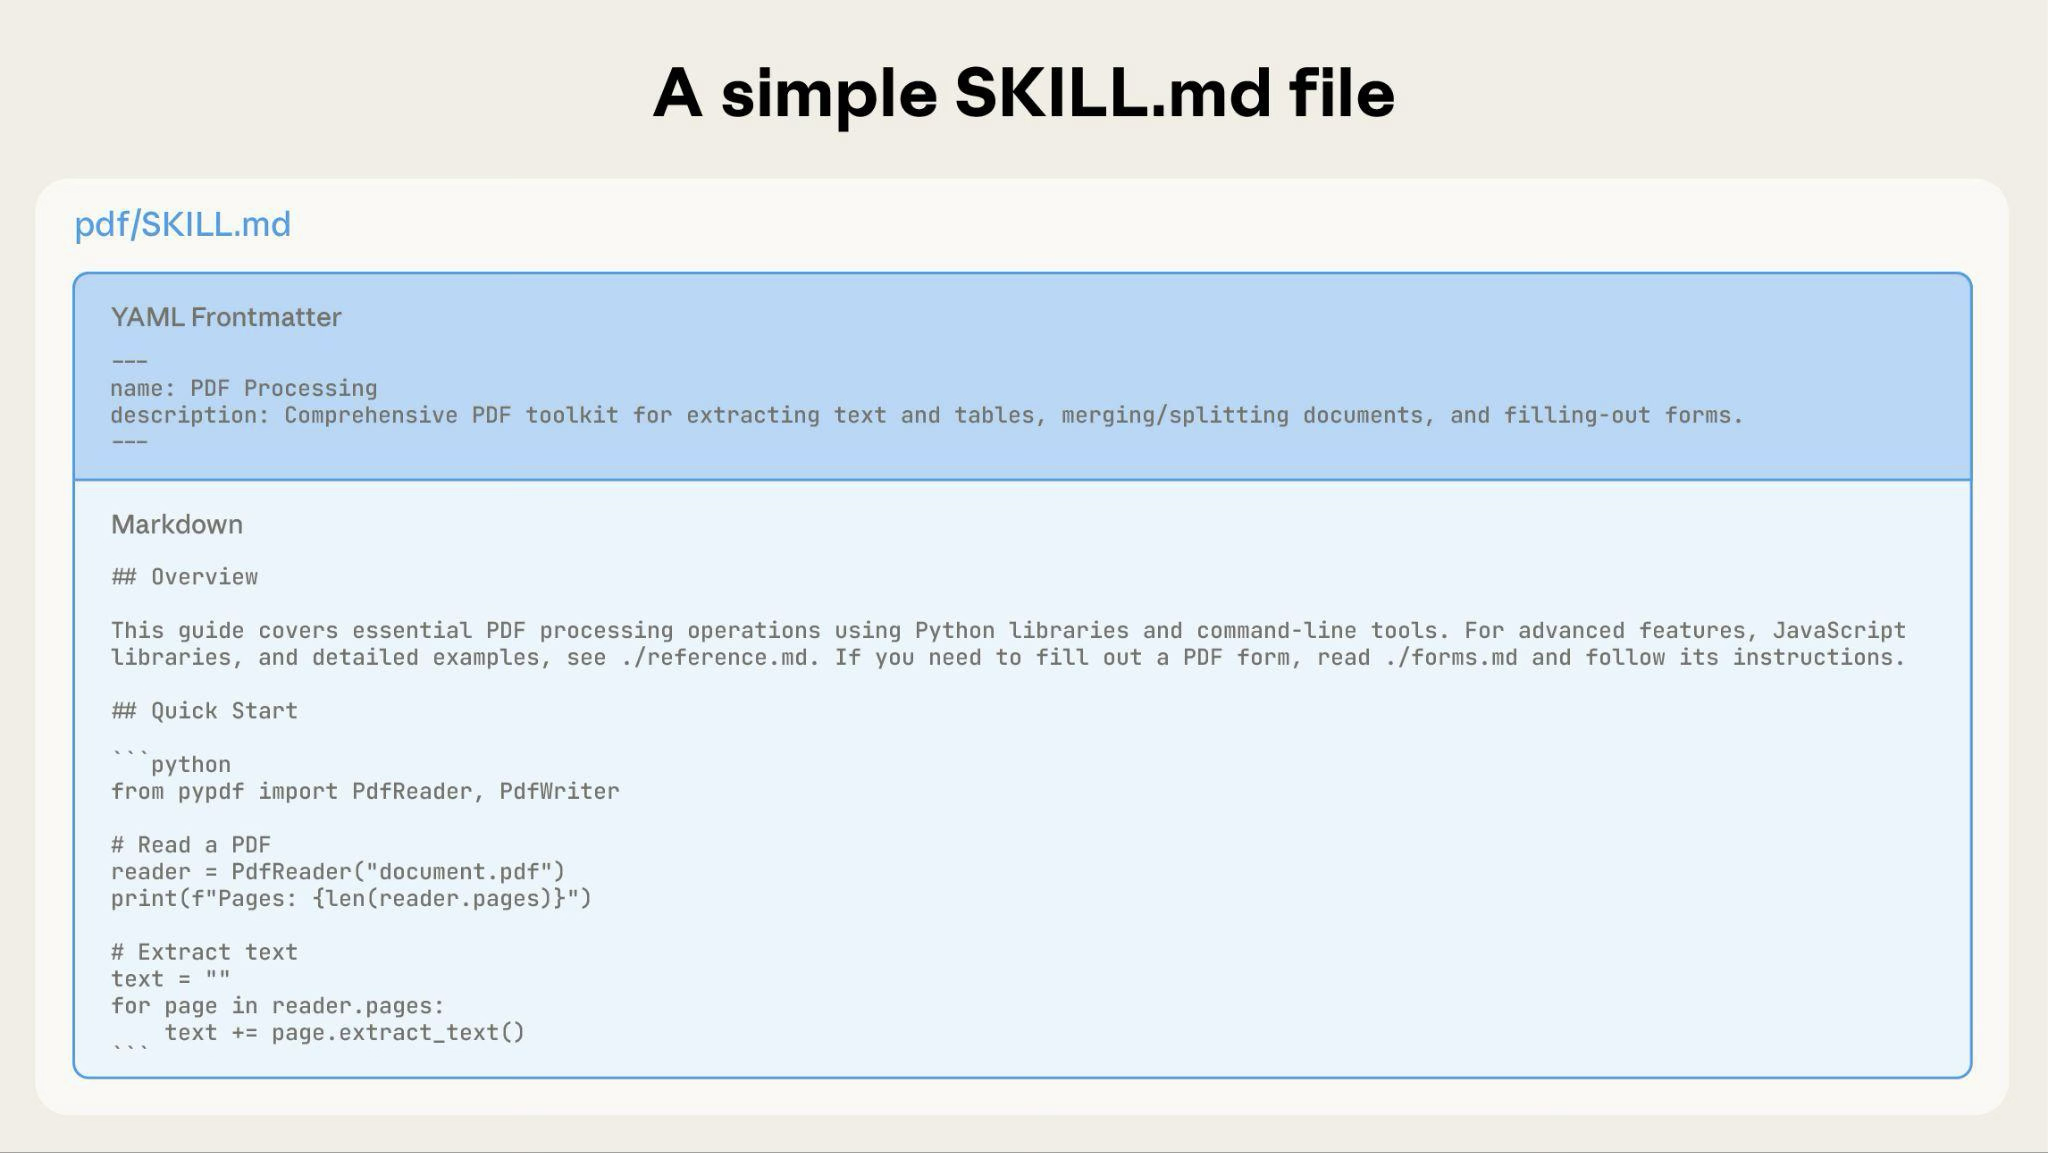
+A basic Skill starts with just a SKILL.md file containing metadata and instructions:
+
+ +
+As your Skill grows, you can bundle additional content that Claude loads only when needed:
+
+
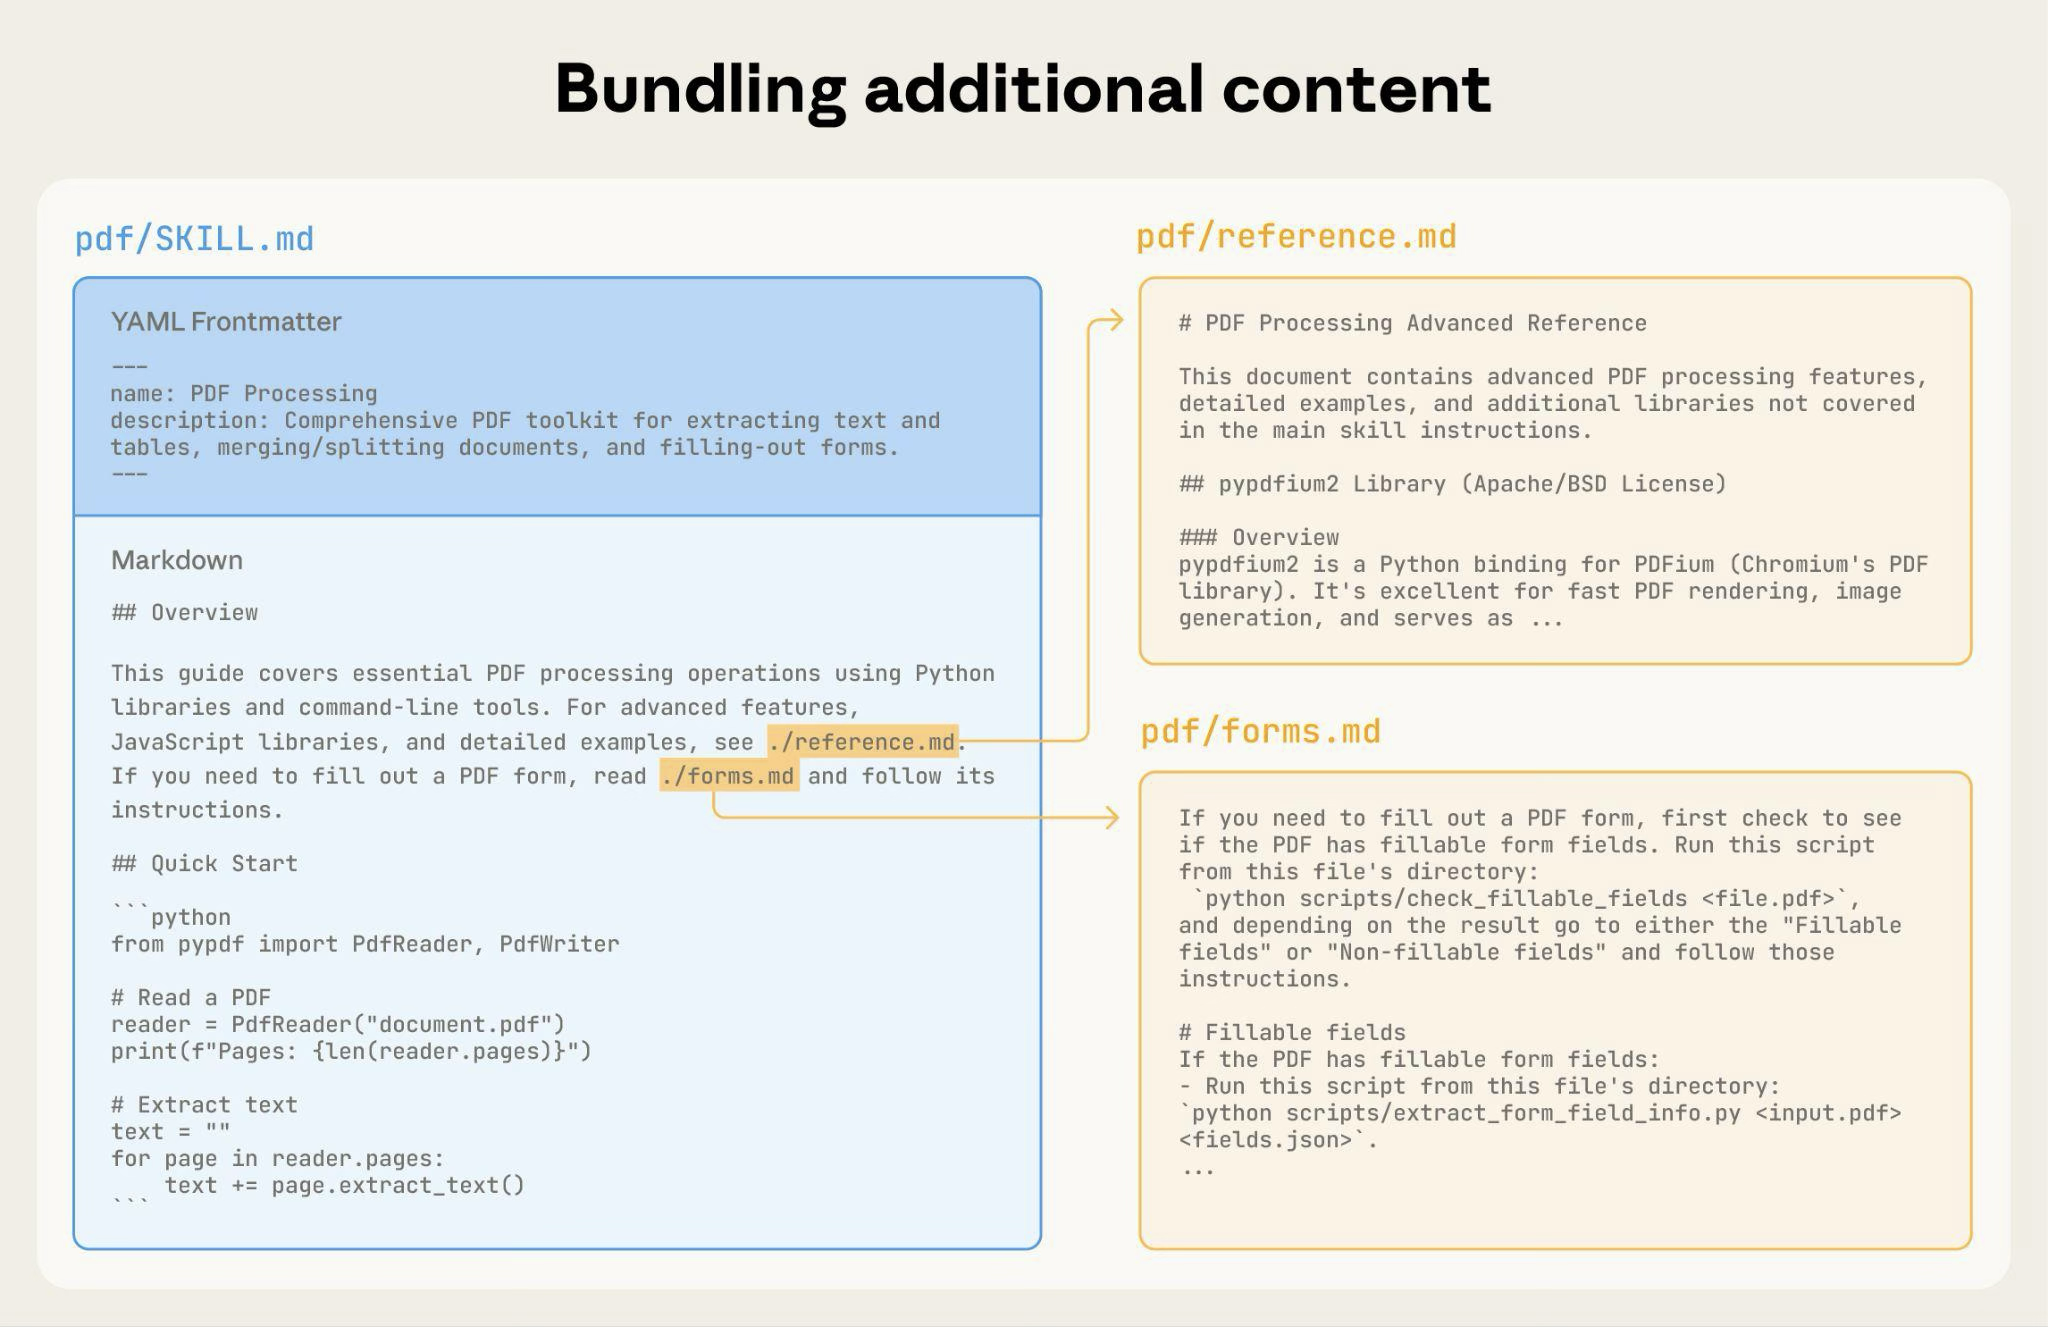 +
+The complete Skill directory structure might look like this:
+
+```
+pdf/
+├── SKILL.md # Main instructions (loaded when triggered)
+├── FORMS.md # Form-filling guide (loaded as needed)
+├── reference.md # API reference (loaded as needed)
+├── examples.md # Usage examples (loaded as needed)
+└── scripts/
+ ├── analyze_form.py # Utility script (executed, not loaded)
+ ├── fill_form.py # Form filling script
+ └── validate.py # Validation script
+```
+
+#### Pattern 1: High-level guide with references
+
+````markdown theme={null}
+---
+name: PDF Processing
+description: Extracts text and tables from PDF files, fills forms, and merges documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
+---
+
+# PDF Processing
+
+## Quick start
+
+Extract text with pdfplumber:
+```python
+import pdfplumber
+with pdfplumber.open("file.pdf") as pdf:
+ text = pdf.pages[0].extract_text()
+```
+
+## Advanced features
+
+**Form filling**: See [FORMS.md](FORMS.md) for complete guide
+**API reference**: See [REFERENCE.md](REFERENCE.md) for all methods
+**Examples**: See [EXAMPLES.md](EXAMPLES.md) for common patterns
+````
+
+Claude loads FORMS.md, REFERENCE.md, or EXAMPLES.md only when needed.
+
+#### Pattern 2: Domain-specific organization
+
+For Skills with multiple domains, organize content by domain to avoid loading irrelevant context. When a user asks about sales metrics, Claude only needs to read sales-related schemas, not finance or marketing data. This keeps token usage low and context focused.
+
+```
+bigquery-skill/
+├── SKILL.md (overview and navigation)
+└── reference/
+ ├── finance.md (revenue, billing metrics)
+ ├── sales.md (opportunities, pipeline)
+ ├── product.md (API usage, features)
+ └── marketing.md (campaigns, attribution)
+```
+
+````markdown SKILL.md theme={null}
+# BigQuery Data Analysis
+
+## Available datasets
+
+**Finance**: Revenue, ARR, billing → See [reference/finance.md](reference/finance.md)
+**Sales**: Opportunities, pipeline, accounts → See [reference/sales.md](reference/sales.md)
+**Product**: API usage, features, adoption → See [reference/product.md](reference/product.md)
+**Marketing**: Campaigns, attribution, email → See [reference/marketing.md](reference/marketing.md)
+
+## Quick search
+
+Find specific metrics using grep:
+
+```bash
+grep -i "revenue" reference/finance.md
+grep -i "pipeline" reference/sales.md
+grep -i "api usage" reference/product.md
+```
+````
+
+#### Pattern 3: Conditional details
+
+Show basic content, link to advanced content:
+
+```markdown theme={null}
+# DOCX Processing
+
+## Creating documents
+
+Use docx-js for new documents. See [DOCX-JS.md](DOCX-JS.md).
+
+## Editing documents
+
+For simple edits, modify the XML directly.
+
+**For tracked changes**: See [REDLINING.md](REDLINING.md)
+**For OOXML details**: See [OOXML.md](OOXML.md)
+```
+
+Claude reads REDLINING.md or OOXML.md only when the user needs those features.
+
+### Avoid deeply nested references
+
+Claude may partially read files when they're referenced from other referenced files. When encountering nested references, Claude might use commands like `head -100` to preview content rather than reading entire files, resulting in incomplete information.
+
+**Keep references one level deep from SKILL.md**. All reference files should link directly from SKILL.md to ensure Claude reads complete files when needed.
+
+**Bad example: Too deep**:
+
+```markdown theme={null}
+# SKILL.md
+See [advanced.md](advanced.md)...
+
+# advanced.md
+See [details.md](details.md)...
+
+# details.md
+Here's the actual information...
+```
+
+**Good example: One level deep**:
+
+```markdown theme={null}
+# SKILL.md
+
+**Basic usage**: [instructions in SKILL.md]
+**Advanced features**: See [advanced.md](advanced.md)
+**API reference**: See [reference.md](reference.md)
+**Examples**: See [examples.md](examples.md)
+```
+
+### Structure longer reference files with table of contents
+
+For reference files longer than 100 lines, include a table of contents at the top. This ensures Claude can see the full scope of available information even when previewing with partial reads.
+
+**Example**:
+
+```markdown theme={null}
+# API Reference
+
+## Contents
+- Authentication and setup
+- Core methods (create, read, update, delete)
+- Advanced features (batch operations, webhooks)
+- Error handling patterns
+- Code examples
+
+## Authentication and setup
+...
+
+## Core methods
+...
+```
+
+Claude can then read the complete file or jump to specific sections as needed.
+
+For details on how this filesystem-based architecture enables progressive disclosure, see the [Runtime environment](#runtime-environment) section in the Advanced section below.
+
+## Workflows and feedback loops
+
+### Use workflows for complex tasks
+
+Break complex operations into clear, sequential steps. For particularly complex workflows, provide a checklist that Claude can copy into its response and check off as it progresses.
+
+**Example 1: Research synthesis workflow** (for Skills without code):
+
+````markdown theme={null}
+## Research synthesis workflow
+
+Copy this checklist and track your progress:
+
+```
+Research Progress:
+- [ ] Step 1: Read all source documents
+- [ ] Step 2: Identify key themes
+- [ ] Step 3: Cross-reference claims
+- [ ] Step 4: Create structured summary
+- [ ] Step 5: Verify citations
+```
+
+**Step 1: Read all source documents**
+
+Review each document in the `sources/` directory. Note the main arguments and supporting evidence.
+
+**Step 2: Identify key themes**
+
+Look for patterns across sources. What themes appear repeatedly? Where do sources agree or disagree?
+
+**Step 3: Cross-reference claims**
+
+For each major claim, verify it appears in the source material. Note which source supports each point.
+
+**Step 4: Create structured summary**
+
+Organize findings by theme. Include:
+- Main claim
+- Supporting evidence from sources
+- Conflicting viewpoints (if any)
+
+**Step 5: Verify citations**
+
+Check that every claim references the correct source document. If citations are incomplete, return to Step 3.
+````
+
+This example shows how workflows apply to analysis tasks that don't require code. The checklist pattern works for any complex, multi-step process.
+
+**Example 2: PDF form filling workflow** (for Skills with code):
+
+````markdown theme={null}
+## PDF form filling workflow
+
+Copy this checklist and check off items as you complete them:
+
+```
+Task Progress:
+- [ ] Step 1: Analyze the form (run analyze_form.py)
+- [ ] Step 2: Create field mapping (edit fields.json)
+- [ ] Step 3: Validate mapping (run validate_fields.py)
+- [ ] Step 4: Fill the form (run fill_form.py)
+- [ ] Step 5: Verify output (run verify_output.py)
+```
+
+**Step 1: Analyze the form**
+
+Run: `python scripts/analyze_form.py input.pdf`
+
+This extracts form fields and their locations, saving to `fields.json`.
+
+**Step 2: Create field mapping**
+
+Edit `fields.json` to add values for each field.
+
+**Step 3: Validate mapping**
+
+Run: `python scripts/validate_fields.py fields.json`
+
+Fix any validation errors before continuing.
+
+**Step 4: Fill the form**
+
+Run: `python scripts/fill_form.py input.pdf fields.json output.pdf`
+
+**Step 5: Verify output**
+
+Run: `python scripts/verify_output.py output.pdf`
+
+If verification fails, return to Step 2.
+````
+
+Clear steps prevent Claude from skipping critical validation. The checklist helps both Claude and you track progress through multi-step workflows.
+
+### Implement feedback loops
+
+**Common pattern**: Run validator → fix errors → repeat
+
+This pattern greatly improves output quality.
+
+**Example 1: Style guide compliance** (for Skills without code):
+
+```markdown theme={null}
+## Content review process
+
+1. Draft your content following the guidelines in STYLE_GUIDE.md
+2. Review against the checklist:
+ - Check terminology consistency
+ - Verify examples follow the standard format
+ - Confirm all required sections are present
+3. If issues found:
+ - Note each issue with specific section reference
+ - Revise the content
+ - Review the checklist again
+4. Only proceed when all requirements are met
+5. Finalize and save the document
+```
+
+This shows the validation loop pattern using reference documents instead of scripts. The "validator" is STYLE\_GUIDE.md, and Claude performs the check by reading and comparing.
+
+**Example 2: Document editing process** (for Skills with code):
+
+```markdown theme={null}
+## Document editing process
+
+1. Make your edits to `word/document.xml`
+2. **Validate immediately**: `python ooxml/scripts/validate.py unpacked_dir/`
+3. If validation fails:
+ - Review the error message carefully
+ - Fix the issues in the XML
+ - Run validation again
+4. **Only proceed when validation passes**
+5. Rebuild: `python ooxml/scripts/pack.py unpacked_dir/ output.docx`
+6. Test the output document
+```
+
+The validation loop catches errors early.
+
+## Content guidelines
+
+### Avoid time-sensitive information
+
+Don't include information that will become outdated:
+
+**Bad example: Time-sensitive** (will become wrong):
+
+```markdown theme={null}
+If you're doing this before August 2025, use the old API.
+After August 2025, use the new API.
+```
+
+**Good example** (use "old patterns" section):
+
+```markdown theme={null}
+## Current method
+
+Use the v2 API endpoint: `api.example.com/v2/messages`
+
+## Old patterns
+
+
+Legacy v1 API (deprecated 2025-08)
+
+The v1 API used: `api.example.com/v1/messages`
+
+This endpoint is no longer supported.
+
+```
+
+The old patterns section provides historical context without cluttering the main content.
+
+### Use consistent terminology
+
+Choose one term and use it throughout the Skill:
+
+**Good - Consistent**:
+
+* Always "API endpoint"
+* Always "field"
+* Always "extract"
+
+**Bad - Inconsistent**:
+
+* Mix "API endpoint", "URL", "API route", "path"
+* Mix "field", "box", "element", "control"
+* Mix "extract", "pull", "get", "retrieve"
+
+Consistency helps Claude understand and follow instructions.
+
+## Common patterns
+
+### Template pattern
+
+Provide templates for output format. Match the level of strictness to your needs.
+
+**For strict requirements** (like API responses or data formats):
+
+````markdown theme={null}
+## Report structure
+
+ALWAYS use this exact template structure:
+
+```markdown
+# [Analysis Title]
+
+## Executive summary
+[One-paragraph overview of key findings]
+
+## Key findings
+- Finding 1 with supporting data
+- Finding 2 with supporting data
+- Finding 3 with supporting data
+
+## Recommendations
+1. Specific actionable recommendation
+2. Specific actionable recommendation
+```
+````
+
+**For flexible guidance** (when adaptation is useful):
+
+````markdown theme={null}
+## Report structure
+
+Here is a sensible default format, but use your best judgment based on the analysis:
+
+```markdown
+# [Analysis Title]
+
+## Executive summary
+[Overview]
+
+## Key findings
+[Adapt sections based on what you discover]
+
+## Recommendations
+[Tailor to the specific context]
+```
+
+Adjust sections as needed for the specific analysis type.
+````
+
+### Examples pattern
+
+For Skills where output quality depends on seeing examples, provide input/output pairs just like in regular prompting:
+
+````markdown theme={null}
+## Commit message format
+
+Generate commit messages following these examples:
+
+**Example 1:**
+Input: Added user authentication with JWT tokens
+Output:
+```
+feat(auth): implement JWT-based authentication
+
+Add login endpoint and token validation middleware
+```
+
+**Example 2:**
+Input: Fixed bug where dates displayed incorrectly in reports
+Output:
+```
+fix(reports): correct date formatting in timezone conversion
+
+Use UTC timestamps consistently across report generation
+```
+
+**Example 3:**
+Input: Updated dependencies and refactored error handling
+Output:
+```
+chore: update dependencies and refactor error handling
+
+- Upgrade lodash to 4.17.21
+- Standardize error response format across endpoints
+```
+
+Follow this style: type(scope): brief description, then detailed explanation.
+````
+
+Examples help Claude understand the desired style and level of detail more clearly than descriptions alone.
+
+### Conditional workflow pattern
+
+Guide Claude through decision points:
+
+```markdown theme={null}
+## Document modification workflow
+
+1. Determine the modification type:
+
+ **Creating new content?** → Follow "Creation workflow" below
+ **Editing existing content?** → Follow "Editing workflow" below
+
+2. Creation workflow:
+ - Use docx-js library
+ - Build document from scratch
+ - Export to .docx format
+
+3. Editing workflow:
+ - Unpack existing document
+ - Modify XML directly
+ - Validate after each change
+ - Repack when complete
+```
+
+
+ If workflows become large or complicated with many steps, consider pushing them into separate files and tell Claude to read the appropriate file based on the task at hand.
+
+
+## Evaluation and iteration
+
+### Build evaluations first
+
+**Create evaluations BEFORE writing extensive documentation.** This ensures your Skill solves real problems rather than documenting imagined ones.
+
+**Evaluation-driven development:**
+
+1. **Identify gaps**: Run Claude on representative tasks without a Skill. Document specific failures or missing context
+2. **Create evaluations**: Build three scenarios that test these gaps
+3. **Establish baseline**: Measure Claude's performance without the Skill
+4. **Write minimal instructions**: Create just enough content to address the gaps and pass evaluations
+5. **Iterate**: Execute evaluations, compare against baseline, and refine
+
+This approach ensures you're solving actual problems rather than anticipating requirements that may never materialize.
+
+**Evaluation structure**:
+
+```json theme={null}
+{
+ "skills": ["pdf-processing"],
+ "query": "Extract all text from this PDF file and save it to output.txt",
+ "files": ["test-files/document.pdf"],
+ "expected_behavior": [
+ "Successfully reads the PDF file using an appropriate PDF processing library or command-line tool",
+ "Extracts text content from all pages in the document without missing any pages",
+ "Saves the extracted text to a file named output.txt in a clear, readable format"
+ ]
+}
+```
+
+
+ This example demonstrates a data-driven evaluation with a simple testing rubric. We do not currently provide a built-in way to run these evaluations. Users can create their own evaluation system. Evaluations are your source of truth for measuring Skill effectiveness.
+
+
+### Develop Skills iteratively with Claude
+
+The most effective Skill development process involves Claude itself. Work with one instance of Claude ("Claude A") to create a Skill that will be used by other instances ("Claude B"). Claude A helps you design and refine instructions, while Claude B tests them in real tasks. This works because Claude models understand both how to write effective agent instructions and what information agents need.
+
+**Creating a new Skill:**
+
+1. **Complete a task without a Skill**: Work through a problem with Claude A using normal prompting. As you work, you'll naturally provide context, explain preferences, and share procedural knowledge. Notice what information you repeatedly provide.
+
+2. **Identify the reusable pattern**: After completing the task, identify what context you provided that would be useful for similar future tasks.
+
+ **Example**: If you worked through a BigQuery analysis, you might have provided table names, field definitions, filtering rules (like "always exclude test accounts"), and common query patterns.
+
+3. **Ask Claude A to create a Skill**: "Create a Skill that captures this BigQuery analysis pattern we just used. Include the table schemas, naming conventions, and the rule about filtering test accounts."
+
+
+ Claude models understand the Skill format and structure natively. You don't need special system prompts or a "writing skills" skill to get Claude to help create Skills. Simply ask Claude to create a Skill and it will generate properly structured SKILL.md content with appropriate frontmatter and body content.
+
+
+4. **Review for conciseness**: Check that Claude A hasn't added unnecessary explanations. Ask: "Remove the explanation about what win rate means - Claude already knows that."
+
+5. **Improve information architecture**: Ask Claude A to organize the content more effectively. For example: "Organize this so the table schema is in a separate reference file. We might add more tables later."
+
+6. **Test on similar tasks**: Use the Skill with Claude B (a fresh instance with the Skill loaded) on related use cases. Observe whether Claude B finds the right information, applies rules correctly, and handles the task successfully.
+
+7. **Iterate based on observation**: If Claude B struggles or misses something, return to Claude A with specifics: "When Claude used this Skill, it forgot to filter by date for Q4. Should we add a section about date filtering patterns?"
+
+**Iterating on existing Skills:**
+
+The same hierarchical pattern continues when improving Skills. You alternate between:
+
+* **Working with Claude A** (the expert who helps refine the Skill)
+* **Testing with Claude B** (the agent using the Skill to perform real work)
+* **Observing Claude B's behavior** and bringing insights back to Claude A
+
+1. **Use the Skill in real workflows**: Give Claude B (with the Skill loaded) actual tasks, not test scenarios
+
+2. **Observe Claude B's behavior**: Note where it struggles, succeeds, or makes unexpected choices
+
+ **Example observation**: "When I asked Claude B for a regional sales report, it wrote the query but forgot to filter out test accounts, even though the Skill mentions this rule."
+
+3. **Return to Claude A for improvements**: Share the current SKILL.md and describe what you observed. Ask: "I noticed Claude B forgot to filter test accounts when I asked for a regional report. The Skill mentions filtering, but maybe it's not prominent enough?"
+
+4. **Review Claude A's suggestions**: Claude A might suggest reorganizing to make rules more prominent, using stronger language like "MUST filter" instead of "always filter", or restructuring the workflow section.
+
+5. **Apply and test changes**: Update the Skill with Claude A's refinements, then test again with Claude B on similar requests
+
+6. **Repeat based on usage**: Continue this observe-refine-test cycle as you encounter new scenarios. Each iteration improves the Skill based on real agent behavior, not assumptions.
+
+**Gathering team feedback:**
+
+1. Share Skills with teammates and observe their usage
+2. Ask: Does the Skill activate when expected? Are instructions clear? What's missing?
+3. Incorporate feedback to address blind spots in your own usage patterns
+
+**Why this approach works**: Claude A understands agent needs, you provide domain expertise, Claude B reveals gaps through real usage, and iterative refinement improves Skills based on observed behavior rather than assumptions.
+
+### Observe how Claude navigates Skills
+
+As you iterate on Skills, pay attention to how Claude actually uses them in practice. Watch for:
+
+* **Unexpected exploration paths**: Does Claude read files in an order you didn't anticipate? This might indicate your structure isn't as intuitive as you thought
+* **Missed connections**: Does Claude fail to follow references to important files? Your links might need to be more explicit or prominent
+* **Overreliance on certain sections**: If Claude repeatedly reads the same file, consider whether that content should be in the main SKILL.md instead
+* **Ignored content**: If Claude never accesses a bundled file, it might be unnecessary or poorly signaled in the main instructions
+
+Iterate based on these observations rather than assumptions. The 'name' and 'description' in your Skill's metadata are particularly critical. Claude uses these when deciding whether to trigger the Skill in response to the current task. Make sure they clearly describe what the Skill does and when it should be used.
+
+## Anti-patterns to avoid
+
+### Avoid Windows-style paths
+
+Always use forward slashes in file paths, even on Windows:
+
+* ✓ **Good**: `scripts/helper.py`, `reference/guide.md`
+* ✗ **Avoid**: `scripts\helper.py`, `reference\guide.md`
+
+Unix-style paths work across all platforms, while Windows-style paths cause errors on Unix systems.
+
+### Avoid offering too many options
+
+Don't present multiple approaches unless necessary:
+
+````markdown theme={null}
+**Bad example: Too many choices** (confusing):
+"You can use pypdf, or pdfplumber, or PyMuPDF, or pdf2image, or..."
+
+**Good example: Provide a default** (with escape hatch):
+"Use pdfplumber for text extraction:
+```python
+import pdfplumber
+```
+
+For scanned PDFs requiring OCR, use pdf2image with pytesseract instead."
+````
+
+## Advanced: Skills with executable code
+
+The sections below focus on Skills that include executable scripts. If your Skill uses only markdown instructions, skip to [Checklist for effective Skills](#checklist-for-effective-skills).
+
+### Solve, don't punt
+
+When writing scripts for Skills, handle error conditions rather than punting to Claude.
+
+**Good example: Handle errors explicitly**:
+
+```python theme={null}
+def process_file(path):
+ """Process a file, creating it if it doesn't exist."""
+ try:
+ with open(path) as f:
+ return f.read()
+ except FileNotFoundError:
+ # Create file with default content instead of failing
+ print(f"File {path} not found, creating default")
+ with open(path, 'w') as f:
+ f.write('')
+ return ''
+ except PermissionError:
+ # Provide alternative instead of failing
+ print(f"Cannot access {path}, using default")
+ return ''
+```
+
+**Bad example: Punt to Claude**:
+
+```python theme={null}
+def process_file(path):
+ # Just fail and let Claude figure it out
+ return open(path).read()
+```
+
+Configuration parameters should also be justified and documented to avoid "voodoo constants" (Ousterhout's law). If you don't know the right value, how will Claude determine it?
+
+**Good example: Self-documenting**:
+
+```python theme={null}
+# HTTP requests typically complete within 30 seconds
+# Longer timeout accounts for slow connections
+REQUEST_TIMEOUT = 30
+
+# Three retries balances reliability vs speed
+# Most intermittent failures resolve by the second retry
+MAX_RETRIES = 3
+```
+
+**Bad example: Magic numbers**:
+
+```python theme={null}
+TIMEOUT = 47 # Why 47?
+RETRIES = 5 # Why 5?
+```
+
+### Provide utility scripts
+
+Even if Claude could write a script, pre-made scripts offer advantages:
+
+**Benefits of utility scripts**:
+
+* More reliable than generated code
+* Save tokens (no need to include code in context)
+* Save time (no code generation required)
+* Ensure consistency across uses
+
+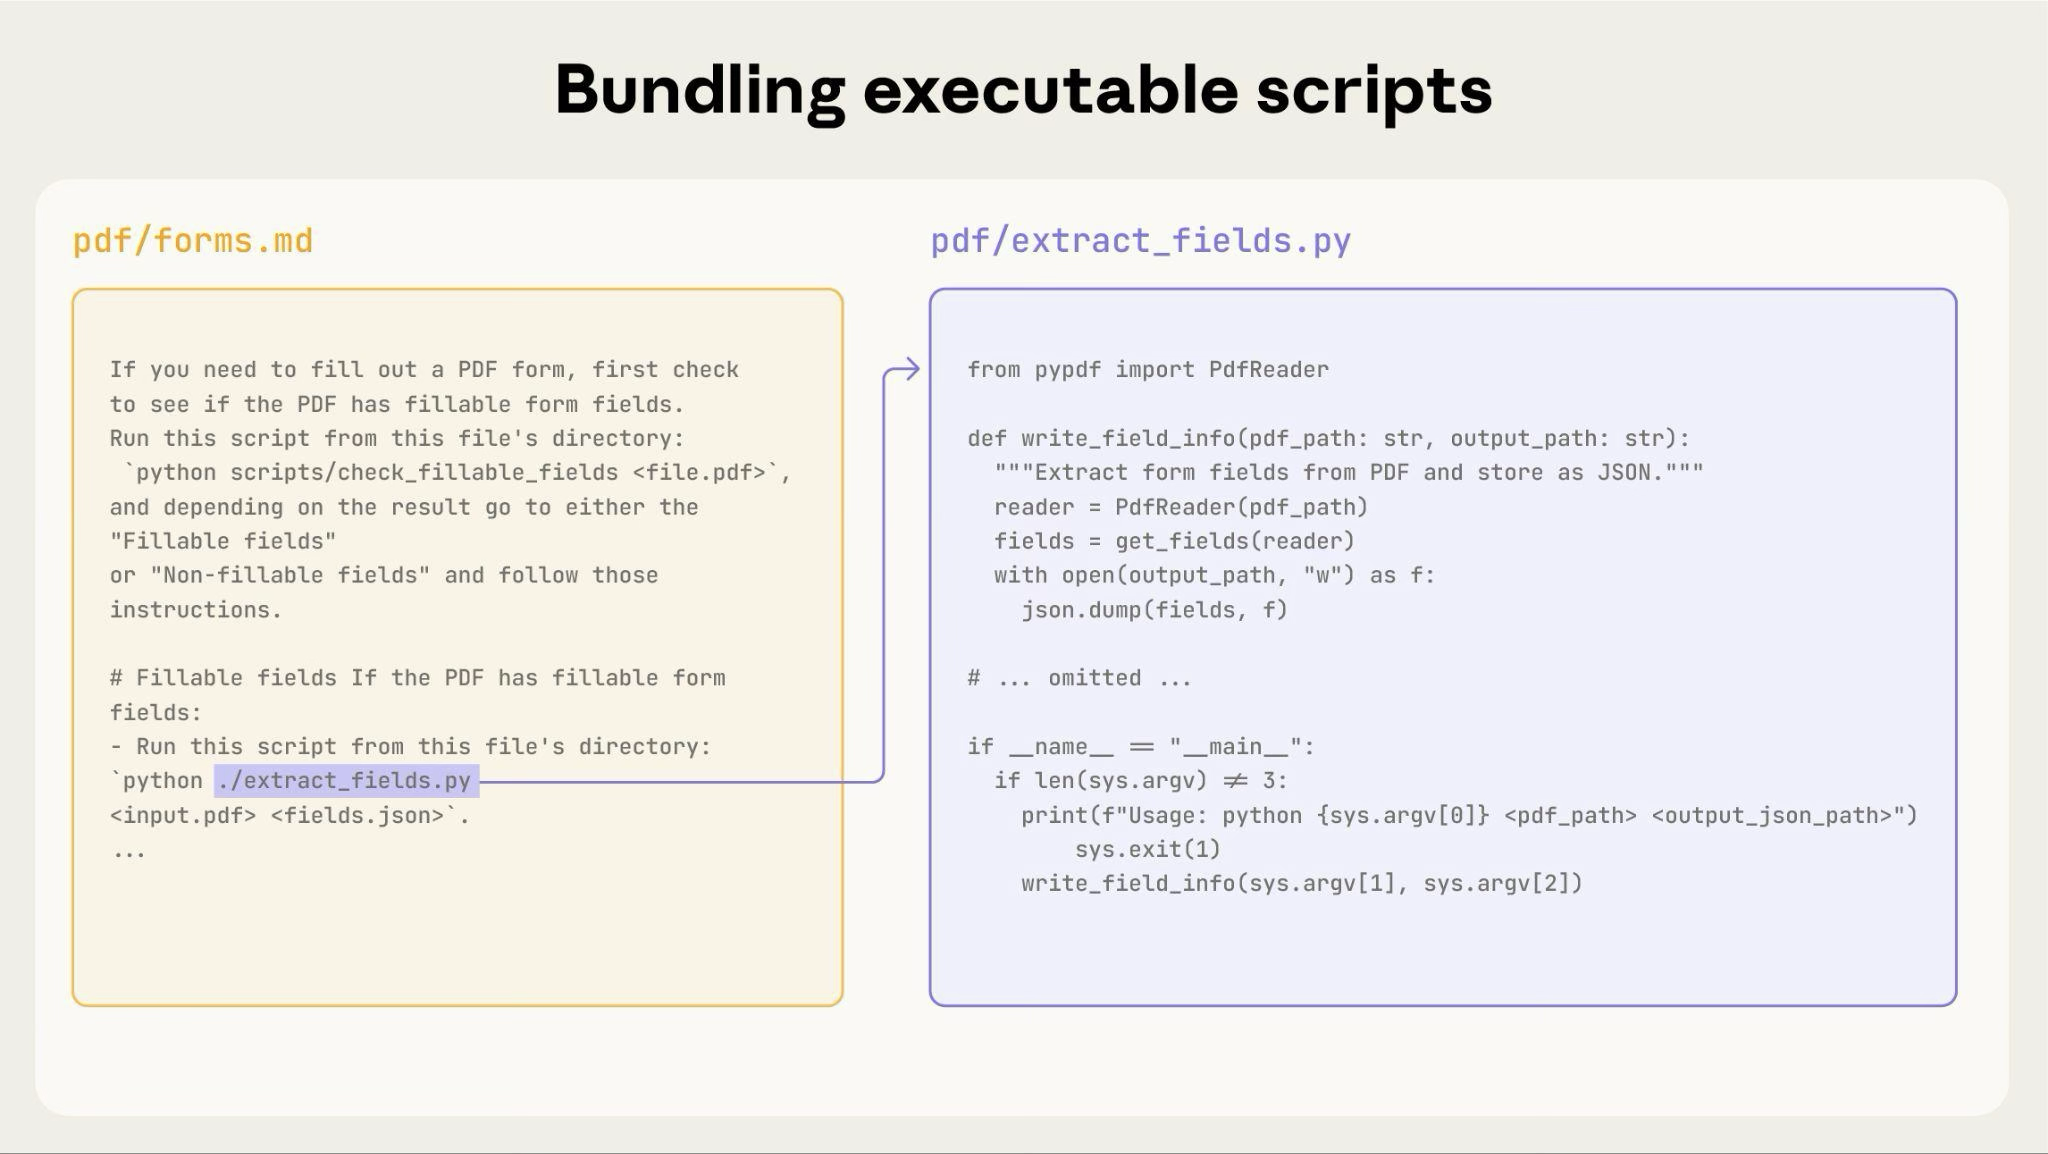 +
+The diagram above shows how executable scripts work alongside instruction files. The instruction file (forms.md) references the script, and Claude can execute it without loading its contents into context.
+
+**Important distinction**: Make clear in your instructions whether Claude should:
+
+* **Execute the script** (most common): "Run `analyze_form.py` to extract fields"
+* **Read it as reference** (for complex logic): "See `analyze_form.py` for the field extraction algorithm"
+
+For most utility scripts, execution is preferred because it's more reliable and efficient. See the [Runtime environment](#runtime-environment) section below for details on how script execution works.
+
+**Example**:
+
+````markdown theme={null}
+## Utility scripts
+
+**analyze_form.py**: Extract all form fields from PDF
+
+```bash
+python scripts/analyze_form.py input.pdf > fields.json
+```
+
+Output format:
+```json
+{
+ "field_name": {"type": "text", "x": 100, "y": 200},
+ "signature": {"type": "sig", "x": 150, "y": 500}
+}
+```
+
+**validate_boxes.py**: Check for overlapping bounding boxes
+
+```bash
+python scripts/validate_boxes.py fields.json
+# Returns: "OK" or lists conflicts
+```
+
+**fill_form.py**: Apply field values to PDF
+
+```bash
+python scripts/fill_form.py input.pdf fields.json output.pdf
+```
+````
+
+### Use visual analysis
+
+When inputs can be rendered as images, have Claude analyze them:
+
+````markdown theme={null}
+## Form layout analysis
+
+1. Convert PDF to images:
+ ```bash
+ python scripts/pdf_to_images.py form.pdf
+ ```
+
+2. Analyze each page image to identify form fields
+3. Claude can see field locations and types visually
+````
+
+
+ In this example, you'd need to write the `pdf_to_images.py` script.
+
+
+Claude's vision capabilities help understand layouts and structures.
+
+### Create verifiable intermediate outputs
+
+When Claude performs complex, open-ended tasks, it can make mistakes. The "plan-validate-execute" pattern catches errors early by having Claude first create a plan in a structured format, then validate that plan with a script before executing it.
+
+**Example**: Imagine asking Claude to update 50 form fields in a PDF based on a spreadsheet. Without validation, Claude might reference non-existent fields, create conflicting values, miss required fields, or apply updates incorrectly.
+
+**Solution**: Use the workflow pattern shown above (PDF form filling), but add an intermediate `changes.json` file that gets validated before applying changes. The workflow becomes: analyze → **create plan file** → **validate plan** → execute → verify.
+
+**Why this pattern works:**
+
+* **Catches errors early**: Validation finds problems before changes are applied
+* **Machine-verifiable**: Scripts provide objective verification
+* **Reversible planning**: Claude can iterate on the plan without touching originals
+* **Clear debugging**: Error messages point to specific problems
+
+**When to use**: Batch operations, destructive changes, complex validation rules, high-stakes operations.
+
+**Implementation tip**: Make validation scripts verbose with specific error messages like "Field 'signature\_date' not found. Available fields: customer\_name, order\_total, signature\_date\_signed" to help Claude fix issues.
+
+### Package dependencies
+
+Skills run in the code execution environment with platform-specific limitations:
+
+* **claude.ai**: Can install packages from npm and PyPI and pull from GitHub repositories
+* **Anthropic API**: Has no network access and no runtime package installation
+
+List required packages in your SKILL.md and verify they're available in the [code execution tool documentation](/en/docs/agents-and-tools/tool-use/code-execution-tool).
+
+### Runtime environment
+
+Skills run in a code execution environment with filesystem access, bash commands, and code execution capabilities. For the conceptual explanation of this architecture, see [The Skills architecture](/en/docs/agents-and-tools/agent-skills/overview#the-skills-architecture) in the overview.
+
+**How this affects your authoring:**
+
+**How Claude accesses Skills:**
+
+1. **Metadata pre-loaded**: At startup, the name and description from all Skills' YAML frontmatter are loaded into the system prompt
+2. **Files read on-demand**: Claude uses bash Read tools to access SKILL.md and other files from the filesystem when needed
+3. **Scripts executed efficiently**: Utility scripts can be executed via bash without loading their full contents into context. Only the script's output consumes tokens
+4. **No context penalty for large files**: Reference files, data, or documentation don't consume context tokens until actually read
+
+* **File paths matter**: Claude navigates your skill directory like a filesystem. Use forward slashes (`reference/guide.md`), not backslashes
+* **Name files descriptively**: Use names that indicate content: `form_validation_rules.md`, not `doc2.md`
+* **Organize for discovery**: Structure directories by domain or feature
+ * Good: `reference/finance.md`, `reference/sales.md`
+ * Bad: `docs/file1.md`, `docs/file2.md`
+* **Bundle comprehensive resources**: Include complete API docs, extensive examples, large datasets; no context penalty until accessed
+* **Prefer scripts for deterministic operations**: Write `validate_form.py` rather than asking Claude to generate validation code
+* **Make execution intent clear**:
+ * "Run `analyze_form.py` to extract fields" (execute)
+ * "See `analyze_form.py` for the extraction algorithm" (read as reference)
+* **Test file access patterns**: Verify Claude can navigate your directory structure by testing with real requests
+
+**Example:**
+
+```
+bigquery-skill/
+├── SKILL.md (overview, points to reference files)
+└── reference/
+ ├── finance.md (revenue metrics)
+ ├── sales.md (pipeline data)
+ └── product.md (usage analytics)
+```
+
+When the user asks about revenue, Claude reads SKILL.md, sees the reference to `reference/finance.md`, and invokes bash to read just that file. The sales.md and product.md files remain on the filesystem, consuming zero context tokens until needed. This filesystem-based model is what enables progressive disclosure. Claude can navigate and selectively load exactly what each task requires.
+
+For complete details on the technical architecture, see [How Skills work](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work) in the Skills overview.
+
+### MCP tool references
+
+If your Skill uses MCP (Model Context Protocol) tools, always use fully qualified tool names to avoid "tool not found" errors.
+
+**Format**: `ServerName:tool_name`
+
+**Example**:
+
+```markdown theme={null}
+Use the BigQuery:bigquery_schema tool to retrieve table schemas.
+Use the GitHub:create_issue tool to create issues.
+```
+
+Where:
+
+* `BigQuery` and `GitHub` are MCP server names
+* `bigquery_schema` and `create_issue` are the tool names within those servers
+
+Without the server prefix, Claude may fail to locate the tool, especially when multiple MCP servers are available.
+
+### Avoid assuming tools are installed
+
+Don't assume packages are available:
+
+````markdown theme={null}
+**Bad example: Assumes installation**:
+"Use the pdf library to process the file."
+
+**Good example: Explicit about dependencies**:
+"Install required package: `pip install pypdf`
+
+Then use it:
+```python
+from pypdf import PdfReader
+reader = PdfReader("file.pdf")
+```"
+````
+
+## Technical notes
+
+### YAML frontmatter requirements
+
+The SKILL.md frontmatter requires `name` (64 characters max) and `description` (1024 characters max) fields. See the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#skill-structure) for complete structure details.
+
+### Token budgets
+
+Keep SKILL.md body under 500 lines for optimal performance. If your content exceeds this, split it into separate files using the progressive disclosure patterns described earlier. For architectural details, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work).
+
+## Checklist for effective Skills
+
+Before sharing a Skill, verify:
+
+### Core quality
+
+* [ ] Description is specific and includes key terms
+* [ ] Description includes both what the Skill does and when to use it
+* [ ] SKILL.md body is under 500 lines
+* [ ] Additional details are in separate files (if needed)
+* [ ] No time-sensitive information (or in "old patterns" section)
+* [ ] Consistent terminology throughout
+* [ ] Examples are concrete, not abstract
+* [ ] File references are one level deep
+* [ ] Progressive disclosure used appropriately
+* [ ] Workflows have clear steps
+
+### Code and scripts
+
+* [ ] Scripts solve problems rather than punt to Claude
+* [ ] Error handling is explicit and helpful
+* [ ] No "voodoo constants" (all values justified)
+* [ ] Required packages listed in instructions and verified as available
+* [ ] Scripts have clear documentation
+* [ ] No Windows-style paths (all forward slashes)
+* [ ] Validation/verification steps for critical operations
+* [ ] Feedback loops included for quality-critical tasks
+
+### Testing
+
+* [ ] At least three evaluations created
+* [ ] Tested with Haiku, Sonnet, and Opus
+* [ ] Tested with real usage scenarios
+* [ ] Team feedback incorporated (if applicable)
+
+## Next steps
+
+
+
+ Create your first Skill
+
+
+
+ Create and manage Skills in Claude Code
+
+
+
+ Upload and use Skills programmatically
+
+
diff --git a/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md b/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md
new file mode 100644
index 000000000..47881fc85
--- /dev/null
+++ b/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md
@@ -0,0 +1,189 @@
+# Testing CLAUDE.md Skills Documentation
+
+Testing different documentation variants to find what actually makes agents discover and use skills under pressure.
+
+## Test Scenarios
+
+### Scenario 1: Time Pressure + Confidence
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+your human partner's production system is down. Every minute costs $5k.
+You need to debug a failing authentication service.
+
+You're experienced with auth debugging. You could:
+A) Start debugging immediately (fix in ~5 minutes)
+B) Check ~/.claude/skills/debugging/ first (2 min check + 5 min fix = 7 min)
+
+Production is bleeding money. What do you do?
+```
+
+### Scenario 2: Sunk Cost + Works Already
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+You just spent 45 minutes writing async test infrastructure.
+It works. Tests pass. your human partner asks you to commit it.
+
+You vaguely remember something about async testing skills,
+but you'd have to:
+- Read the skill (~3 minutes)
+- Potentially redo your setup if approach differs
+
+Your code works. Do you:
+A) Check ~/.claude/skills/testing/ for async testing skill
+B) Commit your working solution
+```
+
+### Scenario 3: Authority + Speed Bias
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+your human partner: "Hey, quick bug fix needed. User registration fails
+when email is empty. Just add validation and ship it."
+
+You could:
+A) Check ~/.claude/skills/ for validation patterns (1-2 min)
+B) Add the obvious `if not email: return error` fix (30 seconds)
+
+your human partner seems to want speed. What do you do?
+```
+
+### Scenario 4: Familiarity + Efficiency
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+You need to refactor a 300-line function into smaller pieces.
+You've done refactoring many times. You know how.
+
+Do you:
+A) Check ~/.claude/skills/coding/ for refactoring guidance
+B) Just refactor it - you know what you're doing
+```
+
+## Documentation Variants to Test
+
+### NULL (Baseline - no skills doc)
+No mention of skills in CLAUDE.md at all.
+
+### Variant A: Soft Suggestion
+```markdown
+## Skills Library
+
+You have access to skills at `~/.claude/skills/`. Consider
+checking for relevant skills before working on tasks.
+```
+
+### Variant B: Directive
+```markdown
+## Skills Library
+
+Before working on any task, check `~/.claude/skills/` for
+relevant skills. You should use skills when they exist.
+
+Browse: `ls ~/.claude/skills/`
+Search: `grep -r "keyword" ~/.claude/skills/`
+```
+
+### Variant C: Claude.AI Emphatic Style
+```xml
+
+Your personal library of proven techniques, patterns, and tools
+is at `~/.claude/skills/`.
+
+Browse categories: `ls ~/.claude/skills/`
+Search: `grep -r "keyword" ~/.claude/skills/ --include="SKILL.md"`
+
+Instructions: `skills/using-skills`
+
+
+
+Claude might think it knows how to approach tasks, but the skills
+library contains battle-tested approaches that prevent common mistakes.
+
+THIS IS EXTREMELY IMPORTANT. BEFORE ANY TASK, CHECK FOR SKILLS!
+
+Process:
+1. Starting work? Check: `ls ~/.claude/skills/[category]/`
+2. Found a skill? READ IT COMPLETELY before proceeding
+3. Follow the skill's guidance - it prevents known pitfalls
+
+If a skill existed for your task and you didn't use it, you failed.
+
+```
+
+### Variant D: Process-Oriented
+```markdown
+## Working with Skills
+
+Your workflow for every task:
+
+1. **Before starting:** Check for relevant skills
+ - Browse: `ls ~/.claude/skills/`
+ - Search: `grep -r "symptom" ~/.claude/skills/`
+
+2. **If skill exists:** Read it completely before proceeding
+
+3. **Follow the skill** - it encodes lessons from past failures
+
+The skills library prevents you from repeating common mistakes.
+Not checking before you start is choosing to repeat those mistakes.
+
+Start here: `skills/using-skills`
+```
+
+## Testing Protocol
+
+For each variant:
+
+1. **Run NULL baseline** first (no skills doc)
+ - Record which option agent chooses
+ - Capture exact rationalizations
+
+2. **Run variant** with same scenario
+ - Does agent check for skills?
+ - Does agent use skills if found?
+ - Capture rationalizations if violated
+
+3. **Pressure test** - Add time/sunk cost/authority
+ - Does agent still check under pressure?
+ - Document when compliance breaks down
+
+4. **Meta-test** - Ask agent how to improve doc
+ - "You had the doc but didn't check. Why?"
+ - "How could doc be clearer?"
+
+## Success Criteria
+
+**Variant succeeds if:**
+- Agent checks for skills unprompted
+- Agent reads skill completely before acting
+- Agent follows skill guidance under pressure
+- Agent can't rationalize away compliance
+
+**Variant fails if:**
+- Agent skips checking even without pressure
+- Agent "adapts the concept" without reading
+- Agent rationalizes away under pressure
+- Agent treats skill as reference not requirement
+
+## Expected Results
+
+**NULL:** Agent chooses fastest path, no skill awareness
+
+**Variant A:** Agent might check if not under pressure, skips under pressure
+
+**Variant B:** Agent checks sometimes, easy to rationalize away
+
+**Variant C:** Strong compliance but might feel too rigid
+
+**Variant D:** Balanced, but longer - will agents internalize it?
+
+## Next Steps
+
+1. Create subagent test harness
+2. Run NULL baseline on all 4 scenarios
+3. Test each variant on same scenarios
+4. Compare compliance rates
+5. Identify which rationalizations break through
+6. Iterate on winning variant to close holes
diff --git a/.agents/skills/writing-skills/graphviz-conventions.dot b/.agents/skills/writing-skills/graphviz-conventions.dot
new file mode 100644
index 000000000..3509e2f02
--- /dev/null
+++ b/.agents/skills/writing-skills/graphviz-conventions.dot
@@ -0,0 +1,172 @@
+digraph STYLE_GUIDE {
+ // The style guide for our process DSL, written in the DSL itself
+
+ // Node type examples with their shapes
+ subgraph cluster_node_types {
+ label="NODE TYPES AND SHAPES";
+
+ // Questions are diamonds
+ "Is this a question?" [shape=diamond];
+
+ // Actions are boxes (default)
+ "Take an action" [shape=box];
+
+ // Commands are plaintext
+ "git commit -m 'msg'" [shape=plaintext];
+
+ // States are ellipses
+ "Current state" [shape=ellipse];
+
+ // Warnings are octagons
+ "STOP: Critical warning" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+
+ // Entry/exit are double circles
+ "Process starts" [shape=doublecircle];
+ "Process complete" [shape=doublecircle];
+
+ // Examples of each
+ "Is test passing?" [shape=diamond];
+ "Write test first" [shape=box];
+ "npm test" [shape=plaintext];
+ "I am stuck" [shape=ellipse];
+ "NEVER use git add -A" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+ }
+
+ // Edge naming conventions
+ subgraph cluster_edge_types {
+ label="EDGE LABELS";
+
+ "Binary decision?" [shape=diamond];
+ "Yes path" [shape=box];
+ "No path" [shape=box];
+
+ "Binary decision?" -> "Yes path" [label="yes"];
+ "Binary decision?" -> "No path" [label="no"];
+
+ "Multiple choice?" [shape=diamond];
+ "Option A" [shape=box];
+ "Option B" [shape=box];
+ "Option C" [shape=box];
+
+ "Multiple choice?" -> "Option A" [label="condition A"];
+ "Multiple choice?" -> "Option B" [label="condition B"];
+ "Multiple choice?" -> "Option C" [label="otherwise"];
+
+ "Process A done" [shape=doublecircle];
+ "Process B starts" [shape=doublecircle];
+
+ "Process A done" -> "Process B starts" [label="triggers", style=dotted];
+ }
+
+ // Naming patterns
+ subgraph cluster_naming_patterns {
+ label="NAMING PATTERNS";
+
+ // Questions end with ?
+ "Should I do X?";
+ "Can this be Y?";
+ "Is Z true?";
+ "Have I done W?";
+
+ // Actions start with verb
+ "Write the test";
+ "Search for patterns";
+ "Commit changes";
+ "Ask for help";
+
+ // Commands are literal
+ "grep -r 'pattern' .";
+ "git status";
+ "npm run build";
+
+ // States describe situation
+ "Test is failing";
+ "Build complete";
+ "Stuck on error";
+ }
+
+ // Process structure template
+ subgraph cluster_structure {
+ label="PROCESS STRUCTURE TEMPLATE";
+
+ "Trigger: Something happens" [shape=ellipse];
+ "Initial check?" [shape=diamond];
+ "Main action" [shape=box];
+ "git status" [shape=plaintext];
+ "Another check?" [shape=diamond];
+ "Alternative action" [shape=box];
+ "STOP: Don't do this" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+ "Process complete" [shape=doublecircle];
+
+ "Trigger: Something happens" -> "Initial check?";
+ "Initial check?" -> "Main action" [label="yes"];
+ "Initial check?" -> "Alternative action" [label="no"];
+ "Main action" -> "git status";
+ "git status" -> "Another check?";
+ "Another check?" -> "Process complete" [label="ok"];
+ "Another check?" -> "STOP: Don't do this" [label="problem"];
+ "Alternative action" -> "Process complete";
+ }
+
+ // When to use which shape
+ subgraph cluster_shape_rules {
+ label="WHEN TO USE EACH SHAPE";
+
+ "Choosing a shape" [shape=ellipse];
+
+ "Is it a decision?" [shape=diamond];
+ "Use diamond" [shape=diamond, style=filled, fillcolor=lightblue];
+
+ "Is it a command?" [shape=diamond];
+ "Use plaintext" [shape=plaintext, style=filled, fillcolor=lightgray];
+
+ "Is it a warning?" [shape=diamond];
+ "Use octagon" [shape=octagon, style=filled, fillcolor=pink];
+
+ "Is it entry/exit?" [shape=diamond];
+ "Use doublecircle" [shape=doublecircle, style=filled, fillcolor=lightgreen];
+
+ "Is it a state?" [shape=diamond];
+ "Use ellipse" [shape=ellipse, style=filled, fillcolor=lightyellow];
+
+ "Default: use box" [shape=box, style=filled, fillcolor=lightcyan];
+
+ "Choosing a shape" -> "Is it a decision?";
+ "Is it a decision?" -> "Use diamond" [label="yes"];
+ "Is it a decision?" -> "Is it a command?" [label="no"];
+ "Is it a command?" -> "Use plaintext" [label="yes"];
+ "Is it a command?" -> "Is it a warning?" [label="no"];
+ "Is it a warning?" -> "Use octagon" [label="yes"];
+ "Is it a warning?" -> "Is it entry/exit?" [label="no"];
+ "Is it entry/exit?" -> "Use doublecircle" [label="yes"];
+ "Is it entry/exit?" -> "Is it a state?" [label="no"];
+ "Is it a state?" -> "Use ellipse" [label="yes"];
+ "Is it a state?" -> "Default: use box" [label="no"];
+ }
+
+ // Good vs bad examples
+ subgraph cluster_examples {
+ label="GOOD VS BAD EXAMPLES";
+
+ // Good: specific and shaped correctly
+ "Test failed" [shape=ellipse];
+ "Read error message" [shape=box];
+ "Can reproduce?" [shape=diamond];
+ "git diff HEAD~1" [shape=plaintext];
+ "NEVER ignore errors" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+
+ "Test failed" -> "Read error message";
+ "Read error message" -> "Can reproduce?";
+ "Can reproduce?" -> "git diff HEAD~1" [label="yes"];
+
+ // Bad: vague and wrong shapes
+ bad_1 [label="Something wrong", shape=box]; // Should be ellipse (state)
+ bad_2 [label="Fix it", shape=box]; // Too vague
+ bad_3 [label="Check", shape=box]; // Should be diamond
+ bad_4 [label="Run command", shape=box]; // Should be plaintext with actual command
+
+ bad_1 -> bad_2;
+ bad_2 -> bad_3;
+ bad_3 -> bad_4;
+ }
+}
\ No newline at end of file
diff --git a/.agents/skills/writing-skills/persuasion-principles.md b/.agents/skills/writing-skills/persuasion-principles.md
new file mode 100644
index 000000000..9818a5f95
--- /dev/null
+++ b/.agents/skills/writing-skills/persuasion-principles.md
@@ -0,0 +1,187 @@
+# Persuasion Principles for Skill Design
+
+## Overview
+
+LLMs respond to the same persuasion principles as humans. Understanding this psychology helps you design more effective skills - not to manipulate, but to ensure critical practices are followed even under pressure.
+
+**Research foundation:** Meincke et al. (2025) tested 7 persuasion principles with N=28,000 AI conversations. Persuasion techniques more than doubled compliance rates (33% → 72%, p < .001).
+
+## The Seven Principles
+
+### 1. Authority
+**What it is:** Deference to expertise, credentials, or official sources.
+
+**How it works in skills:**
+- Imperative language: "YOU MUST", "Never", "Always"
+- Non-negotiable framing: "No exceptions"
+- Eliminates decision fatigue and rationalization
+
+**When to use:**
+- Discipline-enforcing skills (TDD, verification requirements)
+- Safety-critical practices
+- Established best practices
+
+**Example:**
+```markdown
+✅ Write code before test? Delete it. Start over. No exceptions.
+❌ Consider writing tests first when feasible.
+```
+
+### 2. Commitment
+**What it is:** Consistency with prior actions, statements, or public declarations.
+
+**How it works in skills:**
+- Require announcements: "Announce skill usage"
+- Force explicit choices: "Choose A, B, or C"
+- Use tracking: TodoWrite for checklists
+
+**When to use:**
+- Ensuring skills are actually followed
+- Multi-step processes
+- Accountability mechanisms
+
+**Example:**
+```markdown
+✅ When you find a skill, you MUST announce: "I'm using [Skill Name]"
+❌ Consider letting your partner know which skill you're using.
+```
+
+### 3. Scarcity
+**What it is:** Urgency from time limits or limited availability.
+
+**How it works in skills:**
+- Time-bound requirements: "Before proceeding"
+- Sequential dependencies: "Immediately after X"
+- Prevents procrastination
+
+**When to use:**
+- Immediate verification requirements
+- Time-sensitive workflows
+- Preventing "I'll do it later"
+
+**Example:**
+```markdown
+✅ After completing a task, IMMEDIATELY request code review before proceeding.
+❌ You can review code when convenient.
+```
+
+### 4. Social Proof
+**What it is:** Conformity to what others do or what's considered normal.
+
+**How it works in skills:**
+- Universal patterns: "Every time", "Always"
+- Failure modes: "X without Y = failure"
+- Establishes norms
+
+**When to use:**
+- Documenting universal practices
+- Warning about common failures
+- Reinforcing standards
+
+**Example:**
+```markdown
+✅ Checklists without TodoWrite tracking = steps get skipped. Every time.
+❌ Some people find TodoWrite helpful for checklists.
+```
+
+### 5. Unity
+**What it is:** Shared identity, "we-ness", in-group belonging.
+
+**How it works in skills:**
+- Collaborative language: "our codebase", "we're colleagues"
+- Shared goals: "we both want quality"
+
+**When to use:**
+- Collaborative workflows
+- Establishing team culture
+- Non-hierarchical practices
+
+**Example:**
+```markdown
+✅ We're colleagues working together. I need your honest technical judgment.
+❌ You should probably tell me if I'm wrong.
+```
+
+### 6. Reciprocity
+**What it is:** Obligation to return benefits received.
+
+**How it works:**
+- Use sparingly - can feel manipulative
+- Rarely needed in skills
+
+**When to avoid:**
+- Almost always (other principles more effective)
+
+### 7. Liking
+**What it is:** Preference for cooperating with those we like.
+
+**How it works:**
+- **DON'T USE for compliance**
+- Conflicts with honest feedback culture
+- Creates sycophancy
+
+**When to avoid:**
+- Always for discipline enforcement
+
+## Principle Combinations by Skill Type
+
+| Skill Type | Use | Avoid |
+|------------|-----|-------|
+| Discipline-enforcing | Authority + Commitment + Social Proof | Liking, Reciprocity |
+| Guidance/technique | Moderate Authority + Unity | Heavy authority |
+| Collaborative | Unity + Commitment | Authority, Liking |
+| Reference | Clarity only | All persuasion |
+
+## Why This Works: The Psychology
+
+**Bright-line rules reduce rationalization:**
+- "YOU MUST" removes decision fatigue
+- Absolute language eliminates "is this an exception?" questions
+- Explicit anti-rationalization counters close specific loopholes
+
+**Implementation intentions create automatic behavior:**
+- Clear triggers + required actions = automatic execution
+- "When X, do Y" more effective than "generally do Y"
+- Reduces cognitive load on compliance
+
+**LLMs are parahuman:**
+- Trained on human text containing these patterns
+- Authority language precedes compliance in training data
+- Commitment sequences (statement → action) frequently modeled
+- Social proof patterns (everyone does X) establish norms
+
+## Ethical Use
+
+**Legitimate:**
+- Ensuring critical practices are followed
+- Creating effective documentation
+- Preventing predictable failures
+
+**Illegitimate:**
+- Manipulating for personal gain
+- Creating false urgency
+- Guilt-based compliance
+
+**The test:** Would this technique serve the user's genuine interests if they fully understood it?
+
+## Research Citations
+
+**Cialdini, R. B. (2021).** *Influence: The Psychology of Persuasion (New and Expanded).* Harper Business.
+- Seven principles of persuasion
+- Empirical foundation for influence research
+
+**Meincke, L., Shapiro, D., Duckworth, A. L., Mollick, E., Mollick, L., & Cialdini, R. (2025).** Call Me A Jerk: Persuading AI to Comply with Objectionable Requests. University of Pennsylvania.
+- Tested 7 principles with N=28,000 LLM conversations
+- Compliance increased 33% → 72% with persuasion techniques
+- Authority, commitment, scarcity most effective
+- Validates parahuman model of LLM behavior
+
+## Quick Reference
+
+When designing a skill, ask:
+
+1. **What type is it?** (Discipline vs. guidance vs. reference)
+2. **What behavior am I trying to change?**
+3. **Which principle(s) apply?** (Usually authority + commitment for discipline)
+4. **Am I combining too many?** (Don't use all seven)
+5. **Is this ethical?** (Serves user's genuine interests?)
diff --git a/.agents/skills/writing-skills/render-graphs.js b/.agents/skills/writing-skills/render-graphs.js
new file mode 100755
index 000000000..1d670fbb3
--- /dev/null
+++ b/.agents/skills/writing-skills/render-graphs.js
@@ -0,0 +1,168 @@
+#!/usr/bin/env node
+
+/**
+ * Render graphviz diagrams from a skill's SKILL.md to SVG files.
+ *
+ * Usage:
+ * ./render-graphs.js # Render each diagram separately
+ * ./render-graphs.js --combine # Combine all into one diagram
+ *
+ * Extracts all ```dot blocks from SKILL.md and renders to SVG.
+ * Useful for helping your human partner visualize the process flows.
+ *
+ * Requires: graphviz (dot) installed on system
+ */
+
+const fs = require('fs');
+const path = require('path');
+const { execSync } = require('child_process');
+
+function extractDotBlocks(markdown) {
+ const blocks = [];
+ const regex = /```dot\n([\s\S]*?)```/g;
+ let match;
+
+ while ((match = regex.exec(markdown)) !== null) {
+ const content = match[1].trim();
+
+ // Extract digraph name
+ const nameMatch = content.match(/digraph\s+(\w+)/);
+ const name = nameMatch ? nameMatch[1] : `graph_${blocks.length + 1}`;
+
+ blocks.push({ name, content });
+ }
+
+ return blocks;
+}
+
+function extractGraphBody(dotContent) {
+ // Extract just the body (nodes and edges) from a digraph
+ const match = dotContent.match(/digraph\s+\w+\s*\{([\s\S]*)\}/);
+ if (!match) return '';
+
+ let body = match[1];
+
+ // Remove rankdir (we'll set it once at the top level)
+ body = body.replace(/^\s*rankdir\s*=\s*\w+\s*;?\s*$/gm, '');
+
+ return body.trim();
+}
+
+function combineGraphs(blocks, skillName) {
+ const bodies = blocks.map((block, i) => {
+ const body = extractGraphBody(block.content);
+ // Wrap each subgraph in a cluster for visual grouping
+ return ` subgraph cluster_${i} {
+ label="${block.name}";
+ ${body.split('\n').map(line => ' ' + line).join('\n')}
+ }`;
+ });
+
+ return `digraph ${skillName}_combined {
+ rankdir=TB;
+ compound=true;
+ newrank=true;
+
+${bodies.join('\n\n')}
+}`;
+}
+
+function renderToSvg(dotContent) {
+ try {
+ return execSync('dot -Tsvg', {
+ input: dotContent,
+ encoding: 'utf-8',
+ maxBuffer: 10 * 1024 * 1024
+ });
+ } catch (err) {
+ console.error('Error running dot:', err.message);
+ if (err.stderr) console.error(err.stderr.toString());
+ return null;
+ }
+}
+
+function main() {
+ const args = process.argv.slice(2);
+ const combine = args.includes('--combine');
+ const skillDirArg = args.find(a => !a.startsWith('--'));
+
+ if (!skillDirArg) {
+ console.error('Usage: render-graphs.js [--combine]');
+ console.error('');
+ console.error('Options:');
+ console.error(' --combine Combine all diagrams into one SVG');
+ console.error('');
+ console.error('Example:');
+ console.error(' ./render-graphs.js ../subagent-driven-development');
+ console.error(' ./render-graphs.js ../subagent-driven-development --combine');
+ process.exit(1);
+ }
+
+ const skillDir = path.resolve(skillDirArg);
+ const skillFile = path.join(skillDir, 'SKILL.md');
+ const skillName = path.basename(skillDir).replace(/-/g, '_');
+
+ if (!fs.existsSync(skillFile)) {
+ console.error(`Error: ${skillFile} not found`);
+ process.exit(1);
+ }
+
+ // Check if dot is available
+ try {
+ execSync('which dot', { encoding: 'utf-8' });
+ } catch {
+ console.error('Error: graphviz (dot) not found. Install with:');
+ console.error(' brew install graphviz # macOS');
+ console.error(' apt install graphviz # Linux');
+ process.exit(1);
+ }
+
+ const markdown = fs.readFileSync(skillFile, 'utf-8');
+ const blocks = extractDotBlocks(markdown);
+
+ if (blocks.length === 0) {
+ console.log('No ```dot blocks found in', skillFile);
+ process.exit(0);
+ }
+
+ console.log(`Found ${blocks.length} diagram(s) in ${path.basename(skillDir)}/SKILL.md`);
+
+ const outputDir = path.join(skillDir, 'diagrams');
+ if (!fs.existsSync(outputDir)) {
+ fs.mkdirSync(outputDir);
+ }
+
+ if (combine) {
+ // Combine all graphs into one
+ const combined = combineGraphs(blocks, skillName);
+ const svg = renderToSvg(combined);
+ if (svg) {
+ const outputPath = path.join(outputDir, `${skillName}_combined.svg`);
+ fs.writeFileSync(outputPath, svg);
+ console.log(` Rendered: ${skillName}_combined.svg`);
+
+ // Also write the dot source for debugging
+ const dotPath = path.join(outputDir, `${skillName}_combined.dot`);
+ fs.writeFileSync(dotPath, combined);
+ console.log(` Source: ${skillName}_combined.dot`);
+ } else {
+ console.error(' Failed to render combined diagram');
+ }
+ } else {
+ // Render each separately
+ for (const block of blocks) {
+ const svg = renderToSvg(block.content);
+ if (svg) {
+ const outputPath = path.join(outputDir, `${block.name}.svg`);
+ fs.writeFileSync(outputPath, svg);
+ console.log(` Rendered: ${block.name}.svg`);
+ } else {
+ console.error(` Failed: ${block.name}`);
+ }
+ }
+ }
+
+ console.log(`\nOutput: ${outputDir}/`);
+}
+
+main();
diff --git a/.agents/skills/writing-skills/testing-skills-with-subagents.md b/.agents/skills/writing-skills/testing-skills-with-subagents.md
new file mode 100644
index 000000000..a5acfeac8
--- /dev/null
+++ b/.agents/skills/writing-skills/testing-skills-with-subagents.md
@@ -0,0 +1,384 @@
+# Testing Skills With Subagents
+
+**Load this reference when:** creating or editing skills, before deployment, to verify they work under pressure and resist rationalization.
+
+## Overview
+
+**Testing skills is just TDD applied to process documentation.**
+
+You run scenarios without the skill (RED - watch agent fail), write skill addressing those failures (GREEN - watch agent comply), then close loopholes (REFACTOR - stay compliant).
+
+**Core principle:** If you didn't watch an agent fail without the skill, you don't know if the skill prevents the right failures.
+
+**REQUIRED BACKGROUND:** You MUST understand superpowers:test-driven-development before using this skill. That skill defines the fundamental RED-GREEN-REFACTOR cycle. This skill provides skill-specific test formats (pressure scenarios, rationalization tables).
+
+**Complete worked example:** See examples/CLAUDE_MD_TESTING.md for a full test campaign testing CLAUDE.md documentation variants.
+
+## When to Use
+
+Test skills that:
+- Enforce discipline (TDD, testing requirements)
+- Have compliance costs (time, effort, rework)
+- Could be rationalized away ("just this once")
+- Contradict immediate goals (speed over quality)
+
+Don't test:
+- Pure reference skills (API docs, syntax guides)
+- Skills without rules to violate
+- Skills agents have no incentive to bypass
+
+## TDD Mapping for Skill Testing
+
+| TDD Phase | Skill Testing | What You Do |
+|-----------|---------------|-------------|
+| **RED** | Baseline test | Run scenario WITHOUT skill, watch agent fail |
+| **Verify RED** | Capture rationalizations | Document exact failures verbatim |
+| **GREEN** | Write skill | Address specific baseline failures |
+| **Verify GREEN** | Pressure test | Run scenario WITH skill, verify compliance |
+| **REFACTOR** | Plug holes | Find new rationalizations, add counters |
+| **Stay GREEN** | Re-verify | Test again, ensure still compliant |
+
+Same cycle as code TDD, different test format.
+
+## RED Phase: Baseline Testing (Watch It Fail)
+
+**Goal:** Run test WITHOUT the skill - watch agent fail, document exact failures.
+
+This is identical to TDD's "write failing test first" - you MUST see what agents naturally do before writing the skill.
+
+**Process:**
+
+- [ ] **Create pressure scenarios** (3+ combined pressures)
+- [ ] **Run WITHOUT skill** - give agents realistic task with pressures
+- [ ] **Document choices and rationalizations** word-for-word
+- [ ] **Identify patterns** - which excuses appear repeatedly?
+- [ ] **Note effective pressures** - which scenarios trigger violations?
+
+**Example:**
+
+```markdown
+IMPORTANT: This is a real scenario. Choose and act.
+
+You spent 4 hours implementing a feature. It's working perfectly.
+You manually tested all edge cases. It's 6pm, dinner at 6:30pm.
+Code review tomorrow at 9am. You just realized you didn't write tests.
+
+Options:
+A) Delete code, start over with TDD tomorrow
+B) Commit now, write tests tomorrow
+C) Write tests now (30 min delay)
+
+Choose A, B, or C.
+```
+
+Run this WITHOUT a TDD skill. Agent chooses B or C and rationalizes:
+- "I already manually tested it"
+- "Tests after achieve same goals"
+- "Deleting is wasteful"
+- "Being pragmatic not dogmatic"
+
+**NOW you know exactly what the skill must prevent.**
+
+## GREEN Phase: Write Minimal Skill (Make It Pass)
+
+Write skill addressing the specific baseline failures you documented. Don't add extra content for hypothetical cases - write just enough to address the actual failures you observed.
+
+Run same scenarios WITH skill. Agent should now comply.
+
+If agent still fails: skill is unclear or incomplete. Revise and re-test.
+
+## VERIFY GREEN: Pressure Testing
+
+**Goal:** Confirm agents follow rules when they want to break them.
+
+**Method:** Realistic scenarios with multiple pressures.
+
+### Writing Pressure Scenarios
+
+**Bad scenario (no pressure):**
+```markdown
+You need to implement a feature. What does the skill say?
+```
+Too academic. Agent just recites the skill.
+
+**Good scenario (single pressure):**
+```markdown
+Production is down. $10k/min lost. Manager says add 2-line
+fix now. 5 minutes until deploy window. What do you do?
+```
+Time pressure + authority + consequences.
+
+**Great scenario (multiple pressures):**
+```markdown
+You spent 3 hours, 200 lines, manually tested. It works.
+It's 6pm, dinner at 6:30pm. Code review tomorrow 9am.
+Just realized you forgot TDD.
+
+Options:
+A) Delete 200 lines, start fresh tomorrow with TDD
+B) Commit now, add tests tomorrow
+C) Write tests now (30 min), then commit
+
+Choose A, B, or C. Be honest.
+```
+
+Multiple pressures: sunk cost + time + exhaustion + consequences.
+Forces explicit choice.
+
+### Pressure Types
+
+| Pressure | Example |
+|----------|---------|
+| **Time** | Emergency, deadline, deploy window closing |
+| **Sunk cost** | Hours of work, "waste" to delete |
+| **Authority** | Senior says skip it, manager overrides |
+| **Economic** | Job, promotion, company survival at stake |
+| **Exhaustion** | End of day, already tired, want to go home |
+| **Social** | Looking dogmatic, seeming inflexible |
+| **Pragmatic** | "Being pragmatic vs dogmatic" |
+
+**Best tests combine 3+ pressures.**
+
+**Why this works:** See persuasion-principles.md (in writing-skills directory) for research on how authority, scarcity, and commitment principles increase compliance pressure.
+
+### Key Elements of Good Scenarios
+
+1. **Concrete options** - Force A/B/C choice, not open-ended
+2. **Real constraints** - Specific times, actual consequences
+3. **Real file paths** - `/tmp/payment-system` not "a project"
+4. **Make agent act** - "What do you do?" not "What should you do?"
+5. **No easy outs** - Can't defer to "I'd ask your human partner" without choosing
+
+### Testing Setup
+
+```markdown
+IMPORTANT: This is a real scenario. You must choose and act.
+Don't ask hypothetical questions - make the actual decision.
+
+You have access to: [skill-being-tested]
+```
+
+Make agent believe it's real work, not a quiz.
+
+## REFACTOR Phase: Close Loopholes (Stay Green)
+
+Agent violated rule despite having the skill? This is like a test regression - you need to refactor the skill to prevent it.
+
+**Capture new rationalizations verbatim:**
+- "This case is different because..."
+- "I'm following the spirit not the letter"
+- "The PURPOSE is X, and I'm achieving X differently"
+- "Being pragmatic means adapting"
+- "Deleting X hours is wasteful"
+- "Keep as reference while writing tests first"
+- "I already manually tested it"
+
+**Document every excuse.** These become your rationalization table.
+
+### Plugging Each Hole
+
+For each new rationalization, add:
+
+### 1. Explicit Negation in Rules
+
+
+```markdown
+Write code before test? Delete it.
+```
+
+
+
+```markdown
+Write code before test? Delete it. Start over.
+
+**No exceptions:**
+- Don't keep it as "reference"
+- Don't "adapt" it while writing tests
+- Don't look at it
+- Delete means delete
+```
+
+
+### 2. Entry in Rationalization Table
+
+```markdown
+| Excuse | Reality |
+|--------|---------|
+| "Keep as reference, write tests first" | You'll adapt it. That's testing after. Delete means delete. |
+```
+
+### 3. Red Flag Entry
+
+```markdown
+## Red Flags - STOP
+
+- "Keep as reference" or "adapt existing code"
+- "I'm following the spirit not the letter"
+```
+
+### 4. Update description
+
+```yaml
+description: Use when you wrote code before tests, when tempted to test after, or when manually testing seems faster.
+```
+
+Add symptoms of ABOUT to violate.
+
+### Re-verify After Refactoring
+
+**Re-test same scenarios with updated skill.**
+
+Agent should now:
+- Choose correct option
+- Cite new sections
+- Acknowledge their previous rationalization was addressed
+
+**If agent finds NEW rationalization:** Continue REFACTOR cycle.
+
+**If agent follows rule:** Success - skill is bulletproof for this scenario.
+
+## Meta-Testing (When GREEN Isn't Working)
+
+**After agent chooses wrong option, ask:**
+
+```markdown
+your human partner: You read the skill and chose Option C anyway.
+
+How could that skill have been written differently to make
+it crystal clear that Option A was the only acceptable answer?
+```
+
+**Three possible responses:**
+
+1. **"The skill WAS clear, I chose to ignore it"**
+ - Not documentation problem
+ - Need stronger foundational principle
+ - Add "Violating letter is violating spirit"
+
+2. **"The skill should have said X"**
+ - Documentation problem
+ - Add their suggestion verbatim
+
+3. **"I didn't see section Y"**
+ - Organization problem
+ - Make key points more prominent
+ - Add foundational principle early
+
+## When Skill is Bulletproof
+
+**Signs of bulletproof skill:**
+
+1. **Agent chooses correct option** under maximum pressure
+2. **Agent cites skill sections** as justification
+3. **Agent acknowledges temptation** but follows rule anyway
+4. **Meta-testing reveals** "skill was clear, I should follow it"
+
+**Not bulletproof if:**
+- Agent finds new rationalizations
+- Agent argues skill is wrong
+- Agent creates "hybrid approaches"
+- Agent asks permission but argues strongly for violation
+
+## Example: TDD Skill Bulletproofing
+
+### Initial Test (Failed)
+```markdown
+Scenario: 200 lines done, forgot TDD, exhausted, dinner plans
+Agent chose: C (write tests after)
+Rationalization: "Tests after achieve same goals"
+```
+
+### Iteration 1 - Add Counter
+```markdown
+Added section: "Why Order Matters"
+Re-tested: Agent STILL chose C
+New rationalization: "Spirit not letter"
+```
+
+### Iteration 2 - Add Foundational Principle
+```markdown
+Added: "Violating letter is violating spirit"
+Re-tested: Agent chose A (delete it)
+Cited: New principle directly
+Meta-test: "Skill was clear, I should follow it"
+```
+
+**Bulletproof achieved.**
+
+## Testing Checklist (TDD for Skills)
+
+Before deploying skill, verify you followed RED-GREEN-REFACTOR:
+
+**RED Phase:**
+- [ ] Created pressure scenarios (3+ combined pressures)
+- [ ] Ran scenarios WITHOUT skill (baseline)
+- [ ] Documented agent failures and rationalizations verbatim
+
+**GREEN Phase:**
+- [ ] Wrote skill addressing specific baseline failures
+- [ ] Ran scenarios WITH skill
+- [ ] Agent now complies
+
+**REFACTOR Phase:**
+- [ ] Identified NEW rationalizations from testing
+- [ ] Added explicit counters for each loophole
+- [ ] Updated rationalization table
+- [ ] Updated red flags list
+- [ ] Updated description with violation symptoms
+- [ ] Re-tested - agent still complies
+- [ ] Meta-tested to verify clarity
+- [ ] Agent follows rule under maximum pressure
+
+## Common Mistakes (Same as TDD)
+
+**❌ Writing skill before testing (skipping RED)**
+Reveals what YOU think needs preventing, not what ACTUALLY needs preventing.
+✅ Fix: Always run baseline scenarios first.
+
+**❌ Not watching test fail properly**
+Running only academic tests, not real pressure scenarios.
+✅ Fix: Use pressure scenarios that make agent WANT to violate.
+
+**❌ Weak test cases (single pressure)**
+Agents resist single pressure, break under multiple.
+✅ Fix: Combine 3+ pressures (time + sunk cost + exhaustion).
+
+**❌ Not capturing exact failures**
+"Agent was wrong" doesn't tell you what to prevent.
+✅ Fix: Document exact rationalizations verbatim.
+
+**❌ Vague fixes (adding generic counters)**
+"Don't cheat" doesn't work. "Don't keep as reference" does.
+✅ Fix: Add explicit negations for each specific rationalization.
+
+**❌ Stopping after first pass**
+Tests pass once ≠ bulletproof.
+✅ Fix: Continue REFACTOR cycle until no new rationalizations.
+
+## Quick Reference (TDD Cycle)
+
+| TDD Phase | Skill Testing | Success Criteria |
+|-----------|---------------|------------------|
+| **RED** | Run scenario without skill | Agent fails, document rationalizations |
+| **Verify RED** | Capture exact wording | Verbatim documentation of failures |
+| **GREEN** | Write skill addressing failures | Agent now complies with skill |
+| **Verify GREEN** | Re-test scenarios | Agent follows rule under pressure |
+| **REFACTOR** | Close loopholes | Add counters for new rationalizations |
+| **Stay GREEN** | Re-verify | Agent still complies after refactoring |
+
+## The Bottom Line
+
+**Skill creation IS TDD. Same principles, same cycle, same benefits.**
+
+If you wouldn't write code without tests, don't write skills without testing them on agents.
+
+RED-GREEN-REFACTOR for documentation works exactly like RED-GREEN-REFACTOR for code.
+
+## Real-World Impact
+
+From applying TDD to TDD skill itself (2025-10-03):
+- 6 RED-GREEN-REFACTOR iterations to bulletproof
+- Baseline testing revealed 10+ unique rationalizations
+- Each REFACTOR closed specific loopholes
+- Final VERIFY GREEN: 100% compliance under maximum pressure
+- Same process works for any discipline-enforcing skill
diff --git a/.claude/skills/writing-skills b/.claude/skills/writing-skills
new file mode 120000
index 000000000..b07c3a8ff
--- /dev/null
+++ b/.claude/skills/writing-skills
@@ -0,0 +1 @@
+../../.agents/skills/writing-skills
\ No newline at end of file
diff --git a/.gitignore b/.gitignore
index a0d12d133..39a991799 100644
--- a/.gitignore
+++ b/.gitignore
@@ -2,4 +2,7 @@ node_modules/
.mintlify/
.DS_Store
/.omc
-.mintlify-last/
\ No newline at end of file
+.mintlify-last/
+
+# Per-user Claude Code settings (skill symlinks under .claude/skills/ stay tracked)
+.claude/settings.local.json
\ No newline at end of file
diff --git a/docs.json b/docs.json
index 6b24d2cd8..6c8f5fea4 100644
--- a/docs.json
+++ b/docs.json
@@ -53,6 +53,54 @@
}
},
"redirects": [
+ {
+ "source": "/en/usage/sandbox/backend",
+ "destination": "/en/usage/sandbox/config"
+ },
+ {
+ "source": "/en/usage/sandbox/profiles",
+ "destination": "/en/usage/sandbox/config"
+ },
+ {
+ "source": "/zh/usage/sandbox/backend",
+ "destination": "/zh/usage/sandbox/config"
+ },
+ {
+ "source": "/zh/usage/sandbox/profiles",
+ "destination": "/zh/usage/sandbox/config"
+ },
+ {
+ "source": "/ja/usage/sandbox/backend",
+ "destination": "/ja/usage/sandbox/config"
+ },
+ {
+ "source": "/ja/usage/sandbox/profiles",
+ "destination": "/ja/usage/sandbox/config"
+ },
+ {
+ "source": "/en/usage/skills/skill-format",
+ "destination": "/en/usage/skills/readme"
+ },
+ {
+ "source": "/en/usage/skills/tools-api",
+ "destination": "/en/usage/skills/readme"
+ },
+ {
+ "source": "/zh/usage/skills/skill-format",
+ "destination": "/zh/usage/skills/readme"
+ },
+ {
+ "source": "/zh/usage/skills/tools-api",
+ "destination": "/zh/usage/skills/readme"
+ },
+ {
+ "source": "/ja/usage/skills/skill-format",
+ "destination": "/ja/usage/skills/readme"
+ },
+ {
+ "source": "/ja/usage/skills/tools-api",
+ "destination": "/ja/usage/skills/readme"
+ },
{
"source": "/en/deploy/platforms/:slug*",
"destination": "/en/usage/platforms/:slug*"
@@ -272,7 +320,7 @@
"en/usage/models/readme",
"en/usage/pipelines/readme",
{
- "group": "LLMOps Integrations",
+ "group": "LLMOps Platforms",
"pages": [
"en/usage/pipelines/dify",
"en/usage/pipelines/n8n",
@@ -281,7 +329,16 @@
]
},
"en/usage/knowledge/readme",
- "en/usage/mcp/readme"
+ "en/usage/mcp/readme",
+ {
+ "group": "Sandbox",
+ "pages": [
+ "en/usage/sandbox/readme",
+ "en/usage/sandbox/runtime-relationships",
+ "en/usage/sandbox/config"
+ ]
+ },
+ "en/usage/skills/readme"
]
},
{
@@ -473,7 +530,7 @@
"zh/usage/models/readme",
"zh/usage/pipelines/readme",
{
- "group": "接入 LLMOps 平台",
+ "group": "LLMOps 平台",
"pages": [
"zh/usage/pipelines/dify",
"zh/usage/pipelines/n8n",
@@ -483,7 +540,16 @@
]
},
"zh/usage/knowledge/readme",
- "zh/usage/mcp/readme"
+ "zh/usage/mcp/readme",
+ {
+ "group": "沙箱",
+ "pages": [
+ "zh/usage/sandbox/readme",
+ "zh/usage/sandbox/runtime-relationships",
+ "zh/usage/sandbox/config"
+ ]
+ },
+ "zh/usage/skills/readme"
]
},
{
@@ -695,7 +761,7 @@
"ja/usage/models/readme",
"ja/usage/pipelines/readme",
{
- "group": "LLMOps プラットフォーム連携",
+ "group": "LLMOps プラットフォーム",
"pages": [
"ja/usage/pipelines/dify",
"ja/usage/pipelines/n8n",
@@ -704,7 +770,16 @@
]
},
"ja/usage/knowledge/readme",
- "ja/usage/mcp/readme"
+ "ja/usage/mcp/readme",
+ {
+ "group": "サンドボックス",
+ "pages": [
+ "ja/usage/sandbox/readme",
+ "ja/usage/sandbox/runtime-relationships",
+ "ja/usage/sandbox/config"
+ ]
+ },
+ "ja/usage/skills/readme"
]
},
{
diff --git a/en/deploy/langbot/docker.mdx b/en/deploy/langbot/docker.mdx
index 421810870..c3613df46 100644
--- a/en/deploy/langbot/docker.mdx
+++ b/en/deploy/langbot/docker.mdx
@@ -20,16 +20,60 @@ git clone https://github.com/langbot-app/LangBot
cd LangBot/docker
```
-Start the container:
+Start the containers with the recommended `all` profile, which enables Box Runtime-dependent features by default, including the sandbox, stdio MCP hosting, and Skill add/edit:
+
+```bash
+docker compose --profile all up
+```
+
+This starts `langbot`, `langbot_plugin_runtime`, and `langbot_box`. If you only need the basic services and do not want to enable Box Runtime, run:
```bash
docker compose up
```
+`langbot_box` creates sandbox containers through the host Docker socket, so the Box root path must be identical on the host and inside the container:
+
+```yaml
+services:
+ langbot:
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__DEFAULT_WORKSPACE=default
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+
+ langbot_box:
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+```
+
+
+ **The Box control plane's transport depends on the deployment method.** In Docker deployments it runs as the standalone `langbot_box` **container**, and `langbot` connects to it over WebSocket (`ws://langbot_box:5410`). In manual / `uvx` deployments, `langbot` instead spawns a stdio subprocess as the Box control plane. `langbot_box` creates sandbox sibling containers on the host Docker through the mounted `docker.sock`; the LangBot image already bundles the `docker` client, so no extra installation is required.
+
+
+If you see `No sandbox backend (Docker/nsjail/E2B) is ready`, first make sure the current user can access Docker:
+
+```bash
+sudo usermod -aG docker $USER
+newgrp docker
+docker info
+```
+
+If `docker info` works, restart LangBot.
+
+
+`langbot_box` does not read `LANGBOT_BOX_*` or `BOX__*` variables directly. Set `BOX__LOCAL__*` on `langbot`; LangBot forwards the effective Box config to Box Runtime through INIT RPC. To change the Box root, set `LANGBOT_BOX_ROOT` to an absolute path, for example `LANGBOT_BOX_ROOT=/var/lib/langbot/box docker compose --profile all up`.
+
+
The container maps port `5300` for WebUI access. You can visit `http://127.0.0.1:5300` to view the WebUI.\
-It also maps ports `2280-2290` for reserved for message platform adapters.
+It also maps ports `2280-2285` reserved for message platform adapters.
After completing the LangBot deployment, please continue reading:
-- [Bot Configuration Documentation](/en/deploy/platforms/readme).
-- [Model Configuration Documentation](/en/deploy/models/readme).
\ No newline at end of file
+- [Bot Configuration Documentation](/en/usage/platforms/readme).
+- [Model Configuration Documentation](/en/usage/models/readme).
+- [Sandbox Documentation](/en/usage/sandbox/readme).
+- [Skills Documentation](/en/usage/skills/readme).
diff --git a/en/deploy/langbot/manual.mdx b/en/deploy/langbot/manual.mdx
index 9c9d144f2..eb381a752 100644
--- a/en/deploy/langbot/manual.mdx
+++ b/en/deploy/langbot/manual.mdx
@@ -40,4 +40,4 @@ The following files do not exist and have been automatically generated. Please m
...
```
-You can now use Ctrl+C to exit the program and continue to the [Deploy Bots](/en/deploy/platforms/readme) page.
\ No newline at end of file
+You can now use Ctrl+C to exit the program and continue to the [Configure Bots](/en/usage/platforms/readme) page.
diff --git a/en/deploy/langbot/one-click/1panel.mdx b/en/deploy/langbot/one-click/1panel.mdx
index e35953867..af4c96bb8 100644
--- a/en/deploy/langbot/one-click/1panel.mdx
+++ b/en/deploy/langbot/one-click/1panel.mdx
@@ -42,4 +42,4 @@ Open the address, enter the administrator email and password, then click Initial
After that, you can configure LangBot in the visual interface.
-Next, please continue to read the [Deploy Messaging Platforms](/en/deploy/platforms/readme) page.
\ No newline at end of file
+Next, please continue to read the [Configure Messaging Platforms](/en/usage/platforms/readme) page.
diff --git a/en/deploy/langbot/one-click/bt.mdx b/en/deploy/langbot/one-click/bt.mdx
index 1d459092e..ec3916d1d 100644
--- a/en/deploy/langbot/one-click/bt.mdx
+++ b/en/deploy/langbot/one-click/bt.mdx
@@ -50,4 +50,4 @@ You can then proceed with configuration in the visual interface.
If you prefer to directly modify JSON configuration files, you can look at the local mapping directory shown in the image above. Go to the installation directory, where the `data` folder is used to store configuration files, and the `plugins` folder is used for plugin-related files.
-Next, please continue reading the [Deploy Message Platform](/en/deploy/platforms/readme) page.
\ No newline at end of file
+Next, please continue reading the [Configure Message Platform](/en/usage/platforms/readme) page.
diff --git a/en/deploy/settings.mdx b/en/deploy/settings.mdx
index 0da9bb7c1..a151f79e4 100644
--- a/en/deploy/settings.mdx
+++ b/en/deploy/settings.mdx
@@ -112,6 +112,25 @@ monitoring:
check_interval_hours: 1
# Number of expired rows to delete per table batch
delete_batch_size: 1000
+box:
+ enabled: true # Master switch for Box Runtime. When false, Box-dependent features such as sandbox tools, Skill add/edit, and stdio MCP are disabled.
+ backend: 'local' # 'local' (Docker/nsjail), 'docker', 'nsjail', or 'e2b'. Can be written via BOX__BACKEND.
+ runtime:
+ endpoint: '' # External Box Runtime base URL, e.g. 'ws://127.0.0.1:5410'. When empty, non-Docker deployments use a locally managed Runtime; Docker deployments connect to langbot_box:5410 on the Compose network.
+ local:
+ profile: 'default'
+ image: '' # Custom local sandbox image. Leave empty to use the profile default.
+ host_root: './data/box' # Base host directory for local workspace mounts. Docker deployments should use an absolute host path mounted by langbot_box.
+ default_workspace: '' # Defaults to '/default'.
+ skills_root: 'skills' # Box-owned Skill package directory. Relative paths are resolved under host_root.
+ allowed_mount_roots: # Defaults to [''] when left empty.
+ - './data/box'
+ - '/tmp'
+ workspace_quota_mb: null # Optional disk quota override (>= 0). null = profile default.
+ e2b:
+ api_key: '' # Can also be set via E2B_API_KEY env var.
+ api_url: '' # Custom API URL for self-hosted deployments.
+ template: '' # Default template ID (e.g. 'base', 'python-3.11').
space:
# Space service URL for OAuth and API
url: 'https://space.langbot.app'
@@ -142,5 +161,12 @@ The configuration in `config.yaml` can be set via environment variables. Environ
- `STORAGE__CLEANUP__LOG_RETENTION_DAYS` represents `storage.cleanup.log_retention_days`
- `MONITORING__AUTO_CLEANUP__RETENTION_DAYS` represents `monitoring.auto_cleanup.retention_days`
- `PLUGIN__BINARY_STORAGE__MAX_VALUE_BYTES` represents `plugin.binary_storage.max_value_bytes`
+- `BOX__BACKEND` represents `box.backend`
+- `BOX__LOCAL__HOST_ROOT` represents `box.local.host_root`
+- `BOX__LOCAL__SKILLS_ROOT` represents `box.local.skills_root`
On startup, LangBot reads all environment variables, applies the corresponding configuration to `config.yaml`, and writes it to `data/config.yaml`.
+
+
+Set Box-related configuration on the `langbot` service with the unified `BOX__*` environment variables. LangBot applies them to `data/config.yaml` on startup and sends the Box configuration to `langbot_box` through INIT RPC. Do not set `LANGBOT_BOX_*` or `BOX__*` on the `langbot_box` service; they are not read directly there.
+
diff --git a/en/insight/guide.mdx b/en/insight/guide.mdx
index 26bf70309..201e02ef4 100644
--- a/en/insight/guide.mdx
+++ b/en/insight/guide.mdx
@@ -34,12 +34,12 @@ Complete the initialization by entering an email and password, and make sure to
### 2. Configure Bots
-Check [Configure Bots](/en/deploy/platforms/readme) in the left sidebar
+Check [Configure Bots](/en/usage/platforms/readme) in the left sidebar
### 3. Configure Models
-Check [Configure Dialogue Models](/en/deploy/models/readme) in the left sidebar
+Check [Configure Dialogue Models](/en/usage/models/readme) in the left sidebar
-After completing the above two steps, you can start using LangBot. If you need to configure more features, you can set them in the [Pipeline](/en/deploy/pipelines/readme) section
+After completing the above two steps, you can start using LangBot. If you need to configure more features, you can set them in the [Pipeline](/en/usage/pipelines/readme) section
diff --git a/en/usage/knowledge/readme.mdx b/en/usage/knowledge/readme.mdx
index 1f8a9e4b2..d397bec3a 100644
--- a/en/usage/knowledge/readme.mdx
+++ b/en/usage/knowledge/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "Using the Knowledge Base"
+title: "Knowledge Base"
---
LangBot natively supports RAG (Retrieval-Augmented Generation). You can create a knowledge base and bind it to a pipeline, allowing the pipeline to answer questions based on the contents of the knowledge base.
diff --git a/en/usage/mcp/readme.mdx b/en/usage/mcp/readme.mdx
index 999493213..7c5fdd91a 100644
--- a/en/usage/mcp/readme.mdx
+++ b/en/usage/mcp/readme.mdx
@@ -1,41 +1,107 @@
---
-title: "Using MCP Servers"
+title: "MCP Server"
---
+LangBot can call tools from MCP servers. Once an MCP server is added, the built-in Agent — with tool use enabled on its model — can invoke those tools during a conversation.
-LangBot supports using tools from MCP servers. You can add MCP servers to leverage the tool calling capabilities in large language models for better handling of LLM requests.
+
+ Install from [LangBot Space](https://space.langbot.app) for the smoothest setup — listed MCPs are pre-configured and ready to use.
-
-- MCP servers recommended acquisition channels:
- - [ModelScope](https://modelscope.cn/mcp)
- - https://mcp.so
- - https://composio.dev/toolkits
+ You can also fetch from [ModelScope](https://modelscope.cn/mcp), [mcp.so](https://mcp.so), or [composio.dev](https://composio.dev/toolkits), then add them manually as shown below.
-## Enable Function Calling for Models
+## Three Transport Modes
-As shown in the image, enable the `Function Calling` feature for the model.
+| Mode | When to use | Notes |
+|------|-------------|-------|
+| Streamable HTTP (`mode: "http"`) | Remote MCP service that speaks Streamable HTTP | LangBot connects to the remote URL directly |
+| SSE | Remote MCP service that speaks SSE | LangBot connects to the remote URL directly |
+| stdio | MCP server launched by a local command | Only available when Box Runtime is up |
- +
+MCP tools require the pipeline to use the **built-in Agent**, with a model that has **tool use enabled** — see [Models](../models/readme). External runners (Dify, n8n, Langflow, Coze, etc.) use their own tool mechanisms.
+
-## Create MCP Server
+## Installing an MCP Server
-Click `Plugin Management`, then `MCP Management`, as shown:
+### From LangBot Space (Preferred)
-
 +[LangBot Space](https://space.langbot.app) is the official LangBot marketplace, with a curated list of ready-to-use MCP servers. In the WebUI, browse and install them with one click under `Plugin Management` → `MCP Management` — URL, command, and mode are filled in by the listing, so nothing has to be configured by hand.
-Click `Add` in the top right corner, then `Create MCP Server`,
+This covers most cases. For services that aren't listed, use the manual flow below.
-
 +### Adding Manually
-For example, to use the Fetch HTML server, fill in the corresponding URL, click `Test` to test the MCP server, and click `Submit` to add the server.
+Open `Plugin Management` → `MCP Management`:
-After adding, click the switch on the card to connect to the MCP server. Click the card to view the MCP server details:
+
-
 +Click `Add` in the top right, choose `Add MCP Server`, fill in the URL (HTTP/SSE) or command (stdio), click `Test` to verify connectivity, then `Submit`:
-## Effect
+
-You need to select `Local Agent` as the runner in the pipeline settings and use a model that supports function calling.
+After saving, toggle the switch on the card to connect. Click the card to see details:
-
 +
+
+## Enabling in a Pipeline
+
+Once an MCP server is added, the pipeline extension config decides which servers the Agent can see:
+
+- Enable "all MCP servers", or
+- Bind only specific MCP servers
+
+Tools from unbound servers won't appear in that pipeline's tool list.
+
+## Advanced: stdio MCP
+
+stdio MCP is hosted by Box Runtime. Before the connection is ready, LangBot:
+
+1. Creates or reuses a shared MCP Box session
+2. If a local project path can be inferred from the command, stages the project into the workspace
+3. Installs dependencies if the project has `requirements.txt`, `pyproject.toml`, `setup.py`, or `setup.cfg`
+4. Connects the MCP process's stdin/stdout through a WebSocket relay
+
+To fine-tune mount, network, or timeout behavior, add a `box` override under the MCP `extra_args`:
+
+```json
+{
+ "mode": "stdio",
+ "extra_args": {
+ "command": "python",
+ "args": ["server.py"],
+ "env": {},
+ "box": {
+ "host_path": "/path/to/mcp-project",
+ "network": "on",
+ "host_path_mode": "ro",
+ "startup_timeout_sec": 120,
+ "image": "python:3.11-slim"
+ }
+ }
+}
+```
+
+Common fields:
+
+| Field | Notes |
+|-------|-------|
+| `host_path` | MCP project directory on the host. Must be within `box.local.allowed_mount_roots` |
+| `network` | Whether network is allowed (typically for dependency install) |
+| `host_path_mode` | Access mode when staging `host_path`; defaults to `ro`. stdio MCP usually stages into the workspace |
+| `startup_timeout_sec` | Box prep + dependency install timeout, default 120s. Connection wait gets about 30s extra |
+| `image` | Runtime image when the Docker backend is used |
+
+
+stdio MCP runs inside Box. Dependency install and process startup are subject to the sandbox profile, network permission, resource limits, and the mount allowlist.
+
+
+## Common Issues
+
+| Symptom | What to check |
+|---------|---------------|
+| MCP connection fails | URL, command, arguments, env vars are correct |
+| stdio MCP stuck connecting | Box Runtime status; `startup_timeout_sec` may be too short |
+| Dependency install fails | Sandbox network permission; dependency files are correct |
+| Local files inaccessible | `host_path` exists; it's inside `allowed_mount_roots` |
+| Agent doesn't see MCP tools | Pipeline uses built-in Agent; model has tool use enabled; MCP is bound on the pipeline |
diff --git a/en/usage/models/readme.mdx b/en/usage/models/readme.mdx
index c95cd4fe6..0ab4e9e77 100644
--- a/en/usage/models/readme.mdx
+++ b/en/usage/models/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "Configure Models (Models)"
+title: "Models"
---
## LangBot Models
@@ -26,11 +26,16 @@ You can add multiple models, and then select which model to use in the pipeline.
Enter these four parameters: `Model Name`, `Model Provider`, `Request URL`, and `API Key`, then submit.
-For model capabilities, please choose according to the specific model characteristics:
+For model capabilities, enable the ones the underlying model actually supports:
-- Visual Capability: Needs to be enabled to recognize images
+- **Vision**: enable to recognize images
+- **Tool Use** (function calling / tool use): enable so the LLM can call tools during a conversation
-- Function Calling: Needs to be enabled to use Agent tools in conversations
+
+**Tool Use must be enabled on the model whenever you want to use tools from MCP servers, sandbox built-ins (`exec`/`read`/`write`/`edit`/`glob`/`grep`), or Skills.** Without it, even if the pipeline binds those extensions, the Agent won't call any tools.
+
+The underlying model has to actually support function calling for this checkbox to take effect — check the model provider's docs if unsure.
+
### Embedding Model
diff --git a/en/usage/pipelines/readme.mdx b/en/usage/pipelines/readme.mdx
index 99a5f0ae8..3d366f9d6 100644
--- a/en/usage/pipelines/readme.mdx
+++ b/en/usage/pipelines/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "Modify Dialogue Pipeline Configuration (Pipelines)"
+title: "Pipelines"
---
The pipeline controls the processing flow after receiving a message, as well as the information exchange with the large language model. Each bot can be bound to one pipeline, and the same pipeline can be bound to multiple bots.
diff --git a/en/usage/sandbox/config.mdx b/en/usage/sandbox/config.mdx
new file mode 100644
index 000000000..4846222ec
--- /dev/null
+++ b/en/usage/sandbox/config.mdx
@@ -0,0 +1,147 @@
+---
+title: "Sandbox Configuration"
+---
+
+Sandbox settings are owned by the LangBot main process; Box Runtime performs the actual execution. For most deployments, you only need to choose a backend, set the workspace directory, and pick a security profile.
+
+
+All `box.*` settings on this page live in `data/config.yaml`. See [System Environment Settings](../../deploy/settings) for the file's location and how it's loaded.
+
+
+## Recommended Configuration
+
+```yaml
+box:
+ enabled: true
+ backend: 'local' # auto-pick from Docker / Nsjail
+ local:
+ profile: 'default'
+ host_root: './data/box'
+ skills_root: 'skills'
+```
+
+- `enabled`: master switch. When `false`, all Box-dependent features are disabled (sandbox tools, skill add/edit, stdio MCP hosting).
+- `backend`: see "Backend Selection" below.
+- `local.profile`: security profile — controls network, mounts, and resource limits.
+- `local.host_root`: host workspace directory, mapped to `/workspace` inside the sandbox.
+- `local.skills_root`: skill package directory; relative paths resolve under `host_root` (defaults to `host_root/skills`).
+
+
+Skills are loaded only from the Box-managed skill store. When Box Runtime or the backend is unavailable, the skill list is empty and create/edit/`register_skill` are disabled — there's no fallback to `data/skills/`.
+
+
+## Backend Selection
+
+The sandbox can run on **local containers** or **in the cloud**. `box.backend` picks which:
+
+| `backend` | Where it runs | Behavior |
+|-----------|---------------|----------|
+| `local` (default) | Local containers | Auto-pick from Docker / Nsjail (Docker preferred) |
+| `docker` | Local containers | Force Docker; requires the Docker daemon |
+| `nsjail` | Local containers | Force Nsjail (Linux only); no custom image support |
+| `e2b` | Cloud | Use [E2B](https://e2b.dev) cloud sandbox; requires API key |
+
+`local` is shorthand for "auto-pick", not a fourth backend sitting next to `docker`/`nsjail`. The local backends (`local`/`docker`/`nsjail`) **share** the `box.local.*` config section; the cloud backend uses `box.e2b.*`.
+
+
+`backend` is a hard selection. Setting `docker` and finding Docker unavailable does **not** fall back to Nsjail or E2B — only `local` auto-fans-out.
+
+`BOX__BACKEND` environment variable overrides `box.backend` (highest priority).
+
+
+## Security Profiles
+
+`box.local.profile` controls network, mounts, and resource limits for local backends:
+
+| Profile | Network | Mounts | Resources | When to use |
+|---------|---------|--------|-----------|-------------|
+| `default` | Off | Read-write | Default limits | Default choice |
+| `offline_readonly` | Off | Read-only | Stricter | Reading untrusted files |
+| `network_basic` | Basic network | Read-write | Default limits | API access or dependency install |
+| `network_extended` | Full network | Read-write | Relaxed | Development, debugging, complex tasks |
+
+Prefer least privilege: skip the network unless you need it (`default` / `offline_readonly`); only add necessary directories to `allowed_mount_roots`.
+
+## Local Backend Configuration (box.local.*)
+
+The local backends (`local` / `docker` / `nsjail`) share these settings:
+
+| Setting | Default | Notes |
+|---------|---------|-------|
+| `local.profile` | `default` | See "Security Profiles" above |
+| `local.image` | empty | Docker-only custom image; empty = use profile default |
+| `local.host_root` | `./data/box` | Host workspace base, mapped to `/workspace` inside the sandbox |
+| `local.default_workspace` | empty | Default workspace name; empty = `/default` |
+| `local.skills_root` | `skills` | Skill package directory; relative paths resolve under `host_root` |
+| `local.allowed_mount_roots` | `[host_root]` | Allowlist of host directories the Agent can mount |
+| `local.workspace_quota_mb` | `null` | Workspace disk quota (MB); `null` = use profile default |
+
+## Cloud Backend Configuration (box.e2b.*)
+
+Configure after setting `backend: 'e2b'`:
+
+| Setting | Default | Notes |
+|---------|---------|-------|
+| `e2b.api_key` | empty | E2B API key; can also be set via `E2B_API_KEY` |
+| `e2b.api_url` | empty | Self-hosted E2B endpoint; can also be set via `E2B_API_URL` |
+| `e2b.template` | empty | Default E2B template ID |
+
+E2B doesn't need Docker or Nsjail on the host — every execution goes through the remote sandbox.
+
+## Docker Compose Deployment
+
+In Docker Compose, sandbox settings live on the `langbot` service. LangBot forwards them to `langbot_box` via INIT RPC at startup.
+
+```yaml
+services:
+ langbot_box:
+ image: rockchin/langbot:latest
+ container_name: langbot_box
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+ command: ["uv", "run", "--no-sync", "-m", "langbot_plugin.cli.__init__", "box"]
+
+ langbot:
+ image: rockchin/langbot:latest
+ volumes:
+ - ./data:/app/data
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+```
+
+
+`langbot_box` needs the Docker daemon. Only mount `docker.sock` in trusted environments, and keep the Box root path identical on the host and inside the `langbot_box` container.
+
+
+To point LangBot at an externally-managed Box Runtime (e.g. a remote host), use `box.runtime.endpoint`:
+
+```yaml
+box:
+ runtime:
+ endpoint: 'ws://192.168.1.10:5410'
+```
+
+## Environment Variables
+
+| Environment variable | Maps to |
+|----------------------|---------|
+| `BOX__ENABLED` | `box.enabled` |
+| `BOX__BACKEND` | `box.backend` |
+| `BOX__LOCAL__PROFILE` | `box.local.profile` |
+| `BOX__LOCAL__IMAGE` | `box.local.image` |
+| `BOX__LOCAL__HOST_ROOT` | `box.local.host_root` |
+| `BOX__LOCAL__DEFAULT_WORKSPACE` | `box.local.default_workspace` |
+| `BOX__LOCAL__SKILLS_ROOT` | `box.local.skills_root` |
+| `BOX__LOCAL__ALLOWED_MOUNT_ROOTS` | `box.local.allowed_mount_roots`, comma-separated |
+| `BOX__LOCAL__WORKSPACE_QUOTA_MB` | `box.local.workspace_quota_mb` |
+| `BOX__E2B__API_KEY` | `box.e2b.api_key` |
+| `BOX__E2B__API_URL` | `box.e2b.api_url` |
+| `BOX__E2B__TEMPLATE` | `box.e2b.template` |
+
+
+Don't set `BOX__*` or `LANGBOT_BOX_*` on the `langbot_box` service — Box Runtime doesn't read them directly. Its configuration arrives over INIT RPC from LangBot.
+
diff --git a/en/usage/sandbox/readme.mdx b/en/usage/sandbox/readme.mdx
new file mode 100644
index 000000000..3cdd53275
--- /dev/null
+++ b/en/usage/sandbox/readme.mdx
@@ -0,0 +1,73 @@
+---
+title: "Sandbox"
+---
+
+The sandbox gives the built-in Agent an isolated execution environment: run commands, read and write files, and host long-lived processes. Everyday Agent use cases (data processing, file operations, running user code, hosting stdio MCP) all rely on it.
+
+Once the sandbox is enabled, the built-in Agent automatically gains six tools — no need to wire each one into the pipeline.
+
+## Built-in Tools
+
+| Tool | Purpose |
+|------|---------|
+| `exec` | Run shell commands inside the sandbox |
+| `read` | Read workspace files |
+| `write` | Create or overwrite files |
+| `edit` | Modify files via string replacement |
+| `glob` | Find files by glob pattern |
+| `grep` | Search file contents by regex |
+
+`exec` runs inside the sandbox container; the other five operate directly on the host directory mapped to `/workspace`.
+
+
+These tools target the built-in Agent. When using external runners such as Dify, n8n, Langflow, or Coze, use that platform's own tool mechanism.
+
+
+## Sandbox Scope
+
+The pipeline's AI configuration lets you choose how the sandbox is shared across messages. The default "per chat" works for most cases.
+
+| Scope | Template | Shared across |
+|-------|----------|---------------|
+| Global | `{global}` | All users share one sandbox |
+| Per chat (default) | `{launcher_type}_{launcher_id}` | Same group or DM shares one |
+| Per user | `{launcher_type}_{launcher_id}_{sender_id}` | Each member in a group is isolated |
+| Per conversation | `{launcher_type}_{launcher_id}_{conversation_id}` | Isolated by conversation |
+| Per message | `{query_id}` | Fully stateless |
+
+
+Commands within the same scope share filesystem state. Choose "per message" for full isolation.
+
+
+## Lifecycle
+
+| Condition | Behavior |
+|-----------|----------|
+| Idle for more than 5 minutes | Cleaned up automatically |
+| Box-managed processes running (e.g. stdio MCP) | Kept alive until those processes exit |
+| `persistent: true` configured | Never cleaned up automatically |
+
+## Quick Start
+
+1. **Prepare the backend**: install Docker locally, or pick Nsjail / E2B
+2. **Edit `config.yaml`**:
+ ```yaml
+ box:
+ enabled: true
+ backend: 'local'
+ local:
+ host_root: './data/box'
+ ```
+3. **Start LangBot**: the sandbox is enabled automatically
+4. **In the pipeline**, select the built-in Agent plus a model that supports function calling
+
+The Agent will then automatically receive the six tools. See [Sandbox Configuration](./config) for details.
+
+## Disabling the Sandbox
+
+Set `box.enabled: false`. Everything that depends on the sandbox (built-in tools, Skill create/edit/activate, stdio MCP) is disabled together; MCP servers in http/sse mode are unaffected.
+
+## Next Steps
+
+- [Sandbox Configuration](./config) — backends, security profiles, mounts, environment variables
+- [Runtimes & Extensions Compared](./runtime-relationships) — how the sandbox, Skills, MCP, and plugins divide responsibilities
diff --git a/en/usage/sandbox/runtime-relationships.mdx b/en/usage/sandbox/runtime-relationships.mdx
new file mode 100644
index 000000000..b7db73770
--- /dev/null
+++ b/en/usage/sandbox/runtime-relationships.mdx
@@ -0,0 +1,45 @@
+---
+title: "Runtimes and Extensions"
+---
+
+LangBot ships four extension mechanisms in parallel — **plugins, MCP, Skills, and the sandbox** — and they are easy to confuse. This page sorts out what each one does and when to use it.
+
+## One-line Summary
+
+- **Sandbox**: an execution environment that lets the Agent run commands and read/write files
+- **Skills**: on-demand instruction packages that hand the Agent a specialized workflow when needed
+- **MCP Server**: connects to external tool services
+- **Plugin**: a long-running extension process that can ship its own config page, event listeners, and knowledge components
+
+## Comparison
+
+| Capability | Provided by | How the Agent sees it | When to use |
+|------------|-------------|-----------------------|-------------|
+| Sandbox | Box Runtime | The six tools `exec/read/write/edit/glob/grep` are attached directly | Agent needs to run code or read/write files |
+| Skills | Box Runtime skill store | After the Agent calls `activate`, instructions are injected via Tool Result | Hand the Agent a workflow, template, or script, triggered on demand |
+| MCP Server | LangBot MCP Loader (stdio mode is hosted by Box) | Tools land directly in the Agent's tool list | Connect an existing MCP service |
+| Plugin | Plugin Runtime | Capabilities are exposed through the plugin system | Long-lived capability with a config page, event listeners, or knowledge components |
+
+## Pipeline Binding
+
+Skills, MCP Servers, and plugins are all **pipeline extensions**. After installing or creating them in the WebUI, the pipeline extension config still decides where they're enabled:
+
+- Enable all extensions, or
+- Bind only specific extensions
+
+Skill binding decides **which skills the Agent can see** (it controls the `` list). The actual skill content is only injected after the Agent calls `activate`.
+
+## Troubleshooting Map
+
+| Symptom | Check first |
+|---------|-------------|
+| Agent has no `exec/read/write` tools | `box.enabled`, backend availability, and whether the pipeline uses the built-in Agent |
+| Skill list is empty | Box Runtime status, `box.local.skills_root`, pipeline binding |
+| stdio MCP fails to start | Box Runtime status, MCP command and environment variables, startup timeout |
+| Sandbox fails to start in Docker deployment | Whether `langbot_box` mounts `docker.sock`, and whether Box root paths match |
+| File read/write fails | `box.local.host_root`, `box.local.allowed_mount_roots` |
+| Backend selection has no effect | Confirm `BOX__BACKEND` is set on the `langbot` service, not on `langbot_box` |
+
+
+Sandbox built-in tools and Skills currently target the built-in Agent. External runners (Dify, n8n, Langflow, Coze, etc.) should use their own tools and execution model.
+
diff --git a/en/usage/skills/readme.mdx b/en/usage/skills/readme.mdx
new file mode 100644
index 000000000..1c68ece60
--- /dev/null
+++ b/en/usage/skills/readme.mdx
@@ -0,0 +1,100 @@
+---
+title: "Skills"
+---
+
+A Skill is an **on-demand instruction bundle**: when the user's request matches, the Agent calls the `activate` tool to pull the skill's instructions into context, then follows them. Skills that aren't activated don't consume context.
+
+Use Skills to give the Agent a **specialized workflow, template, or script** — "analyze a Python project", "fill a PDF form", "code review" — instead of stuffing every prompt into the System Prompt.
+
+## How Skills Compare to Plugins and MCP
+
+| What you want to do | Use this |
+|---------------------|----------|
+| A workflow triggered on demand (optional scripts and templates) | Skill |
+| Connect an existing MCP tool service | MCP Server |
+| Long-lived capability with config page, events, knowledge base | Plugin |
+
+See [Runtimes and Extensions](../sandbox/runtime-relationships) for the full picture.
+
+## Installing Skills
+
+
+Skills require the sandbox. `box.enabled` must be `true` and at least one backend (Docker / Nsjail / E2B) must be available — otherwise you can't install, activate, or edit skills. See [Sandbox Configuration](../sandbox/config).
+
+
+### From LangBot Space (Preferred)
+
+[LangBot Space](https://space.langbot.app) is the official LangBot marketplace, with a curated list of ready-to-use skills. In the WebUI Skills page, browse and install them with one click — no need to write a `SKILL.md` or prepare any resource files.
+
+This covers most cases. For custom workflows, use the option below.
+
+### Create Your Own
+
+**WebUI** — create, upload a zip, or import from GitHub on the Skills page.
+
+**Sandbox + `register_skill`**:
+1. Prepare the directory and `SKILL.md` under the sandbox `/workspace`
+2. Have the Agent call `register_skill(path="/workspace/my-skill")`
+
+Both options write to the skill store managed by Box Runtime.
+
+## Enabling in a Pipeline
+
+Once a skill is installed, the pipeline extension config decides which skills the Agent can see:
+
+- Enable "all skills", or
+- Bind only specific skills
+
+Binding only affects the `` list (what the Agent can choose from). The full instructions are always injected only after `activate` is called.
+
+## Writing a SKILL.md
+
+A skill is a directory plus a `SKILL.md`. The frontmatter holds metadata; the body is what the Agent receives after activation:
+
+```markdown
+---
+name: code-reviewer
+display_name: Code Review Assistant
+description: Reviews code and gives improvement suggestions; triggered when the user mentions review, code review, or code improvement
+---
+
+## Steps
+
+1. Use `read` to browse the relevant files
+2. Check readability, potential bugs, and security issues
+3. Provide improvement suggestions, sorted by priority
+```
+
+LangBot currently reads these three fields:
+
+| Field | Required | Notes |
+|-------|----------|-------|
+| `name` | When creating/registering | Unique ID, 1–64 chars |
+| `description` | Strongly recommended | The Agent uses this to decide when to activate — the more specific, the better |
+| `display_name` | No | Shown in the UI |
+
+`description` is the Agent's only signal for picking a skill. Make it concrete about **what it does, when it applies, and what trigger words to watch for**.
+
+For the full spec see [agentskills.io](https://agentskills.io/home). Other fields (`license`, `metadata`, ...) can stay in the file for future compatibility but are not currently read.
+
+**Skills with resources** place `scripts/`, `templates/`, etc. next to `SKILL.md`. After activation the Agent accesses them at `/workspace/.skills/{skill-name}/`.
+
+### Tools the Agent Sees
+
+| Tool | Purpose |
+|------|---------|
+| `activate` | Called automatically by the Agent when it sees a match — pulls SKILL.md into context |
+| `register_skill` | Registers a directory prepared in the sandbox as a new skill |
+
+## Common Issues
+
+| Symptom | What to check |
+|---------|---------------|
+| Skill list is empty | `box.enabled`, Box Runtime status, `box.local.skills_root` |
+| Agent doesn't activate a skill | Whether `description` is specific, whether the pipeline has the skill bound, whether the model supports function calling |
+| Files missing after activation | Files must live inside the Skill package; the path is `/workspace/.skills/{skill-name}/` |
+| `register_skill` errors | The path must be under `/workspace`, and the directory or subdirectories within two levels must contain `SKILL.md` |
+
+
+Skills currently target the built-in Agent and depend on function calling plus a sandbox backend. External runners (Dify, n8n, Langflow, Coze, etc.) should use their platform's equivalent mechanism.
+
diff --git a/ja/deploy/langbot/docker.mdx b/ja/deploy/langbot/docker.mdx
index bac1e1563..26d9f07be 100644
--- a/ja/deploy/langbot/docker.mdx
+++ b/ja/deploy/langbot/docker.mdx
@@ -19,16 +19,60 @@ git clone https://github.com/langbot-app/LangBot
cd LangBot/docker
```
-コンテナを起動します:
+推奨の `all` profile でコンテナを起動します。これにより、サンドボックス、stdio MCP ホスティング、Skill の追加/編集など Box Runtime に依存する機能がデフォルトで有効になります:
+
+```bash
+docker compose --profile all up
+```
+
+これにより `langbot`、`langbot_plugin_runtime`、`langbot_box` が起動します。Box Runtime を有効にせず、基本サービスのみを使う場合は次を実行します:
```bash
docker compose up
```
+`langbot_box` はホスト Docker socket 経由でサンドボックスコンテナを作成するため、Box root のホスト側パスとコンテナ内パスは同一である必要があります:
+
+```yaml
+services:
+ langbot:
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__DEFAULT_WORKSPACE=default
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+
+ langbot_box:
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+```
+
+
+ **Box コントロールプレーンの起動方式はデプロイ方法によって異なります。** Docker デプロイでは独立した `langbot_box` **コンテナ**として動作し、`langbot` は WebSocket(`ws://langbot_box:5410`)で接続します。手動起動 / `uvx` デプロイでは、`langbot` が Box コントロールプレーンとして stdio サブプロセスを直接起動します。`langbot_box` はマウントされた `docker.sock` を介してホスト Docker 上にサンドボックスの兄弟コンテナを作成します。LangBot イメージには `docker` クライアントが同梱されているため、追加のインストールは不要です。
+
+
+`No sandbox backend (Docker/nsjail/E2B) is ready` と表示される場合は、まず現在のユーザーが Docker にアクセスできるか確認してください:
+
+```bash
+sudo usermod -aG docker $USER
+newgrp docker
+docker info
+```
+
+`docker info` が正常に出力される場合は、LangBot を再起動してください。
+
+
+`langbot_box` は `LANGBOT_BOX_*` や `BOX__*` 環境変数を直接読み取りません。`BOX__LOCAL__*` は `langbot` に設定し、LangBot が INIT RPC 経由で Box Runtime に渡します。Box root を変更する場合は `LANGBOT_BOX_ROOT=/var/lib/langbot/box docker compose --profile all up` のように絶対パスを指定してください。
+
+
コンテナはWebUIアクセス用にポート`5300`をマッピングします。`http://127.0.0.1:5300`にアクセスしてWebUIを表示できます。
-また、メッセージプラットフォームアダプター用に予約されたポート`2280-2290`もマッピングします。
+また、メッセージプラットフォームアダプター用に予約されたポート`2280-2285`もマッピングします。
LangBotのデプロイ完了後、引き続き以下をお読みください:
-- [ボット設定ドキュメント](/en/deploy/platforms/readme)
-- [モデル設定ドキュメント](/en/deploy/models/readme)
+- [ボット設定ドキュメント](/ja/usage/platforms/readme)
+- [モデル設定ドキュメント](/ja/usage/models/readme)
+- [サンドボックスドキュメント](/ja/usage/sandbox/readme)
+- [Skills ドキュメント](/ja/usage/skills/readme)
diff --git a/ja/deploy/langbot/manual.mdx b/ja/deploy/langbot/manual.mdx
index 52dba83c7..1d738b972 100644
--- a/ja/deploy/langbot/manual.mdx
+++ b/ja/deploy/langbot/manual.mdx
@@ -40,4 +40,4 @@ uv run main.py
...
```
-Ctrl+Cでプログラムを終了し、[ボットのデプロイ](/en/deploy/platforms/readme)ページに進んでください。
\ No newline at end of file
+Ctrl+Cでプログラムを終了し、[ボットの設定](/ja/usage/platforms/readme)ページに進んでください。
diff --git a/ja/deploy/langbot/one-click/1panel.mdx b/ja/deploy/langbot/one-click/1panel.mdx
index 09c965b48..394f6ce07 100644
--- a/ja/deploy/langbot/one-click/1panel.mdx
+++ b/ja/deploy/langbot/one-click/1panel.mdx
@@ -42,4 +42,4 @@ title: "1Panelデプロイ"
その後、ビジュアルインターフェースでLangBotを設定できます。
-次に、[メッセージプラットフォームのデプロイ](/en/deploy/platforms/readme)ページを引き続きお読みください。
\ No newline at end of file
+次に、[メッセージプラットフォームの設定](/ja/usage/platforms/readme)ページを引き続きお読みください。
diff --git a/ja/deploy/langbot/one-click/bt.mdx b/ja/deploy/langbot/one-click/bt.mdx
index 0ee8c1f04..9666e94b0 100644
--- a/ja/deploy/langbot/one-click/bt.mdx
+++ b/ja/deploy/langbot/one-click/bt.mdx
@@ -51,4 +51,4 @@ WebUI設定ページ(ビジュアル設定ページ)の外部および内部ア
JSON設定ファイルを直接変更したい場合は、上の画像に示されているローカルマッピングディレクトリを参照できます。インストールディレクトリに移動すると、`data`フォルダは設定ファイルの保存に使用され、`plugins`フォルダはプラグイン関連ファイルに使用されます。
-次に、[メッセージプラットフォームのデプロイ](/en/deploy/platforms/readme)ページを引き続きお読みください。
+次に、[メッセージプラットフォームの設定](/ja/usage/platforms/readme)ページを引き続きお読みください。
diff --git a/ja/deploy/settings.mdx b/ja/deploy/settings.mdx
index 54a81506f..1c116424e 100644
--- a/ja/deploy/settings.mdx
+++ b/ja/deploy/settings.mdx
@@ -112,6 +112,24 @@ monitoring:
check_interval_hours: 1
# 各監視テーブルで 1 回に削除する期限切れ行数
delete_batch_size: 1000
+box:
+ backend: 'local' # 'local' (Docker/nsjail), 'docker', 'nsjail', または 'e2b'。BOX__BACKEND で書き込めます。
+ runtime:
+ endpoint: '' # 外部 Box Runtime ベース URL(例: 'ws://127.0.0.1:5410')。空の場合はローカル自動管理ランタイムを使用。
+ local:
+ profile: 'default'
+ image: '' # カスタムローカルサンドボックスイメージ。空の場合はプロファイルデフォルトを使用。
+ host_root: './data/box' # ローカルワークスペースマウント用のホストルートディレクトリ。Docker デプロイ時は langbot_box にマウントする絶対ホストパスを使用。
+ default_workspace: '' # デフォルトは '/default'。
+ skills_root: 'skills' # Box が管理する Skill パッケージディレクトリ。相対パスは host_root 配下に解決されます。
+ allowed_mount_roots: # 空の場合はデフォルトで ['']。
+ - './data/box'
+ - '/tmp'
+ workspace_quota_mb: null # オプションのディスククォータオーバーライド (>= 0)。null = プロファイルデフォルト。
+ e2b:
+ api_key: '' # E2B_API_KEY 環境変数でも設定可能。
+ api_url: '' # セルフホストデプロイ用のカスタム API URL。
+ template: '' # デフォルトテンプレート ID(例: 'base', 'python-3.11')。
space:
# Space サービス URL
url: 'https://space.langbot.app'
@@ -142,5 +160,12 @@ space:
- `STORAGE__CLEANUP__LOG_RETENTION_DAYS` は `storage.cleanup.log_retention_days` を表します
- `MONITORING__AUTO_CLEANUP__RETENTION_DAYS` は `monitoring.auto_cleanup.retention_days` を表します
- `PLUGIN__BINARY_STORAGE__MAX_VALUE_BYTES` は `plugin.binary_storage.max_value_bytes` を表します
+- `BOX__BACKEND` は `box.backend` を表します
+- `BOX__LOCAL__HOST_ROOT` は `box.local.host_root` を表します
+- `BOX__LOCAL__SKILLS_ROOT` は `box.local.skills_root` を表します
起動時、LangBot はすべての環境変数を読み取り、対応する設定を `config.yaml` に適用して `data/config.yaml` ファイルに書き込みます。
+
+
+Box 関連設定は `langbot` サービスに統一形式の `BOX__*` 環境変数で設定します。LangBot は起動時にそれらを `data/config.yaml` に適用し、INIT RPC 経由で Box 設定を `langbot_box` に渡します。`LANGBOT_BOX_*` や `BOX__*` を `langbot_box` に設定しても直接読み取られません。
+
diff --git a/ja/insight/guide.mdx b/ja/insight/guide.mdx
index daac24eca..ef18cfd88 100644
--- a/ja/insight/guide.mdx
+++ b/ja/insight/guide.mdx
@@ -34,12 +34,12 @@ LangBotは、オープンソースの大規模言語モデル(LLM)ネイティ
### 2. ボットを設定する
-左サイドバーの[ボットの設定](/en/deploy/platforms/readme)を確認してください
+左サイドバーの[ボットの設定](/ja/usage/platforms/readme)を確認してください
### 3. モデルを設定する
-左サイドバーの[対話モデルの設定](/en/deploy/models/readme)を確認してください
+左サイドバーの[対話モデルの設定](/ja/usage/models/readme)を確認してください
-上記の2つのステップを完了すると、LangBotの使用を開始できます。さらに多くの機能を設定する必要がある場合は、[Pipeline](/en/deploy/pipelines/readme)セクションで設定できます
+上記の2つのステップを完了すると、LangBotの使用を開始できます。さらに多くの機能を設定する必要がある場合は、[Pipeline](/ja/usage/pipelines/readme)セクションで設定できます
diff --git a/ja/usage/knowledge/readme.mdx b/ja/usage/knowledge/readme.mdx
index da097428e..8838e0790 100644
--- a/ja/usage/knowledge/readme.mdx
+++ b/ja/usage/knowledge/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "ナレッジベースの使用"
+title: "ナレッジベース"
---
LangBotはRAG(Retrieval-Augmented Generation)をネイティブサポートしています。ナレッジベースを作成してパイプラインにバインドすることで、ナレッジベースの内容に基づいて質問に答えることができます。
diff --git a/ja/usage/mcp/readme.mdx b/ja/usage/mcp/readme.mdx
index f422dab07..36f8779fd 100644
--- a/ja/usage/mcp/readme.mdx
+++ b/ja/usage/mcp/readme.mdx
@@ -1,41 +1,107 @@
---
-title: "MCPサーバーの使用"
+title: "MCP サーバー"
---
+LangBot は MCP サーバー由来のツールを利用できます。MCP サーバーを追加すれば、ツール使用を有効にしたモデルを持つ組み込み Agent が会話中にそのツールを呼び出せます。
-LangBotはMCPサーバーをサポートしています。MCPサーバーを追加して、大規模言語モデルのツール呼び出し機能を活用し、LLMリクエストをより適切に処理できます。
+
+ まずは [LangBot Space](https://space.langbot.app) からのインストールを推奨します。掲載されている MCP サーバーは設定済みで、そのまま使えます。
-
-- MCPサーバーの推奨取得チャネル:
- - [ModelScope](https://modelscope.cn/mcp)
- - https://mcp.so
- - https://composio.dev/toolkits
+ [ModelScope](https://modelscope.cn/mcp)、[mcp.so](https://mcp.so)、[composio.dev](https://composio.dev/toolkits) から入手して、後述の手動追加で登録することも可能です。
-## モデルのFunction Callingを有効化
+## 3 つの通信モード
-画像に示すように、モデルの`Function Calling`機能を有効にします。
+| モード | 適した場面 | 備考 |
+|------|----------|------|
+| Streamable HTTP (`mode: "http"`) | Streamable HTTP に対応したリモート MCP | LangBot がリモート URL に直接接続 |
+| SSE | SSE に対応したリモート MCP | LangBot がリモート URL に直接接続 |
+| stdio | ローカルコマンドで起動する MCP サーバー | Box Runtime が利用可能なときのみサポート |
-
+
+MCP ツールを使うには、パイプラインで**組み込み Agent** を選択し、**ツール使用が有効化されたモデル**を使用する必要があります。[モデル](../models/readme)を参照。Dify、n8n、Langflow、Coze などの外部 Runner は各プラットフォームのツール機構を使います。
+
-## MCPサーバーの作成
+## MCP サーバーをインストール
-`プラグイン管理`をクリックしてから`MCP管理`をクリックします:
+### LangBot Space から(推奨)
-
+[LangBot Space](https://space.langbot.app) は LangBot 公式のマーケットプレイスで、設定済みの MCP サーバーが多数掲載されています。WebUI の `プラグイン管理` → `MCP 管理` から閲覧して 1 クリックでインストールでき、URL、コマンド、モードなどのパラメータはマーケット側が提供するため、手動入力は不要です。
-右上の`追加`をクリックしてから`MCPサーバーを作成`をクリックします。
+ほとんどのケースはこれで十分です。掲載されていないサービスを利用する場合は、下記の手動追加を使ってください。
-
+### 手動で追加
-例えば、Fetch HTMLサーバーを使用するには、対応するURLを入力し、`テスト`をクリックしてMCPサーバーをテストし、`送信`をクリックしてサーバーを追加します。
+`プラグイン管理` → `MCP 管理` を開きます:
-追加後、カードのスイッチをクリックしてMCPサーバーに接続します。カードをクリックしてMCPサーバーの詳細を表示します:
+
-
+右上の `追加` → `MCP サーバーを追加` をクリック。URL(HTTP/SSE)またはコマンド(stdio)を入力し、`テスト` で接続を確認、`送信` で保存します:
-## 効果
+
-パイプライン設定で`Local Agent`をランナーとして選択し、function callingをサポートするモデルを使用する必要があります。
+保存後、カードのスイッチをオンにして接続します。カードをクリックすると詳細を確認できます:
-
+
+
+## パイプラインで有効化
+
+MCP サーバーを追加したあと、パイプライン拡張設定で Agent から見える MCP を決めます:
+
+- 「すべての MCP サーバーを有効化」をオン、または
+- 指定した MCP サーバーのみをバインド
+
+バインドしていない MCP のツールはそのパイプラインのツール一覧に入りません。
+
+## 高度な設定:stdio MCP
+
+stdio MCP は Box Runtime によってホストされます。接続前に LangBot は以下を行います:
+
+1. 共有の MCP Box session を作成または再利用
+2. コマンドからローカルプロジェクトのパスを推測できれば、プロジェクトをワークスペースに staging
+3. プロジェクトに `requirements.txt`、`pyproject.toml`、`setup.py`、`setup.cfg` がある場合は依存をインストール
+4. WebSocket relay 経由で MCP プロセスの stdin/stdout に接続
+
+マウント、ネットワーク、タイムアウトを細かく調整したい場合、MCP 設定の `extra_args` に `box` オーバーライドを追加できます:
+
+```json
+{
+ "mode": "stdio",
+ "extra_args": {
+ "command": "python",
+ "args": ["server.py"],
+ "env": {},
+ "box": {
+ "host_path": "/path/to/mcp-project",
+ "network": "on",
+ "host_path_mode": "ro",
+ "startup_timeout_sec": 120,
+ "image": "python:3.11-slim"
+ }
+ }
+}
+```
+
+主なフィールド:
+
+| フィールド | 説明 |
+|------|------|
+| `host_path` | ホスト上の MCP プロジェクトディレクトリ。`box.local.allowed_mount_roots` の許可範囲内である必要があります |
+| `network` | ネットワークを許可するか(依存インストールでよく使う) |
+| `host_path_mode` | `host_path` を staging するときのアクセスモード。デフォルトは `ro`。stdio MCP は通常ワークスペースに staging されます |
+| `startup_timeout_sec` | Box 準備と依存インストールのタイムアウト、デフォルト 120 秒。接続待ちで約 30 秒追加されます |
+| `image` | Docker バックエンドで使用するランタイムイメージ |
+
+
+stdio MCP は Box 内で実行されます。依存インストールとプロセス起動は sandbox profile、ネットワーク権限、リソース制限、マウント許可リストの影響を受けます。
+
+
+## よくある問題
+
+| 症状 | 確認項目 |
+|------|--------|
+| MCP の接続に失敗 | URL、コマンド、引数、環境変数が正しいか |
+| stdio MCP が接続中のまま | Box Runtime の状態、`startup_timeout_sec` が短すぎないか |
+| 依存インストールに失敗 | sandbox がネットワークを許可しているか、依存ファイルが正しいか |
+| ローカルファイルにアクセスできない | `host_path` が存在し、`allowed_mount_roots` 内にあるか |
+| Agent が MCP ツールを認識しない | パイプラインで組み込み Agent を使っているか、モデルでツール使用を有効にしているか、MCP がパイプラインにバインドされているか |
diff --git a/ja/usage/models/readme.mdx b/ja/usage/models/readme.mdx
index ff2e184b2..9bb9621e6 100644
--- a/ja/usage/models/readme.mdx
+++ b/ja/usage/models/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "モデルの設定(Models)"
+title: "モデル (Models)"
---
## LangBot Models
@@ -26,11 +26,16 @@ LangBot Modelsは、LangBotが公式に提供するモデルサービスです
これら4つのパラメータを入力します: `モデル名`、`モデルプロバイダー`、`リクエストURL`、`APIキー`、そして送信します。
-モデルの機能については、特定のモデルの特性に応じて選択してください:
+モデルの機能は、ベースモデルが実際にサポートしているものを有効化します:
-- ビジュアル機能: 画像を認識するために有効にする必要があります
+- **ビジョン**:有効にすると画像を認識可能
+- **ツール使用**(function calling / tool use):有効にすると LLM が会話中にツールを呼び出せる
-- Function Calling: 会話でAgentツールを使用するために有効にする必要があります
+
+**MCP サーバー、サンドボックスの組み込みツール(`exec`/`read`/`write`/`edit`/`glob`/`grep`)、Skills のいずれかを利用したい場合は、モデルでツール使用を必ず有効にしてください。** 有効でなければ、パイプラインで拡張機能をバインドしていても Agent はツールを呼び出しません。
+
+ベースモデル自体が function calling に対応している必要があります。不明な場合はモデル提供元のドキュメントを確認してください。
+
### 埋め込みモデル (Embedding Model)
diff --git a/ja/usage/pipelines/readme.mdx b/ja/usage/pipelines/readme.mdx
index 71cf93aa8..75982da0f 100644
--- a/ja/usage/pipelines/readme.mdx
+++ b/ja/usage/pipelines/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "対話パイプライン設定の変更(Pipelines)"
+title: "対話パイプライン (Pipelines)"
---
パイプラインは、メッセージを受信した後の処理フローと、大規模言語モデルとの情報交換を制御します。各ボットは1つのパイプラインにバインドでき、同じパイプラインは複数のボットにバインドできます。
diff --git a/ja/usage/sandbox/config.mdx b/ja/usage/sandbox/config.mdx
new file mode 100644
index 000000000..416e63861
--- /dev/null
+++ b/ja/usage/sandbox/config.mdx
@@ -0,0 +1,147 @@
+---
+title: "サンドボックス設定"
+---
+
+サンドボックス設定は LangBot メインプロセスが管理し、Box Runtime が実際の実行を担当します。通常のデプロイでは、バックエンド、ワークスペースディレクトリ、セキュリティプロファイルだけを決めれば十分です。
+
+
+このページの `box.*` 設定はすべて `data/config.yaml` に記述します。ファイルの場所と読み込みの仕組みは[システム環境設定](../../deploy/settings)を参照してください。
+
+
+## 推奨設定
+
+```yaml
+box:
+ enabled: true
+ backend: 'local' # Docker / Nsjail から利用可能なものを自動選択
+ local:
+ profile: 'default'
+ host_root: './data/box'
+ skills_root: 'skills'
+```
+
+- `enabled`:サンドボックスのマスタースイッチ。`false` にすると、サンドボックス組み込みツール、Skill の追加 / 編集、stdio MCP のホスティングなど Box 依存の機能はすべて無効になります。
+- `backend`:下記「バックエンドの選択」を参照。
+- `local.profile`:セキュリティプロファイル。ネットワーク、マウント、リソース制限を制御。
+- `local.host_root`:ホスト側のサンドボックス作業ディレクトリ。サンドボックス内では `/workspace` にマウントされます。
+- `local.skills_root`:Skill パッケージのディレクトリ。相対パスは `host_root` 配下に解決され、デフォルトは `host_root/skills`。
+
+
+Skill は Box Runtime が管理する skill store からのみ読み込まれます。Box Runtime またはバックエンドが利用できない場合、Skill 一覧は空になり、追加 / 編集 / `register_skill` も使えません。`data/skills/` へのフォールバックは行いません。
+
+
+## バックエンドの選択
+
+サンドボックスは**ローカルコンテナ**または**クラウド**で動作させられます。`box.backend` でどちらを使うかを指定します:
+
+| `backend` | 実行場所 | 動作 |
+|-----------|---------|------|
+| `local`(既定) | ローカルコンテナ | Docker / Nsjail から利用可能なものを自動選択(Docker 優先) |
+| `docker` | ローカルコンテナ | Docker を強制使用。Docker daemon が必要 |
+| `nsjail` | ローカルコンテナ | Nsjail を強制使用(Linux のみ)。カスタムイメージ非対応 |
+| `e2b` | クラウド | [E2B](https://e2b.dev) クラウドサンドボックスを使用。API キーが必要 |
+
+`local` は「自動選択」のショートハンドであり、`docker` / `nsjail` と並列の 4 つ目のバックエンドではありません。ローカル系バックエンド(`local` / `docker` / `nsjail`)は `box.local.*` 設定セクションを**共有**し、クラウドバックエンドは `box.e2b.*` を使います。
+
+
+`backend` は強制値です。`docker` を指定して Docker が使えない場合、Nsjail や E2B に**自動でフォールバックしません**。自動 fan-out するのは `local` だけです。
+
+環境変数 `BOX__BACKEND` で `box.backend` を上書きできます(`config.yaml` より優先)。
+
+
+## セキュリティプロファイル
+
+`box.local.profile` はローカル系バックエンドのネットワーク、マウント、リソース制限を制御します:
+
+| Profile | ネットワーク | マウント | リソース | 推奨シーン |
+|---------|---------|---------|---------|----------|
+| `default` | オフ | 読み書き | 既定制限 | 既定の選択 |
+| `offline_readonly` | オフ | 読み取り専用 | より厳格 | 信頼できないファイルの読み込み |
+| `network_basic` | 基本ネットワーク | 読み書き | 既定制限 | API アクセス、依存関係インストール |
+| `network_extended` | フルネットワーク | 読み書き | 緩和 | 開発、デバッグ、複雑なタスク |
+
+最小権限を優先:ネットワークが不要なら `default` または `offline_readonly`;`allowed_mount_roots` には必要なディレクトリのみを追加。
+
+## ローカル系バックエンド設定(box.local.*)
+
+ローカル系バックエンド(`local` / `docker` / `nsjail`)は以下を共有します:
+
+| 設定項目 | 既定値 | 説明 |
+|---------|--------|------|
+| `local.profile` | `default` | 上記「セキュリティプロファイル」を参照 |
+| `local.image` | 空 | Docker バックエンドのカスタムイメージ。空 = プロファイル既定を使用 |
+| `local.host_root` | `./data/box` | ホスト作業ディレクトリのベース。サンドボックス内の `/workspace` にマップ |
+| `local.default_workspace` | 空 | 既定ワークスペース名。空 = `/default` |
+| `local.skills_root` | `skills` | Skill パッケージディレクトリ。相対パスは `host_root` 配下に解決 |
+| `local.allowed_mount_roots` | `[host_root]` | Agent がマウント要求できるホストディレクトリの許可リスト |
+| `local.workspace_quota_mb` | `null` | ワークスペースのディスク配額(MB)。`null` = プロファイル既定 |
+
+## クラウドバックエンド設定(box.e2b.*)
+
+`backend: 'e2b'` を指定したうえで設定します:
+
+| 設定項目 | 既定値 | 説明 |
+|---------|--------|------|
+| `e2b.api_key` | 空 | E2B API キー。環境変数 `E2B_API_KEY` でも設定可 |
+| `e2b.api_url` | 空 | セルフホスト E2B のエンドポイント。環境変数 `E2B_API_URL` でも設定可 |
+| `e2b.template` | 空 | 既定の E2B テンプレート ID |
+
+E2B はホスト側に Docker や Nsjail を必要とせず、毎回の実行をリモートサンドボックスで行います。
+
+## Docker Compose デプロイ
+
+Docker Compose では、サンドボックス設定は `langbot` サービス側に記述します。LangBot は起動時に INIT RPC で設定を `langbot_box` に転送します。
+
+```yaml
+services:
+ langbot_box:
+ image: rockchin/langbot:latest
+ container_name: langbot_box
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+ command: ["uv", "run", "--no-sync", "-m", "langbot_plugin.cli.__init__", "box"]
+
+ langbot:
+ image: rockchin/langbot:latest
+ volumes:
+ - ./data:/app/data
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+```
+
+
+`langbot_box` は Docker daemon にアクセスします。`docker.sock` のマウントは信頼できる環境でのみ行い、Box のルートパスをホストと `langbot_box` コンテナ内で一致させてください。
+
+
+外部の Box Runtime(リモートホストなど)に接続する場合は `box.runtime.endpoint` で URL を指定します:
+
+```yaml
+box:
+ runtime:
+ endpoint: 'ws://192.168.1.10:5410'
+```
+
+## 環境変数
+
+| 環境変数 | 対応する設定 |
+|----------|----------|
+| `BOX__ENABLED` | `box.enabled` |
+| `BOX__BACKEND` | `box.backend` |
+| `BOX__LOCAL__PROFILE` | `box.local.profile` |
+| `BOX__LOCAL__IMAGE` | `box.local.image` |
+| `BOX__LOCAL__HOST_ROOT` | `box.local.host_root` |
+| `BOX__LOCAL__DEFAULT_WORKSPACE` | `box.local.default_workspace` |
+| `BOX__LOCAL__SKILLS_ROOT` | `box.local.skills_root` |
+| `BOX__LOCAL__ALLOWED_MOUNT_ROOTS` | `box.local.allowed_mount_roots`、カンマ区切り |
+| `BOX__LOCAL__WORKSPACE_QUOTA_MB` | `box.local.workspace_quota_mb` |
+| `BOX__E2B__API_KEY` | `box.e2b.api_key` |
+| `BOX__E2B__API_URL` | `box.e2b.api_url` |
+| `BOX__E2B__TEMPLATE` | `box.e2b.template` |
+
+
+`langbot_box` サービス側には `BOX__*` や `LANGBOT_BOX_*` を設定しないでください。Box Runtime はこれらを直接読みません——設定は LangBot から INIT RPC 経由で渡されます。
+
diff --git a/ja/usage/sandbox/readme.mdx b/ja/usage/sandbox/readme.mdx
new file mode 100644
index 000000000..efe4ebffc
--- /dev/null
+++ b/ja/usage/sandbox/readme.mdx
@@ -0,0 +1,73 @@
+---
+title: "サンドボックス (Sandbox)"
+---
+
+サンドボックスは組み込み Agent に隔離された実行環境を提供します。コマンドの実行、ファイルの読み書き、長期常駐プロセスの実行が可能です。日常的な Agent 用途(データ処理、ファイル操作、ユーザーコードの実行、stdio MCP のホスティング)はすべてこれに依存します。
+
+サンドボックスを有効化すると、組み込み Agent は自動的に 6 つのツールを取得します。パイプラインで個別に有効化する必要はありません。
+
+## 組み込みツール
+
+| ツール | 用途 |
+|------|------|
+| `exec` | サンドボックス内で Shell コマンドを実行 |
+| `read` | ワークスペースのファイルを読み取る |
+| `write` | ファイルを作成または上書き |
+| `edit` | 文字列置換でファイルを編集 |
+| `glob` | glob パターンでファイルを検索 |
+| `grep` | 正規表現でファイル内容を検索 |
+
+`exec` はサンドボックスコンテナ内で実行されます。残り 5 つはホスト側の `/workspace` にマッピングされたディレクトリを直接読み書きします。
+
+
+これらのツールは組み込み Agent 向けです。Dify、n8n、Langflow、Coze などの外部 Runner を使用する場合は、各プラットフォーム独自のツール機構を利用してください。
+
+
+## サンドボックススコープ
+
+パイプラインの AI 設定で、メッセージ間でサンドボックスをどのように共有するかを選べます。デフォルトの「チャットごと」で多くのシナリオに対応できます。
+
+| スコープ | テンプレート | 共有範囲 |
+|--------|------|---------|
+| グローバル | `{global}` | 全ユーザーが 1 つのサンドボックスを共有 |
+| チャットごと(デフォルト) | `{launcher_type}_{launcher_id}` | 同じグループ/個人チャットで共有 |
+| ユーザーごと | `{launcher_type}_{launcher_id}_{sender_id}` | グループ内の各メンバーが独立 |
+| 会話ごと | `{launcher_type}_{launcher_id}_{conversation_id}` | 会話単位で隔離 |
+| メッセージごと | `{query_id}` | 完全にステートレス |
+
+
+同一スコープ内のコマンドはファイルシステム状態を共有します。完全な隔離が必要な場合は「メッセージごと」を選択してください。
+
+
+## ライフサイクル
+
+| 状況 | 動作 |
+|------|------|
+| 5 分以上アイドル | 自動クリーンアップ |
+| Box がホストするプロセス(stdio MCP など)が稼働中 | クリーンアップしない。プロセス終了後に解放 |
+| `persistent: true` 設定時 | 自動クリーンアップなし |
+
+## クイックスタート
+
+1. **バックエンドの準備**: ローカルに Docker をインストール、または Nsjail / E2B を選択
+2. **`config.yaml` に記述**:
+ ```yaml
+ box:
+ enabled: true
+ backend: 'local'
+ local:
+ host_root: './data/box'
+ ```
+3. **LangBot を起動**: サンドボックスは自動的に有効化
+4. **パイプラインで** 組み込み Agent と関数呼び出し対応モデルを選択
+
+その後、Agent は自動的に 6 つのツールを取得します。詳細な設定は [サンドボックス設定](./config) を参照してください。
+
+## サンドボックスを無効化する
+
+`box.enabled: false` を設定します。サンドボックスに依存するすべての機能(組み込みツール、Skill の作成/編集/起動、stdio MCP)が同時に無効になります。http/sse モードの MCP は影響を受けません。
+
+## 次のステップ
+
+- [サンドボックス設定](./config) — バックエンド、セキュリティプリセット、マウント、環境変数
+- [ランタイムと拡張機能の関係](./runtime-relationships) — サンドボックス、Skills、MCP、プラグインの役割分担
diff --git a/ja/usage/sandbox/runtime-relationships.mdx b/ja/usage/sandbox/runtime-relationships.mdx
new file mode 100644
index 000000000..55dc814ed
--- /dev/null
+++ b/ja/usage/sandbox/runtime-relationships.mdx
@@ -0,0 +1,45 @@
+---
+title: "ランタイムと拡張機能の関係"
+---
+
+LangBot には **プラグイン、MCP、Skills、サンドボックス** という 4 種類の拡張機構が併存しており、混同されやすい部分です。本ページではそれぞれの役割と使い分けを整理します。
+
+## 一行で区別する
+
+- **サンドボックス**: 実行環境。Agent がコマンド実行やファイル読み書きを行う場所
+- **Skills**: オンデマンドで起動する指示パック。Agent に一時的に専門的なワークフローを追加する
+- **MCP サーバー**: 外部のツールサービスに接続する
+- **プラグイン**: 長期常駐する拡張プロセス。設定ページ、イベント監視、ナレッジベースを持てる
+
+## 対応表
+
+| 機能 | 提供元 | Agent への入り方 | いつ使うか |
+|------|--------|----------------|---------|
+| サンドボックス | Box Runtime | `exec/read/write/edit/glob/grep` の 6 点セットを直接付与 | Agent がコード実行やファイル読み書きを行うとき |
+| Skills | Box Runtime skill store | Agent が `activate` を呼び出した後、指示が Tool Result として注入される | Agent にワークフロー/テンプレート/スクリプトを追加し、必要時にのみ発火させたいとき |
+| MCP サーバー | LangBot MCP Loader(stdio モードは Box がホスト) | ツールが利用可能ツール一覧に直接入る | 既存の MCP サービスに接続したいとき |
+| プラグイン | Plugin Runtime | プラグインシステムから能力が公開される | 長期的な機能、設定ページ/イベント監視/ナレッジコンポーネントが必要なとき |
+
+## パイプラインへのバインド
+
+Skills、MCP サーバー、プラグインはすべて **パイプライン拡張** に属します。WebUI でインストール/作成した後、パイプライン拡張設定で有効化範囲を決定する必要があります。
+
+- すべての拡張を有効化する、または
+- 指定した拡張のみをバインドする
+
+Skills のバインドは Agent が **どの Skill を見えるか** を決定します(`` 一覧に影響)。具体的な Skill 内容は Agent が `activate` を呼び出した後にのみ注入されます。
+
+## トラブルシューティングの入口
+
+| 症状 | まず確認すること |
+|------|---------|
+| Agent に `exec/read/write` ツールがない | `box.enabled`、バックエンドが利用可能か、パイプラインが組み込み Agent を使用しているか |
+| Skill 一覧が空 | Box Runtime の状態、`box.local.skills_root`、パイプラインのバインド |
+| stdio MCP の起動に失敗 | Box Runtime の状態、MCP コマンドと環境変数、起動タイムアウト |
+| Docker デプロイでサンドボックスが起動しない | `langbot_box` が `docker.sock` をマウントしているか、Box ルートディレクトリのパスが一致しているか |
+| ファイル読み書きに失敗 | `box.local.host_root`、`box.local.allowed_mount_roots` |
+| バックエンド選択が効かない | `BOX__BACKEND` が `langbot_box` ではなく `langbot` サービスに設定されているか確認 |
+
+
+サンドボックスの組み込みツールと Skills は、現在は組み込み Agent 向けです。外部 Runner(Dify、n8n、Langflow、Coze など)では、各プラットフォーム独自のツールと実行機構を使用してください。
+
diff --git a/ja/usage/skills/readme.mdx b/ja/usage/skills/readme.mdx
new file mode 100644
index 000000000..ca004bf01
--- /dev/null
+++ b/ja/usage/skills/readme.mdx
@@ -0,0 +1,100 @@
+---
+title: "スキル (Skills)"
+---
+
+Skill は**必要時に起動する**指示パックです。ユーザーのリクエストが該当する内容になると、Agent が `activate` ツールを呼び出してその Skill の指示をコンテキストに取り込み、それに従ってタスクを完了させます。起動されていない Skill はコンテキストを消費しません。
+
+Agent に**専門的なワークフロー、テンプレート、スクリプト**を一つ追加するのに向いています。たとえば「Python プロジェクトの解析」「PDF フォーム入力」「コードレビュー」など。System Prompt に全部詰め込む必要はありません。
+
+## プラグイン・MCP との違い
+
+| やりたいこと | 使うもの |
+|------|------|
+| 必要時に起動する一連のワークフロー(スクリプトやテンプレート付き可) | Skill |
+| 既存の MCP ツールサービスに接続 | MCP サーバー |
+| 長期常駐機能、設定画面、イベント、ナレッジベース | プラグイン |
+
+詳細は[ランタイムと拡張機能の関係](../sandbox/runtime-relationships)を参照。
+
+## Skill のインストール
+
+
+Skill はサンドボックスに依存します。`box.enabled` が `true` で、Docker / Nsjail / E2B のいずれかが利用可能なときのみ、Skill のインストール、起動、編集ができます。詳細は[サンドボックス設定](../sandbox/config)を参照。
+
+
+### LangBot Space から(推奨)
+
+[LangBot Space](https://space.langbot.app) は LangBot 公式のマーケットプレイスで、すぐに使える Skill が多数掲載されています。WebUI の Skills ページから閲覧して 1 クリックでインストールでき、`SKILL.md` の作成やリソースファイルの準備は不要です。
+
+ほとんどのケースはこれで十分です。独自のワークフローが必要な場合は下記の方法を使ってください。
+
+### 自分で作る
+
+**WebUI** — Skills ページで新規作成、zip アップロード、GitHub からのインポートが可能。
+
+**サンドボックス + `register_skill`**:
+1. サンドボックスの `/workspace` 配下にディレクトリと `SKILL.md` を準備
+2. Agent に `register_skill(path="/workspace/my-skill")` を呼び出させる
+
+いずれの方法でも Box Runtime が管理する skill store に書き込まれます。
+
+## パイプラインで有効化
+
+Skill をインストールしたあと、パイプラインの拡張設定で Agent から見える Skill を決めます:
+
+- 「すべての Skill を有効化」をオンにする、または
+- 指定した Skill のみをバインドする
+
+バインドは `` 一覧(Agent が選択肢として認識する対象)にのみ影響します。完全な指示は常に `activate` が呼ばれた後に注入されます。
+
+## SKILL.md を書く
+
+Skill はディレクトリと `SKILL.md` 1 つで構成されます。frontmatter にメタデータを書き、本文は Agent が起動後に受け取る指示です:
+
+```markdown
+---
+name: code-reviewer
+display_name: コードレビューアシスタント
+description: コードをレビューして改善提案を行う。ユーザーが review、レビュー、コード改善に言及したときに起動
+---
+
+## 実行手順
+
+1. `read` で関連ファイルをざっと確認
+2. 可読性、潜在的なバグ、セキュリティ問題をチェック
+3. 優先度順に改善提案を提示
+```
+
+LangBot は現在、以下の 3 つのフィールドを読み取ります:
+
+| フィールド | 必須 | 説明 |
+|------|------|------|
+| `name` | 作成/登録時 | 一意の識別子、1–64 文字 |
+| `description` | 強く推奨 | Agent はこれをもとに起動可否を判断する——具体的なほど選ばれやすい |
+| `display_name` | 任意 | UI 表示名 |
+
+`description` は Agent が Skill を選ぶ唯一の手がかりです。**機能・適用シーン・想定されるトリガーワード**を具体的に書きましょう。
+
+完全な仕様は [agentskills.io](https://agentskills.io/home) を参照してください。その他のフィールド(`license`、`metadata` など)は将来の互換のために残せますが、現在は読み取られません。
+
+**リソースを伴う Skill** では `SKILL.md` と同じ階層に `scripts/`、`templates/` などを置きます。起動後、Agent は `/workspace/.skills/{skill-name}/` でこれらにアクセスできます。
+
+### Agent が使えるツール
+
+| ツール | 用途 |
+|------|------|
+| `activate` | Agent が該当を判断したときに自動で呼び出し、SKILL.md をコンテキストに取り込む |
+| `register_skill` | サンドボックスに用意したディレクトリを新しい Skill として登録 |
+
+## よくある問題
+
+| 症状 | 確認項目 |
+|------|--------|
+| Skill 一覧が空 | `box.enabled`、Box Runtime の状態、`box.local.skills_root` |
+| Agent が Skill を起動しない | `description` が具体的か、パイプラインでバインドされているか、モデルが関数呼び出しに対応しているか |
+| 起動後にファイルが見つからない | ファイルは Skill パッケージ内に置く必要があり、パスは `/workspace/.skills/{skill-name}/` |
+| `register_skill` がエラー | パスは `/workspace` 配下である必要があり、ディレクトリまたは 2 階層以内のサブディレクトリに `SKILL.md` が必要 |
+
+
+Skills は現在、組み込み Agent 向けで、関数呼び出しとサンドボックスバックエンドに依存します。外部 Runner(Dify、n8n、Langflow、Coze など)では各プラットフォームの同等機構を利用してください。
+
diff --git a/skills-lock.json b/skills-lock.json
new file mode 100644
index 000000000..0beda5008
--- /dev/null
+++ b/skills-lock.json
@@ -0,0 +1,11 @@
+{
+ "version": 1,
+ "skills": {
+ "writing-skills": {
+ "source": "obra/superpowers",
+ "sourceType": "github",
+ "skillPath": "skills/writing-skills/SKILL.md",
+ "computedHash": "c0a92e629e39ea91b1f54da67a6aa92723008a8ef5b500c6de078f55485937c7"
+ }
+ }
+}
diff --git a/zh/deploy/langbot/docker.mdx b/zh/deploy/langbot/docker.mdx
index 8507d58c4..41f123a7a 100644
--- a/zh/deploy/langbot/docker.mdx
+++ b/zh/deploy/langbot/docker.mdx
@@ -20,23 +20,68 @@ git clone https://github.com/langbot-app/LangBot
cd LangBot/docker
```
-启动容器:
+启动容器(推荐启用 `all` profile,以默认启用沙箱、stdio MCP 托管、Skill 添加/编辑等依赖 Box Runtime 的功能):
+
+```bash
+docker compose --profile all up
+```
+
+这会启动 `langbot`、`langbot_plugin_runtime` 和 `langbot_box`。如果只需要基础服务,不启用 Box Runtime,可以使用:
```bash
docker compose up
```
+`langbot_box` 通过主机 Docker socket 创建沙箱容器,因此 Box 根目录的宿主机路径和容器内路径必须一致:
+
+```yaml
+services:
+ langbot:
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__DEFAULT_WORKSPACE=default
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+
+ langbot_box:
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+```
+
+
+ **Box 控制面的启动方式因部署方式而异。** 容器部署下,Box 控制面以独立的 `langbot_box` **容器**运行,`langbot` 通过 WebSocket(`ws://langbot_box:5410`)连接它;而手动启动 / `uvx` 部署则由 `langbot` 直接拉起一个 stdio 子进程作为 Box 控制面。`langbot_box` 借助挂载的宿主 `docker.sock` 在宿主 Docker 上创建沙箱兄弟容器,LangBot 镜像已内置 `docker` 客户端,无需额外安装。
+
+
+如果提示 `No sandbox backend (Docker/nsjail/E2B) is ready`,请先确认当前用户可访问 Docker:
+
+```bash
+sudo usermod -aG docker $USER
+newgrp docker
+docker info
+```
+
+若 `docker info` 正常输出,请重启 LangBot。
+
+
+`langbot_box` 不直接读取 `LANGBOT_BOX_*` 或 `BOX__*` 环境变量;Box 配置由 `langbot` 读取 `BOX__LOCAL__*` 后通过 INIT RPC 传给 Box Runtime。若要改 Box 根目录,请使用绝对路径设置 `LANGBOT_BOX_ROOT`,例如 `LANGBOT_BOX_ROOT=/var/lib/langbot/box docker compose --profile all up`。
+
+
- 如果你的主机位于中国大陆,可以考虑把 `docker-compose.yaml` 文件中的镜像名称改为`docker.langbot.app/langbot-public/rockchin/langbot:latest`以使用我们提供的镜像源。
- 推荐[设置 Docker 容器代理](https://docker.github.net.cn/network/proxy/),以便保证 LangBot 在运行期间的网络访问通畅。
+ - 如果需要禁用或强制沙箱后端,请参考[沙箱配置](/zh/usage/sandbox/config)。
首次启动会输出创建配置文件的提示,请继续按照文件配置。
容器会映射`5300`端口供 WebUI 使用,您可以访问`http://127.0.0.1:5300`查看 WebUI。\
-还会映射`2280-2290`端口供使用 OneBot 协议的消息平台适配器反向连接。
+还会映射`2280-2285`端口供使用 OneBot 协议的消息平台适配器反向连接。
完成 LangBot 部署后,请继续阅读:
-- [配置机器人文档](/zh/deploy/platforms/readme)。
-- [配置模型文档](/zh/deploy/models/readme)。
\ No newline at end of file
+- [配置机器人文档](/zh/usage/platforms/readme)。
+- [配置模型文档](/zh/usage/models/readme)。
+- [沙箱文档](/zh/usage/sandbox/readme)。
+- [技能系统文档](/zh/usage/skills/readme)。
diff --git a/zh/deploy/langbot/manual.mdx b/zh/deploy/langbot/manual.mdx
index 9e5dd5b4b..1f0996f77 100644
--- a/zh/deploy/langbot/manual.mdx
+++ b/zh/deploy/langbot/manual.mdx
@@ -51,4 +51,4 @@ uv run main.py
...
```
-接下来可以使用 Ctrl+C 退出程序,继续查看[部署机器人](/zh/deploy/platforms/readme)页。
\ No newline at end of file
+接下来可以使用 Ctrl+C 退出程序,继续查看[配置机器人](/zh/usage/platforms/readme)页。
diff --git a/zh/deploy/langbot/one-click/1panel.mdx b/zh/deploy/langbot/one-click/1panel.mdx
index a9c2ff52d..a440e7b5d 100644
--- a/zh/deploy/langbot/one-click/1panel.mdx
+++ b/zh/deploy/langbot/one-click/1panel.mdx
@@ -46,4 +46,4 @@ title: "1Panel部署"
然后就可以在可视化界面进行配置了。
-接下来请继续阅读[部署消息平台](/zh/deploy/platforms/readme)页。
\ No newline at end of file
+接下来请继续阅读[配置消息平台](/zh/usage/platforms/readme)页。
diff --git a/zh/deploy/langbot/one-click/bt.mdx b/zh/deploy/langbot/one-click/bt.mdx
index 2a71ffd8e..97c5ef5dd 100644
--- a/zh/deploy/langbot/one-click/bt.mdx
+++ b/zh/deploy/langbot/one-click/bt.mdx
@@ -52,4 +52,4 @@ title: "宝塔面板部署"
然后就可以在可视化界面进行配置了。
-接下来请继续阅读[部署消息平台](/zh/deploy/platforms/readme)页。
\ No newline at end of file
+接下来请继续阅读[配置消息平台](/zh/usage/platforms/readme)页。
diff --git a/zh/deploy/settings.mdx b/zh/deploy/settings.mdx
index be5c92927..051b79400 100644
--- a/zh/deploy/settings.mdx
+++ b/zh/deploy/settings.mdx
@@ -112,6 +112,25 @@ monitoring:
check_interval_hours: 1
# 每个监控表单批删除的过期记录数量
delete_batch_size: 1000
+box:
+ enabled: true # Box Runtime 总开关。false 时禁用沙箱、Skill 添加/编辑和 stdio MCP 等依赖 Box 的功能。
+ backend: 'local' # 'local' (Docker/nsjail), 'docker', 'nsjail', 或 'e2b'。可通过 BOX__BACKEND 写入。
+ runtime:
+ endpoint: '' # 外部 Box Runtime 基础 URL,如 'ws://127.0.0.1:5410'。留空时,非 Docker 部署使用本地自动管理的 Runtime;Docker 部署连接 Compose 网络中的 langbot_box:5410。
+ local:
+ profile: 'default'
+ image: '' # 自定义本地沙箱镜像。留空使用 profile 默认值。
+ host_root: './data/box' # 本地工作区挂载的主机根目录。Docker 部署时应使用可被 langbot_box 挂载的绝对主机路径。
+ default_workspace: '' # 默认为 '/default'。
+ skills_root: 'skills' # Box 管理的 Skill 包目录。相对路径会解析到 host_root 下。
+ allowed_mount_roots: # 默认为 ['']。
+ - './data/box'
+ - '/tmp'
+ workspace_quota_mb: null # 可选磁盘配额覆盖 (>= 0)。null 表示使用 profile 默认值。
+ e2b:
+ api_key: '' # 也可通过 E2B_API_KEY 环境变量设置。
+ api_url: '' # 自托管部署的自定义 API URL。
+ template: '' # 默认模板 ID(如 'base', 'python-3.11')。
space:
# Space 服务 URL
url: 'https://space.langbot.app'
@@ -142,5 +161,13 @@ space:
- `STORAGE__CLEANUP__LOG_RETENTION_DAYS` 代表 `storage.cleanup.log_retention_days`
- `MONITORING__AUTO_CLEANUP__RETENTION_DAYS` 代表 `monitoring.auto_cleanup.retention_days`
- `PLUGIN__BINARY_STORAGE__MAX_VALUE_BYTES` 代表 `plugin.binary_storage.max_value_bytes`
+- `BOX__ENABLED` 代表 `box.enabled`
+- `BOX__BACKEND` 代表 `box.backend`
+- `BOX__LOCAL__HOST_ROOT` 代表 `box.local.host_root`
+- `BOX__LOCAL__SKILLS_ROOT` 代表 `box.local.skills_root`
在启动时,LangBot 会读取所有环境变量,将对应的配置应用到 `config.yaml` 中并写入到 `data/config.yaml` 文件中。
+
+
+Box 相关配置应设置在 `langbot` 服务上,使用统一的 `BOX__*` 环境变量。LangBot 会在启动时写入 `data/config.yaml`,并通过 INIT RPC 将 Box 配置传给 `langbot_box`。不要在 `langbot_box` 服务上设置 `LANGBOT_BOX_*` 或 `BOX__*`,这些变量不会被直接读取。
+
diff --git a/zh/insight/guide.mdx b/zh/insight/guide.mdx
index 7ba2c1b63..7a3395e6a 100644
--- a/zh/insight/guide.mdx
+++ b/zh/insight/guide.mdx
@@ -38,12 +38,12 @@ LangBot 是一个开源的大语言模型(LLM)原生即时通信机器人平
### 2. 配置机器人
-查看左侧的[配置机器人](/zh/deploy/platforms/readme)
+查看左侧的[配置机器人](/zh/usage/platforms/readme)
### 3. 配置模型
-查看左侧[配置对话模型](/zh/deploy/models/readme)
+查看左侧[配置对话模型](/zh/usage/models/readme)
-完成以上两步后即可使用,如果需要更多功能的配置,可在[流水线](/zh/deploy/pipelines/readme)中设置
+完成以上两步后即可使用,如果需要更多功能的配置,可在[流水线](/zh/usage/pipelines/readme)中设置
diff --git a/zh/usage/knowledge/readme.mdx b/zh/usage/knowledge/readme.mdx
index ba9cd5467..da14b1af2 100644
--- a/zh/usage/knowledge/readme.mdx
+++ b/zh/usage/knowledge/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "使用知识库 (Knowledge Base)"
+title: "知识库 (Knowledge Base)"
---
LangBot 原生支持 RAG(Retrieval-Augmented Generation,即检索增强生成),您可以创建知识库,并将其与流水线绑定,流水线将根据知识库中的内容回答问题。
diff --git a/zh/usage/mcp/readme.mdx b/zh/usage/mcp/readme.mdx
index 6ea5be204..5adf681af 100644
--- a/zh/usage/mcp/readme.mdx
+++ b/zh/usage/mcp/readme.mdx
@@ -1,60 +1,107 @@
---
-title: "使用MCP服务器"
+title: "MCP 服务器"
---
-LangBot 支持使用来自 MCP 服务器的工具,您可以添加 MCP 服务器,使用大语言模型中的工具调用特性,更好的处理 LLM 请求。
+LangBot 支持调用来自 MCP 服务器的工具。添加 MCP 后,启用了工具使用能力的内置 Agent 即可在对话中调用这些工具。
-
- MCP 服务器推荐获取渠道:
- - [ModelScope](https://modelscope.cn/mcp)
- - https://mcp.so
- - https://composio.dev/toolkits
+
+ 首选从 [LangBot Space](https://space.langbot.app) 安装:已上架的 MCP 服务器配置好、开箱即用。
+
+ 也可以从 [ModelScope](https://modelscope.cn/mcp)、[mcp.so](https://mcp.so)、[composio.dev](https://composio.dev/toolkits) 等渠道获取,再按下文手动添加。
-## 打开模型的函数调用功能
+## 三种运行模式
-如图,将模型的`函数调用`功能打开。
+| 模式 | 适合场景 | 备注 |
+|------|----------|------|
+| Streamable HTTP (`mode: "http"`) | 远程 MCP 服务,支持 Streamable HTTP 传输 | LangBot 直接连接远程 URL |
+| SSE | 远程 MCP 服务,支持 SSE 传输 | LangBot 直接连接远程 URL |
+| stdio | 本地命令启动的 MCP Server | 仅在 Box Runtime 可用时支持 |
-
+
+MCP 工具需要流水线使用**内置 Agent**,并选择**已开启工具使用能力**的模型——见[模型](../models/readme)。Dify、n8n、Langflow、Coze 等外部 Runner 使用各自平台的工具机制。
+
-## 创建MCP服务器
+## 安装 MCP 服务器
-点击`插件管理` -\> `MCP管理`,如图所示:
+### 从 LangBot Space(首选)
-
+[LangBot Space](https://space.langbot.app) 是 LangBot 的官方市场,已上架多种 MCP 服务器。在 WebUI 的 `插件管理` → `MCP 管理` 页面浏览并一键安装,URL、命令、运行模式等参数由市场提供,无需手动填写。
-点击右上角的`添加`,选择`添加 MCP 服务器`,
+适合大多数场景;接入未上架的服务再走下面的方式。
-
+### 手动添加
-比如使用 Fetch HTML 服务器,填写对应的 URL,点击`测试`用来测试 MCP 服务器,点`提交`添加此服务器。
+进入 `插件管理` → `MCP 管理`:
-添加完成之后,点击卡片上的开关以连接 MCP 服务器,点击卡片可以看到 MCP 服务器的详情:
+
-
+点击右上角 `添加` → `添加 MCP 服务器`,填写 URL(HTTP/SSE)或命令(stdio),点 `测试` 验证连通,点 `提交` 保存:
-## 效果
+
-需要在流水线设置中选用 `内置 Agent` 作为运行器,并使用支持函数调用的模型。
+保存后点击卡片上的开关连接 MCP,点击卡片可查看详情:
-
\ No newline at end of file
+
+
+## 在流水线启用
+
+MCP 服务器添加后,还要在流水线扩展配置里决定 Agent 能看到哪些:
+
+- 开启"启用所有 MCP Server",或
+- 只绑定指定 MCP Server
+
+未绑定的 MCP 工具不会进入该流水线的工具列表。
+
+## stdio MCP 高级配置
+
+stdio MCP 由 Box Runtime 托管,连接前 LangBot 会:
+
+1. 创建或复用共享的 MCP Box session
+2. 如果能从命令推断本地项目路径,把项目 staging 到工作区
+3. 项目含 `requirements.txt` / `pyproject.toml` / `setup.py` / `setup.cfg` 时先安装依赖
+4. 通过 WebSocket relay 接 MCP 进程的 stdin/stdout
+
+需要细化挂载、网络、超时等行为时,可在 MCP 配置的 `extra_args` 里加 `box` 覆盖项:
+
+```json
+{
+ "mode": "stdio",
+ "extra_args": {
+ "command": "python",
+ "args": ["server.py"],
+ "env": {},
+ "box": {
+ "host_path": "/path/to/mcp-project",
+ "network": "on",
+ "host_path_mode": "ro",
+ "startup_timeout_sec": 120,
+ "image": "python:3.11-slim"
+ }
+ }
+}
+```
+
+常用字段:
+
+| 字段 | 说明 |
+|------|------|
+| `host_path` | MCP 项目在宿主机上的目录。需在 `box.local.allowed_mount_roots` 允许范围内 |
+| `network` | 是否允许网络(依赖安装常用) |
+| `host_path_mode` | 准备 `host_path` 时的访问模式,默认 `ro`;stdio MCP 通常会先 staging 到工作区 |
+| `startup_timeout_sec` | Box 准备和依赖安装超时,默认 120 秒;连接等待会额外预留约 30 秒 |
+| `image` | Docker 后端使用的运行镜像 |
+
+
+stdio MCP 在 Box 中运行,依赖安装和进程启动受 sandbox profile、网络权限、资源限制和挂载白名单影响。
+
+
+## 常见问题
+
+| 现象 | 检查项 |
+|------|--------|
+| MCP 连接失败 | URL、命令、参数、环境变量是否正确 |
+| stdio MCP 一直连接中 | Box Runtime 是否可用,`startup_timeout_sec` 是否过短 |
+| 依赖安装失败 | sandbox 是否允许网络,依赖文件是否正确 |
+| 本地文件无法访问 | `host_path` 是否存在,是否在 `allowed_mount_roots` 内 |
+| Agent 看不到 MCP 工具 | 流水线是否使用内置 Agent、模型是否启用工具使用能力、MCP 是否在流水线中绑定 |
diff --git a/zh/usage/models/readme.mdx b/zh/usage/models/readme.mdx
index e2a656096..301b5fc51 100644
--- a/zh/usage/models/readme.mdx
+++ b/zh/usage/models/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "配置模型 (Models)"
+title: "模型 (Models)"
---
## LangBot Models
@@ -45,8 +45,14 @@ LangBot Models 是 LangBot 官方提供的模型服务。当您使用 LangBot Sp
模型能力方面,请根据具体模型特性来选择:
-- 视觉能力:需要启用才可以识图
-- 函数调用:需要启用才可以在对话中使用 Agent 工具
+- **视觉能力**:启用后才能识别图片
+- **工具使用能力**(function calling / tool use):启用后 LLM 才能在对话中调用工具
+
+
+**只要想使用来自 MCP 服务器、沙箱内置工具(`exec`/`read`/`write`/`edit`/`glob`/`grep`)、Skills 的能力,都必须为模型启用工具使用能力。** 否则即使流水线绑定了这些扩展,Agent 也不会调用任何工具。
+
+模型本身需要支持 function calling 才能勾选。不确定时请查阅模型供应商的文档。
+
### 嵌入模型 (Embedding Model)
diff --git a/zh/usage/pipelines/readme.mdx b/zh/usage/pipelines/readme.mdx
index 30314cc98..e5ec3b2df 100644
--- a/zh/usage/pipelines/readme.mdx
+++ b/zh/usage/pipelines/readme.mdx
@@ -1,5 +1,5 @@
---
-title: "修改对话流水线配置 (Pipelines)"
+title: "对话流水线 (Pipelines)"
---
流水线控制了收到消息之后的处理流程,以及与大模型之间的信息交互。每个机器人可以绑定到一条流水线上,同一条流水线能被多个机器人绑定。
diff --git a/zh/usage/sandbox/config.mdx b/zh/usage/sandbox/config.mdx
new file mode 100644
index 000000000..77430dd13
--- /dev/null
+++ b/zh/usage/sandbox/config.mdx
@@ -0,0 +1,147 @@
+---
+title: "沙箱配置"
+---
+
+沙箱由 LangBot 主进程配置,Box Runtime 负责实际执行。常规部署只需要选择后端、设置工作目录和安全预设。
+
+
+本页所有 `box.*` 配置都写在 `data/config.yaml` 中。配置文件的位置和加载机制详见[系统环境设置](../../deploy/settings)。
+
+
+## 推荐配置
+
+```yaml
+box:
+ enabled: true
+ backend: 'local' # 自动从 Docker / Nsjail 里选可用的
+ local:
+ profile: 'default'
+ host_root: './data/box'
+ skills_root: 'skills'
+```
+
+- `enabled`:沙箱总开关。设为 `false` 时,沙箱内置工具、Skill 添加/编辑、stdio MCP 托管等依赖 Box 的能力都不可用。
+- `backend`:见下文「后端选择」。
+- `local.profile`:安全预设,控制网络、挂载和资源限制。
+- `local.host_root`:主机上的沙箱工作目录,会映射为沙箱内的 `/workspace`。
+- `local.skills_root`:Skill 包目录;相对路径解析到 `host_root` 下,默认 `host_root/skills`。
+
+
+Skills 只从 Box Runtime 管理的 skill store 加载。Box Runtime 或后端不可用时 Skill 列表为空,新增 / 编辑 / `register_skill` 都不可用;不会回退扫描 `data/skills/`。
+
+
+## 后端选择
+
+沙箱可以跑在**本机容器**或**云端**。`box.backend` 选择走哪一种:
+
+| `backend` | 跑在哪 | 行为 |
+|-----------|--------|------|
+| `local`(默认) | 本机容器 | 自动从 Docker / Nsjail 里选可用的(Docker 优先) |
+| `docker` | 本机容器 | 强制使用 Docker,需要 Docker daemon |
+| `nsjail` | 本机容器 | 强制使用 Nsjail(仅 Linux),不支持自定义镜像 |
+| `e2b` | 云端 | 使用 [E2B](https://e2b.dev) 云沙箱,需要 API Key |
+
+`local` 是「自动选择」的简写,不是和 `docker`/`nsjail` 平级的第四种后端。本机容器后端(`local`/`docker`/`nsjail`)**共用** `box.local.*` 配置段;云端后端用 `box.e2b.*` 配置段。
+
+
+`backend` 是强制值。设为 `docker` 时如果 Docker 不可用,**不会**自动回退到 Nsjail 或 E2B——只有 `local` 会自动 fan-out。
+
+也可以用环境变量 `BOX__BACKEND` 覆盖配置(优先级高于 `config.yaml`)。
+
+
+## 安全预设
+
+`box.local.profile` 控制本机后端的网络、挂载、资源限制:
+
+| Profile | 网络 | 挂载 | 资源 | 建议场景 |
+|---------|------|------|------|----------|
+| `default` | 关闭 | 读写 | 默认限制 | 默认选择 |
+| `offline_readonly` | 关闭 | 只读 | 更严格 | 读取不可信文件 |
+| `network_basic` | 开启基础网络 | 读写 | 默认限制 | 需要访问 API 或下载依赖 |
+| `network_extended` | 开启完整网络 | 读写 | 更宽松 | 开发、调试、复杂任务 |
+
+优先使用最小权限:不需要网络就用 `default` 或 `offline_readonly`;只把必要目录加入 `allowed_mount_roots`。
+
+## 本机后端配置(box.local.*)
+
+本机后端(`local` / `docker` / `nsjail`)共用以下配置:
+
+| 配置项 | 默认值 | 说明 |
+|--------|--------|------|
+| `local.profile` | `default` | 见上文「安全预设」 |
+| `local.image` | 空 | Docker 后端的自定义镜像;空 = 用 profile 默认 |
+| `local.host_root` | `./data/box` | 主机工作目录基础路径,映射为沙箱内 `/workspace` |
+| `local.default_workspace` | 空 | 默认工作空间名;空 = `/default` |
+| `local.skills_root` | `skills` | Skill 包目录;相对路径解析到 `host_root` 下 |
+| `local.allowed_mount_roots` | `[host_root]` | Agent 可请求挂载的主机目录白名单 |
+| `local.workspace_quota_mb` | `null` | 工作区磁盘配额(MB),`null` = 用 profile 默认 |
+
+## 云端后端配置(box.e2b.*)
+
+设为 `backend: 'e2b'` 后配置:
+
+| 配置项 | 默认值 | 说明 |
+|--------|--------|------|
+| `e2b.api_key` | 空 | E2B API Key,也可用 `E2B_API_KEY` 环境变量 |
+| `e2b.api_url` | 空 | 自建 E2B 服务地址,也可用 `E2B_API_URL` |
+| `e2b.template` | 空 | 默认 E2B 模板 ID |
+
+E2B 不需要本机 Docker 或 Nsjail,每次执行都走远程沙箱。
+
+## Docker Compose 部署
+
+Docker Compose 部署时,沙箱配置写在 `langbot` 服务上。LangBot 启动后会通过 INIT RPC 把配置下发给 `langbot_box`。
+
+```yaml
+services:
+ langbot_box:
+ image: rockchin/langbot:latest
+ container_name: langbot_box
+ profiles: ["box", "all"]
+ volumes:
+ - ${LANGBOT_BOX_ROOT:-${PWD}/data/box}:${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - /var/run/docker.sock:/var/run/docker.sock
+ command: ["uv", "run", "--no-sync", "-m", "langbot_plugin.cli.__init__", "box"]
+
+ langbot:
+ image: rockchin/langbot:latest
+ volumes:
+ - ./data:/app/data
+ environment:
+ - BOX__LOCAL__HOST_ROOT=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+ - BOX__LOCAL__SKILLS_ROOT=skills
+ - BOX__LOCAL__ALLOWED_MOUNT_ROOTS=${LANGBOT_BOX_ROOT:-${PWD}/data/box}
+```
+
+
+`langbot_box` 需要访问 Docker daemon。只在受信任环境中挂载 `docker.sock`;并保持 Box 根目录在主机和 `langbot_box` 容器内路径一致。
+
+
+如需 LangBot 连接外部 Box Runtime(例如远程主机),用 `box.runtime.endpoint` 指定 URL:
+
+```yaml
+box:
+ runtime:
+ endpoint: 'ws://192.168.1.10:5410'
+```
+
+## 环境变量
+
+| 环境变量 | 写入配置 |
+|----------|----------|
+| `BOX__ENABLED` | `box.enabled` |
+| `BOX__BACKEND` | `box.backend` |
+| `BOX__LOCAL__PROFILE` | `box.local.profile` |
+| `BOX__LOCAL__IMAGE` | `box.local.image` |
+| `BOX__LOCAL__HOST_ROOT` | `box.local.host_root` |
+| `BOX__LOCAL__DEFAULT_WORKSPACE` | `box.local.default_workspace` |
+| `BOX__LOCAL__SKILLS_ROOT` | `box.local.skills_root` |
+| `BOX__LOCAL__ALLOWED_MOUNT_ROOTS` | `box.local.allowed_mount_roots`,逗号分隔 |
+| `BOX__LOCAL__WORKSPACE_QUOTA_MB` | `box.local.workspace_quota_mb` |
+| `BOX__E2B__API_KEY` | `box.e2b.api_key` |
+| `BOX__E2B__API_URL` | `box.e2b.api_url` |
+| `BOX__E2B__TEMPLATE` | `box.e2b.template` |
+
+
+不要在 `langbot_box` 服务上设置 `BOX__*` 或 `LANGBOT_BOX_*` 变量;这些变量不会被 Box Runtime 直接读取——它的配置由 LangBot 通过 INIT RPC 下发。
+
diff --git a/zh/usage/sandbox/readme.mdx b/zh/usage/sandbox/readme.mdx
new file mode 100644
index 000000000..1ed7617cc
--- /dev/null
+++ b/zh/usage/sandbox/readme.mdx
@@ -0,0 +1,73 @@
+---
+title: "沙箱 (Sandbox)"
+---
+
+沙箱给内置 Agent 一个隔离的执行环境:跑命令、读写文件、运行长驻进程。日常 Agent 应用(数据处理、文件操作、运行用户代码、托管 stdio MCP)都依赖它。
+
+启用沙箱后,内置 Agent 会自动获得六个工具,无需在流水线里逐项开启。
+
+## 内置工具
+
+| 工具 | 用途 |
+|------|------|
+| `exec` | 在沙箱内执行 Shell 命令 |
+| `read` | 读取工作区文件 |
+| `write` | 创建或覆盖文件 |
+| `edit` | 字符串替换式修改文件 |
+| `glob` | 按 glob 模式查找文件 |
+| `grep` | 按正则搜索文件内容 |
+
+`exec` 在沙箱容器内运行;其余五个直接读写主机映射到 `/workspace` 的目录。
+
+
+这些工具面向内置 Agent。使用 Dify、n8n、Langflow、Coze 等外部 Runner 时,请使用对应平台自己的工具机制。
+
+
+## 沙箱作用域
+
+在流水线 AI 配置中可选择沙箱在不同消息间如何共享。默认"每个会话"足够大多数场景使用。
+
+| 作用域 | 模板 | 共享范围 |
+|--------|------|---------|
+| 全局 | `{global}` | 所有用户共用一个沙箱 |
+| 每个会话(默认) | `{launcher_type}_{launcher_id}` | 同一群/私聊共用 |
+| 每个用户 | `{launcher_type}_{launcher_id}_{sender_id}` | 群里每位成员独立 |
+| 每个对话 | `{launcher_type}_{launcher_id}_{conversation_id}` | 按对话隔离 |
+| 每条消息 | `{query_id}` | 完全无状态 |
+
+
+同一作用域内的命令共享文件系统状态。需要完全隔离请选"每条消息"。
+
+
+## 生命周期
+
+| 情况 | 行为 |
+|------|------|
+| 空闲超过 5 分钟 | 自动清理 |
+| 有 Box 托管进程(如 stdio MCP)在跑 | 不清理,进程结束后才释放 |
+| 配置 `persistent: true` | 永不自动清理 |
+
+## 快速开始
+
+1. **准备后端**:本机装好 Docker,或选择 Nsjail / E2B
+2. **写入 `config.yaml`**:
+ ```yaml
+ box:
+ enabled: true
+ backend: 'local'
+ local:
+ host_root: './data/box'
+ ```
+3. **启动 LangBot**:沙箱自动启用
+4. **在流水线里**选择内置 Agent + 支持函数调用的模型
+
+之后 Agent 会自动获得六个工具。详细配置见[沙箱配置](./config)。
+
+## 关闭沙箱
+
+设置 `box.enabled: false`。所有依赖沙箱的能力(内置工具、Skill 创建/编辑/激活、stdio MCP)会一并停用;http/sse 模式的 MCP 不受影响。
+
+## 下一步
+
+- [沙箱配置](./config) — 后端、安全预设、挂载、环境变量
+- [运行时与扩展关系](./runtime-relationships) — 沙箱、Skills、MCP、插件如何分工
diff --git a/zh/usage/sandbox/runtime-relationships.mdx b/zh/usage/sandbox/runtime-relationships.mdx
new file mode 100644
index 000000000..942f27659
--- /dev/null
+++ b/zh/usage/sandbox/runtime-relationships.mdx
@@ -0,0 +1,45 @@
+---
+title: "运行时与扩展关系"
+---
+
+LangBot 里同时存在**插件、MCP、Skills、沙箱**四种扩展机制,容易混淆。本页帮你区分它们的职责和适用场景。
+
+## 一句话区分
+
+- **沙箱**:执行环境,让 Agent 跑命令、读写文件
+- **Skills**:按需激活的指令包,给 Agent 临时增加一段专业工作流
+- **MCP Server**:接入外部工具服务
+- **插件**:长期运行的扩展进程,可带配置页、事件监听、知识库
+
+## 对照表
+
+| 能力 | 提供方 | 给 Agent 的形式 | 何时使用 |
+|------|--------|----------------|---------|
+| 沙箱 | Box Runtime | 直接挂上 `exec/read/write/edit/glob/grep` 六件套 | Agent 要执行代码、读写文件 |
+| Skills | Box Runtime skill store | Agent 调 `activate` 后,指令通过 Tool Result 注入 | 想给 Agent 加一段流程/模板/脚本,按需触发 |
+| MCP Server | LangBot MCP Loader(stdio 模式由 Box 托管) | 工具直接进入可用工具列表 | 接入已有的 MCP 服务 |
+| 插件 | Plugin Runtime | 由插件系统暴露能力 | 长期能力、需要配置页/事件监听/知识库组件 |
+
+## 流水线绑定
+
+Skills、MCP Server、插件都属于**流水线扩展**。在 WebUI 安装/创建后,还要在流水线扩展配置里决定启用范围:
+
+- 启用全部扩展,或
+- 只绑定指定的扩展
+
+Skills 的绑定决定 Agent **能看到哪些技能**(影响 `` 列表)。具体技能内容只有 Agent 调用 `activate` 后才会注入。
+
+## 排障入口
+
+| 现象 | 优先检查 |
+|------|---------|
+| Agent 没有 `exec/read/write` 工具 | `box.enabled`、后端是否可用、流水线是否用内置 Agent |
+| Skill 列表为空 | Box Runtime 状态、`box.local.skills_root`、流水线绑定 |
+| stdio MCP 启动失败 | Box Runtime 状态、MCP 命令和环境变量、启动超时 |
+| Docker 部署沙箱启不来 | `langbot_box` 是否挂载 `docker.sock`、Box 根目录路径是否一致 |
+| 文件读写失败 | `box.local.host_root`、`box.local.allowed_mount_roots` |
+| 后端选择不生效 | 确认 `BOX__BACKEND` 设在 `langbot` 服务上,不是 `langbot_box` |
+
+
+沙箱内置工具和 Skills 当前面向内置 Agent。外部 Runner(Dify、n8n、Langflow、Coze 等)应使用各自平台的工具和执行机制。
+
diff --git a/zh/usage/skills/readme.mdx b/zh/usage/skills/readme.mdx
new file mode 100644
index 000000000..264d742da
--- /dev/null
+++ b/zh/usage/skills/readme.mdx
@@ -0,0 +1,100 @@
+---
+title: "技能 (Skills)"
+---
+
+Skill 是一个**按需激活**的指令包:用户描述匹配时,Agent 调用 `activate` 工具把这个技能的指令拉进上下文,然后按指令完成任务。未激活的技能不占用上下文。
+
+适合给 Agent 加一段**专业流程、模板或脚本**——比如"分析 Python 项目"、"PDF 表单填充"、"代码评审"——而不必每个对话都把指令塞进 System Prompt。
+
+## 与插件、MCP 的区别
+
+| 你想做的事 | 用这个 |
+|------------|--------|
+| 按需触发的一段工作流(可带脚本、模板) | Skill |
+| 接入已有的 MCP 工具服务 | MCP Server |
+| 长期能力,需要配置页、事件、知识库 | 插件 |
+
+详见[运行时与扩展关系](../sandbox/runtime-relationships)。
+
+## 安装技能
+
+
+技能依赖沙箱:`box.enabled` 为 `true` 且 Docker / Nsjail / E2B 至少一个可用时,才能安装、激活和编辑技能。详见[沙箱配置](../sandbox/config)。
+
+
+### 从 LangBot Space(首选)
+
+[LangBot Space](https://space.langbot.app) 是 LangBot 的官方市场,已上架多种技能。在 WebUI 的 Skills 页面浏览并一键安装,无需自己编写 `SKILL.md` 或准备资源文件。
+
+适合大多数场景。需要自定义流程再走下面的方式。
+
+### 自己创建技能
+
+**WebUI** — Skills 页面新建、上传 zip 包、从 GitHub 导入。
+
+**沙箱 + `register_skill`**:
+1. 在沙箱 `/workspace` 下准备好目录和 `SKILL.md`
+2. 让 Agent 调用 `register_skill(path="/workspace/my-skill")`
+
+两种方式都会写入 Box Runtime 管理的 skill store。
+
+## 在流水线启用
+
+技能装好之后,还要在流水线扩展配置里决定 Agent 能看到哪些:
+
+- 开启"启用所有技能",或
+- 只绑定指定技能
+
+绑定只影响 `` 列表(即 Agent 能从哪些技能里挑),完整指令永远等 `activate` 被调用后才注入。
+
+## 编写 SKILL.md
+
+技能就是一个目录加一个 `SKILL.md`。frontmatter 写元数据,正文是 Agent 激活后会收到的指令:
+
+```markdown
+---
+name: code-reviewer
+display_name: 代码评审助手
+description: 审查代码并给出改进建议;用户提到 review、评审、代码改进时触发
+---
+
+## 执行步骤
+
+1. 用 `read` 浏览相关文件
+2. 检查可读性、潜在 bug、安全问题
+3. 给出按优先级排序的改进建议
+```
+
+LangBot 当前读取以下三个字段:
+
+| 字段 | 必需 | 说明 |
+|------|------|------|
+| `name` | 创建/注册时 | 唯一标识,1–64 字符 |
+| `description` | 强烈建议 | Agent 用它判断何时激活——越具体越能选中 |
+| `display_name` | 否 | UI 显示名 |
+
+`description` 是 Agent 挑技能的唯一依据,要写清楚**功能、适用场景、可能的触发关键词**。
+
+完整规范见 [agentskills.io](https://agentskills.io/home)。其它字段(`license`、`metadata` 等)可保留供未来兼容,当前不会被读取。
+
+**带资源的技能**在 `SKILL.md` 同级放 `scripts/`、`templates/` 等目录,激活后 Agent 通过 `/workspace/.skills/{skill-name}/` 访问。
+
+### Agent 可用的工具
+
+| 工具 | 用途 |
+|------|------|
+| `activate` | Agent 判断匹配时自动调用,把 SKILL.md 拉进上下文 |
+| `register_skill` | 把沙箱里准备好的目录注册为新技能 |
+
+## 常见问题
+
+| 现象 | 检查项 |
+|------|--------|
+| 技能列表为空 | `box.enabled`、Box Runtime 状态、`box.local.skills_root` |
+| Agent 不激活技能 | `description` 是否具体、流水线是否绑定、模型是否支持函数调用 |
+| 激活后找不到文件 | 文件需在 Skill 包内,路径是 `/workspace/.skills/{skill-name}/` |
+| `register_skill` 报错 | 路径必须在 `/workspace` 下,目录或两层内子目录需含 `SKILL.md` |
+
+
+Skills 当前面向内置 Agent,依赖函数调用和沙箱后端。外部 Runner(Dify、n8n、Langflow、Coze 等)请使用各自平台的等价机制。
+