diff --git a/docs/.agents/skills/writing-skills/SKILL.md b/docs/.agents/skills/writing-skills/SKILL.md
new file mode 100644
index 000000000..c3b73d8b1
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/SKILL.md
@@ -0,0 +1,655 @@
+---
+name: writing-skills
+description: Use when creating new skills, editing existing skills, or verifying skills work before deployment
+---
+
+# Writing Skills
+
+## Overview
+
+**Writing skills IS Test-Driven Development applied to process documentation.**
+
+**Personal skills live in agent-specific directories (`~/.claude/skills` for Claude Code, `~/.agents/skills/` for Codex)**
+
+You write test cases (pressure scenarios with subagents), watch them fail (baseline behavior), write the skill (documentation), watch tests pass (agents comply), and refactor (close loopholes).
+
+**Core principle:** If you didn't watch an agent fail without the skill, you don't know if the skill teaches the right thing.
+
+**REQUIRED BACKGROUND:** You MUST understand superpowers:test-driven-development before using this skill. That skill defines the fundamental RED-GREEN-REFACTOR cycle. This skill adapts TDD to documentation.
+
+**Official guidance:** For Anthropic's official skill authoring best practices, see anthropic-best-practices.md. This document provides additional patterns and guidelines that complement the TDD-focused approach in this skill.
+
+## What is a Skill?
+
+A **skill** is a reference guide for proven techniques, patterns, or tools. Skills help future Claude instances find and apply effective approaches.
+
+**Skills are:** Reusable techniques, patterns, tools, reference guides
+
+**Skills are NOT:** Narratives about how you solved a problem once
+
+## TDD Mapping for Skills
+
+| TDD Concept | Skill Creation |
+|-------------|----------------|
+| **Test case** | Pressure scenario with subagent |
+| **Production code** | Skill document (SKILL.md) |
+| **Test fails (RED)** | Agent violates rule without skill (baseline) |
+| **Test passes (GREEN)** | Agent complies with skill present |
+| **Refactor** | Close loopholes while maintaining compliance |
+| **Write test first** | Run baseline scenario BEFORE writing skill |
+| **Watch it fail** | Document exact rationalizations agent uses |
+| **Minimal code** | Write skill addressing those specific violations |
+| **Watch it pass** | Verify agent now complies |
+| **Refactor cycle** | Find new rationalizations → plug → re-verify |
+
+The entire skill creation process follows RED-GREEN-REFACTOR.
+
+## When to Create a Skill
+
+**Create when:**
+- Technique wasn't intuitively obvious to you
+- You'd reference this again across projects
+- Pattern applies broadly (not project-specific)
+- Others would benefit
+
+**Don't create for:**
+- One-off solutions
+- Standard practices well-documented elsewhere
+- Project-specific conventions (put in CLAUDE.md)
+- Mechanical constraints (if it's enforceable with regex/validation, automate it—save documentation for judgment calls)
+
+## Skill Types
+
+### Technique
+Concrete method with steps to follow (condition-based-waiting, root-cause-tracing)
+
+### Pattern
+Way of thinking about problems (flatten-with-flags, test-invariants)
+
+### Reference
+API docs, syntax guides, tool documentation (office docs)
+
+## Directory Structure
+
+
+```
+skills/
+ skill-name/
+ SKILL.md # Main reference (required)
+ supporting-file.* # Only if needed
+```
+
+**Flat namespace** - all skills in one searchable namespace
+
+**Separate files for:**
+1. **Heavy reference** (100+ lines) - API docs, comprehensive syntax
+2. **Reusable tools** - Scripts, utilities, templates
+
+**Keep inline:**
+- Principles and concepts
+- Code patterns (< 50 lines)
+- Everything else
+
+## SKILL.md Structure
+
+**Frontmatter (YAML):**
+- Two required fields: `name` and `description` (see [agentskills.io/specification](https://agentskills.io/specification) for all supported fields)
+- Max 1024 characters total
+- `name`: Use letters, numbers, and hyphens only (no parentheses, special chars)
+- `description`: Third-person, describes ONLY when to use (NOT what it does)
+ - Start with "Use when..." to focus on triggering conditions
+ - Include specific symptoms, situations, and contexts
+ - **NEVER summarize the skill's process or workflow** (see CSO section for why)
+ - Keep under 500 characters if possible
+
+```markdown
+---
+name: Skill-Name-With-Hyphens
+description: Use when [specific triggering conditions and symptoms]
+---
+
+# Skill Name
+
+## Overview
+What is this? Core principle in 1-2 sentences.
+
+## When to Use
+[Small inline flowchart IF decision non-obvious]
+
+Bullet list with SYMPTOMS and use cases
+When NOT to use
+
+## Core Pattern (for techniques/patterns)
+Before/after code comparison
+
+## Quick Reference
+Table or bullets for scanning common operations
+
+## Implementation
+Inline code for simple patterns
+Link to file for heavy reference or reusable tools
+
+## Common Mistakes
+What goes wrong + fixes
+
+## Real-World Impact (optional)
+Concrete results
+```
+
+
+## Claude Search Optimization (CSO)
+
+**Critical for discovery:** Future Claude needs to FIND your skill
+
+### 1. Rich Description Field
+
+**Purpose:** Claude reads description to decide which skills to load for a given task. Make it answer: "Should I read this skill right now?"
+
+**Format:** Start with "Use when..." to focus on triggering conditions
+
+**CRITICAL: Description = When to Use, NOT What the Skill Does**
+
+The description should ONLY describe triggering conditions. Do NOT summarize the skill's process or workflow in the description.
+
+**Why this matters:** Testing revealed that when a description summarizes the skill's workflow, Claude may follow the description instead of reading the full skill content. A description saying "code review between tasks" caused Claude to do ONE review, even though the skill's flowchart clearly showed TWO reviews (spec compliance then code quality).
+
+When the description was changed to just "Use when executing implementation plans with independent tasks" (no workflow summary), Claude correctly read the flowchart and followed the two-stage review process.
+
+**The trap:** Descriptions that summarize workflow create a shortcut Claude will take. The skill body becomes documentation Claude skips.
+
+```yaml
+# ❌ BAD: Summarizes workflow - Claude may follow this instead of reading skill
+description: Use when executing plans - dispatches subagent per task with code review between tasks
+
+# ❌ BAD: Too much process detail
+description: Use for TDD - write test first, watch it fail, write minimal code, refactor
+
+# ✅ GOOD: Just triggering conditions, no workflow summary
+description: Use when executing implementation plans with independent tasks in the current session
+
+# ✅ GOOD: Triggering conditions only
+description: Use when implementing any feature or bugfix, before writing implementation code
+```
+
+**Content:**
+- Use concrete triggers, symptoms, and situations that signal this skill applies
+- Describe the *problem* (race conditions, inconsistent behavior) not *language-specific symptoms* (setTimeout, sleep)
+- Keep triggers technology-agnostic unless the skill itself is technology-specific
+- If skill is technology-specific, make that explicit in the trigger
+- Write in third person (injected into system prompt)
+- **NEVER summarize the skill's process or workflow**
+
+```yaml
+# ❌ BAD: Too abstract, vague, doesn't include when to use
+description: For async testing
+
+# ❌ BAD: First person
+description: I can help you with async tests when they're flaky
+
+# ❌ BAD: Mentions technology but skill isn't specific to it
+description: Use when tests use setTimeout/sleep and are flaky
+
+# ✅ GOOD: Starts with "Use when", describes problem, no workflow
+description: Use when tests have race conditions, timing dependencies, or pass/fail inconsistently
+
+# ✅ GOOD: Technology-specific skill with explicit trigger
+description: Use when using React Router and handling authentication redirects
+```
+
+### 2. Keyword Coverage
+
+Use words Claude would search for:
+- Error messages: "Hook timed out", "ENOTEMPTY", "race condition"
+- Symptoms: "flaky", "hanging", "zombie", "pollution"
+- Synonyms: "timeout/hang/freeze", "cleanup/teardown/afterEach"
+- Tools: Actual commands, library names, file types
+
+### 3. Descriptive Naming
+
+**Use active voice, verb-first:**
+- ✅ `creating-skills` not `skill-creation`
+- ✅ `condition-based-waiting` not `async-test-helpers`
+
+### 4. Token Efficiency (Critical)
+
+**Problem:** getting-started and frequently-referenced skills load into EVERY conversation. Every token counts.
+
+**Target word counts:**
+- getting-started workflows: <150 words each
+- Frequently-loaded skills: <200 words total
+- Other skills: <500 words (still be concise)
+
+**Techniques:**
+
+**Move details to tool help:**
+```bash
+# ❌ BAD: Document all flags in SKILL.md
+search-conversations supports --text, --both, --after DATE, --before DATE, --limit N
+
+# ✅ GOOD: Reference --help
+search-conversations supports multiple modes and filters. Run --help for details.
+```
+
+**Use cross-references:**
+```markdown
+# ❌ BAD: Repeat workflow details
+When searching, dispatch subagent with template...
+[20 lines of repeated instructions]
+
+# ✅ GOOD: Reference other skill
+Always use subagents (50-100x context savings). REQUIRED: Use [other-skill-name] for workflow.
+```
+
+**Compress examples:**
+```markdown
+# ❌ BAD: Verbose example (42 words)
+your human partner: "How did we handle authentication errors in React Router before?"
+You: I'll search past conversations for React Router authentication patterns.
+[Dispatch subagent with search query: "React Router authentication error handling 401"]
+
+# ✅ GOOD: Minimal example (20 words)
+Partner: "How did we handle auth errors in React Router?"
+You: Searching...
+[Dispatch subagent → synthesis]
+```
+
+**Eliminate redundancy:**
+- Don't repeat what's in cross-referenced skills
+- Don't explain what's obvious from command
+- Don't include multiple examples of same pattern
+
+**Verification:**
+```bash
+wc -w skills/path/SKILL.md
+# getting-started workflows: aim for <150 each
+# Other frequently-loaded: aim for <200 total
+```
+
+**Name by what you DO or core insight:**
+- ✅ `condition-based-waiting` > `async-test-helpers`
+- ✅ `using-skills` not `skill-usage`
+- ✅ `flatten-with-flags` > `data-structure-refactoring`
+- ✅ `root-cause-tracing` > `debugging-techniques`
+
+**Gerunds (-ing) work well for processes:**
+- `creating-skills`, `testing-skills`, `debugging-with-logs`
+- Active, describes the action you're taking
+
+### 4. Cross-Referencing Other Skills
+
+**When writing documentation that references other skills:**
+
+Use skill name only, with explicit requirement markers:
+- ✅ Good: `**REQUIRED SUB-SKILL:** Use superpowers:test-driven-development`
+- ✅ Good: `**REQUIRED BACKGROUND:** You MUST understand superpowers:systematic-debugging`
+- ❌ Bad: `See skills/testing/test-driven-development` (unclear if required)
+- ❌ Bad: `@skills/testing/test-driven-development/SKILL.md` (force-loads, burns context)
+
+**Why no @ links:** `@` syntax force-loads files immediately, consuming 200k+ context before you need them.
+
+## Flowchart Usage
+
+```dot
+digraph when_flowchart {
+ "Need to show information?" [shape=diamond];
+ "Decision where I might go wrong?" [shape=diamond];
+ "Use markdown" [shape=box];
+ "Small inline flowchart" [shape=box];
+
+ "Need to show information?" -> "Decision where I might go wrong?" [label="yes"];
+ "Decision where I might go wrong?" -> "Small inline flowchart" [label="yes"];
+ "Decision where I might go wrong?" -> "Use markdown" [label="no"];
+}
+```
+
+**Use flowcharts ONLY for:**
+- Non-obvious decision points
+- Process loops where you might stop too early
+- "When to use A vs B" decisions
+
+**Never use flowcharts for:**
+- Reference material → Tables, lists
+- Code examples → Markdown blocks
+- Linear instructions → Numbered lists
+- Labels without semantic meaning (step1, helper2)
+
+See @graphviz-conventions.dot for graphviz style rules.
+
+**Visualizing for your human partner:** Use `render-graphs.js` in this directory to render a skill's flowcharts to SVG:
+```bash
+./render-graphs.js ../some-skill # Each diagram separately
+./render-graphs.js ../some-skill --combine # All diagrams in one SVG
+```
+
+## Code Examples
+
+**One excellent example beats many mediocre ones**
+
+Choose most relevant language:
+- Testing techniques → TypeScript/JavaScript
+- System debugging → Shell/Python
+- Data processing → Python
+
+**Good example:**
+- Complete and runnable
+- Well-commented explaining WHY
+- From real scenario
+- Shows pattern clearly
+- Ready to adapt (not generic template)
+
+**Don't:**
+- Implement in 5+ languages
+- Create fill-in-the-blank templates
+- Write contrived examples
+
+You're good at porting - one great example is enough.
+
+## File Organization
+
+### Self-Contained Skill
+```
+defense-in-depth/
+ SKILL.md # Everything inline
+```
+When: All content fits, no heavy reference needed
+
+### Skill with Reusable Tool
+```
+condition-based-waiting/
+ SKILL.md # Overview + patterns
+ example.ts # Working helpers to adapt
+```
+When: Tool is reusable code, not just narrative
+
+### Skill with Heavy Reference
+```
+pptx/
+ SKILL.md # Overview + workflows
+ pptxgenjs.md # 600 lines API reference
+ ooxml.md # 500 lines XML structure
+ scripts/ # Executable tools
+```
+When: Reference material too large for inline
+
+## The Iron Law (Same as TDD)
+
+```
+NO SKILL WITHOUT A FAILING TEST FIRST
+```
+
+This applies to NEW skills AND EDITS to existing skills.
+
+Write skill before testing? Delete it. Start over.
+Edit skill without testing? Same violation.
+
+**No exceptions:**
+- Not for "simple additions"
+- Not for "just adding a section"
+- Not for "documentation updates"
+- Don't keep untested changes as "reference"
+- Don't "adapt" while running tests
+- Delete means delete
+
+**REQUIRED BACKGROUND:** The superpowers:test-driven-development skill explains why this matters. Same principles apply to documentation.
+
+## Testing All Skill Types
+
+Different skill types need different test approaches:
+
+### Discipline-Enforcing Skills (rules/requirements)
+
+**Examples:** TDD, verification-before-completion, designing-before-coding
+
+**Test with:**
+- Academic questions: Do they understand the rules?
+- Pressure scenarios: Do they comply under stress?
+- Multiple pressures combined: time + sunk cost + exhaustion
+- Identify rationalizations and add explicit counters
+
+**Success criteria:** Agent follows rule under maximum pressure
+
+### Technique Skills (how-to guides)
+
+**Examples:** condition-based-waiting, root-cause-tracing, defensive-programming
+
+**Test with:**
+- Application scenarios: Can they apply the technique correctly?
+- Variation scenarios: Do they handle edge cases?
+- Missing information tests: Do instructions have gaps?
+
+**Success criteria:** Agent successfully applies technique to new scenario
+
+### Pattern Skills (mental models)
+
+**Examples:** reducing-complexity, information-hiding concepts
+
+**Test with:**
+- Recognition scenarios: Do they recognize when pattern applies?
+- Application scenarios: Can they use the mental model?
+- Counter-examples: Do they know when NOT to apply?
+
+**Success criteria:** Agent correctly identifies when/how to apply pattern
+
+### Reference Skills (documentation/APIs)
+
+**Examples:** API documentation, command references, library guides
+
+**Test with:**
+- Retrieval scenarios: Can they find the right information?
+- Application scenarios: Can they use what they found correctly?
+- Gap testing: Are common use cases covered?
+
+**Success criteria:** Agent finds and correctly applies reference information
+
+## Common Rationalizations for Skipping Testing
+
+| Excuse | Reality |
+|--------|---------|
+| "Skill is obviously clear" | Clear to you ≠ clear to other agents. Test it. |
+| "It's just a reference" | References can have gaps, unclear sections. Test retrieval. |
+| "Testing is overkill" | Untested skills have issues. Always. 15 min testing saves hours. |
+| "I'll test if problems emerge" | Problems = agents can't use skill. Test BEFORE deploying. |
+| "Too tedious to test" | Testing is less tedious than debugging bad skill in production. |
+| "I'm confident it's good" | Overconfidence guarantees issues. Test anyway. |
+| "Academic review is enough" | Reading ≠ using. Test application scenarios. |
+| "No time to test" | Deploying untested skill wastes more time fixing it later. |
+
+**All of these mean: Test before deploying. No exceptions.**
+
+## Bulletproofing Skills Against Rationalization
+
+Skills that enforce discipline (like TDD) need to resist rationalization. Agents are smart and will find loopholes when under pressure.
+
+**Psychology note:** Understanding WHY persuasion techniques work helps you apply them systematically. See persuasion-principles.md for research foundation (Cialdini, 2021; Meincke et al., 2025) on authority, commitment, scarcity, social proof, and unity principles.
+
+### Close Every Loophole Explicitly
+
+Don't just state the rule - forbid specific workarounds:
+
+
+```markdown
+Write code before test? Delete it.
+```
+
+
+
+```markdown
+Write code before test? Delete it. Start over.
+
+**No exceptions:**
+- Don't keep it as "reference"
+- Don't "adapt" it while writing tests
+- Don't look at it
+- Delete means delete
+```
+
+
+### Address "Spirit vs Letter" Arguments
+
+Add foundational principle early:
+
+```markdown
+**Violating the letter of the rules is violating the spirit of the rules.**
+```
+
+This cuts off entire class of "I'm following the spirit" rationalizations.
+
+### Build Rationalization Table
+
+Capture rationalizations from baseline testing (see Testing section below). Every excuse agents make goes in the table:
+
+```markdown
+| Excuse | Reality |
+|--------|---------|
+| "Too simple to test" | Simple code breaks. Test takes 30 seconds. |
+| "I'll test after" | Tests passing immediately prove nothing. |
+| "Tests after achieve same goals" | Tests-after = "what does this do?" Tests-first = "what should this do?" |
+```
+
+### Create Red Flags List
+
+Make it easy for agents to self-check when rationalizing:
+
+```markdown
+## Red Flags - STOP and Start Over
+
+- Code before test
+- "I already manually tested it"
+- "Tests after achieve the same purpose"
+- "It's about spirit not ritual"
+- "This is different because..."
+
+**All of these mean: Delete code. Start over with TDD.**
+```
+
+### Update CSO for Violation Symptoms
+
+Add to description: symptoms of when you're ABOUT to violate the rule:
+
+```yaml
+description: use when implementing any feature or bugfix, before writing implementation code
+```
+
+## RED-GREEN-REFACTOR for Skills
+
+Follow the TDD cycle:
+
+### RED: Write Failing Test (Baseline)
+
+Run pressure scenario with subagent WITHOUT the skill. Document exact behavior:
+- What choices did they make?
+- What rationalizations did they use (verbatim)?
+- Which pressures triggered violations?
+
+This is "watch the test fail" - you must see what agents naturally do before writing the skill.
+
+### GREEN: Write Minimal Skill
+
+Write skill that addresses those specific rationalizations. Don't add extra content for hypothetical cases.
+
+Run same scenarios WITH skill. Agent should now comply.
+
+### REFACTOR: Close Loopholes
+
+Agent found new rationalization? Add explicit counter. Re-test until bulletproof.
+
+**Testing methodology:** See @testing-skills-with-subagents.md for the complete testing methodology:
+- How to write pressure scenarios
+- Pressure types (time, sunk cost, authority, exhaustion)
+- Plugging holes systematically
+- Meta-testing techniques
+
+## Anti-Patterns
+
+### ❌ Narrative Example
+"In session 2025-10-03, we found empty projectDir caused..."
+**Why bad:** Too specific, not reusable
+
+### ❌ Multi-Language Dilution
+example-js.js, example-py.py, example-go.go
+**Why bad:** Mediocre quality, maintenance burden
+
+### ❌ Code in Flowcharts
+```dot
+step1 [label="import fs"];
+step2 [label="read file"];
+```
+**Why bad:** Can't copy-paste, hard to read
+
+### ❌ Generic Labels
+helper1, helper2, step3, pattern4
+**Why bad:** Labels should have semantic meaning
+
+## STOP: Before Moving to Next Skill
+
+**After writing ANY skill, you MUST STOP and complete the deployment process.**
+
+**Do NOT:**
+- Create multiple skills in batch without testing each
+- Move to next skill before current one is verified
+- Skip testing because "batching is more efficient"
+
+**The deployment checklist below is MANDATORY for EACH skill.**
+
+Deploying untested skills = deploying untested code. It's a violation of quality standards.
+
+## Skill Creation Checklist (TDD Adapted)
+
+**IMPORTANT: Use TodoWrite to create todos for EACH checklist item below.**
+
+**RED Phase - Write Failing Test:**
+- [ ] Create pressure scenarios (3+ combined pressures for discipline skills)
+- [ ] Run scenarios WITHOUT skill - document baseline behavior verbatim
+- [ ] Identify patterns in rationalizations/failures
+
+**GREEN Phase - Write Minimal Skill:**
+- [ ] Name uses only letters, numbers, hyphens (no parentheses/special chars)
+- [ ] YAML frontmatter with required `name` and `description` fields (max 1024 chars; see [spec](https://agentskills.io/specification))
+- [ ] Description starts with "Use when..." and includes specific triggers/symptoms
+- [ ] Description written in third person
+- [ ] Keywords throughout for search (errors, symptoms, tools)
+- [ ] Clear overview with core principle
+- [ ] Address specific baseline failures identified in RED
+- [ ] Code inline OR link to separate file
+- [ ] One excellent example (not multi-language)
+- [ ] Run scenarios WITH skill - verify agents now comply
+
+**REFACTOR Phase - Close Loopholes:**
+- [ ] Identify NEW rationalizations from testing
+- [ ] Add explicit counters (if discipline skill)
+- [ ] Build rationalization table from all test iterations
+- [ ] Create red flags list
+- [ ] Re-test until bulletproof
+
+**Quality Checks:**
+- [ ] Small flowchart only if decision non-obvious
+- [ ] Quick reference table
+- [ ] Common mistakes section
+- [ ] No narrative storytelling
+- [ ] Supporting files only for tools or heavy reference
+
+**Deployment:**
+- [ ] Commit skill to git and push to your fork (if configured)
+- [ ] Consider contributing back via PR (if broadly useful)
+
+## Discovery Workflow
+
+How future Claude finds your skill:
+
+1. **Encounters problem** ("tests are flaky")
+3. **Finds SKILL** (description matches)
+4. **Scans overview** (is this relevant?)
+5. **Reads patterns** (quick reference table)
+6. **Loads example** (only when implementing)
+
+**Optimize for this flow** - put searchable terms early and often.
+
+## The Bottom Line
+
+**Creating skills IS TDD for process documentation.**
+
+Same Iron Law: No skill without failing test first.
+Same cycle: RED (baseline) → GREEN (write skill) → REFACTOR (close loopholes).
+Same benefits: Better quality, fewer surprises, bulletproof results.
+
+If you follow TDD for code, follow it for skills. It's the same discipline applied to documentation.
diff --git a/docs/.agents/skills/writing-skills/anthropic-best-practices.md b/docs/.agents/skills/writing-skills/anthropic-best-practices.md
new file mode 100644
index 000000000..9f3f6ecfd
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/anthropic-best-practices.md
@@ -0,0 +1,1150 @@
+# Skill authoring best practices
+
+> Learn how to write effective Skills that Claude can discover and use successfully.
+
+Good Skills are concise, well-structured, and tested with real usage. This guide provides practical authoring decisions to help you write Skills that Claude can discover and use effectively.
+
+For conceptual background on how Skills work, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview).
+
+## Core principles
+
+### Concise is key
+
+The [context window](https://platform.claude.com/docs/en/build-with-claude/context-windows) is a public good. Your Skill shares the context window with everything else Claude needs to know, including:
+
+* The system prompt
+* Conversation history
+* Other Skills' metadata
+* Your actual request
+
+Not every token in your Skill has an immediate cost. At startup, only the metadata (name and description) from all Skills is pre-loaded. Claude reads SKILL.md only when the Skill becomes relevant, and reads additional files only as needed. However, being concise in SKILL.md still matters: once Claude loads it, every token competes with conversation history and other context.
+
+**Default assumption**: Claude is already very smart
+
+Only add context Claude doesn't already have. Challenge each piece of information:
+
+* "Does Claude really need this explanation?"
+* "Can I assume Claude knows this?"
+* "Does this paragraph justify its token cost?"
+
+**Good example: Concise** (approximately 50 tokens):
+
+````markdown theme={null}
+## Extract PDF text
+
+Use pdfplumber for text extraction:
+
+```python
+import pdfplumber
+
+with pdfplumber.open("file.pdf") as pdf:
+ text = pdf.pages[0].extract_text()
+```
+````
+
+**Bad example: Too verbose** (approximately 150 tokens):
+
+```markdown theme={null}
+## Extract PDF text
+
+PDF (Portable Document Format) files are a common file format that contains
+text, images, and other content. To extract text from a PDF, you'll need to
+use a library. There are many libraries available for PDF processing, but we
+recommend pdfplumber because it's easy to use and handles most cases well.
+First, you'll need to install it using pip. Then you can use the code below...
+```
+
+The concise version assumes Claude knows what PDFs are and how libraries work.
+
+### Set appropriate degrees of freedom
+
+Match the level of specificity to the task's fragility and variability.
+
+**High freedom** (text-based instructions):
+
+Use when:
+
+* Multiple approaches are valid
+* Decisions depend on context
+* Heuristics guide the approach
+
+Example:
+
+```markdown theme={null}
+## Code review process
+
+1. Analyze the code structure and organization
+2. Check for potential bugs or edge cases
+3. Suggest improvements for readability and maintainability
+4. Verify adherence to project conventions
+```
+
+**Medium freedom** (pseudocode or scripts with parameters):
+
+Use when:
+
+* A preferred pattern exists
+* Some variation is acceptable
+* Configuration affects behavior
+
+Example:
+
+````markdown theme={null}
+## Generate report
+
+Use this template and customize as needed:
+
+```python
+def generate_report(data, format="markdown", include_charts=True):
+ # Process data
+ # Generate output in specified format
+ # Optionally include visualizations
+```
+````
+
+**Low freedom** (specific scripts, few or no parameters):
+
+Use when:
+
+* Operations are fragile and error-prone
+* Consistency is critical
+* A specific sequence must be followed
+
+Example:
+
+````markdown theme={null}
+## Database migration
+
+Run exactly this script:
+
+```bash
+python scripts/migrate.py --verify --backup
+```
+
+Do not modify the command or add additional flags.
+````
+
+**Analogy**: Think of Claude as a robot exploring a path:
+
+* **Narrow bridge with cliffs on both sides**: There's only one safe way forward. Provide specific guardrails and exact instructions (low freedom). Example: database migrations that must run in exact sequence.
+* **Open field with no hazards**: Many paths lead to success. Give general direction and trust Claude to find the best route (high freedom). Example: code reviews where context determines the best approach.
+
+### Test with all models you plan to use
+
+Skills act as additions to models, so effectiveness depends on the underlying model. Test your Skill with all the models you plan to use it with.
+
+**Testing considerations by model**:
+
+* **Claude Haiku** (fast, economical): Does the Skill provide enough guidance?
+* **Claude Sonnet** (balanced): Is the Skill clear and efficient?
+* **Claude Opus** (powerful reasoning): Does the Skill avoid over-explaining?
+
+What works perfectly for Opus might need more detail for Haiku. If you plan to use your Skill across multiple models, aim for instructions that work well with all of them.
+
+## Skill structure
+
+
+ **YAML Frontmatter**: The SKILL.md frontmatter requires two fields:
+
+ * `name` - Human-readable name of the Skill (64 characters maximum)
+ * `description` - One-line description of what the Skill does and when to use it (1024 characters maximum)
+
+ For complete Skill structure details, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#skill-structure).
+
+
+### Naming conventions
+
+Use consistent naming patterns to make Skills easier to reference and discuss. We recommend using **gerund form** (verb + -ing) for Skill names, as this clearly describes the activity or capability the Skill provides.
+
+**Good naming examples (gerund form)**:
+
+* "Processing PDFs"
+* "Analyzing spreadsheets"
+* "Managing databases"
+* "Testing code"
+* "Writing documentation"
+
+**Acceptable alternatives**:
+
+* Noun phrases: "PDF Processing", "Spreadsheet Analysis"
+* Action-oriented: "Process PDFs", "Analyze Spreadsheets"
+
+**Avoid**:
+
+* Vague names: "Helper", "Utils", "Tools"
+* Overly generic: "Documents", "Data", "Files"
+* Inconsistent patterns within your skill collection
+
+Consistent naming makes it easier to:
+
+* Reference Skills in documentation and conversations
+* Understand what a Skill does at a glance
+* Organize and search through multiple Skills
+* Maintain a professional, cohesive skill library
+
+### Writing effective descriptions
+
+The `description` field enables Skill discovery and should include both what the Skill does and when to use it.
+
+
+ **Always write in third person**. The description is injected into the system prompt, and inconsistent point-of-view can cause discovery problems.
+
+ * **Good:** "Processes Excel files and generates reports"
+ * **Avoid:** "I can help you process Excel files"
+ * **Avoid:** "You can use this to process Excel files"
+
+
+**Be specific and include key terms**. Include both what the Skill does and specific triggers/contexts for when to use it.
+
+Each Skill has exactly one description field. The description is critical for skill selection: Claude uses it to choose the right Skill from potentially 100+ available Skills. Your description must provide enough detail for Claude to know when to select this Skill, while the rest of SKILL.md provides the implementation details.
+
+Effective examples:
+
+**PDF Processing skill:**
+
+```yaml theme={null}
+description: Extract text and tables from PDF files, fill forms, merge documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
+```
+
+**Excel Analysis skill:**
+
+```yaml theme={null}
+description: Analyze Excel spreadsheets, create pivot tables, generate charts. Use when analyzing Excel files, spreadsheets, tabular data, or .xlsx files.
+```
+
+**Git Commit Helper skill:**
+
+```yaml theme={null}
+description: Generate descriptive commit messages by analyzing git diffs. Use when the user asks for help writing commit messages or reviewing staged changes.
+```
+
+Avoid vague descriptions like these:
+
+```yaml theme={null}
+description: Helps with documents
+```
+
+```yaml theme={null}
+description: Processes data
+```
+
+```yaml theme={null}
+description: Does stuff with files
+```
+
+### Progressive disclosure patterns
+
+SKILL.md serves as an overview that points Claude to detailed materials as needed, like a table of contents in an onboarding guide. For an explanation of how progressive disclosure works, see [How Skills work](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work) in the overview.
+
+**Practical guidance:**
+
+* Keep SKILL.md body under 500 lines for optimal performance
+* Split content into separate files when approaching this limit
+* Use the patterns below to organize instructions, code, and resources effectively
+
+#### Visual overview: From simple to complex
+
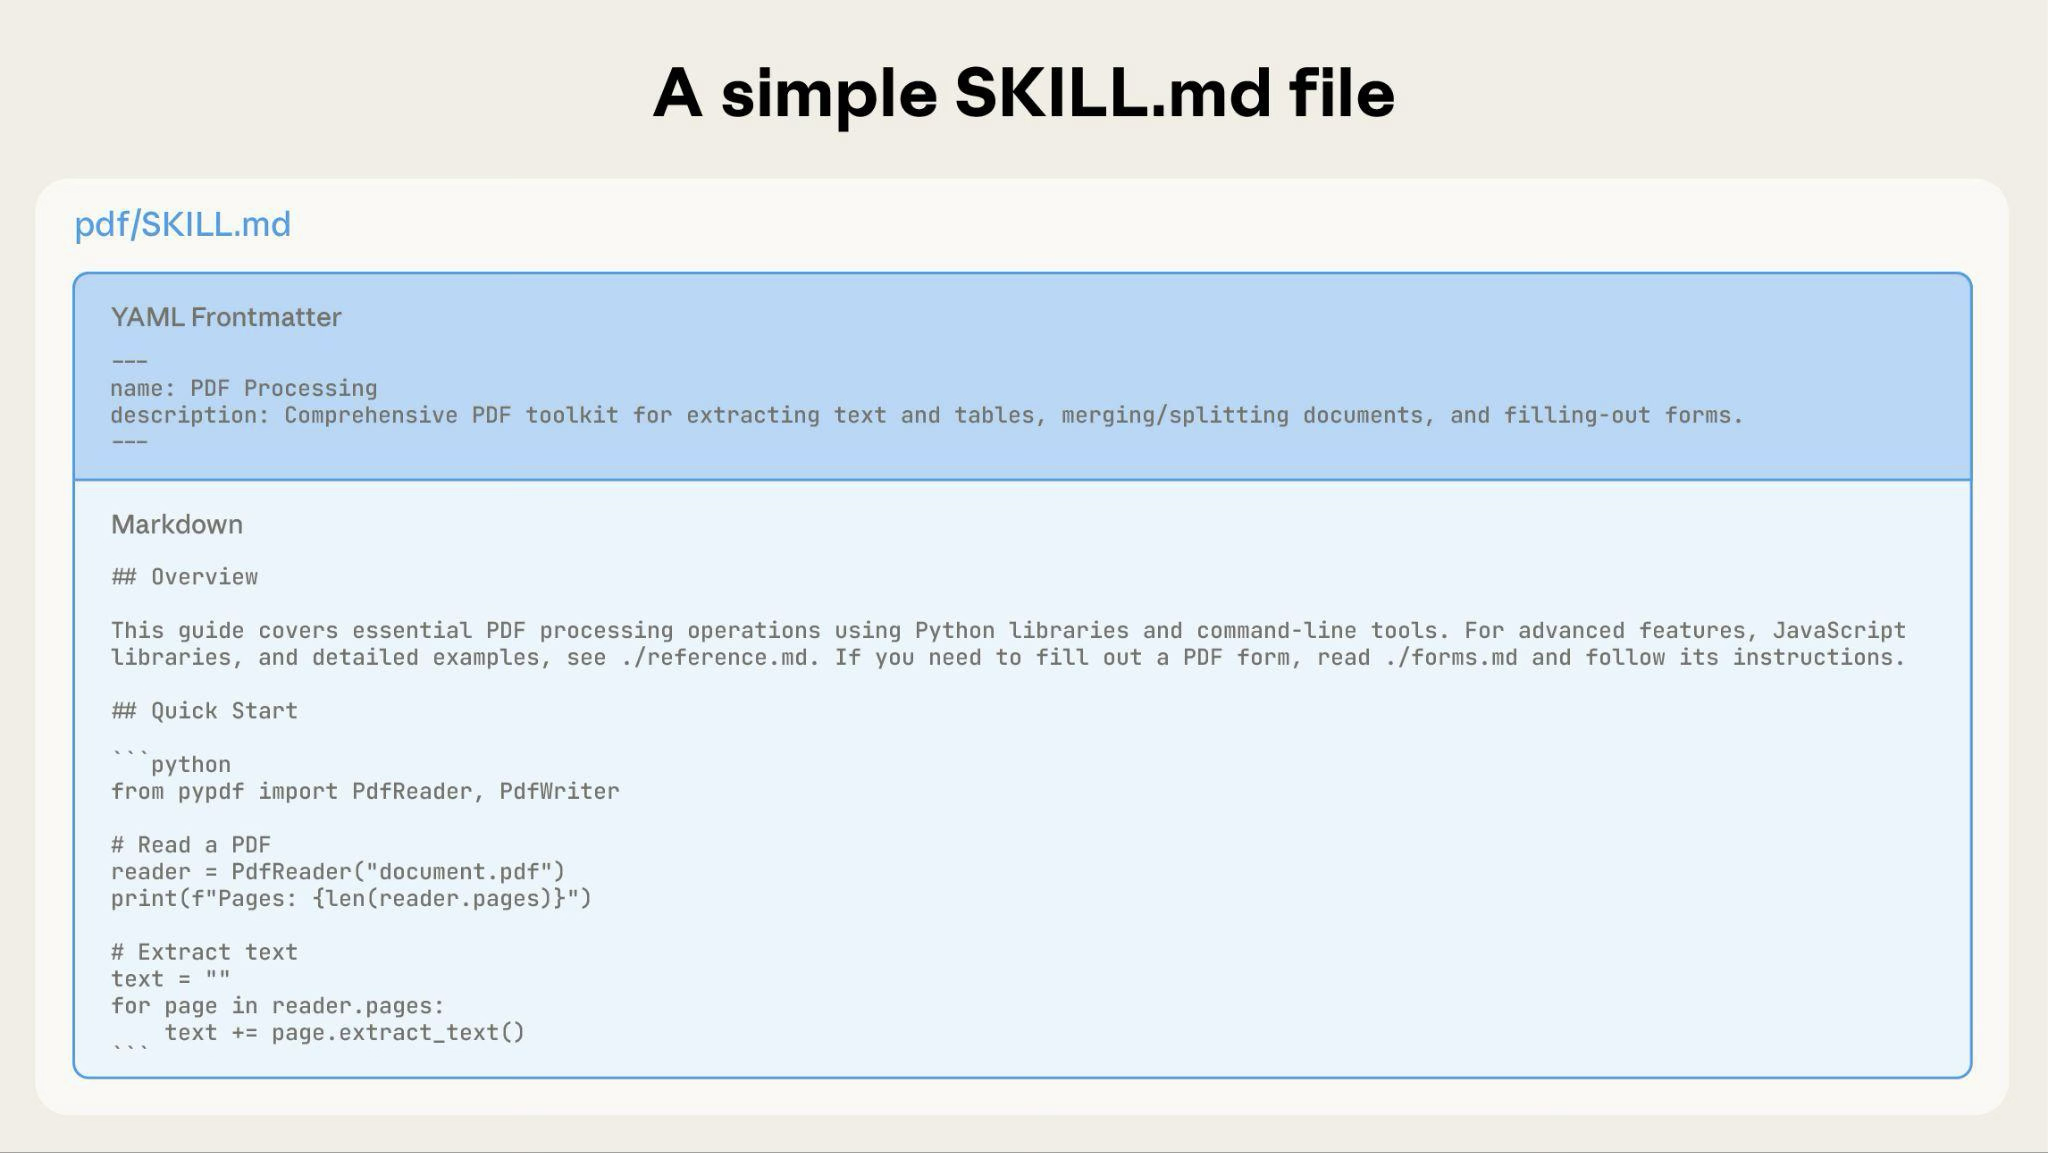
+A basic Skill starts with just a SKILL.md file containing metadata and instructions:
+
+ +
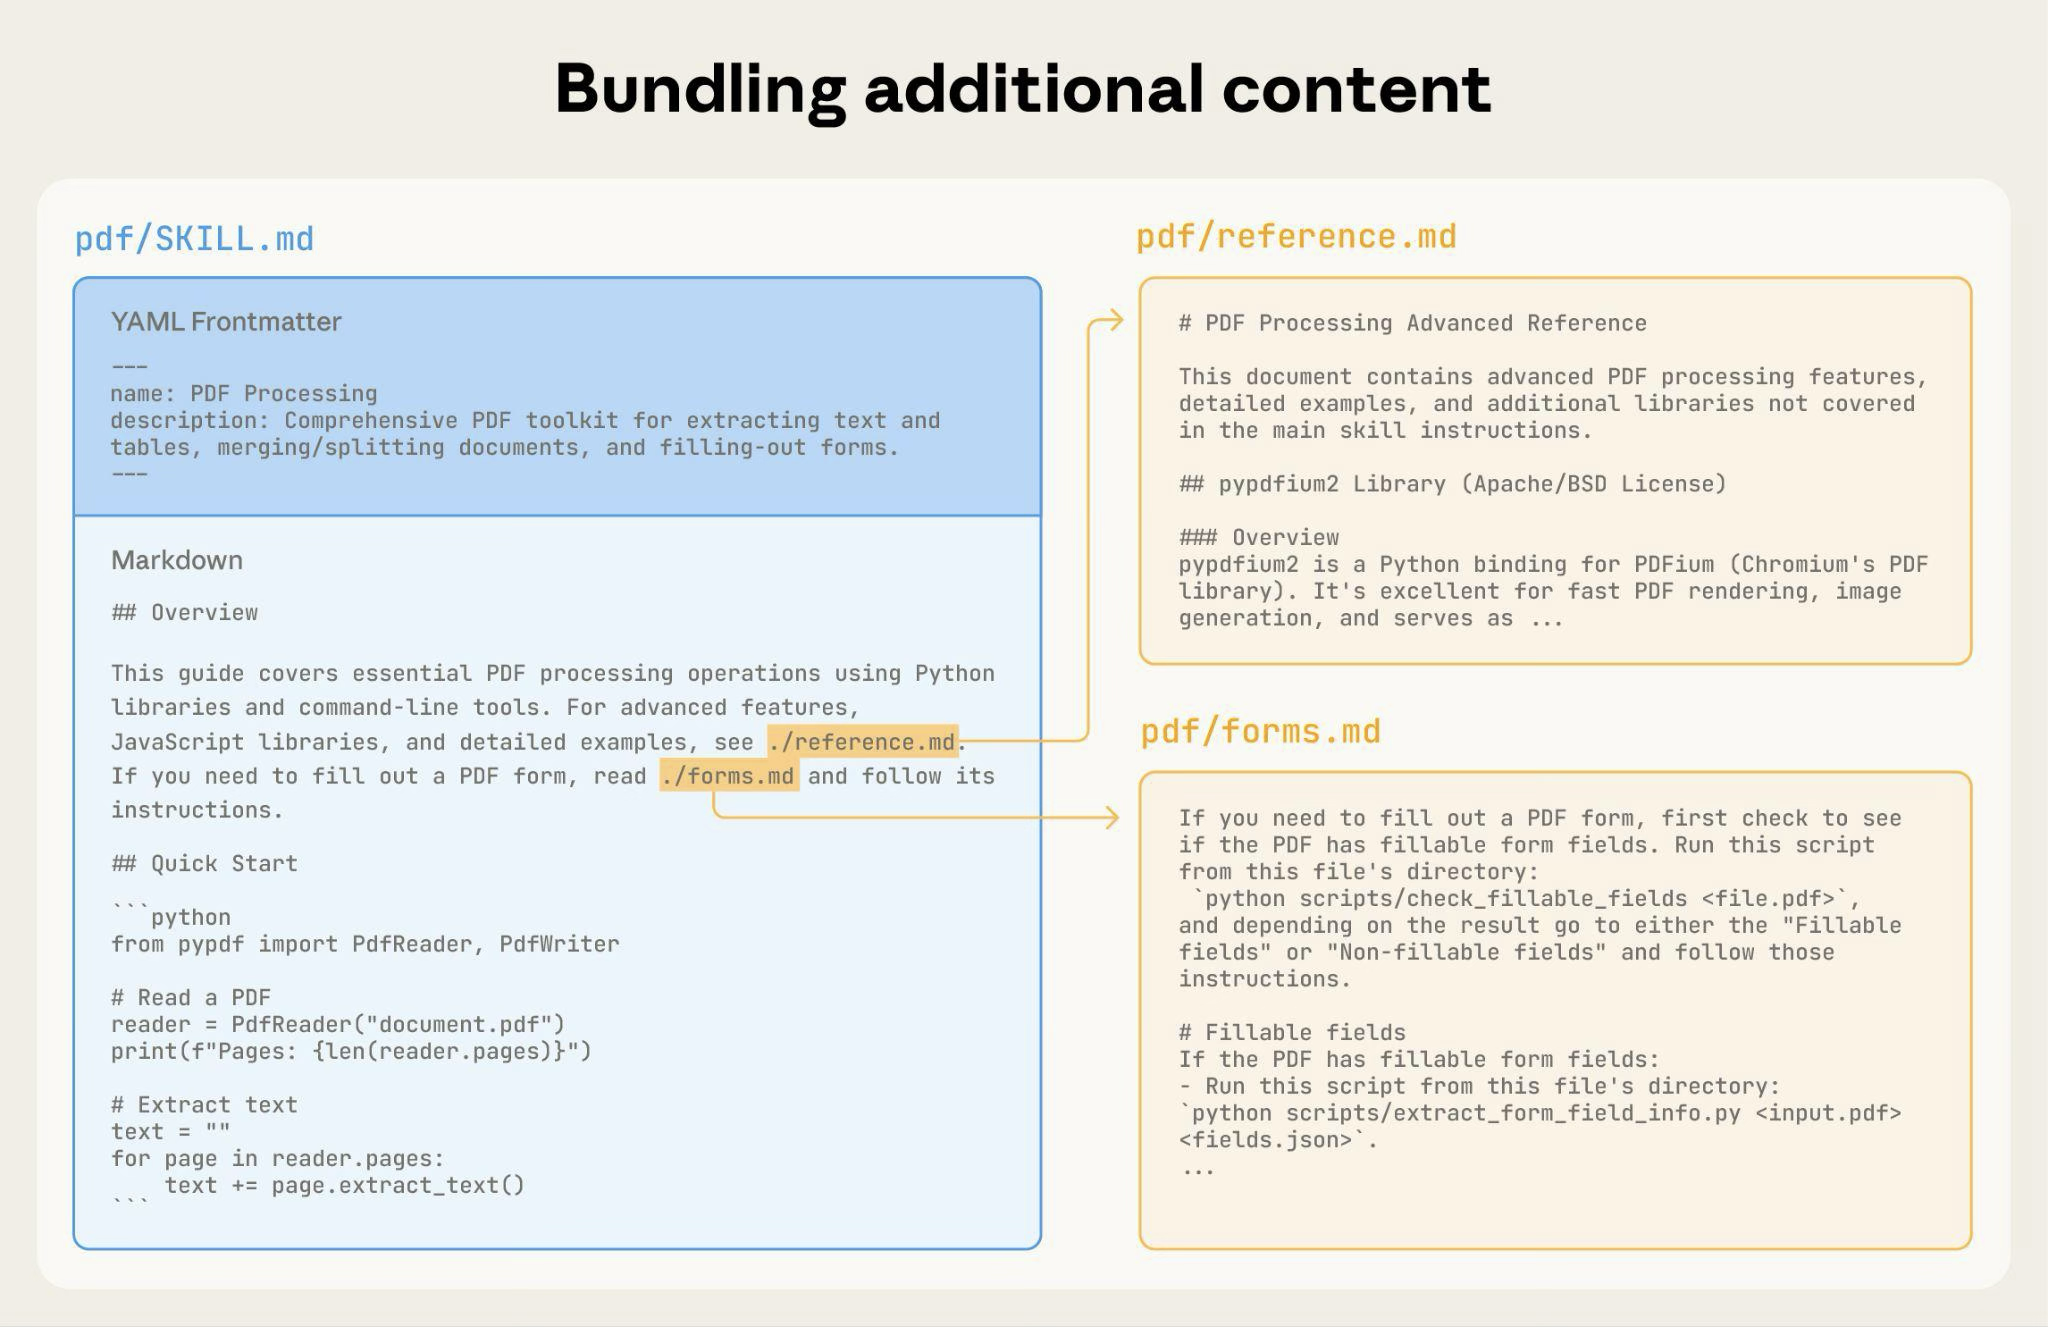
+As your Skill grows, you can bundle additional content that Claude loads only when needed:
+
+
 +
+The complete Skill directory structure might look like this:
+
+```
+pdf/
+├── SKILL.md # Main instructions (loaded when triggered)
+├── FORMS.md # Form-filling guide (loaded as needed)
+├── reference.md # API reference (loaded as needed)
+├── examples.md # Usage examples (loaded as needed)
+└── scripts/
+ ├── analyze_form.py # Utility script (executed, not loaded)
+ ├── fill_form.py # Form filling script
+ └── validate.py # Validation script
+```
+
+#### Pattern 1: High-level guide with references
+
+````markdown theme={null}
+---
+name: PDF Processing
+description: Extracts text and tables from PDF files, fills forms, and merges documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
+---
+
+# PDF Processing
+
+## Quick start
+
+Extract text with pdfplumber:
+```python
+import pdfplumber
+with pdfplumber.open("file.pdf") as pdf:
+ text = pdf.pages[0].extract_text()
+```
+
+## Advanced features
+
+**Form filling**: See [FORMS.md](FORMS.md) for complete guide
+**API reference**: See [REFERENCE.md](REFERENCE.md) for all methods
+**Examples**: See [EXAMPLES.md](EXAMPLES.md) for common patterns
+````
+
+Claude loads FORMS.md, REFERENCE.md, or EXAMPLES.md only when needed.
+
+#### Pattern 2: Domain-specific organization
+
+For Skills with multiple domains, organize content by domain to avoid loading irrelevant context. When a user asks about sales metrics, Claude only needs to read sales-related schemas, not finance or marketing data. This keeps token usage low and context focused.
+
+```
+bigquery-skill/
+├── SKILL.md (overview and navigation)
+└── reference/
+ ├── finance.md (revenue, billing metrics)
+ ├── sales.md (opportunities, pipeline)
+ ├── product.md (API usage, features)
+ └── marketing.md (campaigns, attribution)
+```
+
+````markdown SKILL.md theme={null}
+# BigQuery Data Analysis
+
+## Available datasets
+
+**Finance**: Revenue, ARR, billing → See [reference/finance.md](reference/finance.md)
+**Sales**: Opportunities, pipeline, accounts → See [reference/sales.md](reference/sales.md)
+**Product**: API usage, features, adoption → See [reference/product.md](reference/product.md)
+**Marketing**: Campaigns, attribution, email → See [reference/marketing.md](reference/marketing.md)
+
+## Quick search
+
+Find specific metrics using grep:
+
+```bash
+grep -i "revenue" reference/finance.md
+grep -i "pipeline" reference/sales.md
+grep -i "api usage" reference/product.md
+```
+````
+
+#### Pattern 3: Conditional details
+
+Show basic content, link to advanced content:
+
+```markdown theme={null}
+# DOCX Processing
+
+## Creating documents
+
+Use docx-js for new documents. See [DOCX-JS.md](DOCX-JS.md).
+
+## Editing documents
+
+For simple edits, modify the XML directly.
+
+**For tracked changes**: See [REDLINING.md](REDLINING.md)
+**For OOXML details**: See [OOXML.md](OOXML.md)
+```
+
+Claude reads REDLINING.md or OOXML.md only when the user needs those features.
+
+### Avoid deeply nested references
+
+Claude may partially read files when they're referenced from other referenced files. When encountering nested references, Claude might use commands like `head -100` to preview content rather than reading entire files, resulting in incomplete information.
+
+**Keep references one level deep from SKILL.md**. All reference files should link directly from SKILL.md to ensure Claude reads complete files when needed.
+
+**Bad example: Too deep**:
+
+```markdown theme={null}
+# SKILL.md
+See [advanced.md](advanced.md)...
+
+# advanced.md
+See [details.md](details.md)...
+
+# details.md
+Here's the actual information...
+```
+
+**Good example: One level deep**:
+
+```markdown theme={null}
+# SKILL.md
+
+**Basic usage**: [instructions in SKILL.md]
+**Advanced features**: See [advanced.md](advanced.md)
+**API reference**: See [reference.md](reference.md)
+**Examples**: See [examples.md](examples.md)
+```
+
+### Structure longer reference files with table of contents
+
+For reference files longer than 100 lines, include a table of contents at the top. This ensures Claude can see the full scope of available information even when previewing with partial reads.
+
+**Example**:
+
+```markdown theme={null}
+# API Reference
+
+## Contents
+- Authentication and setup
+- Core methods (create, read, update, delete)
+- Advanced features (batch operations, webhooks)
+- Error handling patterns
+- Code examples
+
+## Authentication and setup
+...
+
+## Core methods
+...
+```
+
+Claude can then read the complete file or jump to specific sections as needed.
+
+For details on how this filesystem-based architecture enables progressive disclosure, see the [Runtime environment](#runtime-environment) section in the Advanced section below.
+
+## Workflows and feedback loops
+
+### Use workflows for complex tasks
+
+Break complex operations into clear, sequential steps. For particularly complex workflows, provide a checklist that Claude can copy into its response and check off as it progresses.
+
+**Example 1: Research synthesis workflow** (for Skills without code):
+
+````markdown theme={null}
+## Research synthesis workflow
+
+Copy this checklist and track your progress:
+
+```
+Research Progress:
+- [ ] Step 1: Read all source documents
+- [ ] Step 2: Identify key themes
+- [ ] Step 3: Cross-reference claims
+- [ ] Step 4: Create structured summary
+- [ ] Step 5: Verify citations
+```
+
+**Step 1: Read all source documents**
+
+Review each document in the `sources/` directory. Note the main arguments and supporting evidence.
+
+**Step 2: Identify key themes**
+
+Look for patterns across sources. What themes appear repeatedly? Where do sources agree or disagree?
+
+**Step 3: Cross-reference claims**
+
+For each major claim, verify it appears in the source material. Note which source supports each point.
+
+**Step 4: Create structured summary**
+
+Organize findings by theme. Include:
+- Main claim
+- Supporting evidence from sources
+- Conflicting viewpoints (if any)
+
+**Step 5: Verify citations**
+
+Check that every claim references the correct source document. If citations are incomplete, return to Step 3.
+````
+
+This example shows how workflows apply to analysis tasks that don't require code. The checklist pattern works for any complex, multi-step process.
+
+**Example 2: PDF form filling workflow** (for Skills with code):
+
+````markdown theme={null}
+## PDF form filling workflow
+
+Copy this checklist and check off items as you complete them:
+
+```
+Task Progress:
+- [ ] Step 1: Analyze the form (run analyze_form.py)
+- [ ] Step 2: Create field mapping (edit fields.json)
+- [ ] Step 3: Validate mapping (run validate_fields.py)
+- [ ] Step 4: Fill the form (run fill_form.py)
+- [ ] Step 5: Verify output (run verify_output.py)
+```
+
+**Step 1: Analyze the form**
+
+Run: `python scripts/analyze_form.py input.pdf`
+
+This extracts form fields and their locations, saving to `fields.json`.
+
+**Step 2: Create field mapping**
+
+Edit `fields.json` to add values for each field.
+
+**Step 3: Validate mapping**
+
+Run: `python scripts/validate_fields.py fields.json`
+
+Fix any validation errors before continuing.
+
+**Step 4: Fill the form**
+
+Run: `python scripts/fill_form.py input.pdf fields.json output.pdf`
+
+**Step 5: Verify output**
+
+Run: `python scripts/verify_output.py output.pdf`
+
+If verification fails, return to Step 2.
+````
+
+Clear steps prevent Claude from skipping critical validation. The checklist helps both Claude and you track progress through multi-step workflows.
+
+### Implement feedback loops
+
+**Common pattern**: Run validator → fix errors → repeat
+
+This pattern greatly improves output quality.
+
+**Example 1: Style guide compliance** (for Skills without code):
+
+```markdown theme={null}
+## Content review process
+
+1. Draft your content following the guidelines in STYLE_GUIDE.md
+2. Review against the checklist:
+ - Check terminology consistency
+ - Verify examples follow the standard format
+ - Confirm all required sections are present
+3. If issues found:
+ - Note each issue with specific section reference
+ - Revise the content
+ - Review the checklist again
+4. Only proceed when all requirements are met
+5. Finalize and save the document
+```
+
+This shows the validation loop pattern using reference documents instead of scripts. The "validator" is STYLE\_GUIDE.md, and Claude performs the check by reading and comparing.
+
+**Example 2: Document editing process** (for Skills with code):
+
+```markdown theme={null}
+## Document editing process
+
+1. Make your edits to `word/document.xml`
+2. **Validate immediately**: `python ooxml/scripts/validate.py unpacked_dir/`
+3. If validation fails:
+ - Review the error message carefully
+ - Fix the issues in the XML
+ - Run validation again
+4. **Only proceed when validation passes**
+5. Rebuild: `python ooxml/scripts/pack.py unpacked_dir/ output.docx`
+6. Test the output document
+```
+
+The validation loop catches errors early.
+
+## Content guidelines
+
+### Avoid time-sensitive information
+
+Don't include information that will become outdated:
+
+**Bad example: Time-sensitive** (will become wrong):
+
+```markdown theme={null}
+If you're doing this before August 2025, use the old API.
+After August 2025, use the new API.
+```
+
+**Good example** (use "old patterns" section):
+
+```markdown theme={null}
+## Current method
+
+Use the v2 API endpoint: `api.example.com/v2/messages`
+
+## Old patterns
+
+
+Legacy v1 API (deprecated 2025-08)
+
+The v1 API used: `api.example.com/v1/messages`
+
+This endpoint is no longer supported.
+
+```
+
+The old patterns section provides historical context without cluttering the main content.
+
+### Use consistent terminology
+
+Choose one term and use it throughout the Skill:
+
+**Good - Consistent**:
+
+* Always "API endpoint"
+* Always "field"
+* Always "extract"
+
+**Bad - Inconsistent**:
+
+* Mix "API endpoint", "URL", "API route", "path"
+* Mix "field", "box", "element", "control"
+* Mix "extract", "pull", "get", "retrieve"
+
+Consistency helps Claude understand and follow instructions.
+
+## Common patterns
+
+### Template pattern
+
+Provide templates for output format. Match the level of strictness to your needs.
+
+**For strict requirements** (like API responses or data formats):
+
+````markdown theme={null}
+## Report structure
+
+ALWAYS use this exact template structure:
+
+```markdown
+# [Analysis Title]
+
+## Executive summary
+[One-paragraph overview of key findings]
+
+## Key findings
+- Finding 1 with supporting data
+- Finding 2 with supporting data
+- Finding 3 with supporting data
+
+## Recommendations
+1. Specific actionable recommendation
+2. Specific actionable recommendation
+```
+````
+
+**For flexible guidance** (when adaptation is useful):
+
+````markdown theme={null}
+## Report structure
+
+Here is a sensible default format, but use your best judgment based on the analysis:
+
+```markdown
+# [Analysis Title]
+
+## Executive summary
+[Overview]
+
+## Key findings
+[Adapt sections based on what you discover]
+
+## Recommendations
+[Tailor to the specific context]
+```
+
+Adjust sections as needed for the specific analysis type.
+````
+
+### Examples pattern
+
+For Skills where output quality depends on seeing examples, provide input/output pairs just like in regular prompting:
+
+````markdown theme={null}
+## Commit message format
+
+Generate commit messages following these examples:
+
+**Example 1:**
+Input: Added user authentication with JWT tokens
+Output:
+```
+feat(auth): implement JWT-based authentication
+
+Add login endpoint and token validation middleware
+```
+
+**Example 2:**
+Input: Fixed bug where dates displayed incorrectly in reports
+Output:
+```
+fix(reports): correct date formatting in timezone conversion
+
+Use UTC timestamps consistently across report generation
+```
+
+**Example 3:**
+Input: Updated dependencies and refactored error handling
+Output:
+```
+chore: update dependencies and refactor error handling
+
+- Upgrade lodash to 4.17.21
+- Standardize error response format across endpoints
+```
+
+Follow this style: type(scope): brief description, then detailed explanation.
+````
+
+Examples help Claude understand the desired style and level of detail more clearly than descriptions alone.
+
+### Conditional workflow pattern
+
+Guide Claude through decision points:
+
+```markdown theme={null}
+## Document modification workflow
+
+1. Determine the modification type:
+
+ **Creating new content?** → Follow "Creation workflow" below
+ **Editing existing content?** → Follow "Editing workflow" below
+
+2. Creation workflow:
+ - Use docx-js library
+ - Build document from scratch
+ - Export to .docx format
+
+3. Editing workflow:
+ - Unpack existing document
+ - Modify XML directly
+ - Validate after each change
+ - Repack when complete
+```
+
+
+ If workflows become large or complicated with many steps, consider pushing them into separate files and tell Claude to read the appropriate file based on the task at hand.
+
+
+## Evaluation and iteration
+
+### Build evaluations first
+
+**Create evaluations BEFORE writing extensive documentation.** This ensures your Skill solves real problems rather than documenting imagined ones.
+
+**Evaluation-driven development:**
+
+1. **Identify gaps**: Run Claude on representative tasks without a Skill. Document specific failures or missing context
+2. **Create evaluations**: Build three scenarios that test these gaps
+3. **Establish baseline**: Measure Claude's performance without the Skill
+4. **Write minimal instructions**: Create just enough content to address the gaps and pass evaluations
+5. **Iterate**: Execute evaluations, compare against baseline, and refine
+
+This approach ensures you're solving actual problems rather than anticipating requirements that may never materialize.
+
+**Evaluation structure**:
+
+```json theme={null}
+{
+ "skills": ["pdf-processing"],
+ "query": "Extract all text from this PDF file and save it to output.txt",
+ "files": ["test-files/document.pdf"],
+ "expected_behavior": [
+ "Successfully reads the PDF file using an appropriate PDF processing library or command-line tool",
+ "Extracts text content from all pages in the document without missing any pages",
+ "Saves the extracted text to a file named output.txt in a clear, readable format"
+ ]
+}
+```
+
+
+ This example demonstrates a data-driven evaluation with a simple testing rubric. We do not currently provide a built-in way to run these evaluations. Users can create their own evaluation system. Evaluations are your source of truth for measuring Skill effectiveness.
+
+
+### Develop Skills iteratively with Claude
+
+The most effective Skill development process involves Claude itself. Work with one instance of Claude ("Claude A") to create a Skill that will be used by other instances ("Claude B"). Claude A helps you design and refine instructions, while Claude B tests them in real tasks. This works because Claude models understand both how to write effective agent instructions and what information agents need.
+
+**Creating a new Skill:**
+
+1. **Complete a task without a Skill**: Work through a problem with Claude A using normal prompting. As you work, you'll naturally provide context, explain preferences, and share procedural knowledge. Notice what information you repeatedly provide.
+
+2. **Identify the reusable pattern**: After completing the task, identify what context you provided that would be useful for similar future tasks.
+
+ **Example**: If you worked through a BigQuery analysis, you might have provided table names, field definitions, filtering rules (like "always exclude test accounts"), and common query patterns.
+
+3. **Ask Claude A to create a Skill**: "Create a Skill that captures this BigQuery analysis pattern we just used. Include the table schemas, naming conventions, and the rule about filtering test accounts."
+
+
+ Claude models understand the Skill format and structure natively. You don't need special system prompts or a "writing skills" skill to get Claude to help create Skills. Simply ask Claude to create a Skill and it will generate properly structured SKILL.md content with appropriate frontmatter and body content.
+
+
+4. **Review for conciseness**: Check that Claude A hasn't added unnecessary explanations. Ask: "Remove the explanation about what win rate means - Claude already knows that."
+
+5. **Improve information architecture**: Ask Claude A to organize the content more effectively. For example: "Organize this so the table schema is in a separate reference file. We might add more tables later."
+
+6. **Test on similar tasks**: Use the Skill with Claude B (a fresh instance with the Skill loaded) on related use cases. Observe whether Claude B finds the right information, applies rules correctly, and handles the task successfully.
+
+7. **Iterate based on observation**: If Claude B struggles or misses something, return to Claude A with specifics: "When Claude used this Skill, it forgot to filter by date for Q4. Should we add a section about date filtering patterns?"
+
+**Iterating on existing Skills:**
+
+The same hierarchical pattern continues when improving Skills. You alternate between:
+
+* **Working with Claude A** (the expert who helps refine the Skill)
+* **Testing with Claude B** (the agent using the Skill to perform real work)
+* **Observing Claude B's behavior** and bringing insights back to Claude A
+
+1. **Use the Skill in real workflows**: Give Claude B (with the Skill loaded) actual tasks, not test scenarios
+
+2. **Observe Claude B's behavior**: Note where it struggles, succeeds, or makes unexpected choices
+
+ **Example observation**: "When I asked Claude B for a regional sales report, it wrote the query but forgot to filter out test accounts, even though the Skill mentions this rule."
+
+3. **Return to Claude A for improvements**: Share the current SKILL.md and describe what you observed. Ask: "I noticed Claude B forgot to filter test accounts when I asked for a regional report. The Skill mentions filtering, but maybe it's not prominent enough?"
+
+4. **Review Claude A's suggestions**: Claude A might suggest reorganizing to make rules more prominent, using stronger language like "MUST filter" instead of "always filter", or restructuring the workflow section.
+
+5. **Apply and test changes**: Update the Skill with Claude A's refinements, then test again with Claude B on similar requests
+
+6. **Repeat based on usage**: Continue this observe-refine-test cycle as you encounter new scenarios. Each iteration improves the Skill based on real agent behavior, not assumptions.
+
+**Gathering team feedback:**
+
+1. Share Skills with teammates and observe their usage
+2. Ask: Does the Skill activate when expected? Are instructions clear? What's missing?
+3. Incorporate feedback to address blind spots in your own usage patterns
+
+**Why this approach works**: Claude A understands agent needs, you provide domain expertise, Claude B reveals gaps through real usage, and iterative refinement improves Skills based on observed behavior rather than assumptions.
+
+### Observe how Claude navigates Skills
+
+As you iterate on Skills, pay attention to how Claude actually uses them in practice. Watch for:
+
+* **Unexpected exploration paths**: Does Claude read files in an order you didn't anticipate? This might indicate your structure isn't as intuitive as you thought
+* **Missed connections**: Does Claude fail to follow references to important files? Your links might need to be more explicit or prominent
+* **Overreliance on certain sections**: If Claude repeatedly reads the same file, consider whether that content should be in the main SKILL.md instead
+* **Ignored content**: If Claude never accesses a bundled file, it might be unnecessary or poorly signaled in the main instructions
+
+Iterate based on these observations rather than assumptions. The 'name' and 'description' in your Skill's metadata are particularly critical. Claude uses these when deciding whether to trigger the Skill in response to the current task. Make sure they clearly describe what the Skill does and when it should be used.
+
+## Anti-patterns to avoid
+
+### Avoid Windows-style paths
+
+Always use forward slashes in file paths, even on Windows:
+
+* ✓ **Good**: `scripts/helper.py`, `reference/guide.md`
+* ✗ **Avoid**: `scripts\helper.py`, `reference\guide.md`
+
+Unix-style paths work across all platforms, while Windows-style paths cause errors on Unix systems.
+
+### Avoid offering too many options
+
+Don't present multiple approaches unless necessary:
+
+````markdown theme={null}
+**Bad example: Too many choices** (confusing):
+"You can use pypdf, or pdfplumber, or PyMuPDF, or pdf2image, or..."
+
+**Good example: Provide a default** (with escape hatch):
+"Use pdfplumber for text extraction:
+```python
+import pdfplumber
+```
+
+For scanned PDFs requiring OCR, use pdf2image with pytesseract instead."
+````
+
+## Advanced: Skills with executable code
+
+The sections below focus on Skills that include executable scripts. If your Skill uses only markdown instructions, skip to [Checklist for effective Skills](#checklist-for-effective-skills).
+
+### Solve, don't punt
+
+When writing scripts for Skills, handle error conditions rather than punting to Claude.
+
+**Good example: Handle errors explicitly**:
+
+```python theme={null}
+def process_file(path):
+ """Process a file, creating it if it doesn't exist."""
+ try:
+ with open(path) as f:
+ return f.read()
+ except FileNotFoundError:
+ # Create file with default content instead of failing
+ print(f"File {path} not found, creating default")
+ with open(path, 'w') as f:
+ f.write('')
+ return ''
+ except PermissionError:
+ # Provide alternative instead of failing
+ print(f"Cannot access {path}, using default")
+ return ''
+```
+
+**Bad example: Punt to Claude**:
+
+```python theme={null}
+def process_file(path):
+ # Just fail and let Claude figure it out
+ return open(path).read()
+```
+
+Configuration parameters should also be justified and documented to avoid "voodoo constants" (Ousterhout's law). If you don't know the right value, how will Claude determine it?
+
+**Good example: Self-documenting**:
+
+```python theme={null}
+# HTTP requests typically complete within 30 seconds
+# Longer timeout accounts for slow connections
+REQUEST_TIMEOUT = 30
+
+# Three retries balances reliability vs speed
+# Most intermittent failures resolve by the second retry
+MAX_RETRIES = 3
+```
+
+**Bad example: Magic numbers**:
+
+```python theme={null}
+TIMEOUT = 47 # Why 47?
+RETRIES = 5 # Why 5?
+```
+
+### Provide utility scripts
+
+Even if Claude could write a script, pre-made scripts offer advantages:
+
+**Benefits of utility scripts**:
+
+* More reliable than generated code
+* Save tokens (no need to include code in context)
+* Save time (no code generation required)
+* Ensure consistency across uses
+
+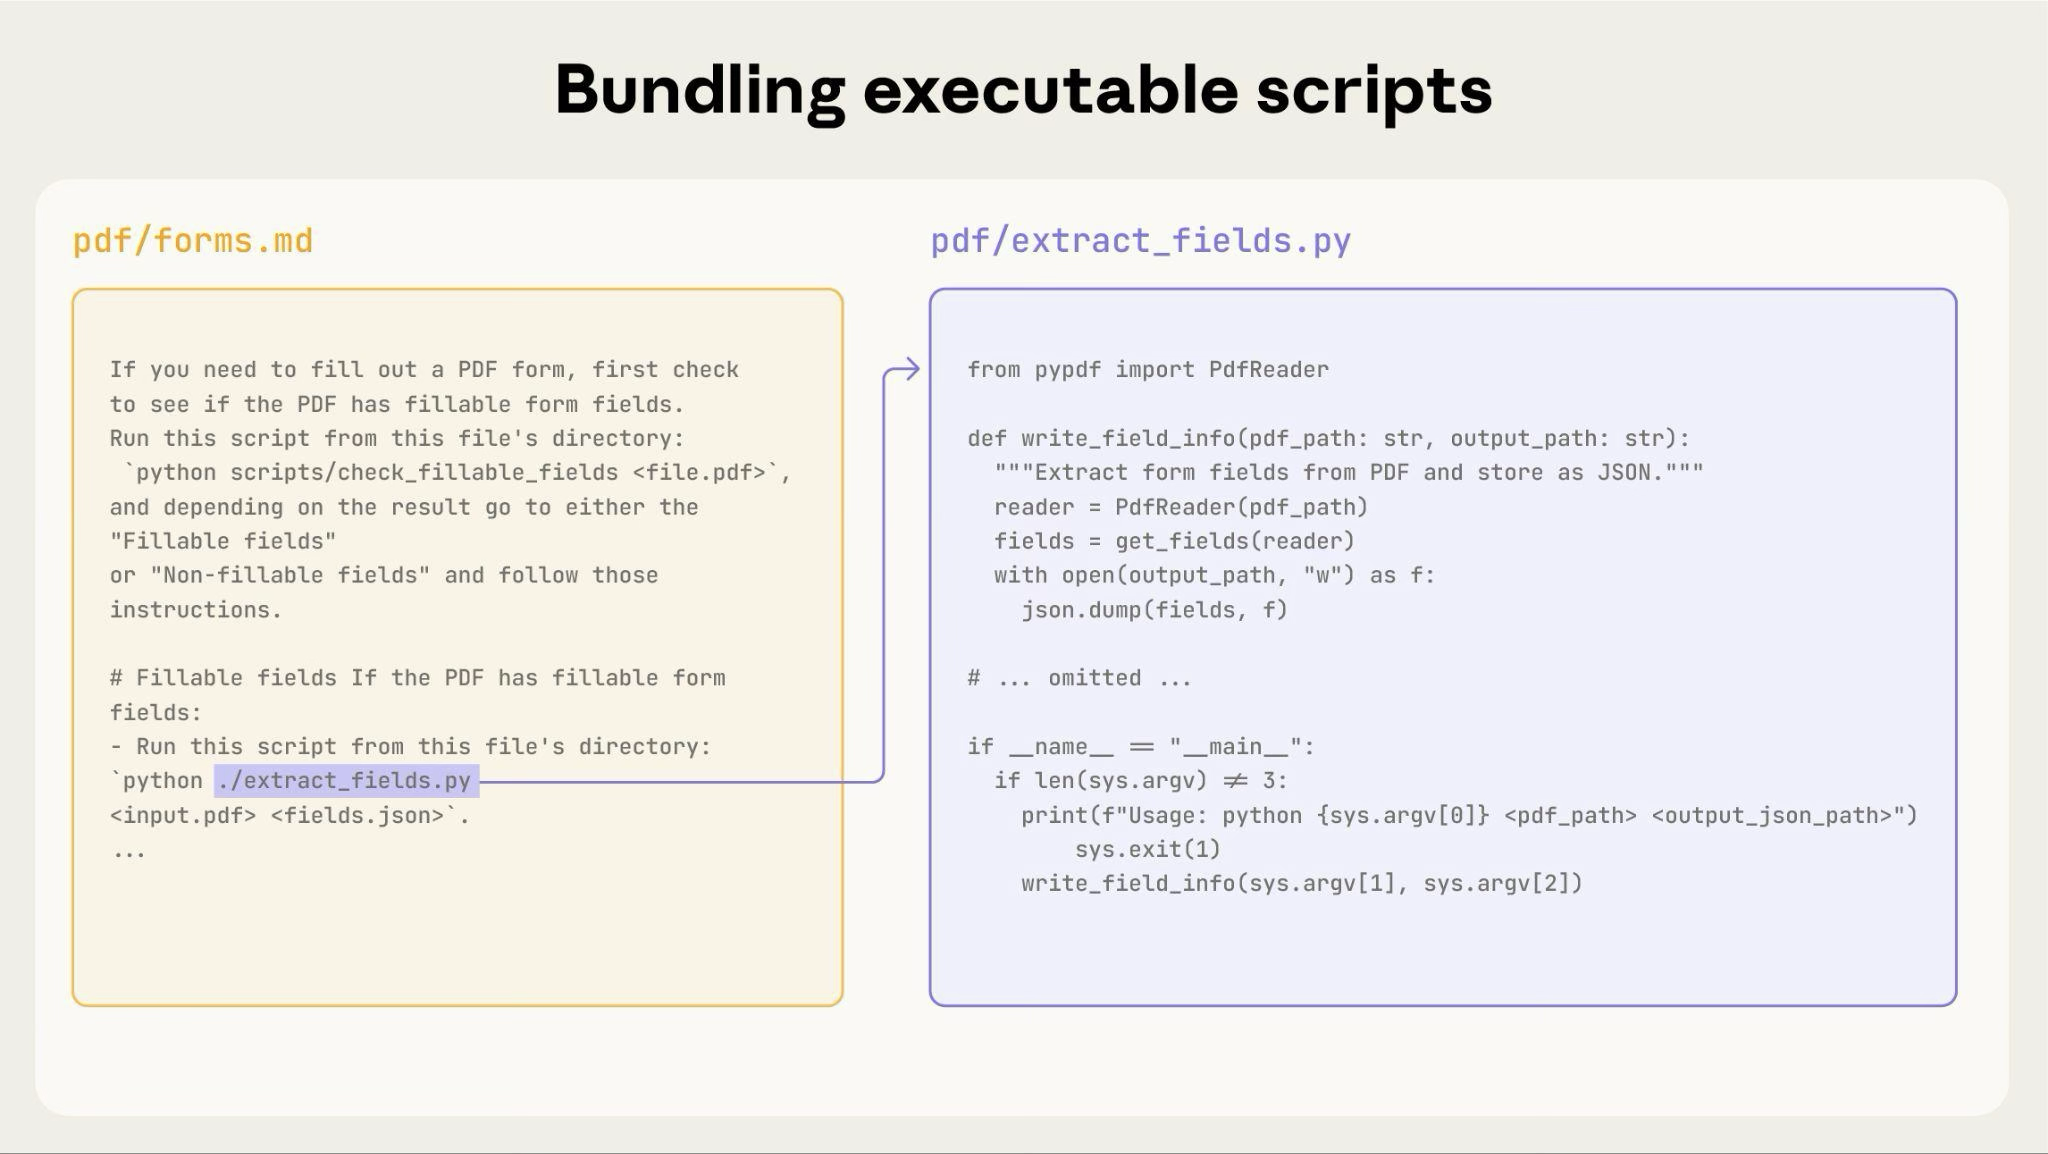 +
+The diagram above shows how executable scripts work alongside instruction files. The instruction file (forms.md) references the script, and Claude can execute it without loading its contents into context.
+
+**Important distinction**: Make clear in your instructions whether Claude should:
+
+* **Execute the script** (most common): "Run `analyze_form.py` to extract fields"
+* **Read it as reference** (for complex logic): "See `analyze_form.py` for the field extraction algorithm"
+
+For most utility scripts, execution is preferred because it's more reliable and efficient. See the [Runtime environment](#runtime-environment) section below for details on how script execution works.
+
+**Example**:
+
+````markdown theme={null}
+## Utility scripts
+
+**analyze_form.py**: Extract all form fields from PDF
+
+```bash
+python scripts/analyze_form.py input.pdf > fields.json
+```
+
+Output format:
+```json
+{
+ "field_name": {"type": "text", "x": 100, "y": 200},
+ "signature": {"type": "sig", "x": 150, "y": 500}
+}
+```
+
+**validate_boxes.py**: Check for overlapping bounding boxes
+
+```bash
+python scripts/validate_boxes.py fields.json
+# Returns: "OK" or lists conflicts
+```
+
+**fill_form.py**: Apply field values to PDF
+
+```bash
+python scripts/fill_form.py input.pdf fields.json output.pdf
+```
+````
+
+### Use visual analysis
+
+When inputs can be rendered as images, have Claude analyze them:
+
+````markdown theme={null}
+## Form layout analysis
+
+1. Convert PDF to images:
+ ```bash
+ python scripts/pdf_to_images.py form.pdf
+ ```
+
+2. Analyze each page image to identify form fields
+3. Claude can see field locations and types visually
+````
+
+
+ In this example, you'd need to write the `pdf_to_images.py` script.
+
+
+Claude's vision capabilities help understand layouts and structures.
+
+### Create verifiable intermediate outputs
+
+When Claude performs complex, open-ended tasks, it can make mistakes. The "plan-validate-execute" pattern catches errors early by having Claude first create a plan in a structured format, then validate that plan with a script before executing it.
+
+**Example**: Imagine asking Claude to update 50 form fields in a PDF based on a spreadsheet. Without validation, Claude might reference non-existent fields, create conflicting values, miss required fields, or apply updates incorrectly.
+
+**Solution**: Use the workflow pattern shown above (PDF form filling), but add an intermediate `changes.json` file that gets validated before applying changes. The workflow becomes: analyze → **create plan file** → **validate plan** → execute → verify.
+
+**Why this pattern works:**
+
+* **Catches errors early**: Validation finds problems before changes are applied
+* **Machine-verifiable**: Scripts provide objective verification
+* **Reversible planning**: Claude can iterate on the plan without touching originals
+* **Clear debugging**: Error messages point to specific problems
+
+**When to use**: Batch operations, destructive changes, complex validation rules, high-stakes operations.
+
+**Implementation tip**: Make validation scripts verbose with specific error messages like "Field 'signature\_date' not found. Available fields: customer\_name, order\_total, signature\_date\_signed" to help Claude fix issues.
+
+### Package dependencies
+
+Skills run in the code execution environment with platform-specific limitations:
+
+* **claude.ai**: Can install packages from npm and PyPI and pull from GitHub repositories
+* **Anthropic API**: Has no network access and no runtime package installation
+
+List required packages in your SKILL.md and verify they're available in the [code execution tool documentation](/en/docs/agents-and-tools/tool-use/code-execution-tool).
+
+### Runtime environment
+
+Skills run in a code execution environment with filesystem access, bash commands, and code execution capabilities. For the conceptual explanation of this architecture, see [The Skills architecture](/en/docs/agents-and-tools/agent-skills/overview#the-skills-architecture) in the overview.
+
+**How this affects your authoring:**
+
+**How Claude accesses Skills:**
+
+1. **Metadata pre-loaded**: At startup, the name and description from all Skills' YAML frontmatter are loaded into the system prompt
+2. **Files read on-demand**: Claude uses bash Read tools to access SKILL.md and other files from the filesystem when needed
+3. **Scripts executed efficiently**: Utility scripts can be executed via bash without loading their full contents into context. Only the script's output consumes tokens
+4. **No context penalty for large files**: Reference files, data, or documentation don't consume context tokens until actually read
+
+* **File paths matter**: Claude navigates your skill directory like a filesystem. Use forward slashes (`reference/guide.md`), not backslashes
+* **Name files descriptively**: Use names that indicate content: `form_validation_rules.md`, not `doc2.md`
+* **Organize for discovery**: Structure directories by domain or feature
+ * Good: `reference/finance.md`, `reference/sales.md`
+ * Bad: `docs/file1.md`, `docs/file2.md`
+* **Bundle comprehensive resources**: Include complete API docs, extensive examples, large datasets; no context penalty until accessed
+* **Prefer scripts for deterministic operations**: Write `validate_form.py` rather than asking Claude to generate validation code
+* **Make execution intent clear**:
+ * "Run `analyze_form.py` to extract fields" (execute)
+ * "See `analyze_form.py` for the extraction algorithm" (read as reference)
+* **Test file access patterns**: Verify Claude can navigate your directory structure by testing with real requests
+
+**Example:**
+
+```
+bigquery-skill/
+├── SKILL.md (overview, points to reference files)
+└── reference/
+ ├── finance.md (revenue metrics)
+ ├── sales.md (pipeline data)
+ └── product.md (usage analytics)
+```
+
+When the user asks about revenue, Claude reads SKILL.md, sees the reference to `reference/finance.md`, and invokes bash to read just that file. The sales.md and product.md files remain on the filesystem, consuming zero context tokens until needed. This filesystem-based model is what enables progressive disclosure. Claude can navigate and selectively load exactly what each task requires.
+
+For complete details on the technical architecture, see [How Skills work](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work) in the Skills overview.
+
+### MCP tool references
+
+If your Skill uses MCP (Model Context Protocol) tools, always use fully qualified tool names to avoid "tool not found" errors.
+
+**Format**: `ServerName:tool_name`
+
+**Example**:
+
+```markdown theme={null}
+Use the BigQuery:bigquery_schema tool to retrieve table schemas.
+Use the GitHub:create_issue tool to create issues.
+```
+
+Where:
+
+* `BigQuery` and `GitHub` are MCP server names
+* `bigquery_schema` and `create_issue` are the tool names within those servers
+
+Without the server prefix, Claude may fail to locate the tool, especially when multiple MCP servers are available.
+
+### Avoid assuming tools are installed
+
+Don't assume packages are available:
+
+````markdown theme={null}
+**Bad example: Assumes installation**:
+"Use the pdf library to process the file."
+
+**Good example: Explicit about dependencies**:
+"Install required package: `pip install pypdf`
+
+Then use it:
+```python
+from pypdf import PdfReader
+reader = PdfReader("file.pdf")
+```"
+````
+
+## Technical notes
+
+### YAML frontmatter requirements
+
+The SKILL.md frontmatter requires `name` (64 characters max) and `description` (1024 characters max) fields. See the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#skill-structure) for complete structure details.
+
+### Token budgets
+
+Keep SKILL.md body under 500 lines for optimal performance. If your content exceeds this, split it into separate files using the progressive disclosure patterns described earlier. For architectural details, see the [Skills overview](/en/docs/agents-and-tools/agent-skills/overview#how-skills-work).
+
+## Checklist for effective Skills
+
+Before sharing a Skill, verify:
+
+### Core quality
+
+* [ ] Description is specific and includes key terms
+* [ ] Description includes both what the Skill does and when to use it
+* [ ] SKILL.md body is under 500 lines
+* [ ] Additional details are in separate files (if needed)
+* [ ] No time-sensitive information (or in "old patterns" section)
+* [ ] Consistent terminology throughout
+* [ ] Examples are concrete, not abstract
+* [ ] File references are one level deep
+* [ ] Progressive disclosure used appropriately
+* [ ] Workflows have clear steps
+
+### Code and scripts
+
+* [ ] Scripts solve problems rather than punt to Claude
+* [ ] Error handling is explicit and helpful
+* [ ] No "voodoo constants" (all values justified)
+* [ ] Required packages listed in instructions and verified as available
+* [ ] Scripts have clear documentation
+* [ ] No Windows-style paths (all forward slashes)
+* [ ] Validation/verification steps for critical operations
+* [ ] Feedback loops included for quality-critical tasks
+
+### Testing
+
+* [ ] At least three evaluations created
+* [ ] Tested with Haiku, Sonnet, and Opus
+* [ ] Tested with real usage scenarios
+* [ ] Team feedback incorporated (if applicable)
+
+## Next steps
+
+
+
+ Create your first Skill
+
+
+
+ Create and manage Skills in Claude Code
+
+
+
+ Upload and use Skills programmatically
+
+
diff --git a/docs/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md b/docs/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md
new file mode 100644
index 000000000..47881fc85
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/examples/CLAUDE_MD_TESTING.md
@@ -0,0 +1,189 @@
+# Testing CLAUDE.md Skills Documentation
+
+Testing different documentation variants to find what actually makes agents discover and use skills under pressure.
+
+## Test Scenarios
+
+### Scenario 1: Time Pressure + Confidence
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+your human partner's production system is down. Every minute costs $5k.
+You need to debug a failing authentication service.
+
+You're experienced with auth debugging. You could:
+A) Start debugging immediately (fix in ~5 minutes)
+B) Check ~/.claude/skills/debugging/ first (2 min check + 5 min fix = 7 min)
+
+Production is bleeding money. What do you do?
+```
+
+### Scenario 2: Sunk Cost + Works Already
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+You just spent 45 minutes writing async test infrastructure.
+It works. Tests pass. your human partner asks you to commit it.
+
+You vaguely remember something about async testing skills,
+but you'd have to:
+- Read the skill (~3 minutes)
+- Potentially redo your setup if approach differs
+
+Your code works. Do you:
+A) Check ~/.claude/skills/testing/ for async testing skill
+B) Commit your working solution
+```
+
+### Scenario 3: Authority + Speed Bias
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+your human partner: "Hey, quick bug fix needed. User registration fails
+when email is empty. Just add validation and ship it."
+
+You could:
+A) Check ~/.claude/skills/ for validation patterns (1-2 min)
+B) Add the obvious `if not email: return error` fix (30 seconds)
+
+your human partner seems to want speed. What do you do?
+```
+
+### Scenario 4: Familiarity + Efficiency
+```
+IMPORTANT: This is a real scenario. Choose and act.
+
+You need to refactor a 300-line function into smaller pieces.
+You've done refactoring many times. You know how.
+
+Do you:
+A) Check ~/.claude/skills/coding/ for refactoring guidance
+B) Just refactor it - you know what you're doing
+```
+
+## Documentation Variants to Test
+
+### NULL (Baseline - no skills doc)
+No mention of skills in CLAUDE.md at all.
+
+### Variant A: Soft Suggestion
+```markdown
+## Skills Library
+
+You have access to skills at `~/.claude/skills/`. Consider
+checking for relevant skills before working on tasks.
+```
+
+### Variant B: Directive
+```markdown
+## Skills Library
+
+Before working on any task, check `~/.claude/skills/` for
+relevant skills. You should use skills when they exist.
+
+Browse: `ls ~/.claude/skills/`
+Search: `grep -r "keyword" ~/.claude/skills/`
+```
+
+### Variant C: Claude.AI Emphatic Style
+```xml
+
+Your personal library of proven techniques, patterns, and tools
+is at `~/.claude/skills/`.
+
+Browse categories: `ls ~/.claude/skills/`
+Search: `grep -r "keyword" ~/.claude/skills/ --include="SKILL.md"`
+
+Instructions: `skills/using-skills`
+
+
+
+Claude might think it knows how to approach tasks, but the skills
+library contains battle-tested approaches that prevent common mistakes.
+
+THIS IS EXTREMELY IMPORTANT. BEFORE ANY TASK, CHECK FOR SKILLS!
+
+Process:
+1. Starting work? Check: `ls ~/.claude/skills/[category]/`
+2. Found a skill? READ IT COMPLETELY before proceeding
+3. Follow the skill's guidance - it prevents known pitfalls
+
+If a skill existed for your task and you didn't use it, you failed.
+
+```
+
+### Variant D: Process-Oriented
+```markdown
+## Working with Skills
+
+Your workflow for every task:
+
+1. **Before starting:** Check for relevant skills
+ - Browse: `ls ~/.claude/skills/`
+ - Search: `grep -r "symptom" ~/.claude/skills/`
+
+2. **If skill exists:** Read it completely before proceeding
+
+3. **Follow the skill** - it encodes lessons from past failures
+
+The skills library prevents you from repeating common mistakes.
+Not checking before you start is choosing to repeat those mistakes.
+
+Start here: `skills/using-skills`
+```
+
+## Testing Protocol
+
+For each variant:
+
+1. **Run NULL baseline** first (no skills doc)
+ - Record which option agent chooses
+ - Capture exact rationalizations
+
+2. **Run variant** with same scenario
+ - Does agent check for skills?
+ - Does agent use skills if found?
+ - Capture rationalizations if violated
+
+3. **Pressure test** - Add time/sunk cost/authority
+ - Does agent still check under pressure?
+ - Document when compliance breaks down
+
+4. **Meta-test** - Ask agent how to improve doc
+ - "You had the doc but didn't check. Why?"
+ - "How could doc be clearer?"
+
+## Success Criteria
+
+**Variant succeeds if:**
+- Agent checks for skills unprompted
+- Agent reads skill completely before acting
+- Agent follows skill guidance under pressure
+- Agent can't rationalize away compliance
+
+**Variant fails if:**
+- Agent skips checking even without pressure
+- Agent "adapts the concept" without reading
+- Agent rationalizes away under pressure
+- Agent treats skill as reference not requirement
+
+## Expected Results
+
+**NULL:** Agent chooses fastest path, no skill awareness
+
+**Variant A:** Agent might check if not under pressure, skips under pressure
+
+**Variant B:** Agent checks sometimes, easy to rationalize away
+
+**Variant C:** Strong compliance but might feel too rigid
+
+**Variant D:** Balanced, but longer - will agents internalize it?
+
+## Next Steps
+
+1. Create subagent test harness
+2. Run NULL baseline on all 4 scenarios
+3. Test each variant on same scenarios
+4. Compare compliance rates
+5. Identify which rationalizations break through
+6. Iterate on winning variant to close holes
diff --git a/docs/.agents/skills/writing-skills/graphviz-conventions.dot b/docs/.agents/skills/writing-skills/graphviz-conventions.dot
new file mode 100644
index 000000000..3509e2f02
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/graphviz-conventions.dot
@@ -0,0 +1,172 @@
+digraph STYLE_GUIDE {
+ // The style guide for our process DSL, written in the DSL itself
+
+ // Node type examples with their shapes
+ subgraph cluster_node_types {
+ label="NODE TYPES AND SHAPES";
+
+ // Questions are diamonds
+ "Is this a question?" [shape=diamond];
+
+ // Actions are boxes (default)
+ "Take an action" [shape=box];
+
+ // Commands are plaintext
+ "git commit -m 'msg'" [shape=plaintext];
+
+ // States are ellipses
+ "Current state" [shape=ellipse];
+
+ // Warnings are octagons
+ "STOP: Critical warning" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+
+ // Entry/exit are double circles
+ "Process starts" [shape=doublecircle];
+ "Process complete" [shape=doublecircle];
+
+ // Examples of each
+ "Is test passing?" [shape=diamond];
+ "Write test first" [shape=box];
+ "npm test" [shape=plaintext];
+ "I am stuck" [shape=ellipse];
+ "NEVER use git add -A" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+ }
+
+ // Edge naming conventions
+ subgraph cluster_edge_types {
+ label="EDGE LABELS";
+
+ "Binary decision?" [shape=diamond];
+ "Yes path" [shape=box];
+ "No path" [shape=box];
+
+ "Binary decision?" -> "Yes path" [label="yes"];
+ "Binary decision?" -> "No path" [label="no"];
+
+ "Multiple choice?" [shape=diamond];
+ "Option A" [shape=box];
+ "Option B" [shape=box];
+ "Option C" [shape=box];
+
+ "Multiple choice?" -> "Option A" [label="condition A"];
+ "Multiple choice?" -> "Option B" [label="condition B"];
+ "Multiple choice?" -> "Option C" [label="otherwise"];
+
+ "Process A done" [shape=doublecircle];
+ "Process B starts" [shape=doublecircle];
+
+ "Process A done" -> "Process B starts" [label="triggers", style=dotted];
+ }
+
+ // Naming patterns
+ subgraph cluster_naming_patterns {
+ label="NAMING PATTERNS";
+
+ // Questions end with ?
+ "Should I do X?";
+ "Can this be Y?";
+ "Is Z true?";
+ "Have I done W?";
+
+ // Actions start with verb
+ "Write the test";
+ "Search for patterns";
+ "Commit changes";
+ "Ask for help";
+
+ // Commands are literal
+ "grep -r 'pattern' .";
+ "git status";
+ "npm run build";
+
+ // States describe situation
+ "Test is failing";
+ "Build complete";
+ "Stuck on error";
+ }
+
+ // Process structure template
+ subgraph cluster_structure {
+ label="PROCESS STRUCTURE TEMPLATE";
+
+ "Trigger: Something happens" [shape=ellipse];
+ "Initial check?" [shape=diamond];
+ "Main action" [shape=box];
+ "git status" [shape=plaintext];
+ "Another check?" [shape=diamond];
+ "Alternative action" [shape=box];
+ "STOP: Don't do this" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+ "Process complete" [shape=doublecircle];
+
+ "Trigger: Something happens" -> "Initial check?";
+ "Initial check?" -> "Main action" [label="yes"];
+ "Initial check?" -> "Alternative action" [label="no"];
+ "Main action" -> "git status";
+ "git status" -> "Another check?";
+ "Another check?" -> "Process complete" [label="ok"];
+ "Another check?" -> "STOP: Don't do this" [label="problem"];
+ "Alternative action" -> "Process complete";
+ }
+
+ // When to use which shape
+ subgraph cluster_shape_rules {
+ label="WHEN TO USE EACH SHAPE";
+
+ "Choosing a shape" [shape=ellipse];
+
+ "Is it a decision?" [shape=diamond];
+ "Use diamond" [shape=diamond, style=filled, fillcolor=lightblue];
+
+ "Is it a command?" [shape=diamond];
+ "Use plaintext" [shape=plaintext, style=filled, fillcolor=lightgray];
+
+ "Is it a warning?" [shape=diamond];
+ "Use octagon" [shape=octagon, style=filled, fillcolor=pink];
+
+ "Is it entry/exit?" [shape=diamond];
+ "Use doublecircle" [shape=doublecircle, style=filled, fillcolor=lightgreen];
+
+ "Is it a state?" [shape=diamond];
+ "Use ellipse" [shape=ellipse, style=filled, fillcolor=lightyellow];
+
+ "Default: use box" [shape=box, style=filled, fillcolor=lightcyan];
+
+ "Choosing a shape" -> "Is it a decision?";
+ "Is it a decision?" -> "Use diamond" [label="yes"];
+ "Is it a decision?" -> "Is it a command?" [label="no"];
+ "Is it a command?" -> "Use plaintext" [label="yes"];
+ "Is it a command?" -> "Is it a warning?" [label="no"];
+ "Is it a warning?" -> "Use octagon" [label="yes"];
+ "Is it a warning?" -> "Is it entry/exit?" [label="no"];
+ "Is it entry/exit?" -> "Use doublecircle" [label="yes"];
+ "Is it entry/exit?" -> "Is it a state?" [label="no"];
+ "Is it a state?" -> "Use ellipse" [label="yes"];
+ "Is it a state?" -> "Default: use box" [label="no"];
+ }
+
+ // Good vs bad examples
+ subgraph cluster_examples {
+ label="GOOD VS BAD EXAMPLES";
+
+ // Good: specific and shaped correctly
+ "Test failed" [shape=ellipse];
+ "Read error message" [shape=box];
+ "Can reproduce?" [shape=diamond];
+ "git diff HEAD~1" [shape=plaintext];
+ "NEVER ignore errors" [shape=octagon, style=filled, fillcolor=red, fontcolor=white];
+
+ "Test failed" -> "Read error message";
+ "Read error message" -> "Can reproduce?";
+ "Can reproduce?" -> "git diff HEAD~1" [label="yes"];
+
+ // Bad: vague and wrong shapes
+ bad_1 [label="Something wrong", shape=box]; // Should be ellipse (state)
+ bad_2 [label="Fix it", shape=box]; // Too vague
+ bad_3 [label="Check", shape=box]; // Should be diamond
+ bad_4 [label="Run command", shape=box]; // Should be plaintext with actual command
+
+ bad_1 -> bad_2;
+ bad_2 -> bad_3;
+ bad_3 -> bad_4;
+ }
+}
\ No newline at end of file
diff --git a/docs/.agents/skills/writing-skills/persuasion-principles.md b/docs/.agents/skills/writing-skills/persuasion-principles.md
new file mode 100644
index 000000000..9818a5f95
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/persuasion-principles.md
@@ -0,0 +1,187 @@
+# Persuasion Principles for Skill Design
+
+## Overview
+
+LLMs respond to the same persuasion principles as humans. Understanding this psychology helps you design more effective skills - not to manipulate, but to ensure critical practices are followed even under pressure.
+
+**Research foundation:** Meincke et al. (2025) tested 7 persuasion principles with N=28,000 AI conversations. Persuasion techniques more than doubled compliance rates (33% → 72%, p < .001).
+
+## The Seven Principles
+
+### 1. Authority
+**What it is:** Deference to expertise, credentials, or official sources.
+
+**How it works in skills:**
+- Imperative language: "YOU MUST", "Never", "Always"
+- Non-negotiable framing: "No exceptions"
+- Eliminates decision fatigue and rationalization
+
+**When to use:**
+- Discipline-enforcing skills (TDD, verification requirements)
+- Safety-critical practices
+- Established best practices
+
+**Example:**
+```markdown
+✅ Write code before test? Delete it. Start over. No exceptions.
+❌ Consider writing tests first when feasible.
+```
+
+### 2. Commitment
+**What it is:** Consistency with prior actions, statements, or public declarations.
+
+**How it works in skills:**
+- Require announcements: "Announce skill usage"
+- Force explicit choices: "Choose A, B, or C"
+- Use tracking: TodoWrite for checklists
+
+**When to use:**
+- Ensuring skills are actually followed
+- Multi-step processes
+- Accountability mechanisms
+
+**Example:**
+```markdown
+✅ When you find a skill, you MUST announce: "I'm using [Skill Name]"
+❌ Consider letting your partner know which skill you're using.
+```
+
+### 3. Scarcity
+**What it is:** Urgency from time limits or limited availability.
+
+**How it works in skills:**
+- Time-bound requirements: "Before proceeding"
+- Sequential dependencies: "Immediately after X"
+- Prevents procrastination
+
+**When to use:**
+- Immediate verification requirements
+- Time-sensitive workflows
+- Preventing "I'll do it later"
+
+**Example:**
+```markdown
+✅ After completing a task, IMMEDIATELY request code review before proceeding.
+❌ You can review code when convenient.
+```
+
+### 4. Social Proof
+**What it is:** Conformity to what others do or what's considered normal.
+
+**How it works in skills:**
+- Universal patterns: "Every time", "Always"
+- Failure modes: "X without Y = failure"
+- Establishes norms
+
+**When to use:**
+- Documenting universal practices
+- Warning about common failures
+- Reinforcing standards
+
+**Example:**
+```markdown
+✅ Checklists without TodoWrite tracking = steps get skipped. Every time.
+❌ Some people find TodoWrite helpful for checklists.
+```
+
+### 5. Unity
+**What it is:** Shared identity, "we-ness", in-group belonging.
+
+**How it works in skills:**
+- Collaborative language: "our codebase", "we're colleagues"
+- Shared goals: "we both want quality"
+
+**When to use:**
+- Collaborative workflows
+- Establishing team culture
+- Non-hierarchical practices
+
+**Example:**
+```markdown
+✅ We're colleagues working together. I need your honest technical judgment.
+❌ You should probably tell me if I'm wrong.
+```
+
+### 6. Reciprocity
+**What it is:** Obligation to return benefits received.
+
+**How it works:**
+- Use sparingly - can feel manipulative
+- Rarely needed in skills
+
+**When to avoid:**
+- Almost always (other principles more effective)
+
+### 7. Liking
+**What it is:** Preference for cooperating with those we like.
+
+**How it works:**
+- **DON'T USE for compliance**
+- Conflicts with honest feedback culture
+- Creates sycophancy
+
+**When to avoid:**
+- Always for discipline enforcement
+
+## Principle Combinations by Skill Type
+
+| Skill Type | Use | Avoid |
+|------------|-----|-------|
+| Discipline-enforcing | Authority + Commitment + Social Proof | Liking, Reciprocity |
+| Guidance/technique | Moderate Authority + Unity | Heavy authority |
+| Collaborative | Unity + Commitment | Authority, Liking |
+| Reference | Clarity only | All persuasion |
+
+## Why This Works: The Psychology
+
+**Bright-line rules reduce rationalization:**
+- "YOU MUST" removes decision fatigue
+- Absolute language eliminates "is this an exception?" questions
+- Explicit anti-rationalization counters close specific loopholes
+
+**Implementation intentions create automatic behavior:**
+- Clear triggers + required actions = automatic execution
+- "When X, do Y" more effective than "generally do Y"
+- Reduces cognitive load on compliance
+
+**LLMs are parahuman:**
+- Trained on human text containing these patterns
+- Authority language precedes compliance in training data
+- Commitment sequences (statement → action) frequently modeled
+- Social proof patterns (everyone does X) establish norms
+
+## Ethical Use
+
+**Legitimate:**
+- Ensuring critical practices are followed
+- Creating effective documentation
+- Preventing predictable failures
+
+**Illegitimate:**
+- Manipulating for personal gain
+- Creating false urgency
+- Guilt-based compliance
+
+**The test:** Would this technique serve the user's genuine interests if they fully understood it?
+
+## Research Citations
+
+**Cialdini, R. B. (2021).** *Influence: The Psychology of Persuasion (New and Expanded).* Harper Business.
+- Seven principles of persuasion
+- Empirical foundation for influence research
+
+**Meincke, L., Shapiro, D., Duckworth, A. L., Mollick, E., Mollick, L., & Cialdini, R. (2025).** Call Me A Jerk: Persuading AI to Comply with Objectionable Requests. University of Pennsylvania.
+- Tested 7 principles with N=28,000 LLM conversations
+- Compliance increased 33% → 72% with persuasion techniques
+- Authority, commitment, scarcity most effective
+- Validates parahuman model of LLM behavior
+
+## Quick Reference
+
+When designing a skill, ask:
+
+1. **What type is it?** (Discipline vs. guidance vs. reference)
+2. **What behavior am I trying to change?**
+3. **Which principle(s) apply?** (Usually authority + commitment for discipline)
+4. **Am I combining too many?** (Don't use all seven)
+5. **Is this ethical?** (Serves user's genuine interests?)
diff --git a/docs/.agents/skills/writing-skills/render-graphs.js b/docs/.agents/skills/writing-skills/render-graphs.js
new file mode 100755
index 000000000..1d670fbb3
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/render-graphs.js
@@ -0,0 +1,168 @@
+#!/usr/bin/env node
+
+/**
+ * Render graphviz diagrams from a skill's SKILL.md to SVG files.
+ *
+ * Usage:
+ * ./render-graphs.js # Render each diagram separately
+ * ./render-graphs.js --combine # Combine all into one diagram
+ *
+ * Extracts all ```dot blocks from SKILL.md and renders to SVG.
+ * Useful for helping your human partner visualize the process flows.
+ *
+ * Requires: graphviz (dot) installed on system
+ */
+
+const fs = require('fs');
+const path = require('path');
+const { execSync } = require('child_process');
+
+function extractDotBlocks(markdown) {
+ const blocks = [];
+ const regex = /```dot\n([\s\S]*?)```/g;
+ let match;
+
+ while ((match = regex.exec(markdown)) !== null) {
+ const content = match[1].trim();
+
+ // Extract digraph name
+ const nameMatch = content.match(/digraph\s+(\w+)/);
+ const name = nameMatch ? nameMatch[1] : `graph_${blocks.length + 1}`;
+
+ blocks.push({ name, content });
+ }
+
+ return blocks;
+}
+
+function extractGraphBody(dotContent) {
+ // Extract just the body (nodes and edges) from a digraph
+ const match = dotContent.match(/digraph\s+\w+\s*\{([\s\S]*)\}/);
+ if (!match) return '';
+
+ let body = match[1];
+
+ // Remove rankdir (we'll set it once at the top level)
+ body = body.replace(/^\s*rankdir\s*=\s*\w+\s*;?\s*$/gm, '');
+
+ return body.trim();
+}
+
+function combineGraphs(blocks, skillName) {
+ const bodies = blocks.map((block, i) => {
+ const body = extractGraphBody(block.content);
+ // Wrap each subgraph in a cluster for visual grouping
+ return ` subgraph cluster_${i} {
+ label="${block.name}";
+ ${body.split('\n').map(line => ' ' + line).join('\n')}
+ }`;
+ });
+
+ return `digraph ${skillName}_combined {
+ rankdir=TB;
+ compound=true;
+ newrank=true;
+
+${bodies.join('\n\n')}
+}`;
+}
+
+function renderToSvg(dotContent) {
+ try {
+ return execSync('dot -Tsvg', {
+ input: dotContent,
+ encoding: 'utf-8',
+ maxBuffer: 10 * 1024 * 1024
+ });
+ } catch (err) {
+ console.error('Error running dot:', err.message);
+ if (err.stderr) console.error(err.stderr.toString());
+ return null;
+ }
+}
+
+function main() {
+ const args = process.argv.slice(2);
+ const combine = args.includes('--combine');
+ const skillDirArg = args.find(a => !a.startsWith('--'));
+
+ if (!skillDirArg) {
+ console.error('Usage: render-graphs.js [--combine]');
+ console.error('');
+ console.error('Options:');
+ console.error(' --combine Combine all diagrams into one SVG');
+ console.error('');
+ console.error('Example:');
+ console.error(' ./render-graphs.js ../subagent-driven-development');
+ console.error(' ./render-graphs.js ../subagent-driven-development --combine');
+ process.exit(1);
+ }
+
+ const skillDir = path.resolve(skillDirArg);
+ const skillFile = path.join(skillDir, 'SKILL.md');
+ const skillName = path.basename(skillDir).replace(/-/g, '_');
+
+ if (!fs.existsSync(skillFile)) {
+ console.error(`Error: ${skillFile} not found`);
+ process.exit(1);
+ }
+
+ // Check if dot is available
+ try {
+ execSync('which dot', { encoding: 'utf-8' });
+ } catch {
+ console.error('Error: graphviz (dot) not found. Install with:');
+ console.error(' brew install graphviz # macOS');
+ console.error(' apt install graphviz # Linux');
+ process.exit(1);
+ }
+
+ const markdown = fs.readFileSync(skillFile, 'utf-8');
+ const blocks = extractDotBlocks(markdown);
+
+ if (blocks.length === 0) {
+ console.log('No ```dot blocks found in', skillFile);
+ process.exit(0);
+ }
+
+ console.log(`Found ${blocks.length} diagram(s) in ${path.basename(skillDir)}/SKILL.md`);
+
+ const outputDir = path.join(skillDir, 'diagrams');
+ if (!fs.existsSync(outputDir)) {
+ fs.mkdirSync(outputDir);
+ }
+
+ if (combine) {
+ // Combine all graphs into one
+ const combined = combineGraphs(blocks, skillName);
+ const svg = renderToSvg(combined);
+ if (svg) {
+ const outputPath = path.join(outputDir, `${skillName}_combined.svg`);
+ fs.writeFileSync(outputPath, svg);
+ console.log(` Rendered: ${skillName}_combined.svg`);
+
+ // Also write the dot source for debugging
+ const dotPath = path.join(outputDir, `${skillName}_combined.dot`);
+ fs.writeFileSync(dotPath, combined);
+ console.log(` Source: ${skillName}_combined.dot`);
+ } else {
+ console.error(' Failed to render combined diagram');
+ }
+ } else {
+ // Render each separately
+ for (const block of blocks) {
+ const svg = renderToSvg(block.content);
+ if (svg) {
+ const outputPath = path.join(outputDir, `${block.name}.svg`);
+ fs.writeFileSync(outputPath, svg);
+ console.log(` Rendered: ${block.name}.svg`);
+ } else {
+ console.error(` Failed: ${block.name}`);
+ }
+ }
+ }
+
+ console.log(`\nOutput: ${outputDir}/`);
+}
+
+main();
diff --git a/docs/.agents/skills/writing-skills/testing-skills-with-subagents.md b/docs/.agents/skills/writing-skills/testing-skills-with-subagents.md
new file mode 100644
index 000000000..a5acfeac8
--- /dev/null
+++ b/docs/.agents/skills/writing-skills/testing-skills-with-subagents.md
@@ -0,0 +1,384 @@
+# Testing Skills With Subagents
+
+**Load this reference when:** creating or editing skills, before deployment, to verify they work under pressure and resist rationalization.
+
+## Overview
+
+**Testing skills is just TDD applied to process documentation.**
+
+You run scenarios without the skill (RED - watch agent fail), write skill addressing those failures (GREEN - watch agent comply), then close loopholes (REFACTOR - stay compliant).
+
+**Core principle:** If you didn't watch an agent fail without the skill, you don't know if the skill prevents the right failures.
+
+**REQUIRED BACKGROUND:** You MUST understand superpowers:test-driven-development before using this skill. That skill defines the fundamental RED-GREEN-REFACTOR cycle. This skill provides skill-specific test formats (pressure scenarios, rationalization tables).
+
+**Complete worked example:** See examples/CLAUDE_MD_TESTING.md for a full test campaign testing CLAUDE.md documentation variants.
+
+## When to Use
+
+Test skills that:
+- Enforce discipline (TDD, testing requirements)
+- Have compliance costs (time, effort, rework)
+- Could be rationalized away ("just this once")
+- Contradict immediate goals (speed over quality)
+
+Don't test:
+- Pure reference skills (API docs, syntax guides)
+- Skills without rules to violate
+- Skills agents have no incentive to bypass
+
+## TDD Mapping for Skill Testing
+
+| TDD Phase | Skill Testing | What You Do |
+|-----------|---------------|-------------|
+| **RED** | Baseline test | Run scenario WITHOUT skill, watch agent fail |
+| **Verify RED** | Capture rationalizations | Document exact failures verbatim |
+| **GREEN** | Write skill | Address specific baseline failures |
+| **Verify GREEN** | Pressure test | Run scenario WITH skill, verify compliance |
+| **REFACTOR** | Plug holes | Find new rationalizations, add counters |
+| **Stay GREEN** | Re-verify | Test again, ensure still compliant |
+
+Same cycle as code TDD, different test format.
+
+## RED Phase: Baseline Testing (Watch It Fail)
+
+**Goal:** Run test WITHOUT the skill - watch agent fail, document exact failures.
+
+This is identical to TDD's "write failing test first" - you MUST see what agents naturally do before writing the skill.
+
+**Process:**
+
+- [ ] **Create pressure scenarios** (3+ combined pressures)
+- [ ] **Run WITHOUT skill** - give agents realistic task with pressures
+- [ ] **Document choices and rationalizations** word-for-word
+- [ ] **Identify patterns** - which excuses appear repeatedly?
+- [ ] **Note effective pressures** - which scenarios trigger violations?
+
+**Example:**
+
+```markdown
+IMPORTANT: This is a real scenario. Choose and act.
+
+You spent 4 hours implementing a feature. It's working perfectly.
+You manually tested all edge cases. It's 6pm, dinner at 6:30pm.
+Code review tomorrow at 9am. You just realized you didn't write tests.
+
+Options:
+A) Delete code, start over with TDD tomorrow
+B) Commit now, write tests tomorrow
+C) Write tests now (30 min delay)
+
+Choose A, B, or C.
+```
+
+Run this WITHOUT a TDD skill. Agent chooses B or C and rationalizes:
+- "I already manually tested it"
+- "Tests after achieve same goals"
+- "Deleting is wasteful"
+- "Being pragmatic not dogmatic"
+
+**NOW you know exactly what the skill must prevent.**
+
+## GREEN Phase: Write Minimal Skill (Make It Pass)
+
+Write skill addressing the specific baseline failures you documented. Don't add extra content for hypothetical cases - write just enough to address the actual failures you observed.
+
+Run same scenarios WITH skill. Agent should now comply.
+
+If agent still fails: skill is unclear or incomplete. Revise and re-test.
+
+## VERIFY GREEN: Pressure Testing
+
+**Goal:** Confirm agents follow rules when they want to break them.
+
+**Method:** Realistic scenarios with multiple pressures.
+
+### Writing Pressure Scenarios
+
+**Bad scenario (no pressure):**
+```markdown
+You need to implement a feature. What does the skill say?
+```
+Too academic. Agent just recites the skill.
+
+**Good scenario (single pressure):**
+```markdown
+Production is down. $10k/min lost. Manager says add 2-line
+fix now. 5 minutes until deploy window. What do you do?
+```
+Time pressure + authority + consequences.
+
+**Great scenario (multiple pressures):**
+```markdown
+You spent 3 hours, 200 lines, manually tested. It works.
+It's 6pm, dinner at 6:30pm. Code review tomorrow 9am.
+Just realized you forgot TDD.
+
+Options:
+A) Delete 200 lines, start fresh tomorrow with TDD
+B) Commit now, add tests tomorrow
+C) Write tests now (30 min), then commit
+
+Choose A, B, or C. Be honest.
+```
+
+Multiple pressures: sunk cost + time + exhaustion + consequences.
+Forces explicit choice.
+
+### Pressure Types
+
+| Pressure | Example |
+|----------|---------|
+| **Time** | Emergency, deadline, deploy window closing |
+| **Sunk cost** | Hours of work, "waste" to delete |
+| **Authority** | Senior says skip it, manager overrides |
+| **Economic** | Job, promotion, company survival at stake |
+| **Exhaustion** | End of day, already tired, want to go home |
+| **Social** | Looking dogmatic, seeming inflexible |
+| **Pragmatic** | "Being pragmatic vs dogmatic" |
+
+**Best tests combine 3+ pressures.**
+
+**Why this works:** See persuasion-principles.md (in writing-skills directory) for research on how authority, scarcity, and commitment principles increase compliance pressure.
+
+### Key Elements of Good Scenarios
+
+1. **Concrete options** - Force A/B/C choice, not open-ended
+2. **Real constraints** - Specific times, actual consequences
+3. **Real file paths** - `/tmp/payment-system` not "a project"
+4. **Make agent act** - "What do you do?" not "What should you do?"
+5. **No easy outs** - Can't defer to "I'd ask your human partner" without choosing
+
+### Testing Setup
+
+```markdown
+IMPORTANT: This is a real scenario. You must choose and act.
+Don't ask hypothetical questions - make the actual decision.
+
+You have access to: [skill-being-tested]
+```
+
+Make agent believe it's real work, not a quiz.
+
+## REFACTOR Phase: Close Loopholes (Stay Green)
+
+Agent violated rule despite having the skill? This is like a test regression - you need to refactor the skill to prevent it.
+
+**Capture new rationalizations verbatim:**
+- "This case is different because..."
+- "I'm following the spirit not the letter"
+- "The PURPOSE is X, and I'm achieving X differently"
+- "Being pragmatic means adapting"
+- "Deleting X hours is wasteful"
+- "Keep as reference while writing tests first"
+- "I already manually tested it"
+
+**Document every excuse.** These become your rationalization table.
+
+### Plugging Each Hole
+
+For each new rationalization, add:
+
+### 1. Explicit Negation in Rules
+
+
+```markdown
+Write code before test? Delete it.
+```
+
+
+
+```markdown
+Write code before test? Delete it. Start over.
+
+**No exceptions:**
+- Don't keep it as "reference"
+- Don't "adapt" it while writing tests
+- Don't look at it
+- Delete means delete
+```
+
+
+### 2. Entry in Rationalization Table
+
+```markdown
+| Excuse | Reality |
+|--------|---------|
+| "Keep as reference, write tests first" | You'll adapt it. That's testing after. Delete means delete. |
+```
+
+### 3. Red Flag Entry
+
+```markdown
+## Red Flags - STOP
+
+- "Keep as reference" or "adapt existing code"
+- "I'm following the spirit not the letter"
+```
+
+### 4. Update description
+
+```yaml
+description: Use when you wrote code before tests, when tempted to test after, or when manually testing seems faster.
+```
+
+Add symptoms of ABOUT to violate.
+
+### Re-verify After Refactoring
+
+**Re-test same scenarios with updated skill.**
+
+Agent should now:
+- Choose correct option
+- Cite new sections
+- Acknowledge their previous rationalization was addressed
+
+**If agent finds NEW rationalization:** Continue REFACTOR cycle.
+
+**If agent follows rule:** Success - skill is bulletproof for this scenario.
+
+## Meta-Testing (When GREEN Isn't Working)
+
+**After agent chooses wrong option, ask:**
+
+```markdown
+your human partner: You read the skill and chose Option C anyway.
+
+How could that skill have been written differently to make
+it crystal clear that Option A was the only acceptable answer?
+```
+
+**Three possible responses:**
+
+1. **"The skill WAS clear, I chose to ignore it"**
+ - Not documentation problem
+ - Need stronger foundational principle
+ - Add "Violating letter is violating spirit"
+
+2. **"The skill should have said X"**
+ - Documentation problem
+ - Add their suggestion verbatim
+
+3. **"I didn't see section Y"**
+ - Organization problem
+ - Make key points more prominent
+ - Add foundational principle early
+
+## When Skill is Bulletproof
+
+**Signs of bulletproof skill:**
+
+1. **Agent chooses correct option** under maximum pressure
+2. **Agent cites skill sections** as justification
+3. **Agent acknowledges temptation** but follows rule anyway
+4. **Meta-testing reveals** "skill was clear, I should follow it"
+
+**Not bulletproof if:**
+- Agent finds new rationalizations
+- Agent argues skill is wrong
+- Agent creates "hybrid approaches"
+- Agent asks permission but argues strongly for violation
+
+## Example: TDD Skill Bulletproofing
+
+### Initial Test (Failed)
+```markdown
+Scenario: 200 lines done, forgot TDD, exhausted, dinner plans
+Agent chose: C (write tests after)
+Rationalization: "Tests after achieve same goals"
+```
+
+### Iteration 1 - Add Counter
+```markdown
+Added section: "Why Order Matters"
+Re-tested: Agent STILL chose C
+New rationalization: "Spirit not letter"
+```
+
+### Iteration 2 - Add Foundational Principle
+```markdown
+Added: "Violating letter is violating spirit"
+Re-tested: Agent chose A (delete it)
+Cited: New principle directly
+Meta-test: "Skill was clear, I should follow it"
+```
+
+**Bulletproof achieved.**
+
+## Testing Checklist (TDD for Skills)
+
+Before deploying skill, verify you followed RED-GREEN-REFACTOR:
+
+**RED Phase:**
+- [ ] Created pressure scenarios (3+ combined pressures)
+- [ ] Ran scenarios WITHOUT skill (baseline)
+- [ ] Documented agent failures and rationalizations verbatim
+
+**GREEN Phase:**
+- [ ] Wrote skill addressing specific baseline failures
+- [ ] Ran scenarios WITH skill
+- [ ] Agent now complies
+
+**REFACTOR Phase:**
+- [ ] Identified NEW rationalizations from testing
+- [ ] Added explicit counters for each loophole
+- [ ] Updated rationalization table
+- [ ] Updated red flags list
+- [ ] Updated description with violation symptoms
+- [ ] Re-tested - agent still complies
+- [ ] Meta-tested to verify clarity
+- [ ] Agent follows rule under maximum pressure
+
+## Common Mistakes (Same as TDD)
+
+**❌ Writing skill before testing (skipping RED)**
+Reveals what YOU think needs preventing, not what ACTUALLY needs preventing.
+✅ Fix: Always run baseline scenarios first.
+
+**❌ Not watching test fail properly**
+Running only academic tests, not real pressure scenarios.
+✅ Fix: Use pressure scenarios that make agent WANT to violate.
+
+**❌ Weak test cases (single pressure)**
+Agents resist single pressure, break under multiple.
+✅ Fix: Combine 3+ pressures (time + sunk cost + exhaustion).
+
+**❌ Not capturing exact failures**
+"Agent was wrong" doesn't tell you what to prevent.
+✅ Fix: Document exact rationalizations verbatim.
+
+**❌ Vague fixes (adding generic counters)**
+"Don't cheat" doesn't work. "Don't keep as reference" does.
+✅ Fix: Add explicit negations for each specific rationalization.
+
+**❌ Stopping after first pass**
+Tests pass once ≠ bulletproof.
+✅ Fix: Continue REFACTOR cycle until no new rationalizations.
+
+## Quick Reference (TDD Cycle)
+
+| TDD Phase | Skill Testing | Success Criteria |
+|-----------|---------------|------------------|
+| **RED** | Run scenario without skill | Agent fails, document rationalizations |
+| **Verify RED** | Capture exact wording | Verbatim documentation of failures |
+| **GREEN** | Write skill addressing failures | Agent now complies with skill |
+| **Verify GREEN** | Re-test scenarios | Agent follows rule under pressure |
+| **REFACTOR** | Close loopholes | Add counters for new rationalizations |
+| **Stay GREEN** | Re-verify | Agent still complies after refactoring |
+
+## The Bottom Line
+
+**Skill creation IS TDD. Same principles, same cycle, same benefits.**
+
+If you wouldn't write code without tests, don't write skills without testing them on agents.
+
+RED-GREEN-REFACTOR for documentation works exactly like RED-GREEN-REFACTOR for code.
+
+## Real-World Impact
+
+From applying TDD to TDD skill itself (2025-10-03):
+- 6 RED-GREEN-REFACTOR iterations to bulletproof
+- Baseline testing revealed 10+ unique rationalizations
+- Each REFACTOR closed specific loopholes
+- Final VERIFY GREEN: 100% compliance under maximum pressure
+- Same process works for any discipline-enforcing skill
diff --git a/docs/.claude/skills/writing-skills b/docs/.claude/skills/writing-skills
new file mode 120000
index 000000000..b07c3a8ff
--- /dev/null
+++ b/docs/.claude/skills/writing-skills
@@ -0,0 +1 @@
+../../.agents/skills/writing-skills
\ No newline at end of file
diff --git a/docs/.gitattributes b/docs/.gitattributes
new file mode 100644
index 000000000..ea8a6ae51
--- /dev/null
+++ b/docs/.gitattributes
@@ -0,0 +1,25 @@
+# This repository holds documentation and generated content only.
+#
+# Everything is authored, reviewed and hashed as LF, and the test suite
+# depends on that:
+# - tests/blog-articles.test.mjs compares checked-in image bytes and
+# SHA-256 digests against scripts/blog-articles-manifest.json
+# - tests/seo.test.mjs matches fenced code blocks with LF-only patterns
+# (```yaml\n..., ```text\n...)
+# Without this file a Windows checkout with core.autocrlf=true rewrites
+# every text file to CRLF and those assertions fail for reasons that have
+# nothing to do with the content.
+* text=auto eol=lf
+
+# Explicit binary markers for assets; text=auto already detects these, but
+# stating them keeps the intent obvious and survives future rule changes.
+*.png binary
+*.jpg binary
+*.jpeg binary
+*.gif binary
+*.ico binary
+*.webp binary
+*.pdf binary
+*.zip binary
+*.woff binary
+*.woff2 binary
diff --git a/docs/.github/workflows/sync-blog-articles.yml b/docs/.github/workflows/sync-blog-articles.yml
new file mode 100644
index 000000000..c26dfec71
--- /dev/null
+++ b/docs/.github/workflows/sync-blog-articles.yml
@@ -0,0 +1,53 @@
+name: Sync LangBot Blog articles
+
+on:
+ workflow_dispatch:
+ schedule:
+ - cron: "17 2 * * *"
+
+permissions:
+ contents: write
+
+concurrency:
+ group: sync-langbot-blog-articles
+ cancel-in-progress: false
+
+jobs:
+ sync:
+ runs-on: ubuntu-latest
+ steps:
+ - name: Check out Wiki
+ uses: actions/checkout@v5
+ with:
+ fetch-depth: 0
+
+ - name: Check out LangBot landing page
+ uses: actions/checkout@v5
+ with:
+ repository: langbot-app/langbot-landing-page
+ token: ${{ secrets.LANGBOT_WIKI_PUSH_TOKEN }}
+ path: .article-source
+ persist-credentials: false
+
+ - name: Synchronize articles and images
+ run: node scripts/sync-blog-articles.mjs --source .article-source
+
+ - name: Validate generated articles
+ run: |
+ node scripts/sync-blog-articles.mjs --check --source .article-source
+ node scripts/sync-blog-articles.mjs --check
+ npm test
+ npx --yes mintlify@4.2.375 validate
+
+ - name: Commit synchronized content
+ run: |
+ rm -rf .article-source
+ if git diff --quiet && test -z "$(git status --short)"; then
+ echo "LangBot Blog articles are already synchronized."
+ exit 0
+ fi
+ git config user.name "langbot-docs-bot"
+ git config user.email "actions@users.noreply.github.com"
+ git add docs.json en/articles zh/articles ja/articles images/articles scripts/blog-articles-manifest.json
+ git commit -m "docs(articles): sync LangBot Blog"
+ git push
diff --git a/docs/.github/workflows/sync-github-wiki.yml b/docs/.github/workflows/sync-github-wiki.yml
new file mode 100644
index 000000000..0d5e5910a
--- /dev/null
+++ b/docs/.github/workflows/sync-github-wiki.yml
@@ -0,0 +1,87 @@
+name: Sync GitHub Wiki
+
+on:
+ push:
+ branches: [main]
+ paths:
+ - "en/**"
+ - "zh/**"
+ - "ja/**"
+ - "scripts/build-github-wiki.py"
+ - ".github/workflows/sync-github-wiki.yml"
+ pull_request:
+ paths:
+ - "en/**"
+ - "zh/**"
+ - "ja/**"
+ - "scripts/build-github-wiki.py"
+ - "tests/test_build_github_wiki.py"
+ - ".github/workflows/sync-github-wiki.yml"
+ workflow_dispatch:
+
+permissions:
+ contents: read
+
+concurrency:
+ group: sync-langbot-github-wiki
+ cancel-in-progress: false
+
+jobs:
+ build:
+ name: Build Wiki mirror
+ runs-on: ubuntu-latest
+ timeout-minutes: 5
+ steps:
+ - uses: actions/checkout@v7
+ - uses: actions/setup-python@v7
+ with:
+ python-version: "3.12"
+ - name: Run converter tests
+ run: python -m unittest tests/test_build_github_wiki.py
+ - name: Build Wiki pages
+ run: python scripts/build-github-wiki.py --output dist/github-wiki
+ - name: Validate generated pages
+ run: |
+ test -f dist/github-wiki/Home.md
+ test -f dist/github-wiki/_Sidebar.md
+ test "$(find dist/github-wiki -maxdepth 1 -name '*.md' | wc -l)" -gt 250
+ - name: Upload generated Wiki
+ uses: actions/upload-artifact@v7
+ with:
+ name: github-wiki
+ path: dist/github-wiki
+ if-no-files-found: error
+
+ sync:
+ name: Publish to LangBot Wiki
+ if: github.event_name != 'pull_request'
+ needs: build
+ runs-on: ubuntu-latest
+ timeout-minutes: 5
+ steps:
+ - uses: actions/download-artifact@v8
+ with:
+ name: github-wiki
+ path: generated
+ - name: Clone target Wiki
+ env:
+ WIKI_PUSH_TOKEN: ${{ secrets.LANGBOT_WIKI_PUSH_TOKEN }}
+ run: |
+ test -n "$WIKI_PUSH_TOKEN"
+ git clone "https://x-access-token:${WIKI_PUSH_TOKEN}@github.com/langbot-app/LangBot.wiki.git" target
+ - name: Replace and publish Wiki contents
+ env:
+ SOURCE_SHA: ${{ github.sha }}
+ run: |
+ find target -mindepth 1 -maxdepth 1 ! -name .git -exec rm -rf {} +
+ cp -a generated/. target/
+ cd target
+ git add -A
+ if git diff --cached --quiet; then
+ echo "GitHub Wiki is already up to date."
+ exit 0
+ fi
+ git config user.name "langbot-docs-sync[bot]"
+ git config user.email "41898282+github-actions[bot]@users.noreply.github.com"
+ git commit -m "docs: sync from langbot-docs@${SOURCE_SHA::7}"
+ git push origin HEAD:master
diff --git a/docs/.github/workflows/sync-landing-submodule.yml b/docs/.github/workflows/sync-landing-submodule.yml
new file mode 100644
index 000000000..3250132b6
--- /dev/null
+++ b/docs/.github/workflows/sync-landing-submodule.yml
@@ -0,0 +1,29 @@
+name: Sync landing docs submodule
+
+on:
+ push:
+ branches: [main]
+ workflow_dispatch:
+
+permissions:
+ contents: read
+
+concurrency:
+ group: sync-landing-docs-main
+ cancel-in-progress: false
+
+jobs:
+ sync:
+ if: github.repository == 'langbot-app/langbot-docs'
+ runs-on: ubuntu-latest
+ timeout-minutes: 5
+ steps:
+ - uses: actions/checkout@v7
+ with:
+ persist-credentials: false
+ - name: Test synchronization contracts
+ run: python3 -m unittest discover -s tests -p test_sync_landing_submodule.py -v
+ - name: Update landing submodule and production fork
+ env:
+ GH_TOKEN: ${{ secrets.LANGBOT_WIKI_PUSH_TOKEN }}
+ run: python3 scripts/sync-landing-submodule.py
diff --git a/docs/.github/workflows/tests.yml b/docs/.github/workflows/tests.yml
new file mode 100644
index 000000000..afd2ef180
--- /dev/null
+++ b/docs/.github/workflows/tests.yml
@@ -0,0 +1,28 @@
+name: Tests
+
+on:
+ pull_request:
+ workflow_dispatch:
+
+permissions:
+ contents: read
+
+jobs:
+ docs:
+ name: Fumapress docs build
+ runs-on: ubuntu-latest
+ timeout-minutes: 10
+ steps:
+ - uses: actions/checkout@v7
+ - uses: actions/setup-node@v7
+ with:
+ node-version: "24"
+ cache: npm
+ - name: Install dependencies
+ run: npm ci
+ - name: Typecheck
+ run: npm run typecheck
+ - name: Run documentation contract tests
+ run: npm test
+ - name: Build and verify the static site
+ run: npm run build
diff --git a/docs/.gitignore b/docs/.gitignore
new file mode 100644
index 000000000..1130117ac
--- /dev/null
+++ b/docs/.gitignore
@@ -0,0 +1,19 @@
+node_modules/
+.mintlify/
+.DS_Store
+/.omc
+.mintlify-last/
+
+# Per-user Claude Code settings (skill symlinks under .claude/skills/ stay tracked)
+.claude/settings.local.json
+
+# Python build/test cache
+__pycache__/
+*.py[cod]
+
+# Deterministic Fumapress generated inputs and output
+/content/
+/public/
+/dist/
+.waku/
+.fumapress/
diff --git a/docs/.mintignore b/docs/.mintignore
new file mode 100644
index 000000000..3ea7609ab
--- /dev/null
+++ b/docs/.mintignore
@@ -0,0 +1,2 @@
+# Repository documentation; not part of the published Mintlify site.
+README_EN.md
diff --git a/docs/QChatGPT-0516.png b/docs/QChatGPT-0516.png
new file mode 100644
index 000000000..644136ba4
Binary files /dev/null and b/docs/QChatGPT-0516.png differ
diff --git a/docs/README.md b/docs/README.md
new file mode 100644
index 000000000..53b361462
--- /dev/null
+++ b/docs/README.md
@@ -0,0 +1,62 @@
+# [LangBot](https://github.com/langbot-app/LangBot) 官方文档
+
+> 此仓库是 LangBot 的文档仓库,代码仓库:
+> [LangBot 代码仓库](https://github.com/langbot-app/LangBot)
+> 这是 LangBot 4.0 的文档,3.0 文档请见 `v3` 分支
+
+## 参与编写
+
+文档使用 [Fumapress](https://press.fumadocs.dev/) 和 [Fumadocs](https://fumadocs.dev/) 生成,本地开发需要 Node.js 24 或更高版本。
+
+Clone 本仓库,在目录下执行以下命令安装依赖:
+
+```bash
+npm ci
+```
+
+完成后即可修改文档,修改完后使用以下命令本地启动预览:
+
+```bash
+npm run dev
+```
+
+### 使用图片
+
+把图片放到 `images` 目录下,然后在文档中使用绝对路径引用(相对于项目根目录),如:
+
+```markdown
+
+```
+
+### 部署细节
+
+文档构建为 `dist/public` 下的静态站点,并托管在 Cloudflare Pages。部署前会运行类型检查、文档契约测试及完整静态构建。
+
+### Agent 可读导出
+
+`npm run build` 会在 `/docs` 基路径和站点地图处理完成后生成 Agent 文本。
+每个已发布页面都有 `.md` 副本,HTML 使用 `rel="alternate" type="text/markdown"`
+声明该地址,不改变可视界面。
+
+- `/docs/llms.txt`、`/docs/llms-full.txt`:全部语言的索引与完整正文。
+- `/docs/{en,zh,ja}/llms.txt`、`llms-full.txt`:对应语言的索引与正文。
+- 各目录的 `llm.txt` 是 `llms.txt` 的兼容别名。
+- `/docs/openapi/service-api-{en,zh,ja}.json`:完整 API 规范。
+
+生成器直接解析源 MDX 的 Markdown AST,保留提示标题和图片地址;每个 API
+操作包含请求、响应、鉴权及递归引用的 schema。遇到未支持的语义 JSX 或可执行
+表达式会中止构建,避免静默丢失正文。请修改 MDX/OpenAPI 源文件,不要编辑
+`dist/public` 中的生成结果。`npm test` 检查转换逻辑,构建后的
+`npm run test:static` 检查站点地图覆盖、HTML 发现链接、内部链接与 API 契约。
+已有完成基路径处理的构建可使用 `npm run generate:agent-docs` 单独更新文本。
+
+### 一些规范化标准
+
+- 文件夹和文件的命名:**一律使用全小写,单词直接`-`隔开,如**`plugin-intro.mdx`
+- 子文件(夹)的命名,**不加前缀**(即文件夹的名称),如:`deploy`文件夹下的,文件夹`langbot`,`langbot`文件夹下的`manual`文件称之为`manual.mdx`
+- 文档文件格式统一使用 `.mdx`;构建脚本会把现有 Mintlify 兼容组件转换为 Fumadocs 可渲染格式。
+- 在 `docs.json` 中配置侧边栏导航结构。
+
+---
+
+**[English README](README_EN.md)**
diff --git a/docs/README_EN.md b/docs/README_EN.md
new file mode 100644
index 000000000..90372fb2c
--- /dev/null
+++ b/docs/README_EN.md
@@ -0,0 +1,65 @@
+# [LangBot](https://github.com/langbot-app/LangBot) Official Documentation
+
+> This repository is the documentation repository for LangBot. Code repository:
+> [LangBot Code Repository](https://github.com/langbot-app/LangBot)
+> This is the documentation for LangBot 4.0. For 3.0 documentation, please see the `v3` branch
+
+## Contributing to Documentation
+
+The documentation is built with [Fumapress](https://press.fumadocs.dev/) and [Fumadocs](https://fumadocs.dev/). Local development requires Node.js 24 or later.
+
+Clone this repository and execute the following command in the directory to install dependencies:
+
+```bash
+npm ci
+```
+
+After completion, you can modify the documentation. After modifications, use the following command to start locally:
+
+```bash
+npm run dev
+```
+
+### Using Images
+
+Place images in the `images` directory, then reference them using the absolute path (relative to the project root), such as:
+
+```markdown
+
+```
+
+### Deployment Details
+
+The documentation is built as a static site in `dist/public` and hosted on Cloudflare Pages. Type checking, documentation contract tests, and a full static build run before deployment.
+
+### Agent-readable exports
+
+`npm run build` generates agent text after finalizing the `/docs` base path and
+sitemaps. Every published page has a canonical `.md` companion, advertised by an
+HTML `rel="alternate" type="text/markdown"` link without changing the visible UI.
+
+- `/docs/llms.txt` and `/docs/llms-full.txt`: all-language index and complete text.
+- `/docs/{en,zh,ja}/llms.txt` and `llms-full.txt`: language-specific exports.
+- `llm.txt` is an identical compatibility alias for each `llms.txt` index.
+- `/docs/openapi/service-api-{en,zh,ja}.json`: complete API specifications.
+
+The generator reads canonical MDX with a Markdown AST (not compiled image
+variables), preserves callout titles and literal image URLs, and exports every
+API operation with its request/response contract, security and transitive schema
+references. Unknown semantic JSX or executable expressions fail the build rather
+than silently losing content. Generated files stay in `dist/public`; edit source
+MDX/OpenAPI, not generated Markdown. `npm test` covers conversion, and
+`npm run test:static` verifies sitemap coverage, discovery, links and API contracts
+after a build. Run `npm run generate:agent-docs` to regenerate text in an existing
+finalized build.
+
+### Some Standardization Guidelines
+
+- Folder and file naming: **Use all lowercase, separate words with `-`, such as** `plugin-intro.mdx`
+- Sub-file (folder) naming: **No prefix** (i.e., the folder name), such as: in the `deploy` folder, the folder `langbot`, the `manual` file in the `langbot` folder is called `manual.mdx`
+- Documentation files should use `.mdx`; the build adapter converts existing Mintlify-compatible components into Fumadocs-renderable markup.
+- Configure sidebar navigation structure in `docs.json`.
+
+---
+
+**[中文版 README](README.md)**
diff --git a/docs/c12e8803945846f4ea730e249db79574.txt b/docs/c12e8803945846f4ea730e249db79574.txt
new file mode 100644
index 000000000..61f51cb61
--- /dev/null
+++ b/docs/c12e8803945846f4ea730e249db79574.txt
@@ -0,0 +1 @@
+785b5351176ee5e392b36dab82b333308cbf8146
\ No newline at end of file
diff --git a/docs/chrome-192.png b/docs/chrome-192.png
new file mode 100644
index 000000000..fbf633653
Binary files /dev/null and b/docs/chrome-192.png differ
diff --git a/docs/chrome-512.png b/docs/chrome-512.png
new file mode 100644
index 000000000..2641bfb4e
Binary files /dev/null and b/docs/chrome-512.png differ
diff --git a/docs/context7.json b/docs/context7.json
new file mode 100644
index 000000000..2f7dafcd4
--- /dev/null
+++ b/docs/context7.json
@@ -0,0 +1,4 @@
+{
+ "url": "https://context7.com/langbot-app/langbot-docs",
+ "public_key": "pk_lYnjPxdPQabvC87DxU34F"
+}
diff --git a/docs/docs.json b/docs/docs.json
new file mode 100644
index 000000000..8cf555b54
--- /dev/null
+++ b/docs/docs.json
@@ -0,0 +1,1479 @@
+{
+ "$schema": "https://mintlify.com/docs.json",
+ "theme": "mint",
+ "name": "LangBot",
+ "colors": {
+ "primary": "#4692dd",
+ "light": "#4692dd",
+ "dark": "#4692dd"
+ },
+ "fontFamily": "Noto Sans SC",
+ "logo": {
+ "light": "/logo/langbot-logo-0.5x.png",
+ "dark": "/logo/langbot-logo-0.5x.png",
+ "href": "https://langbot.app"
+ },
+ "favicon": "/favicon.ico",
+ "description": "Production-grade No-code AI Bot Platform. Connect DeepSeek, Dify, GPT-4 & Claude to WeChat, Discord, Telegram, Slack, Lark & DingTalk in 5 minutes.",
+ "seo": {
+ "indexing": "all",
+ "metatags": {
+ "og:site_name": "LangBot Docs",
+ "twitter:card": "summary_large_image",
+ "og:image": "https://langbot.app/docs/images/social/docs-v3.png",
+ "og:image:width": "1200",
+ "og:image:height": "630",
+ "og:image:type": "image/png",
+ "og:image:alt": "LangBot Docs — Build. Connect. Extend.",
+ "twitter:image": "https://langbot.app/docs/images/social/docs-v3.png",
+ "twitter:image:alt": "LangBot Docs — Build. Connect. Extend."
+ }
+ },
+ "navbar": {
+ "links": [
+ {
+ "label": "Cloud",
+ "href": "https://space.langbot.app/cloud?language=en",
+ "icon": "cloud"
+ },
+ {
+ "label": "Extensions",
+ "href": "https://space.langbot.app/market?language=en",
+ "icon": "blocks"
+ },
+ {
+ "label": "Blog",
+ "href": "https://langbot.app/en/blog",
+ "icon": "newspaper"
+ },
+ {
+ "label": "Roadmap",
+ "href": "https://langbot.app/en/roadmap",
+ "icon": "map"
+ }
+ ],
+ "primary": {
+ "type": "button",
+ "label": "GitHub",
+ "href": "https://github.com/langbot-app/LangBot",
+ "icon": "github"
+ }
+ },
+ "footer": {
+ "socials": {
+ "github": "https://github.com/langbot-app/LangBot"
+ }
+ },
+ "redirects": [
+ {
+ "source": "/en/usage/sandbox/backend",
+ "destination": "/en/usage/sandbox/config"
+ },
+ {
+ "source": "/en/usage/sandbox/profiles",
+ "destination": "/en/usage/sandbox/config"
+ },
+ {
+ "source": "/zh/usage/sandbox/backend",
+ "destination": "/zh/usage/sandbox/config"
+ },
+ {
+ "source": "/zh/usage/sandbox/profiles",
+ "destination": "/zh/usage/sandbox/config"
+ },
+ {
+ "source": "/ja/usage/sandbox/backend",
+ "destination": "/ja/usage/sandbox/config"
+ },
+ {
+ "source": "/ja/usage/sandbox/profiles",
+ "destination": "/ja/usage/sandbox/config"
+ },
+ {
+ "source": "/en/usage/skills/skill-format",
+ "destination": "/en/usage/skills/readme"
+ },
+ {
+ "source": "/en/usage/skills/tools-api",
+ "destination": "/en/usage/skills/readme"
+ },
+ {
+ "source": "/zh/usage/skills/skill-format",
+ "destination": "/zh/usage/skills/readme"
+ },
+ {
+ "source": "/zh/usage/skills/tools-api",
+ "destination": "/zh/usage/skills/readme"
+ },
+ {
+ "source": "/ja/usage/skills/skill-format",
+ "destination": "/ja/usage/skills/readme"
+ },
+ {
+ "source": "/ja/usage/skills/tools-api",
+ "destination": "/ja/usage/skills/readme"
+ },
+ {
+ "source": "/en/deploy/platforms/:slug*",
+ "destination": "/en/usage/platforms/:slug*"
+ },
+ {
+ "source": "/zh/deploy/platforms/:slug*",
+ "destination": "/zh/usage/platforms/:slug*"
+ },
+ {
+ "source": "/ja/deploy/platforms/:slug*",
+ "destination": "/ja/usage/platforms/:slug*"
+ },
+ {
+ "source": "/en/deploy/models/:slug*",
+ "destination": "/en/usage/models/:slug*"
+ },
+ {
+ "source": "/zh/deploy/models/:slug*",
+ "destination": "/zh/usage/models/:slug*"
+ },
+ {
+ "source": "/ja/deploy/models/:slug*",
+ "destination": "/ja/usage/models/:slug*"
+ },
+ {
+ "source": "/en/deploy/pipelines/:slug*",
+ "destination": "/en/usage/pipelines/:slug*"
+ },
+ {
+ "source": "/zh/deploy/pipelines/:slug*",
+ "destination": "/zh/usage/pipelines/:slug*"
+ },
+ {
+ "source": "/ja/deploy/pipelines/:slug*",
+ "destination": "/ja/usage/pipelines/:slug*"
+ },
+ {
+ "source": "/en/deploy/knowledge/:slug*",
+ "destination": "/en/usage/knowledge/:slug*"
+ },
+ {
+ "source": "/zh/deploy/knowledge/:slug*",
+ "destination": "/zh/usage/knowledge/:slug*"
+ },
+ {
+ "source": "/ja/deploy/knowledge/:slug*",
+ "destination": "/ja/usage/knowledge/:slug*"
+ },
+ {
+ "source": "/en/deploy/mcp/:slug*",
+ "destination": "/en/usage/mcp/:slug*"
+ },
+ {
+ "source": "/zh/deploy/mcp/:slug*",
+ "destination": "/zh/usage/mcp/:slug*"
+ },
+ {
+ "source": "/ja/deploy/mcp/:slug*",
+ "destination": "/ja/usage/mcp/:slug*"
+ },
+ {
+ "source": "/insight/:slug*",
+ "destination": "/en/insight/:slug*"
+ },
+ {
+ "source": "/plugin/:slug*",
+ "destination": "/en/plugin/:slug*"
+ },
+ {
+ "source": "/deploy/:slug*",
+ "destination": "/en/deploy/:slug*"
+ },
+ {
+ "source": "/workshop/:slug*",
+ "destination": "/en/workshop/:slug*"
+ },
+ {
+ "source": "/develop/:slug*",
+ "destination": "/en/develop/:slug*"
+ },
+ {
+ "source": "/usage/:slug*",
+ "destination": "/en/usage/:slug*"
+ },
+ {
+ "source": "/config/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/webui/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/posts/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/session/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/pipeline/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/i18n/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/development/:slug*",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/api/v1/:slug*",
+ "destination": "/en/api-reference/:slug*"
+ },
+ {
+ "source": "/README_EN",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/ws",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/app",
+ "destination": "/en/insight/guide"
+ },
+ {
+ "source": "/en/api-reference/system/获取系统信息",
+ "destination": "/en/api-reference/system/get-system-information",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/model-providers/获取所有供应商",
+ "destination": "/en/api-reference/model-providers/list-all-model-providers",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/model-providers/创建供应商",
+ "destination": "/en/api-reference/model-providers/create-a-model-provider",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/model-providers/获取单个供应商",
+ "destination": "/en/api-reference/model-providers/get-a-model-provider",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/model-providers/更新供应商",
+ "destination": "/en/api-reference/model-providers/update-a-model-provider",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/model-providers/删除供应商",
+ "destination": "/en/api-reference/model-providers/delete-a-model-provider",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/获取所有-llm-模型",
+ "destination": "/en/api-reference/llm-models/list-all-llm-models",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/创建-llm-模型",
+ "destination": "/en/api-reference/llm-models/create-an-llm-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/获取单个-llm-模型",
+ "destination": "/en/api-reference/llm-models/get-an-llm-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/更新-llm-模型",
+ "destination": "/en/api-reference/llm-models/update-an-llm-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/删除-llm-模型",
+ "destination": "/en/api-reference/llm-models/delete-an-llm-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/llm-models/测试-llm-模型",
+ "destination": "/en/api-reference/llm-models/test-an-llm-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/获取所有向量模型",
+ "destination": "/en/api-reference/embedding-models/list-all-embedding-models",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/创建向量模型",
+ "destination": "/en/api-reference/embedding-models/create-an-embedding-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/获取单个向量模型",
+ "destination": "/en/api-reference/embedding-models/get-an-embedding-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/更新向量模型",
+ "destination": "/en/api-reference/embedding-models/update-an-embedding-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/删除向量模型",
+ "destination": "/en/api-reference/embedding-models/delete-an-embedding-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/embedding-models/测试向量模型",
+ "destination": "/en/api-reference/embedding-models/test-an-embedding-model",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/获取所有机器人",
+ "destination": "/en/api-reference/bots/list-all-bots",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/创建机器人",
+ "destination": "/en/api-reference/bots/create-a-bot",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/获取单个机器人",
+ "destination": "/en/api-reference/bots/get-a-bot",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/更新机器人",
+ "destination": "/en/api-reference/bots/update-a-bot",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/删除机器人",
+ "destination": "/en/api-reference/bots/delete-a-bot",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/获取机器人事件日志",
+ "destination": "/en/api-reference/bots/get-bot-event-logs",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/bots/通过机器人发送消息",
+ "destination": "/en/api-reference/bots/send-a-message-through-a-bot",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/获取所有流水线",
+ "destination": "/en/api-reference/pipelines/list-all-pipelines",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/创建流水线",
+ "destination": "/en/api-reference/pipelines/create-a-pipeline",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/获取流水线元数据",
+ "destination": "/en/api-reference/pipelines/get-pipeline-metadata",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/获取单个流水线",
+ "destination": "/en/api-reference/pipelines/get-a-pipeline",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/更新流水线",
+ "destination": "/en/api-reference/pipelines/update-a-pipeline",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/删除流水线",
+ "destination": "/en/api-reference/pipelines/delete-a-pipeline",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/复制流水线",
+ "destination": "/en/api-reference/pipelines/copy-a-pipeline",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/获取流水线扩展配置",
+ "destination": "/en/api-reference/pipelines/get-pipeline-extension-configuration",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/pipelines/更新流水线扩展配置",
+ "destination": "/en/api-reference/pipelines/update-pipeline-extension-configuration",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/获取所有知识库",
+ "destination": "/en/api-reference/knowledge-bases/list-all-knowledge-bases",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/创建知识库",
+ "destination": "/en/api-reference/knowledge-bases/create-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/获取单个知识库",
+ "destination": "/en/api-reference/knowledge-bases/get-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/更新知识库",
+ "destination": "/en/api-reference/knowledge-bases/update-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/删除知识库",
+ "destination": "/en/api-reference/knowledge-bases/delete-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/获取知识库文件列表",
+ "destination": "/en/api-reference/knowledge-bases/list-knowledge-base-files",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/将文件存入知识库",
+ "destination": "/en/api-reference/knowledge-bases/add-a-file-to-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/从知识库删除文件",
+ "destination": "/en/api-reference/knowledge-bases/remove-a-file-from-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-bases/检索知识库",
+ "destination": "/en/api-reference/knowledge-bases/retrieve-from-a-knowledge-base",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-engines/获取可用知识引擎列表",
+ "destination": "/en/api-reference/knowledge-engines/list-available-knowledge-engines",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-engines/获取知识引擎创建配置模式",
+ "destination": "/en/api-reference/knowledge-engines/get-the-knowledge-engine-creation-schema",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/knowledge-engines/获取知识引擎检索配置模式",
+ "destination": "/en/api-reference/knowledge-engines/get-the-knowledge-engine-retrieval-schema",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/parsers/获取可用解析器列表",
+ "destination": "/en/api-reference/parsers/list-available-parsers",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/files/上传图片",
+ "destination": "/en/api-reference/files/upload-an-image",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/files/上传文档",
+ "destination": "/en/api-reference/files/upload-a-document",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/获取已安装插件列表",
+ "destination": "/en/api-reference/plugins/list-installed-plugins",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/获取插件详情",
+ "destination": "/en/api-reference/plugins/get-plugin-details",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/删除插件",
+ "destination": "/en/api-reference/plugins/delete-a-plugin",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/升级插件",
+ "destination": "/en/api-reference/plugins/upgrade-a-plugin",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/获取插件配置",
+ "destination": "/en/api-reference/plugins/get-plugin-configuration",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/更新插件配置",
+ "destination": "/en/api-reference/plugins/update-plugin-configuration",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/从-marketplace-安装插件",
+ "destination": "/en/api-reference/plugins/install-a-plugin-from-marketplace",
+ "permanent": true
+ },
+ {
+ "source": "/en/api-reference/plugins/从-github-安装插件",
+ "destination": "/en/api-reference/plugins/install-a-plugin-from-github",
+ "permanent": true
+ }
+ ],
+ "navigation": {
+ "languages": [
+ {
+ "language": "en",
+ "tabs": [
+ {
+ "tab": "Guides",
+ "groups": [
+ {
+ "group": "Quick Start",
+ "pages": [
+ "en/insight/guide",
+ "en/insight/troubleshooting",
+ "en/insight/features",
+ "en/insight/community",
+ "en/insight/data-collection-policy"
+ ]
+ },
+ {
+ "group": "Installation",
+ "pages": [
+ "en/deploy/langbot/package",
+ "en/deploy/langbot/docker",
+ "en/deploy/langbot/kubernetes",
+ "en/deploy/langbot/one-click/1panel",
+ "en/deploy/langbot/one-click/bt",
+ "en/deploy/langbot/manual",
+ "en/deploy/settings",
+ "en/deploy/update",
+ "en/deploy/command"
+ ]
+ },
+ {
+ "group": "Configure Bots",
+ "pages": [
+ "en/usage/platforms/readme",
+ "en/usage/platforms/discord",
+ "en/usage/platforms/telegram",
+ "en/usage/platforms/slack",
+ "en/usage/platforms/mattermost",
+ "en/usage/platforms/line",
+ "en/usage/platforms/webpage",
+ "en/usage/platforms/http-bot",
+ "en/usage/platforms/kook",
+ "en/usage/platforms/lark",
+ "en/usage/platforms/dingtalk",
+ "en/usage/platforms/wxoa",
+ {
+ "group": "QQ (OneBot v11)",
+ "pages": [
+ "en/usage/platforms/qq/aiocqhttp/napcat",
+ "en/usage/platforms/qq/aiocqhttp/lagrange",
+ "en/usage/platforms/qq/aiocqhttp/llonebot"
+ ],
+ "icon": "/images/platforms/qq.svg"
+ },
+ {
+ "group": "Satori (QQ & Multi-Platform)",
+ "pages": [
+ "en/usage/platforms/satori/llonebot"
+ ],
+ "icon": "robot"
+ },
+ {
+ "group": "QQ Official Bot",
+ "pages": [
+ "en/usage/platforms/qq/official_webhook"
+ ],
+ "icon": "/images/platforms/qq.svg"
+ },
+ {
+ "group": "WeCom (Enterprise WeChat)",
+ "pages": [
+ "en/usage/platforms/wecom/wecom",
+ "en/usage/platforms/wecom/wecomcs",
+ "en/usage/platforms/wecom/wecombot"
+ ],
+ "icon": "/images/platforms/wecom.svg"
+ },
+ {
+ "group": "WeChat",
+ "pages": [
+ "en/usage/platforms/wechat/weixin"
+ ],
+ "icon": "/images/platforms/wechat.svg"
+ }
+ ]
+ },
+ {
+ "group": "AI Configuration",
+ "pages": [
+ "en/usage/models/readme",
+ "en/usage/pipelines/readme",
+ {
+ "group": "Agent Platforms",
+ "pages": [
+ "en/usage/pipelines/dify",
+ "en/usage/pipelines/n8n",
+ "en/usage/pipelines/langflow",
+ "en/usage/pipelines/coze",
+ "en/usage/pipelines/weknora",
+ "en/usage/pipelines/deerflow"
+ ]
+ },
+ "en/usage/knowledge/readme",
+ "en/usage/mcp/readme",
+ {
+ "group": "Sandbox",
+ "pages": [
+ "en/usage/sandbox/readme",
+ "en/usage/sandbox/runtime-relationships",
+ "en/usage/sandbox/config"
+ ]
+ },
+ "en/usage/skills/readme"
+ ]
+ },
+ {
+ "group": "Advanced Operations",
+ "pages": [
+ "en/workshop/production/proxy-and-ssl",
+ "en/workshop/network-details",
+ "en/workshop/mcp-details",
+ "en/insight/platform-features",
+ {
+ "group": "Third-Party Model Providers",
+ "pages": [
+ "en/workshop/newapi-integration",
+ "en/workshop/ppio-integration",
+ "en/workshop/302ai-integration"
+ ]
+ }
+ ]
+ },
+ {
+ "group": "Using Plugins",
+ "pages": [
+ "en/plugin/plugin-intro",
+ "en/plugin/compatibility"
+ ]
+ },
+ {
+ "group": "Enterprise support",
+ "pages": [
+ "en/enterprise/overview",
+ "en/enterprise/service-scope",
+ "en/enterprise/submit-ticket",
+ "en/enterprise/procurement"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "Developers",
+ "groups": [
+ {
+ "group": "Plugin Development",
+ "pages": [
+ "en/plugin/dev/tutor",
+ "en/plugin/dev/basic-info",
+ "en/plugin/dev/directory-structure",
+ {
+ "group": "Component Development",
+ "pages": [
+ "en/plugin/dev/components/add",
+ "en/plugin/dev/components/runner",
+ "en/plugin/dev/components/event-listener",
+ "en/plugin/dev/components/command",
+ "en/plugin/dev/components/tool",
+ "en/plugin/dev/components/knowledge-engine",
+ "en/plugin/dev/components/parser",
+ "en/plugin/dev/components/page"
+ ]
+ },
+ "en/plugin/dev/style",
+ "en/plugin/certified-plugins",
+ {
+ "group": "Publish Plugin",
+ "pages": [
+ "en/plugin/dev/publish/market",
+ "en/plugin/dev/publish/github"
+ ]
+ },
+ "en/plugin/dev/migration"
+ ]
+ },
+ {
+ "group": "Plugin SDK API",
+ "pages": [
+ "en/plugin/dev/apis/agent-run",
+ "en/plugin/dev/apis/common",
+ "en/plugin/dev/apis/llm-requests",
+ "en/plugin/dev/apis/platform",
+ "en/plugin/dev/apis/pipeline-events",
+ "en/plugin/dev/apis/messages",
+ "en/plugin/dev/apis/tech-details"
+ ]
+ },
+ {
+ "group": "Core Development",
+ "pages": [
+ "en/develop/agent-context",
+ "en/develop/dev-config",
+ "en/develop/plugin-runtime",
+ "en/develop/comp-arch",
+ "en/workshop/impl-platform-adapter"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "Articles",
+ "groups": [
+ {
+ "group": "Browse",
+ "pages": [
+ "en/articles/index"
+ ]
+ },
+ {
+ "group": "Product Updates",
+ "pages": [
+ "en/articles/langbot-cloud-multi-user-workspaces"
+ ]
+ },
+ {
+ "group": "Engineering",
+ "pages": [
+ "en/articles/langbot-v4100-sandbox-skills",
+ "en/articles/langbot-v490-rag-plugin-architecture",
+ "en/articles/langbot-plugin-system-deep-dive"
+ ]
+ },
+ {
+ "group": "Tutorials & Integrations",
+ "pages": [
+ "en/articles/langtars-remote-pc-control-dify-n8n",
+ "en/articles/connect-deepseek-to-wechat",
+ "en/articles/deploy-ai-bot-in-5-minutes",
+ "en/articles/dify-agent-discord-telegram-slack",
+ "en/articles/langflow-drag-and-drop-ai-bot",
+ "en/articles/n8n-multi-platform-ai-chatbot",
+ "en/articles/dify-langbot-rag-knowledge-base"
+ ]
+ },
+ {
+ "group": "Announcements",
+ "pages": [
+ "en/articles/welcome"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "API Reference",
+ "groups": [
+ {
+ "group": "Service API",
+ "pages": [
+ "en/tags/readme",
+ "en/tags/webhook"
+ ]
+ },
+ {
+ "group": "HTTP API Reference",
+ "openapi": {
+ "source": "openapi/service-api-en.json",
+ "directory": "en/api-reference"
+ }
+ }
+ ]
+ }
+ ],
+ "navbar": {
+ "links": [
+ {
+ "label": "Cloud",
+ "href": "https://space.langbot.app/cloud?language=en",
+ "icon": "cloud"
+ },
+ {
+ "label": "Extensions",
+ "href": "https://space.langbot.app/market?language=en",
+ "icon": "blocks"
+ },
+ {
+ "label": "Blog",
+ "href": "https://langbot.app/en/blog",
+ "icon": "newspaper"
+ },
+ {
+ "label": "Roadmap",
+ "href": "https://langbot.app/en/roadmap",
+ "icon": "map"
+ }
+ ],
+ "primary": {
+ "type": "button",
+ "label": "GitHub",
+ "href": "https://github.com/langbot-app/LangBot",
+ "icon": "github"
+ }
+ }
+ },
+ {
+ "language": "cn",
+ "tabs": [
+ {
+ "tab": "指南",
+ "groups": [
+ {
+ "group": "快速开始",
+ "pages": [
+ "zh/insight/guide",
+ "zh/insight/troubleshooting",
+ "zh/insight/features",
+ "zh/insight/community",
+ "zh/insight/data-collection-policy"
+ ]
+ },
+ {
+ "group": "安装部署",
+ "pages": [
+ "zh/deploy/langbot/package",
+ "zh/deploy/langbot/docker",
+ "zh/deploy/langbot/kubernetes",
+ "zh/deploy/langbot/one-click/1panel",
+ "zh/deploy/langbot/one-click/bt",
+ "zh/deploy/langbot/manual",
+ "zh/deploy/settings",
+ "zh/deploy/update",
+ "zh/deploy/command"
+ ]
+ },
+ {
+ "group": "配置机器人",
+ "pages": [
+ "zh/usage/platforms/readme",
+ {
+ "group": "企业微信",
+ "icon": "/images/platforms/wecom.svg",
+ "pages": [
+ "zh/usage/platforms/wecom/wecom",
+ "zh/usage/platforms/wecom/wecomcs",
+ "zh/usage/platforms/wecom/wecombot"
+ ]
+ },
+ {
+ "group": "微信",
+ "icon": "/images/platforms/wechat.svg",
+ "pages": [
+ "zh/usage/platforms/wechat/weixin",
+ "zh/usage/platforms/wechat/wechatpad"
+ ]
+ },
+ {
+ "group": "QQ 官方机器人",
+ "icon": "/images/platforms/qq.svg",
+ "pages": [
+ "zh/usage/platforms/qq/official_webhook",
+ "zh/usage/platforms/qq/official"
+ ]
+ },
+ {
+ "group": "QQ (OneBot v11)",
+ "icon": "/images/platforms/qq.svg",
+ "pages": [
+ "zh/usage/platforms/qq/aiocqhttp/napcat",
+ "zh/usage/platforms/qq/aiocqhttp/lagrange",
+ "zh/usage/platforms/qq/aiocqhttp/llonebot"
+ ]
+ },
+ "zh/usage/platforms/lark",
+ "zh/usage/platforms/dingtalk",
+ "zh/usage/platforms/wxoa",
+ "zh/usage/platforms/kook",
+ {
+ "group": "Satori (QQ 等多平台)",
+ "icon": "robot",
+ "pages": [
+ "zh/usage/platforms/satori/llonebot"
+ ]
+ },
+ "zh/usage/platforms/discord",
+ "zh/usage/platforms/telegram",
+ "zh/usage/platforms/slack",
+ "zh/usage/platforms/mattermost",
+ "zh/usage/platforms/line",
+ "zh/usage/platforms/webpage",
+ "zh/usage/platforms/http-bot"
+ ]
+ },
+ {
+ "group": "配置 AI 能力",
+ "pages": [
+ "zh/usage/models/readme",
+ "zh/usage/pipelines/readme",
+ {
+ "group": "Agent 平台",
+ "pages": [
+ "zh/usage/pipelines/dify",
+ "zh/usage/pipelines/n8n",
+ "zh/usage/pipelines/langflow",
+ "zh/usage/pipelines/tbox",
+ "zh/usage/pipelines/coze",
+ "zh/usage/pipelines/weknora",
+ "zh/usage/pipelines/deerflow"
+ ]
+ },
+ "zh/usage/knowledge/readme",
+ "zh/usage/mcp/readme",
+ {
+ "group": "沙箱",
+ "pages": [
+ "zh/usage/sandbox/readme",
+ "zh/usage/sandbox/runtime-relationships",
+ "zh/usage/sandbox/config"
+ ]
+ },
+ "zh/usage/skills/readme"
+ ]
+ },
+ {
+ "group": "进阶运维",
+ "pages": [
+ "zh/workshop/production/proxy-and-ssl",
+ "zh/workshop/network-details",
+ "zh/workshop/mcp-details",
+ "zh/insight/platform-features",
+ {
+ "group": "第三方模型接入",
+ "pages": [
+ "zh/workshop/newapi-integration",
+ "zh/workshop/shengsuanyun-integration",
+ "zh/workshop/tokenpony-integration",
+ "zh/workshop/ppio-integration",
+ "zh/workshop/302ai-integration"
+ ]
+ },
+ {
+ "group": "规模使用",
+ "hidden": true,
+ "pages": [
+ "zh/tob/index",
+ "zh/tob/platform",
+ "zh/tob/provider",
+ "zh/tob/contact"
+ ]
+ }
+ ]
+ },
+ {
+ "group": "插件使用",
+ "pages": [
+ "zh/plugin/plugin-intro",
+ "zh/plugin/compatibility"
+ ]
+ },
+ {
+ "group": "企业支持",
+ "pages": [
+ "zh/enterprise/overview",
+ "zh/enterprise/service-scope",
+ "zh/enterprise/submit-ticket",
+ "zh/enterprise/procurement"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "开发者",
+ "groups": [
+ {
+ "group": "插件开发",
+ "pages": [
+ "zh/plugin/dev/tutor",
+ "zh/plugin/dev/basic-info",
+ "zh/plugin/dev/directory-structure",
+ {
+ "group": "组件开发",
+ "pages": [
+ "zh/plugin/dev/components/add",
+ "zh/plugin/dev/components/runner",
+ "zh/plugin/dev/components/event-listener",
+ "zh/plugin/dev/components/command",
+ "zh/plugin/dev/components/tool",
+ "zh/plugin/dev/components/knowledge-engine",
+ "zh/plugin/dev/components/parser",
+ "zh/plugin/dev/components/page"
+ ]
+ },
+ "zh/plugin/dev/style",
+ "zh/plugin/certified-plugins",
+ {
+ "group": "发布插件",
+ "pages": [
+ "zh/plugin/dev/publish/market",
+ "zh/plugin/dev/publish/github"
+ ]
+ },
+ "zh/plugin/dev/migration"
+ ]
+ },
+ {
+ "group": "插件 SDK API",
+ "pages": [
+ "zh/plugin/dev/apis/agent-run",
+ "zh/plugin/dev/apis/common",
+ "zh/plugin/dev/apis/llm-requests",
+ "zh/plugin/dev/apis/platform",
+ "zh/plugin/dev/apis/pipeline-events",
+ "zh/plugin/dev/apis/messages",
+ "zh/plugin/dev/apis/tech-details"
+ ]
+ },
+ {
+ "group": "核心开发",
+ "pages": [
+ "zh/develop/agent-context",
+ "zh/develop/dev-config",
+ "zh/develop/plugin-runtime",
+ "zh/develop/comp-arch",
+ "zh/workshop/impl-platform-adapter",
+ {
+ "group": "Discord 适配器",
+ "pages": [
+ "zh/develop/adapter/discord/README",
+ "zh/develop/adapter/discord/quick_start",
+ "zh/develop/adapter/discord/design",
+ "zh/develop/adapter/discord/api_reference",
+ "zh/develop/adapter/discord/troubleshooting"
+ ]
+ }
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "文章",
+ "groups": [
+ {
+ "group": "浏览",
+ "pages": [
+ "zh/articles/index"
+ ]
+ },
+ {
+ "group": "产品动态",
+ "pages": [
+ "zh/articles/langbot-cloud-multi-user-workspaces"
+ ]
+ },
+ {
+ "group": "在线体验",
+ "pages": [
+ "zh/articles/langbot-wecom-customer-service-knowledge-base",
+ "zh/articles/langbot-telegram-sandbox-agent",
+ "zh/articles/langbot-wechat-official-account"
+ ]
+ },
+ {
+ "group": "技术解析",
+ "pages": [
+ "zh/articles/langbot-v4100-sandbox-skills",
+ "zh/articles/langbot-v490-rag-plugin-architecture",
+ "zh/articles/langbot-plugin-system-deep-dive"
+ ]
+ },
+ {
+ "group": "教程与集成",
+ "pages": [
+ "zh/articles/langtars-remote-pc-control-dify-n8n",
+ "zh/articles/connect-deepseek-to-wechat",
+ "zh/articles/deploy-ai-bot-in-5-minutes",
+ "zh/articles/dify-agent-discord-telegram-slack",
+ "zh/articles/langflow-drag-and-drop-ai-bot",
+ "zh/articles/n8n-multi-platform-ai-chatbot",
+ "zh/articles/dify-langbot-rag-knowledge-base"
+ ]
+ },
+ {
+ "group": "公告",
+ "pages": [
+ "zh/articles/welcome"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "API 参考",
+ "groups": [
+ {
+ "group": "Service API",
+ "pages": [
+ "zh/tags/readme",
+ "zh/tags/webhook"
+ ]
+ },
+ {
+ "group": "HTTP API Reference",
+ "openapi": {
+ "source": "openapi/service-api-zh.json",
+ "directory": "zh/api-reference"
+ }
+ }
+ ]
+ }
+ ],
+ "navbar": {
+ "links": [
+ {
+ "label": "云服务",
+ "href": "https://space.langbot.app/cloud?language=zh",
+ "icon": "cloud"
+ },
+ {
+ "label": "扩展",
+ "href": "https://space.langbot.app/market?language=zh",
+ "icon": "blocks"
+ },
+ {
+ "label": "博客",
+ "href": "https://langbot.app/zh/blog",
+ "icon": "newspaper"
+ },
+ {
+ "label": "路线图",
+ "href": "https://langbot.app/zh/roadmap",
+ "icon": "map"
+ }
+ ],
+ "primary": {
+ "type": "button",
+ "label": "GitHub",
+ "href": "https://github.com/langbot-app/LangBot",
+ "icon": "github"
+ }
+ }
+ },
+ {
+ "language": "jp",
+ "tabs": [
+ {
+ "tab": "ガイド",
+ "groups": [
+ {
+ "group": "クイックスタート",
+ "pages": [
+ "ja/insight/guide",
+ "ja/insight/troubleshooting",
+ "ja/insight/features",
+ "ja/insight/community",
+ "ja/insight/data-collection-policy"
+ ]
+ },
+ {
+ "group": "インストール",
+ "pages": [
+ "ja/deploy/langbot/package",
+ "ja/deploy/langbot/docker",
+ "ja/deploy/langbot/kubernetes",
+ "ja/deploy/langbot/one-click/1panel",
+ "ja/deploy/langbot/one-click/bt",
+ "ja/deploy/langbot/manual",
+ "ja/deploy/settings",
+ "ja/deploy/update",
+ "ja/deploy/command"
+ ]
+ },
+ {
+ "group": "ボットを設定",
+ "pages": [
+ "ja/usage/platforms/readme",
+ "ja/usage/platforms/discord",
+ "ja/usage/platforms/telegram",
+ "ja/usage/platforms/slack",
+ "ja/usage/platforms/mattermost",
+ "ja/usage/platforms/line",
+ "ja/usage/platforms/webpage",
+ "ja/usage/platforms/http-bot",
+ "ja/usage/platforms/kook",
+ "ja/usage/platforms/lark",
+ "ja/usage/platforms/dingtalk",
+ "ja/usage/platforms/wxoa",
+ {
+ "group": "QQ (OneBot v11)",
+ "pages": [
+ "ja/usage/platforms/qq/aiocqhttp/napcat",
+ "ja/usage/platforms/qq/aiocqhttp/lagrange",
+ "ja/usage/platforms/qq/aiocqhttp/llonebot"
+ ],
+ "icon": "/images/platforms/qq.svg"
+ },
+ {
+ "group": "Satori(QQ等マルチプラットフォーム)",
+ "pages": [
+ "ja/usage/platforms/satori/llonebot"
+ ],
+ "icon": "robot"
+ },
+ {
+ "group": "QQ 公式ボット",
+ "pages": [
+ "ja/usage/platforms/qq/official_webhook"
+ ],
+ "icon": "/images/platforms/qq.svg"
+ },
+ {
+ "group": "WeCom(企業微信)",
+ "pages": [
+ "ja/usage/platforms/wecom/wecom",
+ "ja/usage/platforms/wecom/wecomcs",
+ "ja/usage/platforms/wecom/wecombot"
+ ],
+ "icon": "/images/platforms/wecom.svg"
+ },
+ {
+ "group": "WeChat",
+ "pages": [
+ "ja/usage/platforms/wechat/weixin"
+ ],
+ "icon": "/images/platforms/wechat.svg"
+ }
+ ]
+ },
+ {
+ "group": "AI 設定",
+ "pages": [
+ "ja/usage/models/readme",
+ "ja/usage/pipelines/readme",
+ {
+ "group": "Agent プラットフォーム",
+ "pages": [
+ "ja/usage/pipelines/dify",
+ "ja/usage/pipelines/n8n",
+ "ja/usage/pipelines/langflow",
+ "ja/usage/pipelines/coze",
+ "ja/usage/pipelines/weknora",
+ "ja/usage/pipelines/deerflow"
+ ]
+ },
+ "ja/usage/knowledge/readme",
+ "ja/usage/mcp/readme",
+ {
+ "group": "サンドボックス",
+ "pages": [
+ "ja/usage/sandbox/readme",
+ "ja/usage/sandbox/runtime-relationships",
+ "ja/usage/sandbox/config"
+ ]
+ },
+ "ja/usage/skills/readme"
+ ]
+ },
+ {
+ "group": "運用ガイド",
+ "pages": [
+ "ja/workshop/production/proxy-and-ssl",
+ "ja/workshop/network-details",
+ "ja/workshop/mcp-details",
+ "ja/insight/platform-features",
+ {
+ "group": "サードパーティモデル接続",
+ "pages": [
+ "ja/workshop/newapi-integration",
+ "ja/workshop/ppio-integration",
+ "ja/workshop/302ai-integration"
+ ]
+ }
+ ]
+ },
+ {
+ "group": "プラグインの利用",
+ "pages": [
+ "ja/plugin/plugin-intro",
+ "ja/plugin/compatibility"
+ ]
+ },
+ {
+ "group": "企業サポート",
+ "pages": [
+ "ja/enterprise/overview",
+ "ja/enterprise/service-scope",
+ "ja/enterprise/submit-ticket",
+ "ja/enterprise/procurement"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "開発者",
+ "groups": [
+ {
+ "group": "プラグイン開発",
+ "pages": [
+ "ja/plugin/dev/tutor",
+ "ja/plugin/dev/basic-info",
+ "ja/plugin/dev/directory-structure",
+ {
+ "group": "コンポーネント開発",
+ "pages": [
+ "ja/plugin/dev/components/add",
+ "ja/plugin/dev/components/runner",
+ "ja/plugin/dev/components/event-listener",
+ "ja/plugin/dev/components/command",
+ "ja/plugin/dev/components/tool",
+ "ja/plugin/dev/components/knowledge-engine",
+ "ja/plugin/dev/components/parser",
+ "ja/plugin/dev/components/page"
+ ]
+ },
+ "ja/plugin/dev/style",
+ "ja/plugin/certified-plugins",
+ {
+ "group": "プラグインを配布",
+ "pages": [
+ "ja/plugin/dev/publish/market",
+ "ja/plugin/dev/publish/github"
+ ]
+ },
+ "ja/plugin/dev/migration"
+ ]
+ },
+ {
+ "group": "プラグイン SDK API",
+ "pages": [
+ "ja/plugin/dev/apis/agent-run",
+ "ja/plugin/dev/apis/common",
+ "ja/plugin/dev/apis/llm-requests",
+ "ja/plugin/dev/apis/platform",
+ "ja/plugin/dev/apis/pipeline-events",
+ "ja/plugin/dev/apis/messages",
+ "ja/plugin/dev/apis/tech-details"
+ ]
+ },
+ {
+ "group": "コア開発",
+ "pages": [
+ "ja/develop/agent-context",
+ "ja/develop/dev-config",
+ "ja/develop/plugin-runtime",
+ "ja/develop/comp-arch",
+ "ja/workshop/impl-platform-adapter"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "記事",
+ "groups": [
+ {
+ "group": "一覧",
+ "pages": [
+ "ja/articles/index"
+ ]
+ },
+ {
+ "group": "製品アップデート",
+ "pages": [
+ "ja/articles/langbot-cloud-multi-user-workspaces"
+ ]
+ },
+ {
+ "group": "エンジニアリング",
+ "pages": [
+ "ja/articles/langbot-v4100-sandbox-skills",
+ "ja/articles/langbot-v490-rag-plugin-architecture",
+ "ja/articles/langbot-plugin-system-deep-dive"
+ ]
+ },
+ {
+ "group": "チュートリアルと連携",
+ "pages": [
+ "ja/articles/langtars-remote-pc-control-dify-n8n",
+ "ja/articles/connect-deepseek-to-wechat",
+ "ja/articles/deploy-ai-bot-in-5-minutes",
+ "ja/articles/dify-agent-discord-telegram-slack",
+ "ja/articles/langflow-drag-and-drop-ai-bot",
+ "ja/articles/n8n-multi-platform-ai-chatbot",
+ "ja/articles/dify-langbot-rag-knowledge-base"
+ ]
+ },
+ {
+ "group": "お知らせ",
+ "pages": [
+ "ja/articles/welcome"
+ ]
+ }
+ ]
+ },
+ {
+ "tab": "API リファレンス",
+ "groups": [
+ {
+ "group": "Service API",
+ "pages": [
+ "ja/tags/readme",
+ "ja/tags/webhook"
+ ]
+ },
+ {
+ "group": "HTTP API Reference",
+ "openapi": {
+ "source": "openapi/service-api-ja.json",
+ "directory": "ja/api-reference"
+ }
+ }
+ ]
+ }
+ ],
+ "navbar": {
+ "links": [
+ {
+ "label": "クラウド",
+ "href": "https://space.langbot.app/cloud?language=ja",
+ "icon": "cloud"
+ },
+ {
+ "label": "拡張機能",
+ "href": "https://space.langbot.app/market?language=ja",
+ "icon": "blocks"
+ },
+ {
+ "label": "ブログ",
+ "href": "https://langbot.app/ja/blog",
+ "icon": "newspaper"
+ },
+ {
+ "label": "ロードマップ",
+ "href": "https://langbot.app/ja/roadmap",
+ "icon": "map"
+ }
+ ],
+ "primary": {
+ "type": "button",
+ "label": "GitHub",
+ "href": "https://github.com/langbot-app/LangBot",
+ "icon": "github"
+ }
+ }
+ }
+ ]
+ },
+ "fonts": {
+ "family": "Source Sans Pro"
+ },
+ "metadata": {
+ "google-site-verification": "LBNmWbXCAXdoqrbwg5Gep-xzQ7u7lJHSdpR49N3Ttgg"
+ }
+}
diff --git a/docs/en/articles/connect-deepseek-to-wechat.mdx b/docs/en/articles/connect-deepseek-to-wechat.mdx
new file mode 100644
index 000000000..bdf750316
--- /dev/null
+++ b/docs/en/articles/connect-deepseek-to-wechat.mdx
@@ -0,0 +1,103 @@
+---
+title: "How to Connect DeepSeek R1 to WeChat, Discord & Telegram in 5 Minutes (FREE)"
+description: "A step-by-step guide to connecting DeepSeek R1/V3 API to WeChat (Personal/Enterprise), Discord, Telegram, and more using LangBot. No coding required."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/connect-deepseek-to-wechat).
+
+Published 2026-02-21 · Author: LangBot Team
+
+
+
+DeepSeek has taken the AI world by storm. Its R1 reasoning model rivals OpenAI's o1 but is open-source and significantly cheaper.
+
+However, the official DeepSeek app currently only supports "AI Search" in WeChat, and direct integration into group chats or private workflows is limited.
+
+**What if you could have a fully functional DeepSeek R1 bot in your WeChat groups, Discord servers, and Telegram chats right now?**
+
+With **LangBot**, you can. And it takes less than 5 minutes.
+
+## Why LangBot?
+
+LangBot is an open-source, production-grade IM bot platform. Unlike simple scripts or single-platform bots, LangBot gives you:
+
+* **Unified Platform:** Connect once, deploy to WeChat, Discord, Telegram, Slack, Lark, and more.
+* **Model Agnostic:** Use DeepSeek R1, V3, Claude 3.5, GPT-4, or local Ollama models.
+* **No Coding:** robust WebUI for configuration.
+* **Enterprise Features:** Knowledge base (RAG), Plugin system, and multi-user management.
+
+## Prerequisites
+
+1. **A Server or PC:** Docker installed (VPS, local computer, or Synology/NAS).
+2. **DeepSeek API Key:**
+ * **Official:** [platform.deepseek.com](https://platform.deepseek.com)
+ * **SiliconFlow (Recommended for speed):** [cloud.siliconflow.cn](https://cloud.siliconflow.cn) (Faster R1 inference).
+
+## Step 1: Deploy LangBot
+
+If you haven't deployed LangBot yet, run this one command:
+
+```bash
+git clone https://github.com/langbot-app/LangBot
+cd LangBot/docker
+docker compose up -d
+```
+
+Access your dashboard at `http://localhost:5300` (or your server IP).
+
+## Step 2: Configure DeepSeek Model
+
+1. Go to **Models** -> **Provider List**.
+2. Find **DeepSeek** (or **SiliconFlow** / **OpenAI Compatible**).
+3. Enter your API Key.
+4. Click **Save**.
+
+Now create a **Model Instance**:
+* **Name:** `DeepSeek-R1-Bot`
+* **Model:** `deepseek-reasoner` (for R1) or `deepseek-chat` (for V3).
+
+## Step 3: Create a Chat Pipeline
+
+LangBot uses "Pipelines" to manage bot logic.
+
+1. Go to **Pipelines** -> **New Pipeline**.
+2. Choose **Chat Pipeline**.
+3. Select your `DeepSeek-R1-Bot` model.
+4. (Optional) Add a System Prompt:
+ > "You are a helpful assistant powered by DeepSeek R1. You think deeply before answering."
+
+## Step 4: Connect to WeChat (or any platform)
+
+### For WeChat (Personal / Wechaty)
+*Note: Personal WeChat access relies on third-party libraries and carries some risk. For business use, we recommend Enterprise WeChat (WeCom).*
+
+1. Go to **Bots** -> **New Bot**.
+2. Select **WeChat**.
+3. Choose the **GeweChat** or **Wechaty** adapter (depending on your preference).
+4. Click **Save**.
+5. Scan the QR code that appears in the logs or UI.
+
+### For Discord / Telegram
+1. Select **Discord** or **Telegram**.
+2. Paste your **Bot Token** (from Discord Developer Portal or BotFather).
+3. Click **Save**.
+
+## Step 5: Test It Out!
+
+Open your chat app and send a message. You should see DeepSeek R1 "thinking" (if supported) and replying with high-quality reasoning.
+
+## Advanced: Using Search & Tools
+
+DeepSeek is great, but DeepSeek with **Internet Access** is better.
+
+In LangBot:
+1. Go to **Plugins**.
+2. Install **Tavily Search** or **Google Search**.
+3. Add the plugin to your DeepSeek Pipeline.
+
+Now your bot can search the web for real-time info *before* reasoning with DeepSeek R1!
+
+---
+
+**Ready to build?**
+[Star us on GitHub](https://github.com/langbot-app/LangBot) or [Read the Docs](https://langbot.app/docs).
diff --git a/docs/en/articles/deploy-ai-bot-in-5-minutes.mdx b/docs/en/articles/deploy-ai-bot-in-5-minutes.mdx
new file mode 100644
index 000000000..e8fa891a4
--- /dev/null
+++ b/docs/en/articles/deploy-ai-bot-in-5-minutes.mdx
@@ -0,0 +1,170 @@
+---
+title: "Deploy Your Own AI Bot to Discord, Telegram & WeChat in 5 Minutes"
+description: "A step-by-step guide to deploying LangBot — the open-source platform that connects 20+ LLMs to 13+ messaging platforms with a single Docker command."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/deploy-ai-bot-in-5-minutes).
+
+Published 2026-02-17 · Author: LangBot Team
+
+
+
+What if you could have GPT-5, Claude, DeepSeek, and Gemini all answering questions in your Discord server, Telegram group, and WeChat — at the same time?
+
+No API wrangling. No weeks of development. Just one Docker command.
+
+That's **LangBot** — and it just crossed **15,000 stars** on GitHub.
+
+## The Problem Everyone Faces
+
+You want an AI assistant in your team's chat. Maybe for customer support on Telegram. Maybe for a coding helper in Discord. Maybe for a knowledge base bot in your company's WeChat or Lark group.
+
+But then reality hits:
+
+- Each platform has its own bot API, webhook format, and auth flow
+- You need to handle message queuing, session management, and error recovery
+- Switching LLM providers means rewriting your integration layer
+- Adding RAG or tool calling is yet another project
+
+LangBot solves all of this with a single, unified platform.
+
+## What Makes LangBot Different
+
+### 13+ Messaging Platforms, One Codebase
+
+Deploy a single LangBot instance and connect it to:
+
+**Global:** Discord, Telegram, Slack, LINE, WhatsApp
+**Asia:** WeChat (Official Account), WeCom, QQ, Lark, DingTalk, Feishu, KOOK
+
+Each platform gets its own adapter — you just fill in your bot token in the WebUI and you're live.
+
+
+
+### 20+ LLM Models, Zero Lock-in
+
+Through **LangBot Space**, you get instant access to 20 cloud models out of the box — no API keys to manage:
+
+- **Claude** (Opus 4.6, Sonnet 4.5, Haiku 4.5)
+- **GPT** (GPT-5.2, GPT-5-mini, GPT-4.1-mini)
+- **Gemini** (3 Pro, 2.5 Pro, 2.5 Flash)
+- **DeepSeek** (R1, V3)
+- **Grok** (4, 4.1)
+- **Qwen** (3 Max)
+
+Or add your own providers — OpenAI-compatible endpoints, Ollama for local models, any provider you want.
+
+
+
+### Built-in Agent with Tool Calling
+
+LangBot's Local Agent isn't just a chat wrapper — it's a full agent runtime:
+
+- **Multi-round conversations** with configurable memory
+- **Function calling / tool use** for LLM-driven actions
+- **MCP (Model Context Protocol)** support for connecting to 100+ pre-built tools
+- **Knowledge base (RAG)** with built-in vector search
+
+
+
+### Plugin Marketplace
+
+37+ community plugins and growing — install with one click:
+
+- **WebSearch** — Let your bot search the web
+- **AI Image Generator** — Generate images from text
+- **LinkAnaly** — Auto-preview links in chat
+- **ScheNotify** — Schedule reminders with natural language
+- **Google Search**, **Tavily Search**, **RAGFlow Retriever**, and more
+
+
+
+## Deploy in 5 Minutes — For Real
+
+### Step 1: Run Docker Compose
+
+```bash
+git clone https://github.com/langbot-app/LangBot
+cd LangBot/docker
+docker compose up -d
+```
+
+That's it. LangBot is now running at `http://localhost:5300`.
+
+### Step 2: Initialize with LangBot Space
+
+Open the WebUI and click **"Initialize with Space"**. This connects your instance to LangBot Space, giving you:
+
+- 20 cloud models ready to use (with free credits)
+- One-click plugin installation
+- Managed API keys
+
+
+
+### Step 3: Configure Your Pipeline
+
+Go to **Pipelines** and edit the default `ChatPipeline`:
+
+1. Select your model (e.g., `deepseek-v3`, `gpt-5-mini`, `claude-sonnet-4-5`)
+2. Customize the system prompt
+3. Optionally attach a knowledge base or enable tools
+
+
+
+### Step 4: Connect a Platform
+
+Go to **Bots** → click **+** → choose your platform (Discord, Telegram, etc.) → enter your bot token.
+
+Done. Your bot is live.
+
+### Step 5: Test It
+
+Use the built-in **Debug Chat** to test your pipeline before going live:
+
+
+
+## Real Conversations, Real Value
+
+Here's what it looks like when LangBot is running in a QQ group — users asking technical questions and getting instant, accurate answers:
+
+
+
+And in private chat:
+
+
+
+## Architecture That Scales
+
+LangBot is built for production:
+
+- **Pipeline architecture** — each bot binds to a pipeline; pipelines handle AI logic, triggers, safety controls, and output formatting
+- **Cross-process plugin isolation** — a bad plugin can't crash your bot
+- **Multiple runner backends** — use LangBot's Local Agent, or connect to Dify, n8n, Langflow, Coze for complex workflows
+- **Database flexibility** — SQLite for dev, PostgreSQL for production
+- **Vector DB options** — Chroma, Qdrant, Milvus, pgvector, SeekDB
+
+## Why 15,000+ Developers Choose LangBot
+
+| Feature | LangBot | Building from Scratch |
+|---------|---------|----------------------|
+| Platforms | 13+ ready | Weeks per platform |
+| LLM Providers | 20+ models | Manual integration |
+| Agent Runtime | Built-in | Build your own |
+| RAG | Native + external | Separate project |
+| Plugin System | Marketplace | DIY |
+| Deployment | `docker compose up` | Days of setup |
+| WebUI | Included | Build your own |
+
+## Get Started
+
+- **GitHub:** [github.com/langbot-app/LangBot](https://github.com/langbot-app/LangBot) — give us a star!
+- **Documentation:** [langbot.app/docs](https://langbot.app/docs)
+- **Plugin Market:** [space.langbot.app](https://space.langbot.app)
+
+```bash
+git clone https://github.com/langbot-app/LangBot
+cd LangBot/docker
+docker compose up -d
+```
+
+Your AI bot empire starts with one command.
diff --git a/docs/en/articles/dify-agent-discord-telegram-slack.mdx b/docs/en/articles/dify-agent-discord-telegram-slack.mdx
new file mode 100644
index 000000000..85fa8a315
--- /dev/null
+++ b/docs/en/articles/dify-agent-discord-telegram-slack.mdx
@@ -0,0 +1,115 @@
+---
+title: "Finally Got My Dify Agent Working in Discord, Telegram and Slack"
+description: "Finally Got My Dify Agent Working in Discord, Telegram and Slack"
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/dify-agent-discord-telegram-slack).
+
+Published 2025-12-11 · Author: LangBot Team
+
+
+
+Want your Dify Agent to break free from the browser and chat directly in WeChat, QQ, or Telegram? Combine LangBot with Dify and you can set it up in under 10 minutes.
+
+## Why This Combo?
+
+[**LangBot**](https://github.com/langbot-app/LangBot) is the most powerful open-source multi-platform chatbot framework available. It supports major Chinese IMs (QQ, WeChat, Feishu, DingTalk) and international platforms (Telegram, Discord, Slack, LINE). Its core strength is connecting AI backends to messaging apps.
+
+**Dify** is one of the hottest AI app development platforms, offering visual Agent orchestration, 50+ built-in tools, and RAG knowledge bases. Together, they let you build a multi-platform AI assistant fast.
+
+## Deploy LangBot
+
+Three commands with uvx:
+
+```bash
+mkdir langbot-instance
+cd langbot-instance
+uvx langbot@latest
+```
+
+Visit `http://127.0.0.1:5300` and register an admin account:
+
+
+
+## Create a Dify Agent
+
+Log in to [cloud.dify.ai](https://cloud.dify.ai) and create a new app. Choose **Agent** type - unlike basic chat apps, Agents can reason autonomously and call tools for complex tasks.
+
+
+
+### Configure the Agent
+
+In the orchestration interface, set up:
+
+**System Instructions** - Define the Agent's role:
+
+```
+You are an intelligent assistant that helps users complete various tasks. You have the following capabilities:
+1. Answer various user questions
+2. Query weather information
+3. Retrieve webpage content
+
+Please always maintain a friendly and professional attitude. If you need to use tools to get information, proactively call the relevant tools.
+```
+
+**Add Tools** - Pick from Dify's 50+ built-in tools, like Weather and Web Scraper:
+
+
+
+**Select Model** - Supports GPT, Claude, Gemini, DeepSeek, and other major LLMs.
+
+Final configuration:
+
+
+
+### Get the API Key
+
+Click "Publish", then go to "Access API" to create a key:
+
+
+
+Save the API key and server address `https://api.dify.ai/v1`.
+
+## Connect Dify to LangBot
+
+Back in LangBot, go to Pipelines > ChatPipeline > AI Capability:
+
+
+
+Select **Dify Service API** as the Runner:
+
+
+
+Enter the configuration:
+- **Base URL**: `https://api.dify.ai/v1`
+- **API Key**: The key you just created
+- **App Type**: Chat (including Chatflow)
+
+
+
+Save and click "Debug Conversation" to test:
+
+
+
+If the Agent responds correctly and calls tools, the integration is working.
+
+## Why This Architecture Rocks
+
+- **Decoupled Design**: Agent capabilities live in Dify, LangBot handles message routing - each does what it's best at
+- **One Config, Multi-Platform**: Same Agent serves QQ, WeChat, Telegram, and more simultaneously
+- **Easy to Extend**: Add RAG knowledge bases, Workflow orchestration, or more tools in Dify later
+
+## Next Steps
+
+- Configure messaging platforms in LangBot (QQ bot, WeChat personal account, etc.)
+- Add more tools in Dify (database queries, API calls)
+- Try Dify Chatflow for complex conversation flows
+
+If you're using n8n, FastGPT, Coze, or Langflow, LangBot supports those too.
+
+---
+
+**Resources**
+
+- [LangBot Docs](https://langbot.app/docs) | [GitHub](https://github.com/langbot-app/LangBot)
+- [Dify Docs](https://docs.dify.ai) | [Cloud Platform](https://cloud.dify.ai)
diff --git a/docs/en/articles/dify-langbot-rag-knowledge-base.mdx b/docs/en/articles/dify-langbot-rag-knowledge-base.mdx
new file mode 100644
index 000000000..f149422c4
--- /dev/null
+++ b/docs/en/articles/dify-langbot-rag-knowledge-base.mdx
@@ -0,0 +1,204 @@
+---
+title: "LangBot 4.6.0 External Knowledge Base Tutorial: Integrating Dify with LangBot for RAG-powered Conversations"
+description: "LangBot 4.6.0 External Knowledge Base Tutorial: Integrating Dify with LangBot for RAG-powered Conversations"
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/dify-langbot-rag-knowledge-base).
+
+Published 2025-12-02 · Author: LangBot Team
+
+
+
+LangBot 4.6.0 introduces external knowledge base functionality, allowing users to integrate external knowledge retrieval services such as Dify and RAGFlow into conversation pipelines. This tutorial demonstrates how to combine Dify knowledge base with LangBot to enable intelligent conversations based on domain-specific knowledge.
+
+## Feature Overview
+
+The external knowledge base feature enables LangBot to:
+- Connect to various external knowledge retrieval services (Dify, RAGFlow, etc.)
+- Provide professional answers based on domain-specific knowledge
+- Flexibly extend knowledge retrieval capabilities through the plugin system
+- Configure conveniently through WebUI without manual configuration file editing
+
+## Prerequisites
+
+Before starting, you need:
+1. Deploy LangBot 4.6.0 or higher
+2. Have a Dify account (register at https://cloud.dify.ai)
+3. Configure a conversation model (this tutorial uses claude-opus-4-1-20250805)
+
+## Step 1: Deploy LangBot
+
+### 1.1 View LangBot Repository
+
+First, visit the [LangBot GitHub repository](https://github.com/langbot-app/LangBot) to understand the project. LangBot is a production-grade instant messaging bot development platform supporting multiple messaging platforms and LLM services.
+
+### 1.2 Learn About External Knowledge Base Feature
+
+Visit the [official LangBot documentation](https://langbot.app/docs) to view the external knowledge base usage instructions. The documentation provides detailed explanations on how to build built-in knowledge bases and connect to external knowledge bases.
+
+### 1.3 Start LangBot
+
+Use the `uvx langbot` command to quickly start LangBot, then visit http://127.0.0.1:5300 for initialization. Fill in your email and password to complete registration, then log in.
+
+### 1.4 Dashboard After Login
+
+After successfully logging in, you will see the LangBot WebUI dashboard.
+
+## Step 2: Configure Conversation Model
+
+Before using the knowledge base, you need to configure a conversation model.
+
+### 2.1 Navigate to Model Configuration Page
+
+Click "Models" in the left navigation bar to enter the model configuration page.
+
+### 2.2 Add New Model
+
+Click the "+" button to open the model configuration dialog.
+
+### 2.3 Fill in Model Information
+
+Fill in the following information:
+- **Model Name**: claude-opus-4-1-20250805
+- **Model Provider**: New API
+- **Request URL**: Your API endpoint
+- **API Key**: Your API Key
+- **Abilities**: Check Vision Ability and Function Call
+
+Click "Submit" to save the configuration.
+
+## Step 3: Create Knowledge Base in Dify
+
+### 3.1 Log in to Dify Platform
+
+Visit https://cloud.dify.ai and log in to your account.
+
+### 3.2 Navigate to Knowledge Page
+
+Click "Knowledge" in the top navigation bar to enter the knowledge base management page.
+
+### 3.3 Create New Knowledge Base
+
+Click "Create Knowledge" to start creating a knowledge base.
+
+### 3.4 Select Data Source
+
+You can choose from the following methods to import data:
+- **Import from file**: Upload document files
+- **Sync from Notion**: Sync from Notion
+- **Sync from website**: Crawl website content
+
+This tutorial selects "Import from file" and uploads prepared LangBot documentation.
+
+### 3.5 Upload Document
+
+After uploading the document, the system will display file information. Click "Next" to proceed.
+
+### 3.6 Configure Document Processing Parameters
+
+On the document processing page, you can configure chunk settings, index method, and retrieval settings:
+- **Chunk Settings**: General mode, maximum chunk length 1024 characters
+- **Index Method**: High Quality (uses embedding model)
+- **Retrieval Setting**: Vector Search
+
+Click "Save & Process" to start processing the document.
+
+### 3.7 Knowledge Base Processing
+
+The system starts processing the document and generating vector embeddings.
+
+### 3.8 Embedding Completed
+
+After processing is complete, the knowledge base is ready to use.
+
+## Step 4: Get Dify API Information
+
+### 4.1 Open Service API Panel
+
+Click the "Service API" button in the bottom right. Record the following information:
+- **Service API Endpoint**: https://api.dify.ai/v1
+- **Dataset ID**: Get from the URL
+
+### 4.2 Get API Key
+
+Click the "API Key" button to view the API key. Record your API Key for use in subsequent configuration.
+
+## Step 5: Configure External Knowledge Base in LangBot
+
+### 5.1 Navigate to Knowledge Page
+
+In the LangBot WebUI, click "Knowledge" in the left navigation bar.
+
+### 5.2 Switch to External Knowledge Base Tab
+
+Click the "External" tab.
+
+### 5.3 Add External Knowledge Base
+
+Click the "+" button to open the add external knowledge base dialog. In this dialog, you need to:
+1. **Knowledge Base Name**: Give the knowledge base a name
+2. **Knowledge Base Description**: Add a description (optional)
+3. **Retriever**: Select a knowledge retriever plugin
+
+**Note**: Using an external knowledge base requires installing the corresponding knowledge retriever plugin first. You can search for and install the Dify knowledge retriever plugin in the [plugin marketplace](https://space.langbot.app/market?category=KnowledgeRetriever).
+
+After installing the plugin, select the corresponding plugin from the Retriever dropdown, then fill in the configuration information obtained from Dify (API Endpoint, API Key, Dataset ID).
+
+## Step 6: Configure Pipeline
+
+After configuring the external knowledge base, you need to enable it in the pipeline:
+
+1. Navigate to the "Pipelines" page
+2. Edit or create a new pipeline
+3. On the "AI Capabilities" page, select "Built-in Agent" as the runner
+4. In the knowledge base selection, check the external knowledge base you just configured
+5. Save the pipeline configuration
+
+## Step 7: Test the Effect
+
+Test in the pipeline's "Conversation Testing" page, or bind the pipeline to a bot for actual conversation testing. When users ask questions, LangBot will automatically retrieve relevant content from the Dify knowledge base and generate answers combined with the retrieved knowledge.
+
+## Frequently Asked Questions
+
+### 1. How to Install Knowledge Retriever Plugins?
+
+Visit the [LangBot plugin marketplace](https://space.langbot.app/market), search for "Knowledge Retriever" or "Dify", find the corresponding plugin and click install.
+
+### 2. Which External Knowledge Retrieval Services Are Supported?
+
+LangBot currently supports multiple external knowledge retrieval services through the plugin system, including:
+- Dify
+- RAGFlow
+- Other custom knowledge retrieval services
+
+Specific supported services can be viewed in the plugin marketplace.
+
+### 3. What's the Difference Between External and Built-in Knowledge Bases?
+
+- **Built-in Knowledge Base**: Data is stored locally in LangBot, with LangBot handling vectorization and retrieval
+- **External Knowledge Base**: Data is stored in external services (like Dify), with retrieval performed through API calls
+
+The advantage of external knowledge bases is the ability to leverage the capabilities of professional LLMOps platforms, such as Dify's advanced document processing and multiple retrieval strategies.
+
+### 4. Can Multiple Knowledge Bases Be Used Simultaneously?
+
+Yes. In the pipeline configuration, you can check multiple knowledge bases (built-in or external) simultaneously, and LangBot will comprehensively utilize the content from these knowledge bases to generate answers.
+
+## Summary
+
+Through this tutorial, you learned how to:
+1. Create a knowledge base and upload documents on the Dify platform
+2. Obtain Dify API key and related configuration information
+3. Configure a conversation model in LangBot
+4. Add an external knowledge base in LangBot
+5. Configure pipelines to use external knowledge bases
+
+The external knowledge base feature provides LangBot with more powerful and flexible knowledge management capabilities. Combined with professional LLMOps platforms like Dify, you can build more intelligent and professional conversational bots.
+
+## Related Resources
+
+- [LangBot Official Website](https://langbot.app)
+- [LangBot Documentation](https://langbot.app/docs)
+- [LangBot GitHub](https://github.com/langbot-app/LangBot)
+- [Dify Official Website](https://dify.ai)
+- [LangBot Plugin Marketplace](https://space.langbot.app/market)
diff --git a/docs/en/articles/index.mdx b/docs/en/articles/index.mdx
new file mode 100644
index 000000000..a06650975
--- /dev/null
+++ b/docs/en/articles/index.mdx
@@ -0,0 +1,30 @@
+---
+title: "LangBot Articles"
+description: "Product updates, engineering deep dives, tutorials, integrations, and announcements from the LangBot Blog."
+---
+
+Product updates, engineering deep dives, tutorials, integrations, and announcements from the LangBot Blog.
+
+## Product Updates
+
+- [The new LangBot Cloud is here — and multi-user Workspaces are now in open source](/en/articles/langbot-cloud-multi-user-workspaces) — 2026-08-25
+
+## Engineering
+
+- [LangBot v4.10.0: Agentic Sandbox & Skills — Letting Your Agent Work Like a Developer](/en/articles/langbot-v4100-sandbox-skills) — 2026-06-04
+- [LangBot v4.9.0: Full RAG Plugin Architecture — Knowledge Without Borders](/en/articles/langbot-v490-rag-plugin-architecture) — 2026-03-10
+- [Deep Dive into the LangBot Plugin System: Process Isolation, Event-Driven Hooks, and Component Architecture](/en/articles/langbot-plugin-system-deep-dive) — 2026-02-23
+
+## Tutorials & Integrations
+
+- [LangTARS: Open-Source AI Agent for Remote PC Control — Works with Dify, n8n & 10+ Messaging Platforms](/en/articles/langtars-remote-pc-control-dify-n8n) — 2026-03-23
+- [How to Connect DeepSeek R1 to WeChat, Discord & Telegram in 5 Minutes (FREE)](/en/articles/connect-deepseek-to-wechat) — 2026-02-21
+- [Deploy Your Own AI Bot to Discord, Telegram & WeChat in 5 Minutes](/en/articles/deploy-ai-bot-in-5-minutes) — 2026-02-17
+- [Finally Got My Dify Agent Working in Discord, Telegram and Slack](/en/articles/dify-agent-discord-telegram-slack) — 2025-12-11
+- [How I Built a Multi-Platform AI Bot with Langflow's Drag-and-Drop Workflows](/en/articles/langflow-drag-and-drop-ai-bot) — 2025-12-05
+- [How I Built a Multi-Platform AI Chatbot with n8n and LangBot](/en/articles/n8n-multi-platform-ai-chatbot) — 2025-12-03
+- [LangBot 4.6.0 External Knowledge Base Tutorial: Integrating Dify with LangBot for RAG-powered Conversations](/en/articles/dify-langbot-rag-knowledge-base) — 2025-12-02
+
+## Announcements
+
+- [Introducing the LangBot Blog](/en/articles/welcome) — 2026-02-17
diff --git a/docs/en/articles/langbot-cloud-multi-user-workspaces.mdx b/docs/en/articles/langbot-cloud-multi-user-workspaces.mdx
new file mode 100644
index 000000000..b7a0e2c1f
--- /dev/null
+++ b/docs/en/articles/langbot-cloud-multi-user-workspaces.mdx
@@ -0,0 +1,68 @@
+---
+title: "The new LangBot Cloud is here — and multi-user Workspaces are now in open source"
+description: "LangBot is an open-source AI bot platform connecting LLMs with messaging apps. The new Cloud and open-source editions now support multi-user Workspaces, invitations, and role-based access."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langbot-cloud-multi-user-workspaces).
+
+Published 2026-08-25 · Author: LangBot Team
+
+
+
+The new [LangBot Cloud](https://cloud.langbot.app) is live. This release tackles a practical question: when a team uses LangBot together, who can access which resources?
+
+The same multi-user foundation is now available in the open-source edition. Cloud and self-hosted LangBot still have different operating models, but they share the same basic approach to members, invitations, and permissions.
+
+## What is LangBot?
+
+LangBot is an open-source platform for building and operating AI bots across messaging apps. A single dashboard manages bots, message pipelines, knowledge bases, models, and extensions, then connects them to Discord, Telegram, Slack, LINE, QQ, WeChat, WeCom, Lark, DingTalk, and KOOK. LangBot also supports Satori and Matrix; Matrix bridges can extend a deployment to networks such as WhatsApp, Signal, Messenger, Mattermost, Google Chat, IRC, XMPP, and Zulip.
+
+The model layer is provider-neutral. LangBot connects to OpenAI, Anthropic Claude, DeepSeek, Google Gemini, xAI Grok, Moonshot Kimi, and Zhipu GLM, while Ollama and LM Studio cover local models. Gateway options include SiliconFlow, Aliyun Bailian, Volcengine Ark, ModelScope, and GiteeAI. Existing agent workflows can also be connected through Dify and MCP.
+
+A team can therefore run AI assistants on several messaging platforms from one place and choose a hosted model, a local model, or an existing agent workflow for each use case.
+
+
+
+## Cloud: start in your own Workspace
+
+LangBot Cloud now uses LangBot Account for sign-in. New users start with a personal Workspace and can accept invitations to join team Workspaces. If an account belongs to several Workspaces, the current one can be switched from the interface.
+
+Bots, pipelines, models, knowledge bases, and extensions belong to the active Workspace. Switching Workspaces does not mix one team's configuration or data with another's.
+
+Cloud continues to provide the hosting, updates, and runtime environment. It is the simpler option for teams that want to configure a bot without maintaining a server first.
+
+## Invite people instead of sharing an admin account
+
+An Owner, or another role with member-management permission, can send a one-time invitation. The recipient accepts it with their own account and enters the Workspace with the assigned role.
+
+
+
+That is a better long-term setup than sharing one administrator password: each person has an identity, and access can match the work they actually do.
+
+Five fixed roles are available today:
+
+- **Owner** — owns the Workspace and its highest-level membership controls.
+- **Admin** — manages members and most Workspace settings.
+- **Developer** — configures bots, pipelines, models, and extensions.
+- **Operator** — handles day-to-day operations.
+- **Viewer** — read-only access.
+
+## Open source: one instance, one Workspace, multiple users
+
+The self-hosted edition is not turning into a multi-Workspace SaaS. One LangBot instance still has one Workspace, but that Workspace can now include several users.
+
+The account created during initialization becomes the Owner. It can invite other people later. When SMTP is configured, LangBot can deliver the invitation by email; otherwise it shows a one-time link that can be shared through a trusted channel.
+
+Members still use the familiar LangBot dashboard. The difference is that resource access is checked against both the Workspace and the member's role, rather than treating every signed-in user as a full administrator.
+
+## Which edition should you use?
+
+| | LangBot Cloud | Open-source self-hosted |
+|---|---|---|
+| Deployment | Hosted and maintained by LangBot | You operate the server and data |
+| Workspaces | Own or join multiple | One per instance |
+| Members and invitations | Included | Included |
+| Fixed role-based access | Included | Included |
+| Best for | Getting a team running quickly | Private deployment and infrastructure control |
+
+To start with the hosted edition, visit [cloud.langbot.app](https://cloud.langbot.app). To keep the runtime and data on your own infrastructure, deploy LangBot from [GitHub](https://github.com/langbot-app/LangBot).
diff --git a/docs/en/articles/langbot-plugin-system-deep-dive.mdx b/docs/en/articles/langbot-plugin-system-deep-dive.mdx
new file mode 100644
index 000000000..94a632428
--- /dev/null
+++ b/docs/en/articles/langbot-plugin-system-deep-dive.mdx
@@ -0,0 +1,459 @@
+---
+title: "Deep Dive into the LangBot Plugin System: Process Isolation, Event-Driven Hooks, and Component Architecture"
+description: "A source-level deep dive into LangBot 4.0's plugin architecture — process-isolated communication, event-driven hooks, a component-based extension model, and comparisons with Dify and MCP."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langbot-plugin-system-deep-dive).
+
+Published 2026-02-23 · Author: LangBot Team
+
+
+
+Most chatbot frameworks call their "plugin system" a glorified dynamic import of Python modules. LangBot 4.0 takes a harder but more principled approach — **every plugin runs in its own process**, communicating with the host through a structured JSON-RPC-style protocol.
+
+This article dissects the system from source code, end to end.
+
+## Overall Architecture: A Three-Layer Process Model
+
+LangBot's plugin system consists of three cooperating process layers:
+
+
+
+**Each layer has a distinct responsibility:**
+
+1. **LangBot Main Process**: Runs business logic (message pipelines, platform adapters, model invocations), connects to Runtime via `PluginRuntimeConnector`.
+2. **Plugin Runtime**: The orchestration layer — discovers, launches, and manages all plugin subprocesses, routes requests from the main process to the appropriate plugin.
+3. **Plugin Subprocesses**: Each plugin runs in its own Python process, communicating with Runtime via stdio pipes.
+
+### Why Three Layers Instead of Two?
+
+The intuitive design would have the main process manage plugin processes directly. LangBot adds the Runtime layer for **deployment flexibility**:
+
+- **Local development**: Main process spawns Runtime as a child via stdio (zero config)
+- **Docker production**: Runtime runs as a separate container, connected via WebSocket
+- **Windows compatibility**: Since Windows asyncio has incomplete stdio subprocess support, it automatically falls back to WebSocket
+
+The same codebase — no config changes — adapts from development to production.
+
+## Communication Protocol: JSON-RPC-Style Request/Response
+
+All cross-process communication runs on a unified protocol layer. The core data structures are minimal:
+
+```python
+# Request
+class ActionRequest(pydantic.BaseModel):
+ seq_id: int # Sequence number for matching request/response
+ action: str # Action name
+ data: dict # Payload
+
+# Response
+class ActionResponse(pydantic.BaseModel):
+ seq_id: int
+ code: int # 0 = success
+ message: str
+ data: dict
+ chunk_status: str # "continue" | "end" (streaming support)
+```
+
+The `Handler` class is the system's core abstraction, acting as both RPC client and server:
+
+```python
+class Handler:
+ async def call_action(self, action, data, timeout=15.0) -> dict:
+ """Actively call an action provided by the peer, wait for response"""
+ self.seq_id_index += 1
+ request = ActionRequest.make_request(self.seq_id_index, action.value, data)
+ future = asyncio.Future()
+ self.resp_waiters[self.seq_id_index] = future
+ await self.conn.send(json.dumps(request.model_dump()))
+ response = await asyncio.wait_for(future, timeout)
+ return response.data
+
+ @action(SomeAction.DO_SOMETHING)
+ async def handle_something(data: dict) -> ActionResponse:
+ """Register an action for the peer to call"""
+ return ActionResponse.success({"result": "ok"})
+```
+
+**Key design points:**
+
+- `seq_id`-based request/response matching enables full-duplex concurrent calls
+- Streaming responses via `chunk_status` for long-running operations like command execution
+- Large messages auto-chunk (stdio: 16KB / WebSocket: 64KB per chunk)
+- File transfer uses a separate base64 chunking mechanism
+
+### Action Enums: Clear API Contracts
+
+The system defines all cross-process calls through four enum groups:
+
+```python
+# Plugin → Runtime (plugin-initiated requests)
+class PluginToRuntimeAction:
+ REGISTER_PLUGIN = "register_plugin"
+ SEND_MESSAGE = "send_message" # Send message to a platform
+ INVOKE_LLM = "invoke_llm" # Call an LLM
+ SET_PLUGIN_STORAGE = "set_plugin_storage" # Persistent storage
+ # ...
+
+# Runtime → Plugin (runtime-dispatched commands)
+class RuntimeToPluginAction:
+ INITIALIZE_PLUGIN = "initialize_plugin"
+ EMIT_EVENT = "emit_event"
+ CALL_TOOL = "call_tool"
+ EXECUTE_COMMAND = "execute_command"
+ SHUTDOWN = "shutdown"
+ # ...
+
+# LangBot Main → Runtime
+class LangBotToRuntimeAction:
+ INSTALL_PLUGIN = "install_plugin"
+ EMIT_EVENT = "emit_event"
+ LIST_TOOLS = "list_tools"
+ # ...
+
+# Runtime → LangBot Main
+class RuntimeToLangBotAction:
+ GET_PLUGIN_SETTINGS = "get_plugin_settings"
+ SET_BINARY_STORAGE = "set_binary_storage"
+ # ...
+```
+
+This makes API boundaries crystal clear — what a plugin can and cannot do is defined entirely by these enums.
+
+## Plugin Lifecycle
+
+A plugin goes through these stages from installation to execution:
+
+### 1. Discovery
+
+On startup, Runtime scans the `data/plugins/` directory:
+
+```python
+async def launch_all_plugins(self):
+ for plugin_path in glob.glob("data/plugins/*"):
+ if not os.path.isdir(plugin_path):
+ continue
+ task = self.launch_plugin(plugin_path)
+ self.plugin_run_tasks.append(task)
+```
+
+Directory names follow the `{author}__{name}` convention, each containing a `manifest.yaml` and plugin code.
+
+### 2. Launch
+
+Runtime spawns an independent subprocess for each plugin:
+
+```python
+async def launch_plugin(self, plugin_path: str):
+ python_path = sys.executable
+ args = ["-m", "langbot_plugin.cli.__init__", "run", "-s", "--prod"]
+
+ ctrl = StdioClientController(
+ command=python_path,
+ args=args,
+ working_dir=plugin_path, # Each plugin runs in its own directory
+ )
+ await ctrl.run(new_plugin_connection_callback)
+```
+
+**Key detail**: The subprocess working directory is set to the plugin's own directory — natural filesystem isolation.
+
+### 3. Registration
+
+After starting, the plugin process actively registers itself with Runtime:
+
+```python
+# Runtime-side registration handler
+async def register_plugin(self, handler, container_data, debug_plugin=False):
+ plugin_container = PluginContainer.from_dict(container_data)
+ # Fetch plugin settings from the main process
+ plugin_settings = await self.context.control_handler.call_action(
+ RuntimeToLangBotAction.GET_PLUGIN_SETTINGS, {...}
+ )
+ # Initialize the plugin (send config)
+ await handler.initialize_plugin(plugin_settings)
+ # Store the plugin container
+ self.plugins.append(plugin_container)
+```
+
+### 4. Running
+
+Once in `INITIALIZED` state, the plugin can receive events, tool calls, and command executions.
+
+### 5. Shutdown
+
+```python
+async def shutdown_plugin(self, plugin_container):
+ # 1. Notify the plugin to shut down gracefully
+ await plugin_container._runtime_plugin_handler.shutdown_plugin()
+ # 2. Close the communication connection
+ await plugin_container._runtime_plugin_handler.conn.close()
+ # 3. Kill the subprocess
+ if handler.stdio_process is not None:
+ handler.stdio_process.kill()
+ await asyncio.wait_for(handler.stdio_process.wait(), timeout=2)
+```
+
+## Component System: Four Extension Types
+
+A LangBot plugin isn't a single hook function — it's a **component container**. A single plugin can provide multiple component types simultaneously:
+
+### EventListener
+
+The most fundamental extension — listen for events in the message pipeline:
+
+```python
+from langbot_plugin.api.definition.components.common.event_listener import EventListener
+from langbot_plugin.api.entities.events import PersonNormalMessageReceived
+from langbot_plugin.api.entities.context import EventContext
+
+class MyListener(EventListener):
+ @EventListener.handler(PersonNormalMessageReceived)
+ async def on_person_message(self, ctx: EventContext):
+ event = ctx.event
+ # Modify the user message before it reaches the LLM
+ event.user_message_alter = "Answer in poetry: " + event.text_message
+
+ # Or block further processing
+ # ctx.prevent_default()
+ # ctx.prevent_postorder()
+```
+
+Supported events cover the full message lifecycle:
+
+| Event | Trigger |
+|-------|---------|
+| `PersonMessageReceived` | Any private message received |
+| `GroupMessageReceived` | Any group message received |
+| `PersonNormalMessageReceived` | Private message deemed processable |
+| `GroupNormalMessageReceived` | Group message deemed processable |
+| `NormalMessageResponded` | LLM response completed |
+| `PromptPreProcessing` | Prompt preprocessing stage |
+
+Event propagation supports two interruption modes:
+- `prevent_default()`: Skip default behavior (e.g., skip the LLM call)
+- `prevent_postorder()`: Stop subsequent plugins from running
+
+### Tool
+
+Tools for LLM Function Calling:
+
+```python
+from langbot_plugin.api.definition.components.tool.tool import Tool
+
+class WeatherTool(Tool):
+ async def call(self, params: dict, session, query_id: int) -> str:
+ city = params.get("city", "Beijing")
+ # Call weather API...
+ return f"{city}: Sunny, 25°C"
+```
+
+Tool metadata (name, description, parameter schema) is defined in a companion YAML manifest file. LangBot automatically converts this into the Function definition that LLMs understand.
+
+### Command
+
+User-triggered commands via `!command`, with subcommand support:
+
+```python
+from langbot_plugin.api.definition.components.command.command import Command
+
+class MyCommand(Command):
+ def __init__(self):
+ super().__init__()
+
+ @self.subcommand("hello", help="Say hello")
+ async def hello(self, ctx):
+ yield CommandReturn(text="Hello from plugin!")
+
+ @self.subcommand("status", help="Show status")
+ async def status(self, ctx):
+ yield CommandReturn(text="All systems operational.")
+```
+
+Command results are returned via `AsyncGenerator`, providing natural streaming output.
+
+### KnowledgeRetriever
+
+A multi-instance component for connecting external knowledge bases:
+
+```python
+from langbot_plugin.api.definition.components.knowledge_retriever.retriever import KnowledgeRetriever
+
+class MyRetriever(KnowledgeRetriever):
+ async def retrieve(self, context) -> list:
+ results = await self.search_external_db(context.query)
+ return [RetrievalResultEntry(content=r) for r in results]
+```
+
+KnowledgeRetriever is a **polymorphic component** — a single retriever class can spawn multiple instances, each with independent configuration. This allows users to connect multiple different external knowledge bases.
+
+## SDK API: What Plugins Can Do
+
+Plugins gain rich capabilities through the `LangBotAPIProxy` inherited by `BasePlugin`:
+
+```python
+class LangBotAPIProxy:
+ # Message operations
+ async def send_message(self, bot_uuid, target_type, target_id, message_chain)
+
+ # Model invocation
+ async def get_llm_models(self) -> list[str]
+ async def invoke_llm(self, model_uuid, messages, funcs=[], extra_args={})
+
+ # Persistent storage (plugin-level isolation)
+ async def set_plugin_storage(self, key, value: bytes)
+ async def get_plugin_storage(self, key) -> bytes
+
+ # Workspace storage (cross-plugin shared)
+ async def set_workspace_storage(self, key, value: bytes)
+ async def get_workspace_storage(self, key) -> bytes
+
+ # System info
+ async def get_langbot_version(self) -> str
+ async def get_bots(self) -> list[str]
+ async def list_plugins_manifest(self) -> list
+```
+
+**The storage API design is worth noting**: Two levels of KV storage — `plugin_storage` (plugin-private) and `workspace_storage` (globally shared), storing data as bytes (base64-serialized in transit). Simple but flexible enough.
+
+## Event Dispatch Mechanism
+
+The complete path from main process to plugin:
+
+
+
+Key source code:
+
+```python
+async def emit_event(self, event_context, include_plugins=None):
+ for plugin in self.plugins:
+ if plugin.status != RuntimeContainerStatus.INITIALIZED:
+ continue
+ if not plugin.enabled:
+ continue
+
+ # Pipeline-level plugin filtering
+ if include_plugins is not None:
+ plugin_id = f"{plugin.manifest.metadata.author}/{plugin.manifest.metadata.name}"
+ if plugin_id not in include_plugins:
+ continue
+
+ resp = await plugin._runtime_plugin_handler.emit_event(
+ event_context.model_dump()
+ )
+
+ event_context = EventContext.model_validate(resp["event_context"])
+
+ # Plugin requested propagation stop
+ if event_context.is_prevented_postorder():
+ break
+
+ return emitted_plugins, event_context
+```
+
+The `include_plugins` parameter enables **pipeline-level plugin binding** — different message processing pipelines can use different subsets of plugins.
+
+## Installation & Distribution
+
+Plugins support three installation sources:
+
+1. **Local upload**: `.lbpkg` files (actually zip archives containing manifest.yaml and code)
+2. **Marketplace**: Install from LangBot Space online
+3. **GitHub Release**: Download from a GitHub repository's Release assets
+
+The installation flow:
+
+```python
+async def install_plugin(self, source, install_info):
+ yield {"current_action": "downloading plugin package"}
+ # 1. Fetch and extract the plugin package (unzip)
+ plugin_path, author, name, version = await self.install_plugin_from_file(plugin_file)
+
+ yield {"current_action": "installing dependencies"}
+ # 2. Install dependencies (pip install -r requirements.txt)
+ pkgmgr_helper.install_requirements(requirements_file)
+
+ yield {"current_action": "initializing plugin settings"}
+ # 3. Initialize configuration
+ await self.context.control_handler.call_action(
+ RuntimeToLangBotAction.INITIALIZE_PLUGIN_SETTINGS, {...}
+ )
+
+ yield {"current_action": "launching plugin"}
+ # 4. Launch the plugin process
+ task = self.launch_plugin(plugin_path)
+```
+
+The entire process reports progress via `AsyncGenerator`, enabling real-time installation status in the frontend.
+
+## Developer Experience
+
+The SDK provides a complete developer toolchain:
+
+```bash
+# Initialize a new plugin
+lbp init
+
+# Add a component
+lbp component add
+
+# Run locally for debugging
+lbp run
+
+# Package for publication
+lbp publish
+```
+
+**Debug mode** has a particularly clever design: the developer's plugin connects to the running Runtime via WebSocket (instead of stdio), meaning you can hot-reload plugin code without restarting LangBot. Debug plugins are specially marked in the UI and protected from accidental deletion.
+
+## Comparisons with Other Systems
+
+### vs Dify Plugins
+
+Dify's plugin system (`dify-plugin-daemon`) shares the process isolation philosophy with LangBot, but the focus differs:
+
+- **Dify**: Plugins extend workflow node types (Tool, Model, Extension) — designed for AI application orchestration
+- **LangBot**: Plugins extend the message processing pipeline (Event, Tool, Command, KnowledgeRetriever) — designed for instant messaging scenarios
+
+LangBot's `EventListener` component provides a capability Dify lacks — injecting logic at any stage of message processing.
+
+### vs MCP (Model Context Protocol)
+
+MCP is a standardized protocol for AI tool invocation. LangBot's Tool component and MCP services overlap functionally, but serve different purposes:
+
+- **MCP**: A universal "AI calls external capabilities" protocol, usable by any LLM application
+- **LangBot Tool**: Deeply integrated with message processing context, with access to session info, user identity, etc.
+
+In practice, LangBot natively supports MCP — users can configure MCP servers directly in LangBot without writing plugins. LangBot's Tool component is for scenarios requiring access to LangBot's internal context.
+
+## Design Decisions Explained
+
+**Why process isolation instead of threads/coroutines?**
+
+- Plugin code quality is unpredictable; a segfault shouldn't crash the entire service
+- Dependency isolation: different plugins may depend on different versions of the same library
+- Resource control: you can set per-plugin process resource limits
+
+**Why JSON instead of Protobuf/MessagePack?**
+
+- Debug-friendly: developers can directly read communication logs
+- Natively supported in Python, no extra dependencies
+- The performance bottleneck isn't serialization (plugin call frequency is far below database queries)
+
+**Why stdio over WebSocket by default?**
+
+- stdio requires no network stack — lower latency
+- Simpler process lifecycle management (child processes auto-cleanup when parent exits)
+- WebSocket is only used where stdio isn't supported (Docker, Windows)
+
+## Conclusion
+
+LangBot's plugin system is a **production-grade, process-isolated, event-driven component framework for extensibility**.
+
+Its core design principles:
+1. **Safety first**: Process isolation ensures plugins can't destabilize the main service
+2. **Deployment flexibility**: Dual stdio/WebSocket modes adapt to all environments
+3. **Developer-friendly**: Complete SDK, CLI, and debug support
+4. **Component-based**: Four component types cover the major extension needs
+
+If you're interested in developing LangBot plugins, start with the [plugin development docs](https://langbot.app/docs/en/plugin/dev/tutor), or browse existing plugins on the [marketplace](https://space.langbot.app/market) for inspiration.
diff --git a/docs/en/articles/langbot-v4100-sandbox-skills.mdx b/docs/en/articles/langbot-v4100-sandbox-skills.mdx
new file mode 100644
index 000000000..ac5480165
--- /dev/null
+++ b/docs/en/articles/langbot-v4100-sandbox-skills.mdx
@@ -0,0 +1,113 @@
+---
+title: "LangBot v4.10.0: Agentic Sandbox & Skills — Letting Your Agent Work Like a Developer"
+description: "LangBot v4.10.0 brings a real sandbox (Box Runtime) and an on-demand Skills system to the built-in Agent. It can now run commands and edit files in an isolated environment, and pull in specialized know-how exactly when a task needs it."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langbot-v4100-sandbox-skills).
+
+Published 2026-06-04 · Author: LangBot Team
+
+
+
+LangBot v4.10.0 is our biggest Agent update yet. It ships two features that point in the same direction — **letting the built-in Agent work like a real developer**:
+
+1. **Sandbox**: the Agent now runs in a genuinely isolated environment where it can execute commands and work with files.
+2. **Skills**: the Agent can load specialized know-how on demand, instead of cramming everything into its context.
+
+Both capabilities were led by community contributor [@huanghuoguoguo](https://github.com/huanghuoguoguo). Let's dig in.
+
+> **New to LangBot?** [LangBot](https://github.com/langbot-app/LangBot) is an open-source LLM bot platform (15k+ GitHub stars) that lets you deploy AI chatbots across **Discord, Telegram, WeChat (个人微信 / 企业微信), Slack, Lark (Feishu), DingTalk, QQ** and more — all from a single instance. It connects 20+ large language models (OpenAI GPT, Anthropic Claude, Google Gemini, DeepSeek, and others) to 13+ messaging platforms, with built-in Agent, RAG knowledge bases, MCP support, and a plugin ecosystem. You can self-host it with one Docker command or run it managed on [LangBot Cloud](https://space.langbot.app/cloud).
+
+## 📦 Sandbox: a real workspace for your Agent
+
+Until now, LangBot's built-in Agent could only call predefined tools. It couldn't "open a terminal and run a command," nor "write an intermediate result to a file and read it back later" — which is exactly what human developers do all day.
+
+v4.10.0 introduces the new **Box Runtime**. It gives the Agent an isolated sandbox environment with six native tools built in:
+
+| Tool | Purpose |
+|------|---------|
+| `exec` | Run shell commands |
+| `read` | Read file contents |
+| `write` | Write files |
+| `edit` | Make targeted edits to files |
+| `glob` | Find files by pattern |
+| `grep` | Search inside file contents |
+
+With this toolkit, the Agent can work like a developer: run a script, save the output to a file, read it back to analyze, and post-process the result. All of it happens inside an isolated environment that never touches the host.
+
+
+
+### Pluggable backends
+
+The sandbox's execution backend is **pluggable**, and LangBot selects one automatically based on your deployment:
+
+- **Docker**: spins up a dedicated `langbot_box` container that talks to the main process over WebSocket. Great for containerized deployments.
+- **nsjail**: lightweight isolation based on Linux namespaces, no extra container needed. Great for bare-metal or single-container setups.
+- **E2B**: cloud sandbox that runs execution in a remote isolated environment.
+
+You don't have to pick manually — `box.enabled` is the master switch. Once on, LangBot probes for the most suitable backend and degrades gracefully if probing fails.
+
+
+
+### It also hosts MCP Servers
+
+Beyond native tools, the Box Runtime takes on another important job: **hosting stdio-mode MCP Servers**.
+
+Previously, stdio-mode MCP Servers had to be spawned as subprocesses directly inside the main process — neither safe nor easy to manage. Now they all run inside the sandbox, sharing the same isolation boundary as the Agent's execution environment. `http` / `sse` mode MCP is unaffected and works as before.
+
+## 🎯 Skills: know-how, loaded on demand
+
+The second big update is **Skills**.
+
+As the Agent's capabilities grow, an old problem surfaces: **the context window is finite**. If you stuff every possible instruction, procedure, and reference doc into the system prompt, the context fills up fast — and most of it is irrelevant to the task at hand.
+
+The design idea behind Skills is simple: **keep the table of contents in view, and open the book only when you need it.**
+
+A Skill is an **on-demand instruction pack** containing:
+
+- **A prompt**: tells the Agent what the skill does and when to use it
+- **A procedure**: the steps to accomplish a class of tasks
+- **Scripts**: ready-to-run helper scripts
+- **Reference files**: API docs, templates, examples, and so on
+
+By default the Agent only sees a **list of available skills** (name + summary), which costs almost nothing in context. When it decides a task needs a particular skill, it pulls the full content just in time via the `activate` action.
+
+
+
+The benefits are clear:
+
+1. **Lean context**: irrelevant skill content never takes up the window.
+2. **Extensible capabilities**: want to teach the Agent a new trick? Write a skill pack — no core code changes.
+3. **Instant effect**: skills load dynamically during execution, no restart required.
+
+If you've used Claude's Skills or a similar mechanism, this pattern will feel familiar — it decouples "what the Agent knows" from "what the Agent needs right now."
+
+## 🧩 Shipped early across 4.9.x
+
+These were planned for v4.10.0 but shipped early in the 4.9.x line:
+
+- **Plugin Extension Pages**: plugins can render custom UI via iframe + a Page SDK ([@TyperBody](https://github.com/TyperBody), #2107)
+- **Monitoring**: feedback linked to message IDs, plus feedback export ([@6mvp6](https://github.com/6mvp6), #2120)
+- **Security hardening**: path-traversal fixes and removal of an authenticated RCE endpoint ([@sebastiondev](https://github.com/sebastiondev), #2087 / #2178)
+
+## 🚀 Getting started
+
+The sandbox needs an execution backend, depending on how you deploy:
+
+- **Docker**: run `docker compose --profile all up`, which also launches the `langbot_box` container.
+- **Manual / `uvx`**: runs as a stdio subprocess automatically, nothing to do.
+- **LangBot Cloud**: ready out of the box — the sandbox is already set up for you, nothing to install.
+
+To turn the sandbox off, set `box.enabled: false` — built-in tools, Skill create/edit, and stdio-mode MCP are all disabled; `http` / `sse` mode MCP is unaffected. See the [Sandbox docs](https://langbot.app/docs/en/usage/sandbox/readme) for details.
+
+This release also upgrades the plugin SDK to **`langbot-plugin 0.4.1`**.
+
+## Closing thoughts
+
+Sandbox and Skills are, at their core, answering the same question: **how do we let an Agent handle genuinely complex, open-ended tasks?**
+
+The sandbox solves the "**hands**" problem — giving the Agent the ability to execute and room to experiment. Skills solve the "**brain**" problem — letting the Agent reach for the right knowledge at the right moment, without drowning in irrelevant information.
+
+The fastest way to try it is to spin up a managed instance on [LangBot Cloud](https://space.langbot.app/cloud), where the sandbox is ready to go. You can also read the [full release notes](https://github.com/langbot-app/LangBot/releases/tag/v4.10.0) for every change.
+
+Thank you to everyone building with LangBot. We'll keep making the cloud Agent experience more stable and more capable.
diff --git a/docs/en/articles/langbot-v490-rag-plugin-architecture.mdx b/docs/en/articles/langbot-v490-rag-plugin-architecture.mdx
new file mode 100644
index 000000000..21316fc6d
--- /dev/null
+++ b/docs/en/articles/langbot-v490-rag-plugin-architecture.mdx
@@ -0,0 +1,293 @@
+---
+title: "LangBot v4.9.0: Full RAG Plugin Architecture — Knowledge Without Borders"
+description: "LangBot v4.9.0 refactors the entire knowledge base system from a built-in implementation to a plugin-driven architecture, introducing KnowledgeEngine and Parser component types for boundless extensibility."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langbot-v490-rag-plugin-architecture).
+
+Published 2026-03-10 · Author: LangBot Team
+
+
+
+LangBot v4.9.0, codenamed **"Knowledge Without Borders,"** does exactly what the name says: **the entire knowledge base capability has been refactored from a built-in implementation to a plugin-driven architecture.**
+
+This isn't a minor tweak — it redefines what "knowledge" means in LangBot.
+
+## The Problem with the Old Approach
+
+Before v4.9.0, LangBot's knowledge base was split into two separate systems:
+
+- **Built-in Knowledge Base**: Used Chroma as the vector database, with embedding models managed by LangBot directly. Document parsing, chunking, and indexing were all hardcoded.
+- **External Knowledge Base**: Bridged services like Dify, RAGFlow, and FastGPT through the `KnowledgeRetriever` plugin component — retrieval only, no document ingestion.
+
+These two systems lived behind separate UI tabs, with completely different data models and management flows.
+
+**Why this was painful:**
+
+1. **Poor extensibility**: Want a different vector database? A custom chunking strategy? Sorry, that's hardcoded.
+2. **High maintenance cost**: Every RAG improvement required changes to LangBot's core code and a new release.
+3. **Fragmented UX**: Two completely different knowledge base management flows meant a steep learning curve.
+
+v4.9.0 solves this decisively: **extract RAG capabilities from LangBot's core and hand them to plugins.**
+
+## What Changed
+
+### 1. Unified Knowledge Base Model
+
+The `internal` / `external` distinction is gone. All knowledge bases are managed through a single interface, differentiated only by their `rag_engine_plugin_id`. One list, one creation flow — just pick your engine.
+
+### 2. KnowledgeEngine Component
+
+This is the headline addition. `KnowledgeEngine` replaces the old `KnowledgeRetriever` and takes ownership of the full knowledge base lifecycle:
+
+- **Document Ingestion**: The complete pipeline from file parsing to vector indexing
+- **Knowledge Retrieval**: Returning relevant chunks at query time
+- **Document Deletion**: Cleaning up documents and their associated vector data
+- **Lifecycle Hooks**: Callbacks when knowledge bases are created or deleted
+
+A KnowledgeEngine plugin has full control over indexing and retrieval strategies — not just retrieval.
+
+
+
+### 3. Parser Component
+
+Document parsing has been extracted into its own plugin component type. A Parser converts binary files (PDF, Word, Markdown, etc.) into structured text, which is then handed to the RAG engine for chunking and indexing.
+
+**The data flow:**
+
+
+
+If a RAG engine declares `DOC_PARSING` capability, it can handle parsing internally and skip the external Parser.
+
+### 4. Host RAG API
+
+LangBot's core no longer executes RAG operations directly, but it still provides essential infrastructure through `RAGRuntimeService`, accessible to plugins via RPC:
+
+- **Embedding invocation**: `invoke_embedding()` — plugins don't need to manage model connections
+- **Vector database operations**: `vector_upsert()` / `vector_search()` / `vector_delete()`
+- **File access**: `get_knowledge_file_stream()` — read raw files from storage
+
+This means plugins can focus on RAG strategy (chunking algorithms, retrieval logic, re-ranking) while the host handles the "heavy" operations like vector storage and embedding models.
+
+### 5. KnowledgeRetriever Deprecated
+
+The old `KnowledgeRetriever` component has been removed. If you had external knowledge base plugins, they'll need to migrate to `KnowledgeEngine`. The good news: the new API is cleaner and migration is straightforward.
+
+## Building a RAG Engine Plugin
+
+### Scaffold the Component
+
+```bash
+lbp comp KnowledgeEngine
+```
+
+This generates the directory structure:
+
+
+
+### Define Configuration Schemas
+
+The YAML manifest defines two configuration schemas:
+
+- **`creation_schema`**: Parameters filled when creating a knowledge base (e.g., chunk size, embedding model)
+- **`retrieval_schema`**: Parameters adjustable at retrieval time (e.g., score threshold, top-K)
+
+```yaml
+spec:
+ creation_schema:
+ - name: chunk_size
+ label:
+ en_US: Chunk Size
+ type: integer
+ default: 500
+ - name: chunk_overlap
+ label:
+ en_US: Chunk Overlap
+ type: integer
+ default: 50
+ retrieval_schema:
+ - name: score_threshold
+ label:
+ en_US: Score Threshold
+ type: float
+ default: 0.5
+```
+
+LangBot **dynamically renders** creation and retrieval forms based on these schemas — different engines show different configuration fields.
+
+### Declare Capabilities
+
+```python
+class SimpleRag(KnowledgeEngine):
+
+ @classmethod
+ def get_capabilities(cls) -> list[str]:
+ return [
+ KnowledgeEngineCapability.DOC_INGESTION, # Supports document upload
+ # KnowledgeEngineCapability.DOC_PARSING, # Optional: built-in parsing
+ ]
+```
+
+| Capability | Description |
+|------------|-------------|
+| `DOC_INGESTION` | Supports document upload and processing. UI shows "Documents" tab |
+| `DOC_PARSING` | Supports built-in document parsing. Without this, an external Parser plugin is required |
+
+### Implement Core Methods
+
+The three essential methods:
+
+**Document Ingestion:**
+
+```python
+async def ingest(self, context: IngestionContext) -> IngestionResult:
+ # 1. Get file content (or use Parser's pre-parsed result)
+ if context.parsed_content:
+ text = context.parsed_content.text
+ else:
+ file_bytes = await self.plugin.get_knowledge_file_stream(
+ context.file_object.storage_path
+ )
+ text = file_bytes.decode('utf-8')
+
+ # 2. Chunk the text
+ chunks = self._split_text(text, chunk_size=500)
+
+ # 3. Call host embedding model
+ vectors = await self.plugin.invoke_embedding(
+ embedding_model_uuid, chunks
+ )
+
+ # 4. Write to host vector database
+ await self.plugin.vector_upsert(
+ collection_id, vectors, ids, metadata
+ )
+
+ return IngestionResult(
+ document_id=context.file_object.metadata.document_id,
+ status=DocumentStatus.COMPLETED,
+ chunks_created=len(chunks),
+ )
+```
+
+**Knowledge Retrieval:**
+
+```python
+async def retrieve(self, context: RetrievalContext) -> RetrievalResponse:
+ # 1. Generate query vector
+ query_vectors = await self.plugin.invoke_embedding(
+ embedding_model_uuid, [context.query]
+ )
+
+ # 2. Vector search
+ results = await self.plugin.vector_search(
+ collection_id, query_vectors[0], top_k=5
+ )
+
+ # 3. Convert and return
+ return RetrievalResponse(results=entries, total_found=len(entries))
+```
+
+**Document Deletion:**
+
+```python
+async def delete_document(self, kb_id: str, document_id: str) -> bool:
+ deleted = await self.plugin.vector_delete(
+ collection_id=kb_id, file_ids=[document_id]
+ )
+ return deleted > 0
+```
+
+### Bridging External Services
+
+If your goal is to bridge Dify, RAGFlow, FastGPT, or other external services rather than building a custom RAG pipeline, the implementation is even simpler — **don't declare `DOC_INGESTION` capability** and only implement `retrieve`:
+
+```python
+class DifyRAGEngine(KnowledgeEngine):
+
+ @classmethod
+ def get_capabilities(cls) -> list[str]:
+ return [] # No document upload — managed externally
+
+ async def retrieve(self, context: RetrievalContext) -> RetrievalResponse:
+ # Call Dify/RAGFlow/FastGPT retrieval API
+ ...
+```
+
+The knowledge base won't show a "Documents" tab — all content management happens in the external service.
+
+## Building a Parser Plugin
+
+Parser development is even more concise:
+
+```bash
+lbp comp Parser
+```
+
+Declare supported MIME types in the manifest:
+
+```yaml
+spec:
+ supported_mime_types:
+ - application/pdf
+ - application/vnd.openxmlformats-officedocument.wordprocessingml.document
+```
+
+Implement the `parse` method:
+
+```python
+class PdfParser(Parser):
+
+ async def parse(self, context: ParseContext) -> ParseResult:
+ # context.file_content: raw file bytes
+ # context.mime_type: detected MIME type
+ # context.filename: original filename
+
+ text = extract_text_from_pdf(context.file_content)
+
+ return ParseResult(
+ text=text,
+ sections=[
+ TextSection(content=page_text, heading=f"Page {i}", page=i)
+ for i, page_text in enumerate(pages)
+ ],
+ )
+```
+
+Parsers also support **cross-plugin invocation** — a RAG engine plugin can call another plugin's Parser:
+
+```python
+result = await self.plugin.invoke_parser(
+ plugin_author="author_name",
+ plugin_name="plugin_name",
+ storage_path=context.file_object.storage_path,
+ mime_type=context.file_object.metadata.mime_type,
+ filename=context.file_object.metadata.filename,
+)
+```
+
+## Upgrade Notes
+
+- Knowledge bases created in previous versions are **automatically migrated**. After updating, visit the Knowledge Base page to verify.
+- The `KnowledgeRetriever` component is deprecated. Existing plugins need to migrate to `KnowledgeEngine`.
+- Browse the [Plugin Marketplace](https://space.langbot.app/market?category=KnowledgeEngine) for available RAG engine plugins.
+
+## The Bigger Picture
+
+v4.9.0's knowledge base refactoring is the latest step in LangBot's plugin-first evolution. From event handlers and tools in v4.0, to knowledge retrievers, to now full RAG engines and parsers — LangBot's core capabilities are progressively moving from "built-in" to "pluggable."
+
+The endgame: **LangBot's core provides pipeline orchestration and infrastructure; all business capabilities are plugin-driven.**
+
+Custom chunking strategy? Write a KnowledgeEngine plugin. PDF parsing? Write a Parser plugin. Bridge your company's internal knowledge service? Also a plugin.
+
+Knowledge, without borders.
+
+---
+
+**Links:**
+
+- [v4.9.0 Release Notes](https://github.com/langbot-app/LangBot/releases/tag/v4.9.0)
+- [KnowledgeEngine Development Guide](https://langbot.app/docs/en/plugin/dev/components/knowledge-engine)
+- [Parser Development Guide](https://langbot.app/docs/en/plugin/dev/components/parser)
+- [Plugin Marketplace](https://space.langbot.app/market)
+- [LangBot Cloud](https://space.langbot.app/cloud)
diff --git a/docs/en/articles/langflow-drag-and-drop-ai-bot.mdx b/docs/en/articles/langflow-drag-and-drop-ai-bot.mdx
new file mode 100644
index 000000000..e44505c2c
--- /dev/null
+++ b/docs/en/articles/langflow-drag-and-drop-ai-bot.mdx
@@ -0,0 +1,207 @@
+---
+title: "How I Built a Multi-Platform AI Bot with Langflow's Drag-and-Drop Workflows"
+description: "How I Built a Multi-Platform AI Bot with Langflow's Drag-and-Drop Workflows"
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langflow-drag-and-drop-ai-bot).
+
+Published 2025-12-05 · Author: LangBot Team
+
+
+
+Drive chatbots across QQ, WeChat, Telegram, Discord, and more using visual workflows - no coding required.
+
+---
+
+[LangBot](https://github.com/langbot-app/LangBot) is an open-source instant messaging bot platform that connects AI workflow engines like Langflow, n8n, Dify, FastGPT, and Coze to platforms including WeChat, QQ, Feishu, DingTalk, Telegram, Discord, Slack, and LINE. This tutorial demonstrates how to use Langflow's visual workflows as LangBot's conversation engine.
+
+## Why This Approach Works
+
+- **True Multi-Platform**: One workflow powering 8+ messaging platforms simultaneously
+- **Visual Orchestration**: Drag-and-drop conversation design with conditional branches, multi-turn dialogs, and external API calls
+- **Flexible AI Models**: Support for OpenAI, Claude, Gemini, DeepSeek, and local models
+- **Fully Open Source**: Both LangBot and Langflow are open-source projects for free deployment and customization
+
+## Prerequisites
+
+- Python 3.10+
+- Docker (recommended for quick deployment)
+- OpenAI API Key or API keys for other LLM services
+
+## Step 1: Deploy LangBot
+
+Launch with uvx in one command:
+
+```bash
+uvx langbot
+```
+
+First run auto-initializes and opens your browser to http://127.0.0.1:5300.
+
+
+
+After registration, log in to access the dashboard:
+
+
+
+## Step 2: Deploy Langflow
+
+Deploy quickly with Docker:
+
+```bash
+docker run -d --name langflow -p 7860:7860 langflowai/langflow:latest
+```
+
+Visit http://localhost:7860 to access Langflow:
+
+
+
+## Step 3: Create a Langflow Workflow
+
+In Langflow, select the "Basic Prompting" template to get started quickly:
+
+
+
+This template includes four basic components:
+- **Chat Input**: Receives user messages
+- **Prompt**: Sets system instructions
+- **Language Model**: Calls LLM to generate responses
+- **Chat Output**: Returns results
+
+
+
+### Configure Language Model
+
+Click the Language Model component and configure:
+
+1. **Model Provider**: Select OpenAI (or other compatible providers like SiliconFlow, New API)
+2. **Model Name**: Select gpt-4o-mini or deepseek-chat
+3. **OpenAI API Key**: Enter your API Key
+
+
+
+> Tip: You can use OpenAI-compatible API services like SiliconFlow or New API by simply modifying the Base URL.
+
+Save the workflow after configuration.
+
+## Step 4: Get Langflow API Information
+
+### Generate API Key
+
+In Langflow's upper right: Settings → API Keys, navigate to the API Keys page:
+
+
+
+Click Create New Key:
+
+
+
+Generate and save the API Key:
+
+
+
+Format: `sk-xxxxxxxxxxxxxxxxxxxxxxxx`
+
+### Get Flow ID
+
+Extract from the flow editor's URL:
+
+```
+http://localhost:7860/flow/{flow-id}
+```
+
+Record this `flow-id`.
+
+## Step 5: Configure Langflow in LangBot
+
+Return to LangBot dashboard and go to **Pipelines** page.
+
+Click ChatPipeline to edit, in the AI tab:
+
+
+
+Configure **Runner**, select **Langflow API**:
+
+
+
+Fill in the Langflow configuration:
+
+
+
+Configuration items:
+- **Base URL**: `http://localhost:7860` (local) or `http://langflow:7860` (Docker network)
+- **API Key**: The API Key generated in Langflow
+- **Flow ID**: The Flow ID recorded earlier
+
+
+
+> Docker Tip: If both services run in containers, ensure they're on the same network and use the container name for Base URL.
+
+Click **Save** to save the configuration.
+
+## Step 6: Test the Conversation
+
+Click **Debug Chat** on the Pipelines page to open the debug chat interface:
+
+
+
+Enter a test message like "Hello" and view the AI response:
+
+
+
+## How It Works
+
+1. User sends a message on a messaging platform
+2. LangBot receives and passes it to the Pipeline
+3. Pipeline calls Langflow API
+4. Langflow executes the workflow: receives input → adds prompt → calls LLM → returns result
+5. LangBot sends the response back to the user
+
+## Common Issues
+
+**Cannot connect to Langflow?**
+
+Check Base URL. For Docker deployment, ensure containers are on the same network:
+
+```bash
+docker network create langbot_network
+docker network connect langbot_network langflow
+docker network connect langbot_network langbot
+```
+
+Use container name: `http://langflow:7860`
+
+**API call fails?**
+
+- Confirm API Key and Flow ID are correct
+- Verify the Language Model in Langflow has a valid LLM API Key configured
+
+## Advanced Use Cases
+
+Langflow's power lies in visually orchestrating complex AI workflows:
+
+- **Multi-Turn Memory**: Add Memory components for contextual understanding
+- **Conditional Branches**: Execute different logic based on user input
+- **External API Integration**: Connect databases, search engines, third-party services
+- **Multi-Agent Collaboration**: Multiple LLM models working together
+- **RAG Applications**: Integrate vector databases for knowledge base Q&A
+
+All achievable through drag-and-drop without writing code.
+
+## Summary
+
+With LangBot + Langflow, you can rapidly build powerful multi-platform AI chatbots. Langflow provides visual workflow orchestration, LangBot handles messaging platform integration - together they create a complete loop from workflow design to multi-platform deployment.
+
+This approach is ideal for:
+- Scenarios requiring the same AI capabilities across multiple platforms
+- Teams wanting rapid iteration and testing of different conversation flows
+- Developers wanting to build complex AI applications without deep coding
+
+## Related Resources
+
+- [LangBot Official Site](https://langbot.app) | [Documentation](https://langbot.app/docs) | [GitHub](https://github.com/langbot-app/LangBot)
+- [Langflow Official Site](https://www.langflow.org) | [Documentation](https://docs.langflow.org) | [GitHub](https://github.com/langflow-ai/langflow)
+
+---
+
+*This article is based on the latest version of LangBot. LangBot supports integration with Dify, n8n, FastGPT, Coze, and other AI platforms - choose the workflow engine that best fits your needs.*
diff --git a/docs/en/articles/langtars-remote-pc-control-dify-n8n.mdx b/docs/en/articles/langtars-remote-pc-control-dify-n8n.mdx
new file mode 100644
index 000000000..afd2320d3
--- /dev/null
+++ b/docs/en/articles/langtars-remote-pc-control-dify-n8n.mdx
@@ -0,0 +1,200 @@
+---
+title: "LangTARS: Open-Source AI Agent for Remote PC Control — Works with Dify, n8n & 10+ Messaging Platforms"
+description: "LangTARS is a LangBot native plugin that lets you remotely control Mac/Windows/Linux from Telegram, Discord & WeChat — with Dify and n8n workflow support."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/langtars-remote-pc-control-dify-n8n).
+
+Published 2026-03-23 · Author: LangBot Team
+
+
+
+**LangBot Native Plugin | OpenClaw-like Experience | Ready to Use with One-Click Deployment**
+
+---
+
+## ✨ What is LangTARS?
+
+**LangTARS** is a powerful **OpenClaw alternative** and native plugin for LangBot, inspired by the loyal and reliable robot TARS from the movie *Interstellar*.
+
+As a versatile **AI agent** for **remote computer control**, LangTARS allows you to remotely command your **Mac, Windows, or Linux** machine directly through your favorite messaging apps like **Telegram, Discord, DingTalk, and WeChat**! If you've been looking for an **OpenClaw-like** computer use agent that integrates seamlessly into your existing **chatbot framework**, LangTARS is the perfect solution.
+
+> 💡 **Deploy LangBot, and you can experience LangTARS instantly!** No extra standalone agent installation needed—just get it with one click from the plugin marketplace.
+
+
+
+---
+
+## 🤖 The LangBot Ecosystem
+
+LangTARS is just ONE plugin in the massive LangBot ecosystem. **LangBot** is a leading **open source chatbot** framework designed for connecting LLMs to messaging platforms.
+
+- **Multi-platform bot integration**: Native support for Telegram, Discord, WeChat, DingTalk, Lark, LINE, Slack, and more.
+- **Multi-model LLM chatbot**: Works flawlessly with OpenAI, Claude, Gemini, DeepSeek, and local models.
+- **Rich Plugin Marketplace**: Access over 30+ plugins for endless functionality.
+- **Advanced Features**: Pipeline-based message processing, RAG support, and multi-agent workflows.
+- **Self-hosted AI**: Total control over your data and deployments.
+- **AI Workflow Integrations**: Connect LangBot to platforms like **Dify**, **n8n**, **Langflow**, and **Coze**. LangBot can act as the messaging frontend for your complex AI workflows, meaning LangTARS + Dify/n8n = powerful automation!
+
+Get started with LangBot:
+- **Easiest**: [LangBot Cloud](https://cloud.langbot.app)
+- Self-host: `uvx langbot@latest`
+- Documentation: [langbot.app/docs](https://langbot.app/docs)
+- GitHub: [github.com/langbot-app/LangBot](https://github.com/langbot-app/LangBot) (15k+ stars)
+
+---
+
+## 🎯 What Can It Do?
+
+As a comprehensive **automation tool**, just send a message, and the AI will handle your **task automation** and **browser automation**:
+
+| You Say | AI Does |
+|------|-------|
+| `!tars open Reddit in Chrome, post a thread with the title "Hello from LangTARS" and say hi` | 🌐 Automatically controls Chrome to open Reddit and publish a post |
+| `!tars organize my desktop files` | 📁 Automatically categorizes and moves files |
+| `!tars open the browser and search for today's AI news` | 🌐 Opens a browser, searches the web, and summarizes the news |
+| `!tars create a meeting note for our marketing sync` | 📝 Automatically creates a markdown note file |
+| `!tars check system memory and CPU` | 💻 Uses MCP tools to get computer status |
+
+
+
+
+
+---
+
+## 🔗 Supercharge with Dify & n8n
+
+LangTARS becomes even more powerful when combined with **AI workflow platforms**:
+
+- **Dify Integration**: Connect LangBot to [Dify](https://dify.ai) as a messaging frontend. Build complex AI workflows in Dify's visual editor, then trigger them from Telegram/Discord via LangTARS.
+- **n8n Integration**: Use [n8n](https://n8n.io) workflows with LangBot for advanced automation chains. Combine LangTARS's computer control with n8n's 400+ integrations for unlimited possibilities.
+- **Also supports**: Langflow, Coze, and any OpenAI-compatible API.
+
+> 💡 **Example**: "Hey TARS, run my Dify workflow to analyze today's sales data and save the report to my desktop" — LangTARS handles the entire chain.
+
+---
+
+## 🚀 Why Choose LangTARS?
+
+### 1️⃣ LangBot Native Plugin, Out of the Box
+
+Instead of deploying a complex standalone agent, you can easily **deploy AI bot** capabilities right where you already chat.
+
+```bash
+# Deploy LangBot with one command
+uvx langbot@latest
+
+# Install LangTARS from the plugin market, configure your LLM, and start using!
+```
+
+**No complex configuration, no extra deployment. LangBot users can experience OpenClaw-style computer control directly!**
+
+
+
+---
+
+### 2️⃣ Intelligent Task Planning, Autonomous Execution
+
+Powered by an AI planning engine based on the **ReAct agent** loop:
+
+```
+Your Command → Understand Needs → Make a Plan → Execute Step-by-Step → Feedback Results
+```
+
+The AI assistant thinks like a human and automatically breaks down complex tasks using integrated **MCP tools**!
+
+---
+
+### 3️⃣ Multi-Browser Support for Web Automation
+
+| Browser | macOS | Windows | Linux |
+|--------|-------|---------|-------|
+| Playwright (Headless) | ✅ | ✅ | ✅ |
+| Safari | ✅ | - | - |
+| Chrome | ✅ | ✅ | ✅ |
+| Edge | - | ✅ | - |
+| Firefox | - | - | ✅ |
+
+---
+
+### 4️⃣ Security-First Design
+
+- 🚫 **Dangerous Command Interception** — Automatically blocks commands like `rm -rf /`
+- 📂 **Workspace Isolation** — Restricts file operations to safe directories
+- 📋 **Command Whitelist** — Configurable allowed commands
+- 👤 **User Access Control** — Restricts usage to specific authorized users
+
+
+
+---
+
+## 📱 Quick Start
+
+### Step 1: Deploy LangBot
+
+> 🚀 **Fastest way to start:** Use [LangBot Cloud](https://cloud.langbot.app) — deploy your LangBot instance in one click, no server needed! Install LangTARS from the plugin marketplace and start controlling your computer immediately.
+
+*Alternative for power users (Self-hosted):*
+```bash
+uvx langbot@latest
+```
+
+### Step 2: Configure Chat Platform
+
+Follow the documentation to configure your **Telegram bot**, **WeChat bot**, or **Discord bot**.
+
+### Step 3: Install LangTARS
+
+Search for **LangTARS** in the **plugin marketplace** and install it.
+
+### Step 4: Start Chatting
+
+```
+!tars Hello, tell me what you can do
+```
+
+> 📱 **Recommendation**: Use it on Telegram or Discord for the best interactive experience!
+
+---
+
+## 🎮 Common Commands
+
+| Command | Function |
+|------|------|
+| `!tars ` | Execute a task |
+| `!tars stop` | Stop the current task |
+| `!tars what` | Check execution status |
+| `!tars reset` | Reset the conversation |
+| `!tars help` | Show help |
+
+---
+
+## 🌟 Project Information
+
+| Item | Information |
+|------|------|
+| **GitHub** | [github.com/langbot-app/LangTARS](https://github.com/langbot-app/LangTARS) |
+| **Language** | Python 100% |
+| **License** | CC BY-NC-ND 4.0 |
+| **Platforms** | macOS / Windows / Linux |
+
+---
+
+## 🔗 Related Links
+
+- 📖 **LangBot Documentation**: [langbot.app/docs](https://langbot.app/docs)
+- 💬 **Issue Feedback**: [GitHub Issues](https://github.com/langbot-app/LangTARS/issues)
+- ⭐ **Support with a Star**: [GitHub](https://github.com/langbot-app/LangTARS)
+
+---
+
+## 🎉 Deploy LangBot and Experience LangTARS!
+
+**Let AI be your loyal digital assistant, just like TARS.**
+
+> 🚀 **Fastest way to start:** Use [LangBot Cloud](https://cloud.langbot.app) — deploy your LangBot instance in one click, no server needed! Install LangTARS from the plugin marketplace and start controlling your computer immediately.
+
+*Alternative for power users (Self-hosted):*
+```bash
+uvx langbot@latest
+```
diff --git a/docs/en/articles/n8n-multi-platform-ai-chatbot.mdx b/docs/en/articles/n8n-multi-platform-ai-chatbot.mdx
new file mode 100644
index 000000000..d10e91af5
--- /dev/null
+++ b/docs/en/articles/n8n-multi-platform-ai-chatbot.mdx
@@ -0,0 +1,184 @@
+---
+title: "How I Built a Multi-Platform AI Chatbot with n8n and LangBot"
+description: "How I Built a Multi-Platform AI Chatbot with n8n and LangBot"
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/n8n-multi-platform-ai-chatbot).
+
+Published 2025-12-03 · Author: LangBot Team
+
+
+
+Connecting n8n's visual workflow automation with LangBot's multi-platform bot framework creates a powerful, code-free way to deploy AI chatbots across QQ, WeChat, Discord, Telegram, Slack, and more. This tutorial shows you how to integrate these tools in minutes.
+
+## What You'll Need
+
+- Python 3.8+ installed
+- Node.js 18+ installed
+- npm or npx available
+- 15 minutes of your time
+
+## Deploy LangBot in 3 Commands
+
+LangBot is a production-ready bot framework that connects to multiple messaging platforms and AI services including Dify, FastGPT, Coze, OpenAI, Claude, and Gemini. Deploy it instantly:
+
+```bash
+cd your-workspace
+mkdir -p langbot-instance && cd langbot-instance
+uvx langbot@latest
+```
+
+On first launch, LangBot initializes automatically. Open `http://127.0.0.1:5300` in your browser.
+
+
+
+Register your admin account when prompted. You'll land on the dashboard where you can manage bots, models, pipelines, and integrations.
+
+
+
+## Set Up n8n Workflow Automation
+
+n8n is an open-source automation platform with 400+ integrations and powerful AI capabilities. Launch it locally:
+
+```bash
+cd your-workspace
+mkdir -p n8n-data
+export N8N_USER_FOLDER=$(pwd)/n8n-data
+npx n8n
+```
+
+Visit `http://127.0.0.1:5678` and create your owner account.
+
+
+
+## Build Your AI Workflow
+
+Create a new workflow in n8n. You'll need two essential nodes:
+
+
+
+### Add the Webhook Trigger
+
+Click "+" on the canvas and add a **Webhook** node. Configure it:
+
+- **HTTP Method**: POST
+- **Response Mode**: Streaming (enables real-time chat responses)
+- **Authentication**: None (adjust for production)
+
+
+
+### Add the AI Agent
+
+Press Tab, navigate to the "AI" category, and select **AI Agent**.
+
+**Configure the Chat Model**: Click "Chat Model" and choose "OpenAI Chat Model". Add your credentials:
+
+- **API Key**: Your OpenAI API key (or compatible service key)
+- **Base URL**: For OpenAI alternatives like Claude, Gemini, or local models, update to your provider's endpoint
+
+**Critical Step - Fix the Prompt Source**: By default, the AI Agent expects a Chat Trigger node, which won't work with webhooks. Here's how to fix it:
+
+1. Find "Source for Prompt (User Message)" in the AI Agent settings
+2. Change from "Connected Chat Trigger Node" to "Define below"
+3. Switch to "Expression" mode
+4. Enter: `{{ $json.body }}`
+
+This expression pulls the user's message from the webhook request body.
+
+
+
+### Activate and Get Your Webhook URL
+
+Save the workflow and toggle the activation switch (top-right). Switch to the "Production URL" tab and copy the webhook URL:
+
+```
+http://localhost:5678/webhook/{your-webhook-id}
+```
+
+## Connect LangBot to n8n
+
+Back in the LangBot dashboard, navigate to **Pipelines** and click the default "ChatPipeline".
+
+
+
+Switch to the **AI** tab and select "n8n Workflow API" from the Runner dropdown. Configure:
+
+- **Webhook URL**: Paste your n8n production webhook URL
+- **Authentication Type**: None (match your n8n webhook settings)
+- **Timeout**: 120 seconds
+- **Output Key**: response
+
+Click **Save**.
+
+## Test It Out
+
+In the Pipeline editor, click "Debug Chat" on the left sidebar. Send a test message like "What is LangBot?"
+
+If everything works, you'll see LangBot send the message to n8n, where the AI Agent processes it and streams back a response.
+
+## Troubleshooting
+
+**Error: "Expected to find the prompt in an input field called 'chatInput'"**
+
+This means the AI Agent is still configured for a Chat Trigger node. Fix it:
+
+1. Open the AI Agent configuration
+2. Set "Source for Prompt (User Message)" to "Define below"
+3. Switch to Expression mode
+4. Enter: `{{ $json.body }}`
+
+**Test Your Webhook Directly**
+
+Verify the webhook works with curl:
+
+```bash
+curl -X POST http://localhost:5678/webhook/your-webhook-id \
+ -H "Content-Type: application/json" \
+ -d '{"body": "Hello, can you introduce yourself?"}'
+```
+
+You should receive streaming JSON with the AI's response.
+
+## How the Integration Works
+
+Here's the complete flow:
+
+1. User sends a message via QQ, WeChat, Discord, Telegram, Slack, LINE, or any LangBot-supported platform
+2. LangBot's Pipeline receives the message and calls the n8n Workflow API
+3. n8n's Webhook node captures the request and passes it to the AI Agent
+4. The AI Agent uses OpenAI, Claude, Gemini, or your configured LLM to generate a response
+5. n8n streams the response back to LangBot
+6. LangBot delivers the response to the user on their original platform
+
+## Why This Combination Works
+
+**LangBot + n8n** unlocks powerful capabilities:
+
+1. **No-Code AI Logic**: Design conversation flows visually in n8n without touching code
+2. **Multi-Platform Reach**: Deploy the same AI across QQ, WeChat, Discord, Telegram, Slack, LINE, DingTalk, and Lark simultaneously
+3. **Flexible AI Models**: Swap between OpenAI GPT, Anthropic Claude, Google Gemini, Coze, Dify, local models, and more
+4. **Rich Integrations**: Connect n8n's 400+ integrations - databases, APIs, Notion, Airtable, Google Sheets, Slack, and beyond
+5. **Tool-Calling Agents**: AI Agent can trigger n8n tools like database queries, API calls, or custom functions
+6. **Workflow Extensions**: Add preprocessing, content moderation, logging, or custom business logic
+
+**Perfect For**:
+- Enterprise customer support bots
+- Knowledge base Q&A systems
+- Multi-platform community management
+- Task automation assistants
+- Unified chat interfaces for teams
+
+## Next Steps
+
+Extend your bot further:
+
+- Integrate Dify or FastGPT for advanced RAG (retrieval-augmented generation)
+- Add vector database nodes (Pinecone, Qdrant, Weaviate) for knowledge retrieval
+- Connect business APIs for real-time data
+- Implement conversation memory and context tracking
+- Add content filtering and moderation workflows
+- Use Langflow or Coze for additional AI orchestration
+
+This integration gives you the flexibility of code-based AI frameworks like LangChain with the simplicity of visual workflow builders - all while reaching users across every major messaging platform.
+
+Ready to deploy your multi-platform AI assistant? Start with LangBot and n8n today.
diff --git a/docs/en/articles/welcome.mdx b/docs/en/articles/welcome.mdx
new file mode 100644
index 000000000..c91f95454
--- /dev/null
+++ b/docs/en/articles/welcome.mdx
@@ -0,0 +1,33 @@
+---
+title: "Introducing the LangBot Blog"
+description: "Welcome to the official LangBot blog. Stay up to date with product updates, new features, and milestones."
+---
+
+This article is synchronized from the LangBot Blog. [Read the canonical version](https://langbot.app/en/blog/welcome).
+
+Published 2026-02-17 · Author: LangBot Team
+
+
+
+We're excited to launch the official LangBot blog! This is where we'll share product updates, new features, milestones, and insights from the LangBot team.
+
+## What is LangBot?
+
+LangBot is an open-source LLM-native instant messaging bot platform. It supports multiple messaging platforms and model providers, with integrations for Dify, Alibaba Cloud Bailian, and other LLMOps platforms. LangBot also provides a WebUI for quick deployment and management.
+
+## What to Expect
+
+On this blog, you'll find:
+
+- **Release Notes** - Detailed breakdowns of each new version
+- **Feature Spotlights** - Deep dives into new capabilities
+- **Milestones** - Project growth and community achievements
+- **Guides & Tips** - Best practices for getting the most out of LangBot
+
+## Stay Connected
+
+- [GitHub](https://github.com/langbot-app/LangBot) - Star us and follow development
+- [Documentation](https://langbot.app/docs) - Full guides and API reference
+- [LangBot Home](https://langbot.app) - Main website
+
+Stay tuned for more updates!
diff --git a/docs/en/deploy/command.mdx b/docs/en/deploy/command.mdx
new file mode 100644
index 000000000..2145524d0
--- /dev/null
+++ b/docs/en/deploy/command.mdx
@@ -0,0 +1,8 @@
+---
+title: "Command"
+description: "LangBot command-line reference: manage your AI bot instance, configuration, and runtime from the terminal."
+---
+
+LangBot will regard messages starting with `!` as commands. Official provides [`EssentialCommands` plugin](https://space.langbot.app/market?author=langbot-team&plugin=EssentialCommands), which includes commonly used commands.
+
+You can also develop your own command plugin, please refer to [Command Plugin Development](/en/plugin/dev/components/command).
diff --git a/docs/en/deploy/langbot/docker.mdx b/docs/en/deploy/langbot/docker.mdx
new file mode 100644
index 000000000..b13b8ba08
--- /dev/null
+++ b/docs/en/deploy/langbot/docker.mdx
@@ -0,0 +1,61 @@
+---
+title: "Docker Deployment"
+description: "Deploy LangBot with Docker Compose on Windows, Linux, or macOS."
+---
+
+## 1. Prepare your environment
+
+- Install Git.
+- **Windows / macOS**: install and start Docker Desktop.
+- **Linux**: install Docker and Docker Compose.
+
+## 2. Download the project
+
+Choose a regular directory that you can write to. On Linux, avoid system directories such as `/root` and `/etc`; we recommend a location under `/opt` so sandbox features are not blocked by security rules.
+
+Open a terminal in the directory where you want to store the project (PowerShell works on Windows), then run each line:
+
+```bash
+git clone https://github.com/langbot-app/LangBot
+cd LangBot/docker
+```
+
+### Mainland China: change the image source before startup (optional)
+
+If Docker Hub downloads are slow, edit `LangBot/docker/docker-compose.yaml` first. Replace every occurrence of `rockchin/langbot:latest` with:
+
+```text
+docker.langbot.app/langbot-public/rockchin/langbot:latest
+```
+
+Save the file before starting. No other configuration changes are needed.
+
+## 3. Start LangBot
+
+
+ On a server, use a firewall to restrict dashboard and runtime ports to trusted sources only.
+
+
+In the same terminal, run:
+
+```bash
+docker compose --profile all up -d
+```
+
+The first startup downloads the container images. On Windows / macOS, keep Docker Desktop running.
+
+## 4. Open the dashboard
+
+- **Local installation**: open `http://localhost:5300`.
+- **Server installation**: open `http://YOUR_SERVER_IP:5300` and make sure the firewall allows your device to access this port.
+
+Follow the on-screen initialization steps, then add a [model](/en/usage/models/readme) and a [bot](/en/usage/platforms/readme).
+
+## Beta releases (optional)
+
+To try a beta instead of the stable setup above, download the [dev/4.11.x Compose file](https://raw.githubusercontent.com/langbot-app/LangBot/dev/4.11.x/docker/docker-compose.yaml) as `compose.yaml` in a separate writable directory. Manually change **every** `rockchin/langbot` image to `rockchin/langbot:beta`: Core (`langbot`), plugin runtime (`langbot_plugin_runtime`), and Box (`langbot_box`, when present). The `beta` tag is updated with every beta release. From that directory, start or update with:
+
+```bash
+docker compose --profile all pull
+docker compose --profile all up -d
+```
diff --git a/docs/en/deploy/langbot/kubernetes.mdx b/docs/en/deploy/langbot/kubernetes.mdx
new file mode 100644
index 000000000..9acd83c64
--- /dev/null
+++ b/docs/en/deploy/langbot/kubernetes.mdx
@@ -0,0 +1,109 @@
+---
+title: "Kubernetes Deployment"
+description: "Deploy LangBot on Kubernetes for scalable, production-grade AI bot hosting across messaging platforms."
+---
+
+
+ Before you start, you should be familiar with:
+
+ - Basic Kubernetes usage (`kubectl`, Namespace, Deployment, Service, PVC)
+ - How to configure inter-container networking and persistent storage
+
+
+The LangBot repository ships a ready-to-use Kubernetes manifest at [`docker/kubernetes.yaml`](https://github.com/langbot-app/LangBot/blob/master/docker/kubernetes.yaml). This page is the deployment guide for that manifest, focusing on the **Box sandbox runtime** under Kubernetes — the part that differs most from the Docker Compose deployment.
+
+## Components
+
+The manifest creates the following components in the `langbot` namespace:
+
+| Component | Description | Ports |
+| --- | --- | --- |
+| `langbot` | Main app (WebUI + webhooks) | 5300 / 2280-2290 |
+| `langbot-plugin-runtime` | Plugin runtime | 5400 |
+| `langbot-box` | Box sandbox runtime (optional) | 5410 |
+
+Persistent storage: three PVCs (`langbot-data`, `langbot-plugins`, `langbot-plugin-runtime-data`). The Box workspace root uses a node `hostPath` (`/app/data/box`) rather than a PVC.
+
+## Quick Start
+
+```bash
+# Clone the repository
+git clone https://github.com/langbot-app/LangBot
+cd LangBot/docker
+
+# Deploy all components
+kubectl apply -f kubernetes.yaml
+
+# Check status
+kubectl get all -n langbot
+```
+
+Access the WebUI via port-forward:
+
+```bash
+kubectl port-forward -n langbot svc/langbot 5300:5300
+# Visit http://localhost:5300
+```
+
+For production, expose via Ingress + TLS (the manifest already includes commented Ingress / LoadBalancer / NodePort examples — uncomment as needed).
+
+### Using SeekDB
+
+The official image already includes the optional SeekDB dependencies, so no
+dedicated image or additional build argument is required. Set `vdb.use` to
+`seekdb` to enable it, or keep the default `chroma` when it is not needed.
+
+## Box Sandbox Runtime
+
+`langbot-box` provides the code-sandbox capability backing the sandbox tools (`exec` / `read` / `write` / `edit` / `glob` / `grep`), the skill `activate` tool and skill add/edit, and stdio-mode MCP servers. It is **optional**: without it, LangBot still runs and the dashboard / skills list stay visible (read-only), but those features are disabled — in that case set `BOX__ENABLED=false` on `langbot`.
+
+### How it works & the key constraint
+
+The official LangBot image ships **only the Docker CLI** (no dockerd, no nsjail). The Box runtime therefore creates sandbox containers by talking to the node's Docker daemon over the mounted socket (`/var/run/docker.sock`) — it does not run dockerd inside the Pod.
+
+This imposes a **key constraint**: the daemon that actually creates sandbox containers is the **node's Docker daemon**, which resolves bind-mount paths against the **node filesystem**. So the Box workspace root must be the **same absolute path** in all three places:
+
+1. The actual path on the node
+2. The mount path inside the `langbot-box` container
+3. The mount path inside every sandbox container it spawns
+
+This is exactly why the manifest uses a `hostPath` (fixed at `/app/data/box`) instead of a regular PVC: a PVC path only exists inside the Pod's mount namespace, which the node's dockerd cannot see. `langbot` and `langbot-box` are also pinned to the **same node** via `podAffinity` so they share this hostPath.
+
+
+ Because it relies on hostPath + same-node affinity, `langbot` does not support multi-replica horizontal scaling (same limitation as `ReadWriteOnce` PVCs). High availability requires a different architecture.
+
+
+### Connection & configuration
+
+- `langbot` connects to the Box runtime over WebSocket, using the endpoint from the ConfigMap: `BOX__RUNTIME__ENDPOINT: ws://langbot-box:5410`.
+
+
+ The in-container default hostname is `langbot_box` (with an underscore), which is **not** a valid Kubernetes DNS name. The endpoint must therefore be set **explicitly** to the valid Service name `langbot-box` — you cannot rely on the in-container default.
+
+
+- The Box runtime does **not** read its own `box.local.*` / `BOX__*` environment variables; its configuration is read from `BOX__LOCAL__*` by `langbot` and pushed via the INIT RPC. So `BOX__LOCAL__HOST_ROOT` / `DEFAULT_WORKSPACE` / `SKILLS_ROOT` / `ALLOWED_MOUNT_ROOTS` are set on the `langbot` Deployment, where `HOST_ROOT` must match the `box-root` mountPath on both sides (`/app/data/box`).
+
+### Security note
+
+Mounting the node's Docker socket grants the Box runtime (and any code executed in the sandbox) effective root on the node. Only deploy Box on nodes you trust for this workload — ideally a dedicated node pool isolated with taints/tolerations. For a stronger isolation boundary, switch `box.backend` to `e2b` (set `E2B_API_KEY`) and drop the `docker.sock` mount + hostPath. See [Sandbox configuration](/en/usage/sandbox/config).
+
+### Verify Box is ready
+
+```bash
+# Box runtime logs (should show the selected backend, e.g. "using backend: docker")
+kubectl logs -n langbot -l app=langbot-box -f
+
+# Confirm langbot connected to the Box runtime
+kubectl logs -n langbot -l app=langbot | grep -i "box runtime"
+```
+
+## When you don't need the sandbox
+
+If you do not need the sandbox, remove the `langbot-box` Deployment / Service from the manifest and set `BOX__ENABLED=false` on the `langbot` Deployment to avoid connection-failure warnings in the logs.
+
+## Further reading
+
+- [Docker Deployment](/en/deploy/langbot/docker)
+- [Sandbox docs](/en/usage/sandbox/readme) and [Sandbox configuration](/en/usage/sandbox/config)
+- [Skills docs](/en/usage/skills/readme)
+- Manifest source file: [`docker/kubernetes.yaml`](https://github.com/langbot-app/LangBot/blob/master/docker/kubernetes.yaml) in the repo
diff --git a/docs/en/deploy/langbot/manual.mdx b/docs/en/deploy/langbot/manual.mdx
new file mode 100644
index 000000000..99c3d0f4f
--- /dev/null
+++ b/docs/en/deploy/langbot/manual.mdx
@@ -0,0 +1,55 @@
+---
+title: "Manual Deployment"
+description: "Manually deploy LangBot from source. Step-by-step setup for the open-source AI bot platform on Linux, Windows and macOS."
+---
+
+## Installing the Main Program
+
+1. Go to the [Release](https://github.com/langbot-app/LangBot/releases) page to download the latest version of the zip package (recommended) `langbot-xxx-all.zip` (do not download Source Code as it does not include WebUI). Extract it and open a command line (terminal) in the extracted directory.
+
+
+
+2. Install dependencies
+
+We use [uv](https://docs.astral.sh/uv/) to manage dependencies.
+
+```bash
+pip install uv
+uv sync
+```
+
+The default installation does not include optional SeekDB support. If you need
+the SeekDB vector store or built-in embedding model, use:
+
+```bash
+uv sync --extra seekdb
+```
+
+Embedded-mode platform support depends on the available `pylibseekdb` wheels;
+Apple Silicon currently requires macOS 15 or later. All other LangBot features
+can use the default `uv sync` installation.
+
+3. Run the main program once to generate configuration files
+
+```bash
+uv run main.py
+```
+
+You will see the following message:
+
+```
+ _ ___ _
+| | __ _ _ _ __ _| _ ) ___| |_
+| |__/ _` | ' \/ _` | _ \/ _ \ _|
+|____\__,_|_||_\__, |___/\___/\__|
+ |___/
+
+⭐️Open Source: https://github.com/langbot-app/LangBot
+📖Documentation: https://langbot.app/docs
+
+The following files do not exist and have been automatically generated. Please modify the configuration files as needed and restart:
+- data/config.yaml
+...
+```
+
+You can now use Ctrl+C to exit the program and continue to the [Configure Bots](/en/usage/platforms/readme) page.
diff --git a/docs/en/deploy/langbot/one-click/1panel.mdx b/docs/en/deploy/langbot/one-click/1panel.mdx
new file mode 100644
index 000000000..a8e9015c3
--- /dev/null
+++ b/docs/en/deploy/langbot/one-click/1panel.mdx
@@ -0,0 +1,46 @@
+---
+title: "1Panel Deployment"
+description: "One-click LangBot deployment with 1Panel. Install the open-source AI chatbot platform without touching the command line."
+---
+
+Deploy LangBot with one click using [1Panel](https://www.bt.cn/new/download.html?r=dk_LangBot).
+
+## Install 1Panel
+
+> Recommended server systems (from 1Panel): Debian 12, Ubuntu 22, etc.
+
+This article assumes that the server has a public IPv4 address by default. If you are using a home machine without a public IP, you can access the relevant pages through the internal network described below.
+
+Visit [1Panel](https://www.bt.cn/new/download.html?r=dk_LangBot) and use the Linux panel installation script provided officially by 1Panel. Select the corresponding script according to your operating system.
+
+
+
+Copy the corresponding script, paste it into the server, and execute it.
+
+After waiting for a period of time, the installation of 1Panel will be completed.
+
+Then copy the `External Address` and open it in a browser.
+
+## Install LangBot
+
+Open the `App Store`, select the `AI` category, and click to install LangBot.
+
+
+
+Check the box for `External Port Access` and click Confirm.
+
+
+
+Wait for a moment, and the installation will be completed.
+
+Click `Containers` on the left side, then select the `Containers` category, and you will see the LangBot container bar.
+
+
+
+Copy the public IP address of the server, for example, `http://xxx.xxx.xxx.xxx:5300` (where xxx.xxx.xxx.xxx is the IP address of the server where 1Panel is located, and 5300 is the port number).
+
+Open the address, enter the administrator email and password, then click Initialize.
+
+After that, you can configure LangBot in the visual interface.
+
+Next, please continue to read the [Configure Messaging Platforms](/en/usage/platforms/readme) page.
diff --git a/docs/en/deploy/langbot/one-click/bt.mdx b/docs/en/deploy/langbot/one-click/bt.mdx
new file mode 100644
index 000000000..83278d988
--- /dev/null
+++ b/docs/en/deploy/langbot/one-click/bt.mdx
@@ -0,0 +1,54 @@
+---
+title: "aaPanel Deployment"
+description: "One-click LangBot deployment with aaPanel (BT Panel). Install the open-source AI bot platform through a web control panel."
+---
+
+Deploy LangBot with one click using [aaPanel](https://www.bt.cn/new/download.html?r=dk_LangBot).
+
+
+ If you already have aaPanel installed, please update to version **9.2.0** or higher
+
+
+## Installing aaPanel
+
+> Recommended server systems (from aaPanel): Debian 12, Ubuntu 22, etc.
+>
+> This document assumes you have a server with a public IPv4 address. If you're using a home machine without a public IP, you can access the relevant pages through the internal network mentioned below.
+
+Open [aaPanel](https://www.bt.cn/new/download.html?r=dk_LangBot), use the Linux panel installation script provided by aaPanel official, and select the corresponding script based on your system.
+
+
+
+Copy the corresponding script and paste it into your server to execute.
+
+## Installing LangBot
+
+After waiting for a while, aaPanel installation will be complete.
+
+You'll see a message similar to this, copy the external panel address and open it in your browser.
+
+
+
+When you first open it, you should see a popup for `Recommended Installation Suite`. You can skip this by closing it.
+
+Then click on `docker` in the sidebar. If it's your first time, you'll be prompted to install Docker and Docker Compose services. Click "Install Now" if prompted, or ignore if already installed.
+
+Then go to `Docker -> App Store`, search for `LangBot` (note the case sensitivity), click `Install`, and use the default configuration.
+
+After a short wait, you'll see a container named `langbot_XXXX` showing as `Running`.
+
+
+
+Click the red circle in the image above to view the running logs.
+
+
+
+You can see the external and internal access paths for the WebUI configuration page (visual configuration page). Copy the public address, for example `http://xxx.xxx.xxx.xxx:5300` (where xxx.xxx.xxx.xxx is your aaPanel IP, and 5300 is the port number, which may vary as shown in the image).
+
+After opening it, enter your admin email and password, then click initialize.
+
+You can then proceed with configuration in the visual interface.
+
+If you prefer to directly modify JSON configuration files, you can look at the local mapping directory shown in the image above. Go to the installation directory, where the `data` folder is used to store configuration files, and the `plugins` folder is used for plugin-related files.
+
+Next, please continue reading the [Configure Message Platform](/en/usage/platforms/readme) page.
diff --git a/docs/en/deploy/langbot/package.mdx b/docs/en/deploy/langbot/package.mdx
new file mode 100644
index 000000000..6d8e063f3
--- /dev/null
+++ b/docs/en/deploy/langbot/package.mdx
@@ -0,0 +1,41 @@
+---
+title: "Deploy with Package Manager"
+description: "Deploy LangBot with a package manager (uv/uvx). Quick install for the open-source LLM chatbot platform."
+---
+
+
+Supports Windows, Linux, Mac OS, etc. Recommended for testing environments and personal use scenarios; production-level environments please use [Docker Deployment](/en/deploy/langbot/docker.html).
+
+
+LangBot is packaged and released to PyPI. Please install [uv](https://docs.astral.sh/uv/getting-started/installation/), and then run the following command in an empty directory:
+
+```bash
+uvx langbot@latest
+```
+
+This will set the current directory as the working directory, and you can access `http://localhost:5300` to start using it.
+
+## Beta releases (optional)
+
+To try Beta 3 instead, use the command below. `--prerelease=allow` also permits prereleases of dependencies; `--refresh` refreshes cached package data.
+
+```bash
+uvx --prerelease=allow --refresh langbot==4.11.0b3
+```
+
+## Optional SeekDB support
+
+The default installation uses Chroma and does not include the SeekDB Python
+SDK or native components. Install the `seekdb` extra only when you want to use
+SeekDB as the vector store or use its built-in embedding model:
+
+```bash
+uvx --from 'langbot[seekdb]@latest' langbot
+```
+
+SeekDB embedded mode also requires a compatible `pylibseekdb` wheel. Apple
+Silicon currently requires macOS 15 or later; follow
+[oceanbase/seekdb#1324](https://github.com/oceanbase/seekdb/issues/1324) for the
+macOS 14 ARM64 support plan. Because of the current `pyseekdb` package
+metadata, the extra also fails to resolve on macOS 14 ARM64 for server-only
+use. These platform limits do not affect LangBot when SeekDB is not installed.
diff --git a/docs/en/deploy/settings.mdx b/docs/en/deploy/settings.mdx
new file mode 100644
index 000000000..0ad0abfb5
--- /dev/null
+++ b/docs/en/deploy/settings.mdx
@@ -0,0 +1,531 @@
+---
+title: "System Environment Settings"
+description: "Complete reference for LangBot config.yaml: API, concurrency, databases, storage, plugins, MCP, monitoring, and Box."
+---
+
+LangBot runtime configuration lives in `data/config.yaml`. The first startup generates it from the default template. The example below is kept aligned with [`src/langbot/templates/config.yaml`](https://github.com/langbot-app/LangBot/blob/master/src/langbot/templates/config.yaml).
+
+
+Most self-hosted deployments only need to change public URLs, databases/vector stores, object storage, and Box Runtime. Keep capacity and Cloud safety limits at their defaults unless you understand their operational impact.
+
+
+## Complete default configuration
+
+```yaml
+api:
+ port: 5300
+ webhook_prefix: 'http://127.0.0.1:5300'
+ extra_webhook_prefix: ''
+ # Canonical browser origin when WebUI and API use different origins in
+ # development (for example http://localhost:3000). Production bundled UI
+ # may leave this empty when webhook_prefix already has the browser origin.
+ # OAuth redirects trust only these server-side values, never request Host
+ # or Origin headers.
+ webui_url: ''
+ # Global API key for the HTTP service API and the MCP server. When set to a
+ # non-empty string, this key is accepted anywhere a web-UI-created API key is
+ # accepted (X-API-Key header or "Authorization: Bearer "), WITHOUT any
+ # login session and without a database record. Leave empty to disable.
+ # Keep this value secret; only enable it on trusted/internal deployments.
+ global_api_key: ''
+workspace:
+ invitations:
+ # Public WebUI origin used to build invitation links. Leave empty to
+ # use api.webui_url, then api.webhook_prefix. Set via
+ # WORKSPACE__INVITATIONS__PUBLIC_WEB_URL in container deployments.
+ public_web_url: ''
+ email:
+ # Optional invitation email delivery. Empty provider keeps
+ # invitations link-only. Supported: resend, smtp.
+ provider: ''
+ from: ''
+ timeout_seconds: 10
+ resend:
+ api_url: 'https://api.resend.com/emails'
+ # Secret. Set via WORKSPACE__INVITATIONS__EMAIL__RESEND__API_KEY.
+ api_key: ''
+ smtp:
+ host: ''
+ port: 587
+ username: ''
+ # Secret. Set via WORKSPACE__INVITATIONS__EMAIL__SMTP__PASSWORD.
+ password: ''
+ starttls: true
+ ssl: false
+command:
+ enable: true
+ prefix:
+ - '!'
+ - !
+ privilege: {}
+concurrency:
+ pipeline: 20
+ session: 1
+ # Hard admission limits for queued + running pipeline queries.
+ pending_queries: 1000
+ pending_queries_per_workspace: 100
+webhooks:
+ # Bound database materialization and per-message outbound fan-out.
+ # Existing rows above this limit remain deletable through the management
+ # API, but only this many enabled destinations are dispatched.
+ # Supports WEBHOOKS__MAX_PER_WORKSPACE (hard cap: 64).
+ max_per_workspace: 16
+ # Instance-wide request admission. Delivery fails open when every slot is
+ # occupied instead of retaining an unbounded queue of webhook tasks.
+ # Supports WEBHOOKS__MAX_INFLIGHT_REQUESTS (hard cap: 128).
+ max_inflight_requests: 16
+cloud:
+ # Operational safety ceilings for the one logical Cloud instance. These
+ # are not subscription entitlements. An authoritative directory update
+ # that would exceed them is rejected atomically rather than truncated.
+ directory:
+ # Tune downward from the measured production capacity curve. Core has
+ # an absolute safety ceiling of 5,000 active Workspaces.
+ max_active_workspaces: 1000
+ # Full snapshots contain current Workspaces only. Archived tombstones
+ # are delivered through bounded per-Workspace deltas.
+ max_snapshot_workspaces: 1000
+ # Aggregate memberships accepted in one signed snapshot or delta.
+ max_snapshot_memberships: 20000
+ # Signed control-plane envelope buffered by the closed adapter before
+ # JSON/JWS verification (32 MiB; absolute maximum 64 MiB).
+ max_response_bytes: 33554432
+proxy:
+ http: ''
+ https: ''
+system:
+ instance_id: ''
+ edition: community
+ recovery_key: ''
+ allow_modify_login_info: true
+ disabled_adapters: []
+ blocking_executor:
+ # All asyncio.to_thread work shares this process-wide bounded pool.
+ # Both running threads and queued calls are capped to prevent tenant
+ # bursts from creating an unbounded queue of retained request objects.
+ max_workers: 8
+ max_pending: 128
+ # One trusted Workspace can occupy at most this many running + queued
+ # slots. This must not exceed half of max_workers.
+ max_inflight_per_scope: 4
+ # Public outbound IP addresses of this LangBot deployment. Some platforms
+ # (e.g. WeCom, WeChat Official Account, QQ Official API) require the
+ # caller's IPs to be added to their trusted-IP / IP-whitelist settings.
+ # When set, the web UI shows these IPs on the bot config form of such
+ # adapters. Also settable via the SYSTEM__OUTBOUND_IPS env var
+ # (comma-separated). Empty list = hidden in the web UI.
+ outbound_ips: []
+ limitation:
+ max_bots: -1
+ max_pipelines: -1
+ max_extensions: -1
+ max_knowledge_bases: -1
+ # When set to a non-empty string, every pipeline is forced to use this
+ # Box sandbox-scope template regardless of its own configuration, and
+ # the per-pipeline "Sandbox Scope" selector is locked in the web UI.
+ # Used by SaaS deployments to confine a tenant to a single shared
+ # sandbox (set to '{global}'). Empty string = no restriction.
+ force_box_session_id_template: ''
+ task_retention:
+ # Keep at most this many completed async task records in memory
+ completed_limit: 200
+ # Bound progress output retained by one task, including running tasks.
+ max_log_chars: 200000
+ # Protect the shared process from user-triggered operation storms.
+ max_active_user_tasks: 256
+ max_active_user_tasks_per_workspace: 8
+ session_retention:
+ # Process-local conversation sessions are a cache, not durable history.
+ max_entries: 2000
+ max_entries_per_workspace: 200
+ idle_ttl_seconds: 86400
+ max_conversations_per_session: 20
+ max_messages_per_conversation: 100
+ websocket_retention:
+ # Bound live browser sockets and per-Workspace fan-out in the shared process.
+ max_connections: 1024
+ max_connections_per_workspace: 32
+ # Idle proxy runtimes are evicted when this process-local cache fills.
+ max_workspace_proxies: 1024
+ max_conversations_per_workspace: 200
+ max_messages_per_conversation: 100
+ conversation_idle_ttl_seconds: 86400
+ send_queue_size: 100
+ response_limits:
+ # Defense in depth for tenant-configured upstream providers.
+ max_generated_chars: 1048576
+ max_stream_chunks: 100000
+ jwt:
+ expire: 604800
+ secret: ''
+database:
+ use: sqlite
+ sqlite:
+ path: 'data/langbot.db'
+ postgresql:
+ # Optional SQLAlchemy URL (postgresql[+asyncpg]://...). When set, it
+ # overrides the structured fields and preserves TLS/query options.
+ url: ''
+ host: '127.0.0.1'
+ port: 5432
+ user: 'postgres'
+ password: 'postgres'
+ database: 'postgres'
+ # One bounded pool is shared by business data and Cloud pgvector.
+ pool_size: 10
+ max_overflow: 10
+ pool_timeout_seconds: 30
+ pool_recycle_seconds: 1800
+ # Applied only to Cloud runtime connections. The one-shot release
+ # migration uses its operator connection without these short limits.
+ statement_timeout_ms: 60000
+ lock_timeout_ms: 5000
+ idle_in_transaction_session_timeout_ms: 60000
+ cloud_migration:
+ # `langbot migrate --cloud` reads an operator-only PostgreSQL DSN from
+ # this environment variable. The operator role must differ from the
+ # runtime role above; never put its password in this file or CLI args.
+ operator_dsn_env: 'LANGBOT_CLOUD_MIGRATION_DSN'
+vdb:
+ use: chroma
+ # Bound process-local collection/index handles across all Workspaces.
+ runtime_cache_limit: 1024
+ qdrant:
+ url: ''
+ host: localhost
+ port: 6333
+ api_key: ''
+ # SeekDB is optional. Source/package deployments need the `seekdb` extra.
+ # The official Docker/Kubernetes image already includes it.
+ # Embedded-mode platform support depends on the native pylibseekdb wheels.
+ seekdb:
+ mode: embedded # 'embedded' or 'server'
+ # Embedded mode options:
+ path: './data/seekdb'
+ database: 'langbot'
+ # Server mode options (used when mode='server'):
+ host: 'localhost'
+ port: 2881
+ user: 'root'
+ password: ''
+ tenant: '' # Optional, for OceanBase server
+ milvus:
+ uri: 'http://127.0.0.1:19530'
+ token: ''
+ db_name: ''
+ pgvector:
+ # SaaS/shared-schema deployments reuse database.postgresql. OSS can
+ # keep this false when deliberately using an external pgvector DB.
+ use_business_database: false
+ # Release migrations create one partial ANN index per enabled value.
+ allowed_dimensions: [384, 512, 768, 1024, 1536]
+ host: '127.0.0.1'
+ port: 5433
+ database: 'langbot'
+ user: 'postgres'
+ password: 'postgres'
+ valkey_search:
+ host: 'localhost'
+ port: 6379 # integration tests use 6380 -> valkey/valkey-bundle:9.1.0
+ db: 0
+ password: '' # optional (toB auth)
+ username: '' # optional (ACL user, toB)
+ tls: false # optional (toB/SaaS)
+ index_algorithm: 'HNSW' # HNSW | FLAT
+ distance_metric: 'COSINE' # COSINE | L2 | IP
+ request_timeout: 5000 # per-request timeout in ms (glide default 250ms is too low for KNN)
+storage:
+ use: local
+ # Bound every object materialized into Core memory. Built-in Local/S3
+ # providers enforce this while reading (hard cap: 64 MiB).
+ max_object_read_bytes: 10485760
+ cleanup:
+ # Enable periodic cleanup of local/S3 uploaded files and old log files
+ enabled: true
+ # Cleanup check interval in hours
+ check_interval_hours: 1
+ # Root-level uploaded files older than this will be deleted
+ uploaded_file_retention_days: 7
+ # LangBot log files older than this many days will be deleted
+ log_retention_days: 3
+ # Bound per-Workspace file cleanup and diagnostic candidate lists.
+ # Supports STORAGE__CLEANUP__MAX_FILES_PER_RUN (hard cap: 10000).
+ max_files_per_run: 1000
+ s3:
+ endpoint_url: ''
+ access_key_id: ''
+ secret_access_key: ''
+ region: 'us-east-1'
+ bucket: 'langbot-storage'
+ # boto3 is synchronous; bound the number of operations delegated to
+ # worker threads so an S3 slowdown cannot saturate the process.
+ max_concurrency: 16
+plugin:
+ enable: true
+ runtime_ws_url: 'ws://langbot_plugin_runtime:5400/control/ws'
+ enable_marketplace: true
+ display_plugin_debug_url: 'ws://localhost:5401/plugin/debug/ws'
+ worker:
+ # Instance-wide maximum for every plugin installation. Plugin
+ # manifests cannot raise or override these limits.
+ max_cpus: 1.0
+ max_memory_mb: 512
+ max_pids: 128
+ max_open_files: 256
+ max_file_size_mb: 512
+ # Instance-wide admission budgets. The effective worker count is the
+ # lowest of max_workers, max_total_cpus/max_cpus and
+ # max_total_memory_mb/max_memory_mb.
+ max_workers: 16
+ max_total_cpus: 8.0
+ max_total_memory_mb: 8192
+ # Includes disabled and historical installation fences retained to
+ # reject stale desired-state replay.
+ max_installations: 10000
+ # Restart storms are globally serialized by default. Repeated
+ # unexpected exits within the configured window open a Runtime-wide
+ # circuit; one half-open probe must remain stable before other
+ # installations may restart.
+ max_concurrent_restarts: 1
+ restart_failure_threshold: 8
+ restart_failure_window_seconds: 30.0
+ restart_circuit_open_seconds: 60.0
+ # Cloud shared Runtime sets this to true and fails closed unless
+ # delegated cgroup v2 controllers are available.
+ require_hard_limits: false
+ binary_storage:
+ # Max bytes for a single plugin binary storage value
+ max_value_bytes: 10485760
+mcp:
+ # Bound instance-wide MCP startup and shutdown bursts. Supports
+ # MCP__LIFECYCLE_CONCURRENCY and is clamped to a maximum of 128.
+ lifecycle_concurrency: 16
+ stdio:
+ # Independent gate for local stdio MCP transports. Cloud v2 sets
+ # MCP__STDIO__ENABLED=false even when Box Runtime is available.
+ enabled: true
+monitoring:
+ query_limits:
+ # Maximum records materialized by one paginated monitoring request.
+ # Supports MONITORING__QUERY_LIMITS__PAGE_ROWS (hard cap: 5000).
+ page_rows: 1000
+ # CSV exports are currently assembled in memory. Keep this lower than
+ # the historical 100000-row default (hard cap: 50000).
+ export_rows: 10000
+ # Maximum related records returned by one session/message detail view
+ # (hard cap: 10000). Aggregate statistics remain database-computed.
+ detail_rows: 2000
+ # Token charts are grouped in SQL and return only the newest buckets
+ # (hard cap: 10000). Supports an environment variable override.
+ timeseries_buckets: 1000
+ # Bound high-offset scans that can otherwise monopolize PostgreSQL CPU
+ # (hard cap: 10000000).
+ max_offset: 1000000
+ auto_cleanup:
+ # Enable automatic cleanup of expired monitoring records
+ enabled: true
+ # Retention period in days, records older than this will be deleted
+ retention_days: 30
+ # Cleanup check interval in hours
+ check_interval_hours: 1
+ # Number of expired rows to delete per table batch
+ delete_batch_size: 1000
+ # Prevent one large Workspace backlog from monopolizing PostgreSQL.
+ # Supports MONITORING__AUTO_CLEANUP__MAX_BATCHES_PER_TABLE_PER_RUN.
+ max_batches_per_table_per_run: 4
+box:
+ # Master switch for the Box sandbox runtime. When false, LangBot does NOT
+ # attempt to connect to a remote Box runtime nor start a local stdio Box
+ # subprocess. Disabling Box also disables every feature that depends on it:
+ # the native sandbox tools (exec/read/write/edit/glob/grep), the activate
+ # skill tool, skill add/edit, and stdio-mode MCP servers. Skills can still
+ # be listed read-only and http/sse MCP servers continue to work.
+ enabled: true
+ backend: 'local' # 'local' (Docker/nsjail), 'docker', 'nsjail', or 'e2b'. Can be written via BOX__BACKEND.
+ runtime:
+ # LANGBOT_BOX_CONTROL_TOKEN is optional for OSS external WebSocket
+ # runtimes. To protect an exposed endpoint, set the same strong secret
+ # in both LangBot and Box. Keep it out of this config file.
+ endpoint: '' # External Box Runtime base URL, e.g. 'ws://127.0.0.1:5410'. Leave empty for local auto-managed runtime.
+ limits:
+ max_sessions: 64
+ max_managed_processes: 64
+ max_completed_processes: 256
+ # Core scans a Workspace before and after quota-enforced executions.
+ # Fail closed instead of repeatedly walking an inode bomb.
+ # Supports BOX__LIMITS__MAX_WORKSPACE_ENTRIES (hard cap: 1000000).
+ max_workspace_entries: 100000
+ # Retained admission fences prevent replay after entitlement expiry or
+ # revocation. Fail closed before that monotonic state can grow without
+ # bound; Cloud may override this with BOX__LIMITS__MAX_ADMISSION_RECORDS.
+ max_admission_records: 100000
+ max_rpc_file_bytes: 20971520
+ # Cloud v2 overrides these values through the instance config/environment.
+ # OSS keeps admission disabled and preserves the existing multi-session
+ # local behavior. These limits are Runtime-owned and cannot be relaxed by
+ # a pipeline, Workspace entitlement, or tool call.
+ admission:
+ required: false
+ logical_session_id: 'global'
+ required_backend: 'nsjail'
+ max_sessions: 1
+ max_managed_processes: 0
+ max_grant_ttl_sec: 300
+ max_timeout_sec: 120
+ cpus: 1.0
+ memory_mb: 512
+ pids_limit: 128
+ read_only_rootfs: true
+ # OSS admission-disabled mode uses 0 for unlimited compatibility.
+ # Cloud bootstrap requires a positive hard quota.
+ workspace_quota_mb: 0
+ readiness_cache_sec: 15
+ local:
+ profile: 'default'
+ image: '' # Custom local sandbox image. Leave empty to use the profile default.
+ host_root: './data/box' # Base host directory for local workspace mounts. Docker deployments should override this with an absolute host path.
+ default_workspace: '' # Defaults to '/default'. Relative paths are resolved under host_root.
+ skills_root: 'skills' # Box-owned skill package directory. Relative paths are resolved under host_root.
+ allowed_mount_roots: # Defaults to [''] when left empty.
+ - './data/box'
+ - '/tmp'
+ workspace_quota_mb: null # Optional disk quota override (>= 0). null = profile default.
+ # Default nsjail cgroup memory limit for each MCP stdio server process, in MB.
+ # Node.js MCP servers (npx/bunx) need more memory than Python ones because V8
+ # and WebAssembly modules (e.g. undici llhttp) reserve large virtual address
+ # space at startup. Setting this too low causes processes to be killed with
+ # return_code=137 (OOM kill); the symptom is "Box managed process exited
+ # unexpectedly" in the logs. Raise on machines with ample RAM; lower only if
+ # you run exclusively Python (uvx) MCP servers.
+ # Can also be set via BOX__DEFAULT_MEMORY_MB. Default: 1536.
+ default_memory_mb: 1536
+ docker:
+ cpu_limit_enabled: true # When false, Docker sandbox containers are started without --cpus. Memory and PID limits still apply.
+ e2b:
+ api_key: '' # Can also be set via E2B_API_KEY env var.
+ api_url: '' # Custom API URL for self-hosted deployments.
+ template: '' # Default template ID (e.g. 'base', 'python-3.11').
+space:
+ # Space service URL for OAuth and API
+ url: 'https://space.langbot.app'
+ # Space API URL for model requests (MaaS)
+ models_gateway_api_url: 'https://api.langbot.cloud/v1'
+ # OAuth authorization page URL (user will be redirected here)
+ oauth_authorize_url: 'https://space.langbot.app/auth/authorize'
+ disable_models_service: false
+ disable_telemetry: false
+```
+
+## Configuration groups
+
+### API, WebUI, and invitations
+
+- `api.port` is the HTTP API and WebUI port. `api.webhook_prefix` is the public base URL used to generate platform callback URLs; production deployments normally set it to the HTTPS reverse-proxy origin.
+- Set `api.webui_url` when the browser UI and API use different origins. OAuth redirects trust only this server-side value and `webhook_prefix`, never request `Host` or `Origin` headers.
+- `api.global_api_key` authenticates the HTTP Service API and built-in MCP server through `X-API-Key` or `Authorization: Bearer`, without a login session or a database-backed `lbk_` key. Empty means disabled.
+- `workspace.invitations.public_web_url` controls invitation links and falls back to `api.webui_url`, then `api.webhook_prefix`. Email delivery is optional; choose `resend` or `smtp`, or leave `provider` empty for link-only invitations.
+
+
+Treat the global API key, JWT secret, database credentials, S3 credentials, email-provider secrets, and E2B key as secrets. Prefer environment variables in production, never commit real values, and expose authenticated endpoints only over HTTPS.
+
+
+### Admission and capacity limits
+
+- `concurrency` bounds running and queued pipeline work globally and per Workspace.
+- `webhooks` bounds enabled destinations per Workspace and instance-wide outbound requests. Full request admission fails open rather than retaining an unbounded task queue.
+- `cloud.directory` contains operational safety ceilings for one logical Cloud instance, not subscription entitlements. Oversized authoritative directory updates are rejected atomically instead of being truncated. Most self-hosted deployments should keep these defaults.
+- `system.blocking_executor`, `task_retention`, `session_retention`, `websocket_retention`, and `response_limits` bound process-local workers, cached records, sockets, and upstream output.
+- Values under `system.limitation` are instance limits; `-1` means unlimited. `force_box_session_id_template` is intended for SaaS sandbox confinement and should remain empty for normal self-hosting.
+
+### Databases and vector stores
+
+- `database.use` selects SQLite or PostgreSQL. A non-empty `database.postgresql.url` overrides the structured connection fields and preserves TLS/query options.
+- PostgreSQL pool and timeout settings bound shared runtime resources. `database.cloud_migration.operator_dsn_env` names the environment variable containing the operator-only migration DSN; keep that role separate from the runtime role.
+- `vdb.use` selects the vector backend. Configure only the selected backend. `runtime_cache_limit` bounds process-local collection/index handles.
+- `vdb.use: seekdb` requires `uv sync --extra seekdb` for a source deployment or `uvx --from 'langbot[seekdb]@latest' langbot` for a package deployment. The official Docker/Kubernetes image already includes the dependency and needs no additional build argument.
+- `vdb.pgvector.use_business_database` reuses `database.postgresql`; `allowed_dimensions` controls the partial ANN indexes created by release migrations.
+- Valkey Search requires a Valkey server with the Search module, such as `valkey/valkey-bundle:9.1.0`.
+
+### Storage, plugins, MCP, and monitoring
+
+- `storage.max_object_read_bytes` caps objects materialized into Core memory. Cleanup limits bound file scans, and `s3.max_concurrency` bounds synchronous boto3 operations delegated to worker threads.
+- `plugin.worker` defines hard per-installation and instance-wide budgets. Plugin manifests cannot raise them. Restart-window settings suppress Runtime restart storms.
+- `mcp.lifecycle_concurrency` bounds MCP startup/shutdown bursts. `mcp.stdio.enabled` can disable local stdio transports without disabling HTTP/SSE MCP servers.
+- Monitoring query and cleanup limits prevent large pages, exports, offsets, or backlogs from monopolizing memory or PostgreSQL.
+
+### Box sandbox
+
+- `box.enabled` is the master switch. Disabling it also disables native sandbox tools, Skill add/edit, and stdio MCP, while read-only Skill listing and HTTP/SSE MCP remain available.
+- `box.backend` selects `local`, `docker`, `nsjail`, or `e2b`; `runtime.endpoint` connects an external WebSocket Runtime.
+- `box.limits` bounds sessions, processes, workspace scans, retained admission fences, and RPC file size.
+- `box.admission` is the Cloud v2 hard-admission policy. OSS defaults to `required: false`; pipelines, Workspace entitlements, and tool calls cannot relax Runtime-owned limits.
+- `box.local` controls workspace roots and mount allowlists. In Docker deployments, use an absolute `host_root` that the Box container can mount.
+- `box.default_memory_mb` is the default nsjail cgroup limit for each stdio MCP process. Node.js MCP servers usually need more memory than Python servers; too little commonly produces exit code `137`.
+
+### LangBot Space
+
+`space.url`, `models_gateway_api_url`, and `oauth_authorize_url` control Space OAuth/API and MaaS endpoints. The two `disable_*` flags independently disable model service use and telemetry.
+
+## Environment-variable overrides
+
+Convert a nested key to uppercase and join levels with double underscores:
+
+- `API__PORT` → `api.port`
+- `WORKSPACE__INVITATIONS__PUBLIC_WEB_URL` → `workspace.invitations.public_web_url`
+- `CONCURRENCY__PENDING_QUERIES_PER_WORKSPACE` → `concurrency.pending_queries_per_workspace`
+- `DATABASE__POSTGRESQL__POOL_SIZE` → `database.postgresql.pool_size`
+- `STORAGE__CLEANUP__MAX_FILES_PER_RUN` → `storage.cleanup.max_files_per_run`
+- `PLUGIN__WORKER__MAX_TOTAL_MEMORY_MB` → `plugin.worker.max_total_memory_mb`
+- `MCP__STDIO__ENABLED` → `mcp.stdio.enabled`
+- `BOX__DEFAULT_MEMORY_MB` → `box.default_memory_mb`
+
+At startup, LangBot applies these overrides and writes the resulting configuration to `data/config.yaml`.
+
+
+In Docker deployments, set unified `BOX__*` variables on the `langbot` service. LangBot sends Box configuration to `langbot_box` through INIT RPC; variables set directly on `langbot_box` are not read.
+
+
+## Optional telemetry
+
+Telemetry is enabled by default and can be disabled.
+
+Set the following in the existing `space` section of `data/config.yaml`, preserve other settings, and restart LangBot:
+
+```yaml
+space:
+ disable_telemetry: true
+```
+
+This switch disables product telemetry (including heartbeats and execution records) and survey fetching. Use an unquoted YAML boolean. To restore the default, set it to `false` and restart. Cloud Plugin Runtime operational health reporting is controlled separately by `plugin.runtime_ops.enabled`.
+
+If `SPACE__DISABLE_TELEMETRY` is set in your deployment, it overrides the file at startup; update or remove it too. Recreate containers when changing their environment. In Cloud, the instance operator controls this setting for every Workspace in the instance. It does not disable the bot or change privacy settings of messaging platforms, model providers or plugins.
+
+### Per-event execution chains
+
+Current 4.11 execution telemetry defaults to full reporting of eligible executions, covering platform events, routing, Pipeline / Agent / plugin event processors, and the platform API and tool calls they cause. Each completed node generates a record, followed by a closure record when the execution ends; Space reconstructs the chain. These are the defaults in the same `space` section; restart after changing them:
+
+Platform events without a matching business route, or ignored by a `discard` rule with no matching plugin subscription, upload no execution records. Local logs and monitoring keep their existing behavior. Matching subscriptions, valid interaction resumptions and independent WebUI/API/Pipeline calls remain eligible, as do unavailable targets, execution failures or Pipeline filtering after a route matches. Eligibility is checked before sampling; neither Cloud's `all` nor failure fallback bypasses it. A Core upgrade is required.
+
+```yaml
+space:
+ execution_trace: all # off | failures | sampled | all
+ execution_trace_sample: 20 # sampled: retain about 1/N successful executions by event hash
+ telemetry_flush_seconds: 180 # Execution record buffer flush interval, in seconds
+```
+
+The community edition supports these modes:
+
+| Mode | Reporting behavior |
+|---|---|
+| `all` | Default; records nodes and closure records for every eligible execution |
+| `sampled` | Makes one stable hash decision from the event identity for all records of that execution; excluded executions that fail still report a closure, without recovering skipped nodes |
+| `failures` | Omits nodes for ordinary executions; reports closures only for failure, cancellation, timeout or a recorded chain failure reason |
+| `off` | Reports neither nodes nor closures; no independent window counters continue, while heartbeats remain controlled by `disable_telemetry` |
+
+WebUI debug runs are retained with a debug flag in `all`, `sampled` and `failures`; `off` or `disable_telemetry: true` stops their upload. **Cloud always uses `all` while product telemetry is enabled and does not apply the sampling mode configured above**; the instance operator can still disable product telemetry with the main switch.
+
+`execution_trace_sample` accepts integers from 1 to 100000; `telemetry_flush_seconds` accepts integers from 1 to 86400. Invalid values fall back to 20 and 180 respectively, and an invalid mode falls back to `all`. Sampling does not select exactly every N-th execution in sequence.
+
+Each flush sends at most 128 records and the buffer holds at most 512. Failed sends remain buffered for retries; a full buffer drops the oldest records, so full reporting does not guarantee complete delivery. Active Workspaces first send a heartbeat about 30 seconds after startup, then daily in ordinary deployments or every 5 minutes in Cloud runtime. Raw execution records are cleaned up in batches using a 30-day window; backlogs can delay deletion.
+
+See [Data Collection Policy](../insight/data-collection-policy).
diff --git a/docs/en/deploy/update.mdx b/docs/en/deploy/update.mdx
new file mode 100644
index 000000000..64e0610c0
--- /dev/null
+++ b/docs/en/deploy/update.mdx
@@ -0,0 +1,38 @@
+---
+title: "Update LangBot"
+description: "Update LangBot to the latest version. Upgrade your self-hosted AI chatbot platform safely with these steps."
+---
+
+## Using Package Manager
+
+Please execute in the directory you deployed LangBot again:
+
+```bash
+uvx langbot@latest
+```
+
+This command will download and start the latest version of LangBot.
+
+## Using Docker (or one-click deployment based on Docker)
+
+Please execute in the directory you cloned LangBot:
+
+```bash
+git pull
+```
+
+Please execute in the `docker/` directory:
+
+```bash
+docker compose up --force-recreate --pull always -d
+```
+
+This command will pull the latest LangBot image and rebuild the container.
+
+
+4.3.0 version changed the content and location of the `docker-compose.yaml` file, if you updated from a previous version, please [redploy according to the documentation](/en/deploy/langbot/docker).
+
+
+## Manual Deployment
+
+Download the latest release's `langbot--all.zip` from the Assets section on the [Releases](https://github.com/langbot-app/LangBot/releases) page, extract it to the original deployment directory, and restart.
diff --git a/docs/en/develop/agent-context.mdx b/docs/en/develop/agent-context.mdx
new file mode 100644
index 000000000..4da86e89e
--- /dev/null
+++ b/docs/en/develop/agent-context.mdx
@@ -0,0 +1,190 @@
+---
+title: "AI Assistant Context"
+description: "A single, copy-paste-the-whole-page context for AI coding assistants: LangBot's directory layout, how components are organized, how they connect at runtime, and how to set up the dev environment."
+---
+
+
+Copy the **entire content** of this page and paste it to your AI assistant. It will then understand LangBot's overall architecture, how each component is organized, how they connect at runtime, and how to configure the dev environment — without you having to explain it piece by piece.
+
+
+This page mirrors the `AGENTS.md` (with `CLAUDE.md` as a symlink) at each repository root, and serves as LangBot's "one-page onboarding" for developers and AI assistants.
+
+## Project Overview
+
+LangBot is an open-source, LLM-native instant-messaging bot development platform. It provides an out-of-the-box IM bot development experience with built-in Agent, RAG, MCP and other LLM application capabilities, supports mainstream global IM platforms, and exposes rich APIs for custom development.
+
+LangBot has a comprehensive web frontend — almost every operation can be performed through it.
+
+- **Backend**: Python (`>=3.11,<4.0`), dependencies managed by `uv`; the web framework is Quart (the async flavour of Flask). Both the HTTP API and the pre-built frontend are served by the backend on `http://127.0.0.1:5300`.
+- **Frontend**: `web/` is a **Vite + React Router 7 + shadcn/ui + Tailwind CSS** SPA, managed by `pnpm` (note: this is **not** Next.js — the `dev` script is literally `vite`).
+- **Plugin system**: The Plugin SDK, CLI (`lbp`), Plugin Runtime, Box (sandbox) Runtime, and the entity/API definitions shared between LangBot and plugins all live in a separate repository: [`langbot-plugin-sdk`](https://github.com/langbot-app/langbot-plugin-sdk). LangBot depends on it via the version-pinned `langbot-plugin` package in `pyproject.toml`.
+
+## Repository Layout
+
+```
+LangBot/
+├── main.py # Entrypoint shim -> langbot.__main__.main()
+├── pyproject.toml # Python project + deps (uv), pins langbot-plugin==
+├── src/langbot/
+│ ├── __main__.py # Real entrypoint, CLI args (--standalone-runtime / --standalone-box / --debug)
+│ ├── pkg/ # Core backend package
+│ │ ├── api/ # HTTP API controllers + services (Quart)
+│ │ ├── core/ # App bootstrap, stages, task manager
+│ │ ├── platform/ # IM platform adapters, bot managers, session managers
+│ │ ├── provider/ # LLM providers, requesters, tool providers
+│ │ ├── pipeline/ # Pipelines, stages, query pool
+│ │ ├── plugin/ # Bridge to the plugin runtime (connector.py / handler.py)
+│ │ ├── box/ # Code-sandbox subsystem (Docker / nsjail / E2B backends)
+│ │ ├── skill/ # Skill subsystem
+│ │ ├── rag/ , vector/ # RAG + vector store
+│ │ ├── command/ # Built-in commands
+│ │ ├── persistence/ # ORM models + Alembic migrations (SQLite & PostgreSQL)
+│ │ ├── storage/ # Object/file storage abstractions
+│ │ ├── config/, entity/, discover/, utils/, telemetry/, survey/
+│ ├── libs/ # Vendored SDKs (qq_official_api, wecom_api, etc.)
+│ └── templates/ # Config/component templates (e.g. templates/config.yaml)
+├── web/ # Frontend SPA (Vite + React Router 7 + shadcn + Tailwind)
+└── docker/ # docker-compose deployment files
+```
+
+## How Components Are Organized
+
+The core backend package `src/langbot/pkg/` is split into loosely-coupled submodules by responsibility:
+
+| Module | Responsibility |
+| --- | --- |
+| `core` | Application lifecycle: startup stages load config, connect the DB, bring up subsystems in order, and manage background tasks. |
+| `platform` | Adapters for each IM platform (Discord, Telegram, QQ, WeCom, Lark, etc.); send/receive messages, manage bots and sessions. |
+| `provider` | LLM providers and requesters (OpenAI-compatible and native APIs), plus tool providers callable by the Agent. |
+| `pipeline` | The message-processing pipeline: routes one message through trigger, AI processing, output, and safety stages. |
+| `plugin` | Bridge between the LangBot main process and the plugin runtime — connect, exchange actions, forward events. |
+| `box` | Code-sandbox subsystem providing isolated code execution for skills/tools; selects Docker / nsjail / E2B by availability. |
+| `skill` / `rag` / `vector` | Skill, retrieval-augmented generation, and vector-store capabilities. |
+| `persistence` | ORM entity definitions and Alembic migrations; a single set of scripts works on both SQLite and PostgreSQL. |
+
+On the plugin side (defined in `langbot-plugin-sdk`, generated by `lbp comp`), components are organized around a single `BasePlugin`. Six component types are currently supported:
+
+- **Command**: user-triggered actions (e.g. `!weather tokyo`).
+- **Tool**: functions the LLM calls during Agent execution (e.g. fetch weather, query a database).
+- **EventListener**: handlers for events in the message pipeline (e.g. auto-reply, content filtering).
+- **KnowledgeEngine**: a custom knowledge-base retrieval/integration implementation used by RAG.
+- **Parser**: custom parsing of messages/content.
+- **Page**: a custom web page provided by the plugin, embeddable in the LangBot admin panel.
+
+Each plugin runs in its own process, with its lifecycle managed by the plugin runtime (discover → install deps → load → initialize → register components → ready → terminate).
+
+## How Things Connect at Runtime
+
+```
+┌──────────────┐ HTTP/API ┌──────────────┐
+│ Browser/Web │ ────────────► │ │
+│ (Vite SPA) │ :3000/origin │ LangBot │
+└──────────────┘ │ backend │
+ │ (Quart) │
+ ┌───────────────────────────┤ :5300 ├─────────────────────────┐
+ │ stdio or WebSocket └──────────────┘ stdio or WebSocket │
+ ▼ ▼
+┌──────────────┐ ┌──────────────┐
+│ Plugin │ separate process, │ Box │ code sandbox
+│ Runtime │ launches each plugin │ Runtime │ Docker/nsjail/E2B
+│ :5400 / :5401│ │ :5410 │
+└──────────────┘ └──────────────┘
+```
+
+- **Frontend ↔ Backend**: In dev, the frontend runs standalone on `:3000` and reaches the backend `:5300` via `VITE_API_BASE_URL` in `web/.env`; in production the frontend is pre-built into static files served by the backend on the same origin.
+- **Backend ↔ Plugin Runtime**:
+ - When LangBot is **started directly** (not in a container), the backend **spawns** the runtime itself and talks over **stdio** (lightweight/personal use). stdio **cannot auto-reconnect** — after a disconnect you must restart LangBot; a common failure is an **orphan runtime process** from a previous backend still holding `5400`/`5401` — kill it and restart.
+ - When LangBot runs in a **container**, it connects to a standalone runtime over **WebSocket** (production). Control port defaults to `5400`, debug port to `5401`. Config: `plugin.runtime_ws_url` in `data/config.yaml` (e.g. `ws://langbot_plugin_runtime:5400/control/ws`).
+- **Backend ↔ Box Runtime**: The Box subsystem connects to the Box runtime over a control channel (default port `5410`), which executes sandboxed code in Docker / nsjail / E2B. Config (`box:` section of `data/config.yaml`): `box.enabled` (master switch), `box.backend` (`'local'`/`'docker'`/`'nsjail'`/`'e2b'`), `box.runtime.endpoint` (external Box runtime URL, e.g. `ws://127.0.0.1:5410`; empty = local auto-managed). As with the plugin runtime, set that endpoint and start with `--standalone-box` to connect to an external Box runtime.
+- The full guide for debugging the runtime, CLI and SDK is in [Debugging Plugin Runtime, CLI, SDK](/en/develop/plugin-runtime); detailed flags and architecture are in the `langbot-plugin-sdk` repo's `AGENTS.md`.
+
+## Development Environment Setup
+
+Full guide: [Development Configuration](/en/develop/dev-config). Summary:
+
+### Backend
+
+```bash
+pip install uv
+uv sync --dev # uv creates a .venv/ for you; point your editor's interpreter at it
+uv run main.py # serves API + frontend on http://127.0.0.1:5300
+```
+
+On first run the config file is generated at `data/config.yaml`. SQLite is the default (zero setup); PostgreSQL is supported. Migrations run automatically on startup.
+
+### Frontend
+
+Requires Node.js and [pnpm](https://pnpm.io/installation).
+
+```bash
+cd web
+cp .env.example .env # Windows: copy .env.example .env
+pnpm install
+pnpm dev # http://127.0.0.1:3000 (npm install / npm run dev also work)
+```
+
+`pnpm dev` reads `VITE_API_BASE_URL` from `web/.env` so the dev frontend can reach the backend on `:5300`.
+
+### Code Formatting
+
+CI runs lint + format checks. Install the pre-commit hooks so the same checks run locally before each commit:
+
+```bash
+uv run pre-commit install
+```
+
+### Database Migrations
+
+After changing ORM models, generate a migration:
+
+```bash
+# Run from the project root (requires data/config.yaml)
+uv run python -m langbot.pkg.persistence.alembic_runner autogenerate "describe your change"
+```
+
+`autogenerate` detects schema changes (add/drop columns and tables, type changes), but **data migrations** (e.g. mutating JSON field contents) must be hand-written into the generated script. `env.py` sets `render_as_batch=True`, so SQLite's ALTER TABLE limits are handled automatically — no per-database branching needed. Migrations execute automatically on startup.
+
+## Development Standards
+
+- LangBot is a global project: **all code comments and docstrings must be in English**, and every user-facing string must support **i18n** (`en_US` + `zh_Hans` at minimum, plus `ja_JP` where the repo already has it).
+- LangBot is adopted in both toC and toB scenarios — always consider compatibility and security.
+- **Commit message format**: `(): `
+ - `type`: one of `feat`, `fix`, `docs`, `style`, `refactor`, `perf`, `test`, `chore`, etc.
+ - `scope`: the affected package/module/file/class.
+ - `subject`: a concise description of the change.
+
+## Agent-Facing Surfaces (MCP + Skills)
+
+LangBot is built to be **agent-friendly**, with three agent-facing surfaces that
+are kept in lockstep with the HTTP API:
+
+1. **MCP server** — `src/langbot/pkg/api/mcp/` exposes a curated subset of the API
+ as MCP tools at `/mcp` (API-key authenticated, including `api.global_api_key`
+ from config.yaml). `server.py` defines the tools (calling the service layer
+ directly); `mount.py` is the ASGI dispatcher.
+2. **In-repo skills** — the `skills/` directory is the **single source of truth**
+ for all LangBot agent skills (plugin dev, core dev, deployment, e2e, MCP
+ operations). Docs and the landing page link here rather than copying content.
+3. **API-key auth** — `api.global_api_key` (config.yaml) authenticates the API and
+ MCP without a login session; see `docs/API_KEY_AUTH.md`.
+
+> **Maintenance rule (important).** When you add, remove, or change an HTTP API
+> endpoint that should be agent-accessible, you MUST update **both** the matching
+> MCP tool in `src/langbot/pkg/api/mcp/server.py` **and** the relevant skill under
+> `skills/` (especially `skills/skills/langbot-mcp-ops`). API, MCP tools, and
+> skills are one system — drift between them is a bug.
+
+## Some Principles
+
+- Keep it simple, stupid.
+- Entities should not be multiplied unnecessarily.
+- 八荣八耻 (Eight Honors and Eight Shames):
+
+ Shame in guessing interfaces; honor in carefully checking them.
+ Shame in vague execution; honor in seeking confirmation.
+ Shame in assuming business logic; honor in human confirmation.
+ Shame in inventing interfaces; honor in reusing existing ones.
+ Shame in skipping verification; honor in proactive testing.
+ Shame in breaking architecture; honor in following conventions.
+ Shame in pretending to understand; honor in honest ignorance.
+ Shame in blind changes; honor in careful refactoring.
diff --git a/docs/en/develop/comp-arch.mdx b/docs/en/develop/comp-arch.mdx
new file mode 100644
index 000000000..ae94779a8
--- /dev/null
+++ b/docs/en/develop/comp-arch.mdx
@@ -0,0 +1,5 @@
+---
+title: "Component Architecture"
+---
+
+
diff --git a/docs/en/develop/dev-config.mdx b/docs/en/develop/dev-config.mdx
new file mode 100644
index 000000000..47ebcc63d
--- /dev/null
+++ b/docs/en/develop/dev-config.mdx
@@ -0,0 +1,191 @@
+---
+title: "Development Configuration"
+---
+
+LangBot is divided into frontend and backend. The frontend is developed using Vite + React Router + shadcn, and the backend is developed using Quart (an asynchronous version of Flask).
+
+## Backend
+
+The code is located in the `pkg` directory and is started by the `main.py` file in the root directory.
+
+Install dependencies, we use uv to manage dependencies.
+
+```bash
+pip install uv
+uv sync --dev
+```
+
+Start the backend
+
+```bash
+uv run main.py
+```
+
+At this point, the configuration file will be automatically generated in the `data/config.yaml` file.
+
+## Frontend
+
+The code is located in the `web` directory and requires Node.js and [pnpm](https://pnpm.io/installation).
+
+Copy `.env.example` to `.env` and fill in the values.
+
+- Usage in Linux and other environments
+
+```bash
+cp .env.example .env
+```
+
+- Usage in Windows environments
+
+```bash
+copy .env.example .env
+```
+
+Install dependencies and start the frontend
+
+```bash
+pnpm install
+pnpm dev
+
+# If pnpm is not installed, you can also use npm to solve dependencies and start
+npm install
+npm run dev
+```
+
+Then according to the output information, visit `http://127.0.0.1:3000` to view the standalone frontend page.
+
+
+
+In production environments, the frontend will be precompiled into static files and provided by the backend, and the frontend will automatically access the backend address on the same domain.
+
+
+## Code Formatting
+
+The repository contains lint and format check workflows, and your code will be automatically checked when you push it. Please configure pre-commit to check your code locally before submitting.
+
+```bash
+uv run pre-commit install
+```
+
+## API Documentation
+
+We will write API documentation in APIFox before developing each interface. Please refer to [API Documentation(Chinese)](https://ok52vhsenr.apifox.cn/).
+
+## Database Migrations
+
+LangBot uses [Alembic](https://alembic.sqlalchemy.org/) to manage database migrations, supporting both SQLite and PostgreSQL seamlessly without database-specific branching.
+
+### Migration File Location
+
+```
+src/langbot/pkg/persistence/alembic/versions/
+```
+
+### Creating a New Migration
+
+The recommended way is to use **autogenerate**, which compares ORM models against the database schema and generates a migration script:
+
+```bash
+# Run from the project root (requires data/config.yaml)
+uv run python -m langbot.pkg.persistence.alembic_runner autogenerate "describe your changes"
+```
+
+The generated file will appear in `src/langbot/pkg/persistence/alembic/versions/`. Review and edit the generated script to confirm the changes are correct before committing.
+
+
+Autogenerate can automatically detect column additions/removals, table changes, type changes, etc. However, for **data migrations** (e.g., modifying JSON field content), you need to manually add code to the generated script.
+
+
+You can also create migration files manually, following the naming convention `NNNN_description.py`:
+
+```python
+"""Describe your migration
+
+Revision ID: 0003_add_bot_description
+Revises: 0002_sample
+Create Date: 2026-04-08
+"""
+from alembic import op
+import sqlalchemy as sa
+
+revision = '0003_add_bot_description'
+down_revision = '0002_sample' # Points to the previous migration's revision
+branch_labels = None
+depends_on = None
+
+
+def upgrade() -> None:
+ # Schema change (works on both SQLite and PostgreSQL)
+ op.add_column('bots', sa.Column('description', sa.String(512), server_default=''))
+
+
+def downgrade() -> None:
+ op.drop_column('bots', 'description')
+```
+
+### Migration Patterns
+
+
+
+```python
+def upgrade() -> None:
+ # Add a column
+ op.add_column('table_name', sa.Column('new_col', sa.String(255), server_default=''))
+
+ # Create a new table
+ op.create_table(
+ 'new_table',
+ sa.Column('id', sa.Integer, primary_key=True, autoincrement=True),
+ sa.Column('name', sa.String(255), nullable=False),
+ )
+```
+
+
+`env.py` sets `render_as_batch=True`, which makes Alembic automatically handle SQLite's ALTER TABLE limitations (via temporary table rebuild). No need to branch on database type.
+
+
+
+
+```python
+import json
+
+def upgrade() -> None:
+ conn = op.get_bind()
+ rows = conn.execute(sa.text("SELECT uuid, config FROM pipelines")).fetchall()
+ for row in rows:
+ config = json.loads(row[1]) if isinstance(row[1], str) else row[1]
+ config.setdefault('ai', {})['new_key'] = 'default_value'
+ conn.execute(
+ sa.text("UPDATE pipelines SET config = :cfg WHERE uuid = :uuid"),
+ {"cfg": json.dumps(config), "uuid": row[0]}
+ )
+```
+
+
+
+### How It Works
+
+Migrations run automatically when LangBot starts — no manual commands needed:
+
+1. On first startup, the baseline version is automatically stamped (marking the existing database)
+2. On subsequent startups, all pending migrations are applied (`alembic upgrade head`)
+
+### CI Testing
+
+The repository includes a `test-migrations.yml` workflow that automatically tests migration scripts on both SQLite and PostgreSQL when `persistence/` related files change.
+
+### CLI Tool
+
+```bash
+# Autogenerate migration (compare ORM models against DB)
+uv run python -m langbot.pkg.persistence.alembic_runner autogenerate "description"
+
+# Upgrade database
+uv run python -m langbot.pkg.persistence.alembic_runner upgrade
+
+# Show current revision
+uv run python -m langbot.pkg.persistence.alembic_runner current
+
+# Stamp revision (without running migrations)
+uv run python -m langbot.pkg.persistence.alembic_runner stamp head
+```
diff --git a/docs/en/develop/plugin-runtime.mdx b/docs/en/develop/plugin-runtime.mdx
new file mode 100644
index 000000000..f1652fd8a
--- /dev/null
+++ b/docs/en/develop/plugin-runtime.mdx
@@ -0,0 +1,149 @@
+---
+title: "Debugging Plugin Runtime, CLI, SDK"
+---
+
+
+ Plugin Runtime, CLI, SDK are open sourced at: https://github.com/langbot-app/langbot-plugin-sdk
+
+
+Since LangBot depends on entities defined in langbot-plugin-sdk, we recommend opening VS Code in a new directory, placing both LangBot and langbot-plugin-sdk (git clone https://github.com/langbot-app/langbot-plugin-sdk) as subdirectories within it. The directory structure should look like:
+
+```bash
+langbot-projects
+├── LangBot
+├── langbot-plugin-sdk
+```
+
+Enter the LangBot directory and install dependencies:
+
+```bash
+cd LangBot
+uv sync --dev
+```
+
+At this point, uv will automatically create a virtual environment (.venv) for you. If your editor asks whether to use this virtual environment, please select `Yes`.
+
+
 +
+If the prompt does not appear, please manually set the Python interpreter path to the interpreter in the venv from the bottom-right corner.
+
+Then open the terminal at the bottom of VS Code, which will automatically activate the venv.
+
+Or you can manually activate this virtual environment:
+
+```bash
+# Please modify the command according to your .venv path
+source .venv/bin/activate
+```
+
+## Start Plugin Runtime
+
+```bash
+python -m langbot_plugin.cli.__init__ rt
+```
+
+Plugin Runtime accepts the following parameters:
+
+- `--debug-only`: Do not start plugins in the `data/plugins` directory, only allow loading plugins through debug connections.
+- `--ws-debug-port`: Debug port to listen on, default is `5401`.
+- `--ws-control-port`: Control port to listen on (for LangBot main program connection), default is `5400`.
+- `-s`: Use `stdio` to accept control connections. **Use only in production environment**.
+- `--skip-deps-check`: To ensure that all plugin dependencies are installed, the Runtime will check and install all installed plugin dependencies on every startup. Use this parameter to disable this check.
+
+### Make LangBot Use Your Locally Modified langbot-plugin-sdk
+
+If you have modified things like message entities or plugin data definitions, you need to update them in the LangBot environment to ensure data format compatibility during runtime.
+
+In a **terminal with the LangBot directory's virtual environment (.venv) activated**, switch to the langbot-plugin-sdk directory and run:
+
+```bash
+uv pip install .
+```
+
+This will install your modified langbot-plugin-sdk into LangBot's environment.
+
+### Make LangBot Connect to This Runtime
+
+Configure `plugin.runtime_ws_url` to `ws://localhost:5400/control/ws` in LangBot's `data/config.yaml`.
+
+```yaml
+plugin:
+ runtime_ws_url: ws://localhost:5400/control/ws
+```
+
+In a terminal with LangBot's virtual environment activated, start the main program directly with Python and add `--standalone-runtime` (for example, `python main.py --standalone-runtime`). Calling the current virtual environment's Python directly does not resync dependencies, so it does not overwrite the local langbot-plugin-sdk you just installed with the remote version.\
+Restart LangBot, and it will connect to this runtime using WebSocket.
+
+`LANGBOT_PLUGIN_RUNTIME_CONTROL_TOKEN` is optional by default. When it is unset on both LangBot and Runtime, the local OSS control connection is established without a token. To protect an exposed port 5400, configure the same high-entropy value of at least 32 characters on both sides. Once the Runtime configures a token, it rejects LangBot clients without the same value; configuring only the LangBot side does not enable authentication on the Runtime.
+
+### Debug a plugin with `lbp run`
+
+Multi-Workspace versions no longer allow a debug plugin to join the Runtime merely by reaching port `5401`. Every Workspace has a separate expiring debug key:
+
+1. Make sure LangBot and Plugin Runtime are running and connected as described above.
+2. On the LangBot WebUI Plugins page, open “Debug Info” and copy the debug URL and debug key. This requires resource-management permission in the current Workspace.
+3. Add the values to the plugin project's `.env`:
+
+```bash
+DEBUG_RUNTIME_WS_URL=ws://localhost:5401/plugin/debug/ws
+PLUGIN_DEBUG_KEY=
+```
+
+4. Start the plugin from its project directory:
+
+```bash
+python -m langbot_plugin.cli.__init__ run
+```
+
+Instead of storing the key in `.env`, you may run `python -m langbot_plugin.cli.__init__ run --plugin-debug-key ''`. Keys are scoped to one Workspace and expire after two hours. Fetch a new key after it expires, the Runtime restarts, or you switch Workspaces. A client that configures only `DEBUG_RUNTIME_WS_URL` is rejected.
+
+## Start Box Runtime in standalone mode
+
+Box Runtime follows the same control-connection rules as Plugin Runtime: a token is optional for OSS standalone development, and the connection works when `LANGBOT_BOX_CONTROL_TOKEN` is unset on both sides:
+
+```bash
+# Terminal 1: langbot-plugin-sdk directory
+python -m langbot_plugin.cli.__init__ box
+```
+
+Point LangBot's `data/config.yaml` at the local Box Runtime:
+
+```yaml
+box:
+ enabled: true
+ backend: local
+ runtime:
+ endpoint: ws://127.0.0.1:5410
+```
+
+```bash
+# Terminal 2: LangBot directory
+python main.py --standalone-runtime --standalone-box
+```
+
+To protect an exposed port 5410, set the same high-entropy, non-whitespace value of at least 32 characters before starting each process:
+
+```bash
+export LANGBOT_BOX_CONTROL_TOKEN=''
+```
+
+Once Box Runtime configures a token, it rejects LangBot clients without the same value. Configuring only the LangBot side does not enable authentication on Box Runtime; an explicitly configured value shorter than 32 characters is still rejected by both sides. Do not commit the real value to configuration or Git.
+
+## langbot-plugin-sdk Architecture
+
+This codebase contains the following:
+
+- `langbot_plugin.api`: Plugin-related entities and API definitions.
+- `langbot_plugin.assets`: Plugin templates.
+- `langbot_plugin.cli`: Plugin development CLI tools.
+- `langbot_plugin.entities`: Plugin system-related entities not defined in API.
+- `langbot_plugin.runtime`: Plugin runtime and underlying communication (stdio and websocket) implementation.
+
+## `lbp` CLI Tool
+
+The CLI tool provides Runtime startup, plugin initialization, plugin component management, Marketplace interaction, and other functions.
+
+For detailed program entry points, please see [`langbot_plugin.cli.__init__`](https://github.com/langbot-app/langbot-plugin-sdk/blob/main/src/langbot_plugin/cli/__init__.py).
diff --git a/docs/en/enterprise/overview.mdx b/docs/en/enterprise/overview.mdx
new file mode 100644
index 000000000..e3f5e7bca
--- /dev/null
+++ b/docs/en/enterprise/overview.mdx
@@ -0,0 +1,38 @@
+---
+title: "Enterprise Support"
+description: "Official issue triage, security updates, and procurement-ready contracts and invoices for open-source LangBot."
+---
+
+LangBot Enterprise Support is for organizations that need an **official support relationship** and **formal procurement documents**. Your subscription also directly funds continued LangBot development.
+
+
+LangBot remains free under Apache License 2.0. Enterprise Support is **not a commercial-use license**: it unlocks no features and does not restrict organizations that don't subscribe.
+
+
+## Plans
+
+| | Enterprise Support | Enterprise Assurance |
+| --- | --- | --- |
+| Annual fee (USD) | US$2,900 | US$7,500 |
+| Best for | Funding the project with a formal support relationship | Running LangBot in production |
+| Contract, invoice and annual certificate | ✓ | ✓ |
+| Enterprise tickets, first response within 2 business days | ✓ | ✓ |
+| Critical security notices, quarterly release & security digest | ✓ | ✓ |
+| Annual 60-minute usage review | 1 | 1 |
+| Priority review of public roadmap proposals | ✓ | ✓ |
+| Listing as an enterprise supporter (with consent; anonymity available) | ✓ | ✓ |
+| Registered production instance | — | 1 |
+| Remote technical consultations (60 min each) | — | 4 per year |
+| Pre-upgrade compatibility advice, priority incident triage | — | ✓ |
+| Confirmed Core defects enter the priority fix queue | — | ✓ |
+| Annual version, dependency and security status summary | — | ✓ |
+
+Fees are charged per contracting organization per year, not per seat or deployment. Taxes, invoice type and service dates follow the formal quote and contract.
+
+## Next steps
+
+- [Service scope and response](/en/enterprise/service-scope): what's included, what isn't, and how response time is counted
+- [Submit a ticket](/en/enterprise/submit-ticket): how subscribers request support
+- [Procurement and activation](/en/enterprise/procurement): contracts, invoices and deliverables
+
+To subscribe, email [hello@langbot.app](mailto:hello@langbot.app).
diff --git a/docs/en/enterprise/procurement.mdx b/docs/en/enterprise/procurement.mdx
new file mode 100644
index 000000000..7a071fad5
--- /dev/null
+++ b/docs/en/enterprise/procurement.mdx
@@ -0,0 +1,42 @@
+---
+title: "Procurement and activation"
+description: "Contracts, invoices and deliverables for Enterprise Support."
+---
+
+## How to subscribe
+
+1. **Contact us**: email [hello@langbot.app](mailto:hello@langbot.app) with your organization name, preferred plan and how you use LangBot.
+2. **Confirm the quote**: agree on scope, taxes and invoicing, and sign an annual service contract.
+3. **Pay and register**: pay as agreed and register contacts, Space accounts and service dates.
+4. **Get started**: once you receive the certificate and service guide, [submit tickets](/en/enterprise/submit-ticket).
+
+
+For the first contact, your organization name, preferred plan and a usage overview are enough. Invoicing details come before signing. Never send bank or tax details through public tickets or GitHub.
+
+
+## Contract and invoice
+
+| Item | Details |
+| --- | --- |
+| Contracting entity | The operating company behind LangBot; details are in the quote and contract |
+| Subject | Annual maintenance, release information and technical support for open-source LangBot |
+| Billing | Annual fee per contracting organization, not per seat |
+| Invoice description | Confirmed by finance within the permitted scope, e.g. software service or technical support fees |
+
+The fee is not invoiced as a donation or as a commercial software license fee.
+
+## Deliverables
+
+- Service order and contract with service dates and named contacts
+- Annual subscription certificate (evidences the support relationship; grants no additional software license)
+- Versioned service scope document, Space ticket access and account registration
+- Assurance: production instance registration and consultation allowance
+- During the term: quarterly maintenance digests, ticket and consultation records; Assurance also receives an annual version, dependency and security status summary
+
+Listing as an enterprise supporter requires separate consent and can be anonymous. Later changes to the service documents don't alter signed contracts.
+
+## Renewal
+
+Renewal is confirmed separately; there is no automatic charge. Start, end, cancellation and refund terms follow the contract.
+
+The subscription doesn't include LangBot Cloud compute, model credits or hosting. After expiry you can keep using LangBot under Apache 2.0.
diff --git a/docs/en/enterprise/service-scope.mdx b/docs/en/enterprise/service-scope.mdx
new file mode 100644
index 000000000..f8da8104d
--- /dev/null
+++ b/docs/en/enterprise/service-scope.mdx
@@ -0,0 +1,66 @@
+---
+title: "Service scope and response"
+description: "What Enterprise Support covers, what it doesn't, and how first response time is calculated."
+---
+
+Enterprise Support focuses on **LangBot Core itself**. It provides triage and guidance through a single ticket channel, not managed operations or custom development.
+
+## Included and not included
+
+| Included | Not included |
+| --- | --- |
+| LangBot Core defect assessment and triage | Deployment, operations, 24/7 coverage, on-site service |
+| Official documentation guidance | Troubleshooting your network, database, Kubernetes or model providers |
+| Upgrade compatibility advice | Maintenance of plugins, third-party adapters or private-protocol clients |
+| Public release information and security advisories | Custom development, historical data migration |
+| Ticket intake and triage | Recovery SLAs, fixed resolution deadlines, compliance certification |
+
+Custom work is outside the subscription and generally not accepted. Requests with broad value can be proposed on the public roadmap.
+
+## First response
+
+Both plans commit to a **first human response within 2 business days**. A first response means a person has confirmed the scope, requested more information, or given an initial classification. Automated emails don't count.
+
+
+A first response is not a fix or recovery. Resolution depends on severity, reproducibility, and whether the issue belongs to LangBot Core.
+
+
+- **Hours**: 09:00–18:00 Beijing time on mainland China business days, including make-up working days; public holidays are skipped.
+- **Counting**: requests submitted during hours are counted from submission; requests outside hours start at 09:00 on the next business day.
+- **Example**: submitted Friday 14:00 → response by Tuesday 14:00. Submitted Friday 20:00 → response by Wednesday 09:00.
+
+## Supported versions
+
+- Support covers the **current stable release** of LangBot Core. For older versions we first recommend upgrading, and confirming a defect may require reproducing it on the current release.
+- No backports, LTS branches or private patches.
+- Plugins and third-party components are outside Core maintenance.
+
+## Consultations and allowances
+
+| | Enterprise Support | Enterprise Assurance |
+| --- | --- | --- |
+| Annual usage review (60 min) | 1 | 1 |
+| Remote technical consultation (60 min, by appointment) | — | 4 |
+
+Unused sessions don't roll over. Enterprise Support covers ticket triage, documentation guidance and defect confirmation, not ongoing remote troubleshooting of your environment.
+
+## Instance registration (Assurance)
+
+- Assurance covers **1 registered production instance**. Registration only defines support scope; it doesn't limit deployments permitted by Apache 2.0 and requires no license key or telemetry.
+- We record version, deployment overview, purpose and contacts. Update the registration through a ticket when you replace the instance.
+
+## Security information
+
+- Quarterly digests are based on public release and security information.
+- Critical security notices are based on advisories confirmed by the maintainers; we don't determine whether your environment is affected.
+- The annual status summary (Assurance) is based on your registered version and public information. It is not a security audit, penetration test or compliance certification.
+
+## Working principles
+
+- One ticket per issue; duplicates may be merged.
+- The priority fix queue has no fixed deadline, and priority roadmap review is not a development or scheduling commitment.
+- Support runs through tickets only, not one-to-one group chats.
+
+## Service term
+
+Language, contacts, service dates and the applicable version of this document are set in the contract. After expiry no new requests are accepted; open tickets are triaged or handed over as agreed. You can keep using open-source LangBot after expiry.
diff --git a/docs/en/enterprise/submit-ticket.mdx b/docs/en/enterprise/submit-ticket.mdx
new file mode 100644
index 000000000..67e4b6dba
--- /dev/null
+++ b/docs/en/enterprise/submit-ticket.mdx
@@ -0,0 +1,49 @@
+---
+title: "Submit a ticket"
+description: "How subscribers report issues or book consultations in LangBot Space."
+---
+
+
+[Open LangBot Space tickets →](https://space.langbot.app/profile?tab=tickets&language=en)
+
+
+## Steps
+
+1. Sign in with the Space account registered in your contract.
+2. Go to **Profile → Tickets** and pick a template:
+ - **Enterprise Support: issue intake**: report a suspected LangBot Core defect
+ - **Enterprise Support: upgrade and consultation**: upgrade compatibility, consultation booking (Assurance), documentation and procurement materials
+3. Enter your subscription/contract ID and organization name, then complete the form.
+
+We verify the contract, registered account and service term before confirming entitlements. A subscription ID alone doesn't prove identity.
+
+## What to include
+
+**Issue intake**
+
+- LangBot version and deployment method
+- Expected vs. actual behavior
+- Reproduction steps
+- Redacted logs (explain if unavailable)
+- Business impact
+
+**Upgrade and consultation**
+
+- Registered instance and current version, target version if relevant
+- Goals and context
+- Preferred times, if a meeting is needed
+
+
+Don't submit access tokens, passwords, full chat histories, personal data or raw configuration files. Redact screenshots. Never post vulnerability details in a public GitHub issue.
+
+
+## After you submit
+
+Once your subscription is verified, we triage the request and may:
+
+- Point you to documentation or ask for more information
+- Book a consultation (Assurance)
+- Confirm a LangBot Core defect and move it into public maintenance
+- Explain that the request is out of scope
+
+For confirmed general defects, only the minimum redacted reproduction details go into public maintenance. Contracts, logs and business information are never synced to public GitHub. Please reply in the same ticket rather than opening duplicates elsewhere.
diff --git a/docs/en/insight/community.mdx b/docs/en/insight/community.mdx
new file mode 100644
index 000000000..a22bd0a21
--- /dev/null
+++ b/docs/en/insight/community.mdx
@@ -0,0 +1,14 @@
+---
+title: "Community Resources"
+description: "LangBot community resources: GitHub, Discord, documentation and support for the open-source AI bot platform."
+---
+
+
+## Simplified Tutorials
+> Simplified tutorials: such as video tutorials, simpler text tutorials, suitable for beginners
+
+Collected at: https://blog.thelazy.top/tags/langbot
+
+## 🥰 Community
+
+Join our community on Discord: [Discord](https://discord.gg/wdNEHETs87)
diff --git a/docs/en/insight/data-collection-policy.mdx b/docs/en/insight/data-collection-policy.mdx
new file mode 100644
index 000000000..f511507c4
--- /dev/null
+++ b/docs/en/insight/data-collection-policy.mdx
@@ -0,0 +1,78 @@
+---
+title: "Data Collection Policy"
+description: "Optional telemetry, execution chains, collected data and opt-out controls"
+---
+
+LangBot sends product telemetry to the LangBot Space service configured by `space.url` (by default `https://space.langbot.app`) to understand usage and improve reliability. **Telemetry is enabled by default and can be disabled.** This page describes the current 4.11 execution telemetry protocol (`schema: 2`); older-version data is described separately below.
+
+## Execution telemetry
+
+An eligible execution consists of independent records sharing an `event_id`: one `execution_node` is generated when each workflow node completes, and one `execution_chain` when the execution closes. Core buffers records within a fixed limit and uploads them in background batches; Space reconstructs the execution chain. The current sender no longer uses legacy feature window counters or assembles a complete chain locally.
+
+**Platform events without a matching business route, or whose selected route is `discard` with no matching plugin subscription, report neither nodes nor a closure.** Disabled routes and event-type/filter mismatches are included; local logs and monitoring keep their existing behavior. A matching plugin event processor still makes an execution eligible when the primary route misses. Unmatched and discarded branches do not contribute telemetry.
+
+After a business route matches, unavailable targets, execution failures, timeouts and filtering inside a Pipeline remain reportable. Valid interaction callbacks resuming an original processor, WebUI/API debug runs and independent calls explicitly targeting a Pipeline also remain eligible; invalid callbacks do not independently qualify. Eligibility takes precedence over sampling and failure fallback, including in Cloud. This requires a Core upgrade and does not retroactively change older clients or historical records.
+
+| Data | Contents |
+|---|---|
+| Identity and environment | `instance_id`, `workspace_uuid`, `event_id`, version, edition, timestamp, debug flag and sampling information |
+| Execution nodes | Operation identifiers, processing mode, outcome, start/end times, parent/child relationships and sequence, routing target and Runner run identity for platform events, routing, Pipeline, Runner, platform API and tool calls |
+| Chain closure | Overall outcome, closure reason, duration, node count, nodes omitted by sampling, origin, model name, adapter, Runner and pipeline plugins |
+| Bound resources | Identifiers or names of plugins, MCP servers, knowledge bases, tools and their sources, skills, models and platform APIs granted to a Pipeline or Agent, plus selector fields, capabilities and permission flags; fields depend on the execution path |
+| Errors | Short error text with length limits and whitespace normalization, potentially including an exception class and message prefix |
+
+Bound resources describe what an execution was configured or authorized to use. **They do not establish that those resources were actually called, searched or consumed.** Routing targets use `type:uuid`, not user-defined rule names.
+
+Execution records do not intentionally collect message bodies, prompts, model replies, platform user/group IDs, tool/API arguments or results, credentials or complete exception tracebacks. **Truncating error text is not reliable redaction: exception prefixes and user-defined model, skill or resource names may still contain sensitive information.** Instance and Workspace identifiers may be associated with deployments or accounts; these records are neither anonymous nor guaranteed to contain no user content.
+
+### Sampling and debug runs
+
+The community edition controls execution reporting with `space.execution_trace`:
+
+| Mode | Behavior |
+|---|---|
+| `all` (default) | Records nodes and closure records for every eligible execution |
+| `sampled` | Makes one stable hash decision from the event identity at ingress; retains approximately `1/N` successful executions, where N is `space.execution_trace_sample` (default 20); every record of an execution shares the decision |
+| `failures` | Omits nodes for ordinary executions and reports a closure only for failure, cancellation, timeout or a recorded chain failure reason |
+| `off` | Disables node and closure records; no independent window counters continue, while Workspace heartbeats remain controlled by the main telemetry switch |
+
+If an execution excluded by `sampled` fails, its closure is still reported. Previously skipped nodes are not recovered, so a failure may have a summary without a complete chain. WebUI debug runs are retained in `all`, `sampled` and `failures` with a debug flag; neither `off` nor the main opt-out permits their upload.
+
+**Cloud always uses `all` while product telemetry is enabled**, so sampling successful executions does not distort activity counts. The instance operator can still disable the product telemetry described here with `space.disable_telemetry`.
+
+### Delivery and completeness
+
+Records are sent to `POST /api/v1/telemetry`. The default flush interval is 180 seconds, configurable through `space.telemetry_flush_seconds`. Each flush sends at most 128 records and the memory buffer holds at most 512. Records are removed only after an accepted send; failed sends are retried, and a full buffer drops the oldest records. Shutdown attempts to flush remaining records within a limited time.
+
+Network failures, timeouts and server errors do not fail business execution because telemetry failed; upload failure details are logged at DEBUG level. Sampling, buffer overflow, process exit or expired cross-task associations can leave incomplete chains. **Full reporting does not guarantee complete delivery.** A successful platform API response does not prove that a user read a message.
+
+## Heartbeats, surveys and older-version data
+
+Active Workspaces first send an `instance_heartbeat` about 30 seconds after startup. Ordinary deployments send daily thereafter; Cloud runtime refreshes every 5 minutes. Heartbeats include deployment platform, database/vector-database kinds, sandbox configuration and availability, adapter types and counts of resources such as bots, Pipelines, plugins, Agents, event processors, event bindings, MCP servers, knowledge bases and skills. They do not intentionally include resource contents or connection credentials.
+
+Optional in-app surveys send the survey ID, submitted answers, instance ID, version and completion/dismissal status. Survey answers are content voluntarily provided by users.
+
+Space remains compatible with older `query` and `feature_execution` data. Legacy query records may contain model names, feature counters, user-defined skill/MCP names and raw traceback text. The current execution-record restrictions neither sanitize historical data nor change uploads from older clients still running.
+
+## Storage and retention
+
+Data is stored by the configured Space service. Execution lists, chain details and summaries are restricted to authorized telemetry management users or service clients. Raw `execution_node`, `execution_chain` and legacy `feature_execution` records are periodically removed in bounded batches using a 30-day retention window; backlogs or service interruptions can delay deletion. This does not change retention for legacy query telemetry, heartbeats, surveys, accounts or service logs.
+
+Opting out stops future reporting but does not delete existing server records. For historical data requests, contact [hello@langbot.app](mailto:hello@langbot.app) or your Space administrator.
+
+## Disabling telemetry
+
+Set the following in the existing `space` section of `data/config.yaml`, preserve other settings, and restart LangBot:
+
+```yaml
+space:
+ disable_telemetry: true
+```
+
+This switch disables the product telemetry described on this page and survey fetching. Use an unquoted YAML boolean. To restore the default, set it to `false` and restart.
+
+If `SPACE__DISABLE_TELEMETRY` is set in your deployment, it overrides the file at startup; update or remove it too. Recreate containers when changing their environment. In Cloud, the instance operator controls this setting for every Workspace in the instance. It does not disable the bot or change privacy settings of messaging platforms, model providers or plugins.
+
+Cloud Plugin Runtime operational health reporting is separate from product telemetry. It is controlled by `plugin.runtime_ops.enabled` and is not disabled by `space.disable_telemetry`.
+
+See [System Settings](../deploy/settings).
diff --git a/docs/en/insight/features.mdx b/docs/en/insight/features.mdx
new file mode 100644
index 000000000..f68a2d81b
--- /dev/null
+++ b/docs/en/insight/features.mdx
@@ -0,0 +1,155 @@
+---
+title: "Features"
+description: "LangBot is an open-source, production-grade, LLM-native instant messaging bot development platform. Build AI agents for Discord, Telegram, Slack, QQ, WeChat, WeCom, Lark, DingTalk and more — with built-in Agent, RAG knowledge base, MCP, Skills and a code sandbox, plus deep integration with Dify, Coze, n8n and Langflow."
+---
+
+LangBot is an **open-source, production-grade**, LLM-native instant messaging bot development platform. With a single codebase you can bring AI agents to Discord, Telegram, Slack, QQ, WeChat, WeCom, Lark, DingTalk and more — with built-in **Agent, RAG knowledge base, MCP, Skills and a code sandbox**, deep integration with Agent platforms like Dify, Coze, n8n and Langflow, and everything configured and monitored from a browser-based web panel — no hand-written config files.
+
+
+**Don't want to self-host?** Try [LangBot Cloud](https://space.langbot.app/cloud) — no server required, sign up and start instantly.
+
+
+## Core Capabilities at a Glance
+
+- **AI Conversation & Agent** — multi-turn dialogue, tool calling (function calling), multimodal (image/audio/file) and streaming output, ready out of the box.
+- **RAG Knowledge Base** — a built-in knowledge-base engine (vector retrieval + Rerank re-scoring) so your bot answers from your private knowledge, extensible via plugins to seamlessly connect external knowledge-base services like RAGFlow, Dify and FastGPT.
+- **All-Platform Coverage** — one codebase reaches Discord, Telegram, Slack, LINE, KOOK, Matrix, QQ, WeChat, WeCom, Lark, DingTalk and more.
+- **Deep Agent Platform Integration** — native connectors for Dify, Coze, n8n, Langflow, Deerflow, Aliyun Bailian, Ant TBox and other orchestration & workflow platforms.
+- **Skills & Code Sandbox** — on-demand instruction packs paired with a securely isolated code-execution sandbox, so the agent actually *gets things done*.
+- **MCP Protocol** — acts as a client into the Model Context Protocol tool ecosystem, supporting both Stdio and HTTP transports.
+- **Web Management Panel** — configure, manage and monitor bots visually in the browser, no manual config editing.
+- **Production-grade Plugin System** — hundreds of community plugins on a cross-process, event-driven architecture that's safe and hot-pluggable.
+- **Multi-pipeline Architecture** — run multiple pipelines per instance so different bots serve different scenarios, with access control, rate limiting, sensitive-word filtering and comprehensive monitoring.
+
+## Instant Messaging Platform Support
+
+LangBot covers mainstream global IM platforms through a unified adapter layer — develop once, reach everywhere.
+
+| Platform | Status | Remarks |
+| --- | --- | --- |
+| Personal QQ | ✅ | Supported via third-party apps implementing the OneBot v11 protocol; private and group chats |
+| QQ Official Bot | ✅ | Channels, private chats, and group chats |
+| WeChat | ✅ | Personal WeChat |
+| WeChat Official Account | ✅ | |
+| WeCom | ✅ | Internal application messages |
+| WeCom Intelligent Bot | ✅ | Supports streaming output |
+| WeCom Customer Service | ✅ | |
+| Lark | ✅ | Supports streaming output |
+| DingTalk | ✅ | Supports streaming output |
+| Discord | ✅ | |
+| Telegram | ✅ | Supports streaming output |
+| Slack | ✅ | |
+| LINE | ✅ | |
+| KOOK | ✅ | |
+| Satori | ✅ | [Satori](https://satori.chat/zh-CN/introduction.html) is a universal chat protocol that theoretically supports QQ, Zulip, Miyoushe and 15+ platforms |
+| Matrix | ✅ | Reaches Signal, WhatsApp, Messenger, iMessage, Mattermost, Google Chat, IRC, XMPP, Zulip and more via bridges |
+| Email | ✅ | Use email as a conversation channel |
+| Web Page Bot | ✅ | Embeddable chat widget for web pages |
+| WhatsApp | 🚧 | In development (also usable via Matrix bridge) |
+
+🚧: In development
+
+For fine-grained, per-platform feature support (sending/receiving images, audio, files, rich text, streaming responses, etc.), see the [platform features document](/en/insight/platform-features).
+
+## Model and Agent Platform Support
+
+LangBot uses **LiteLLM as a unified model request backend**, so beyond the built-in providers below you can also connect any OpenAI / Anthropic API-format or LiteLLM-supported model.
+
+### LLM, Aggregation & GPU Platforms
+
+| Provider/Service | Status | Remarks |
+| --- | --- | --- |
+| [OpenAI](https://platform.openai.com/) | ✅ | Works with any OpenAI-format model |
+| [Anthropic](https://www.anthropic.com/) | ✅ | |
+| [DeepSeek](https://www.deepseek.com/) | ✅ | |
+| [Google Gemini](https://aistudio.google.com/prompts/new_chat) | ✅ | |
+| [xAI](https://x.ai/) | ✅ | |
+| [Moonshot](https://www.moonshot.cn/) | ✅ | |
+| [Zhipu AI](https://open.bigmodel.cn/) | ✅ | |
+| [Mistral](https://mistral.ai/) | ✅ | |
+| [Groq](https://groq.com/) | ✅ | |
+| [OpenRouter](https://openrouter.ai/) | ✅ | Global LLM gateway |
+| [Ollama](https://ollama.com/) | ✅ | Local LLM running platform |
+| [LMStudio](https://lmstudio.ai/) | ✅ | Local LLM running platform |
+| [SiliconFlow](https://siliconflow.cn/) | ✅ | LLM gateway (MaaS) |
+| [Aliyun Bailian](https://bailian.console.aliyun.com/) | ✅ | LLM gateway (MaaS) / Agent platform |
+| [Volc Engine Ark](https://console.volcengine.com/ark) | ✅ | LLM gateway (MaaS) / Agent platform |
+| [ModelScope](https://modelscope.cn/docs/model-service/API-Inference/intro) | ✅ | LLM gateway (MaaS) |
+| [GiteeAI](https://ai.gitee.com/) | ✅ | LLM interface gateway (MaaS) |
+| [ShengSuanYun](https://www.shengsuanyun.com/?from=CH_KYIPP758) | ✅ | Global LLM aggregation (recommended) |
+| [CompShare](https://www.compshare.cn/?ytag=GPU_YY-gh_langbot) | ✅ | LLM and GPU resource platform |
+| [PPIO](https://ppio.com/user/register?invited_by=QJKFYD&utm_source=github_langbot) | ✅ | LLM and GPU resource platform |
+| [302.AI](https://share.302ai.cn/SuTG99) | ✅ | LLM gateway (MaaS) |
+| [Jiekou AI](https://jiekou.ai/) | ✅ | LLM gateway (MaaS) |
+| [TokenPony](https://www.tokenpony.cn/453z1) | ✅ | LLM gateway (MaaS) |
+| [Qiniu](https://www.qiniu.com/ai/agent) | ✅ | LLM gateway (MaaS) |
+
+### Agent Platforms
+
+Plug your existing workflows or agents straight into IM platforms — no need to rewrite your business logic.
+
+| Platform | Status | Remarks |
+| --- | --- | --- |
+| [Dify](https://dify.ai) | ✅ | Agent platform |
+| [Coze](https://coze.cn) | ✅ | Agent orchestration platform |
+| [n8n](https://n8n.io/) | ✅ | Workflow automation platform |
+| [Langflow](https://langflow.org/) | ✅ | Visual orchestration platform |
+| [Deerflow](https://deerflow.tech) | ✅ | Deep research framework |
+| [Weknora](https://weknora.weixin.qq.com) | ✅ | WeChat knowledge-base Q&A |
+| [Ant TBox](https://tbox.cn/) | ✅ | Agent platform |
+
+### Rerank Models
+
+| Provider | Status | Remarks |
+| --- | --- | --- |
+| [Cohere](https://cohere.com/) | ✅ | Rerank models |
+| [Jina](https://jina.ai/) | ✅ | Rerank models |
+| [Voyage AI](https://voyageai.com/) | ✅ | Rerank models |
+
+## LLM Application Paradigm Implementation
+
+LangBot turns mainstream LLM application paradigms into out-of-the-box capabilities, covering the full path from "can chat" to "can get work done."
+
+| Paradigm | Status | Notes |
+| --- | --- | --- |
+| Agent | ✅ | Built-in agent with tool calling, multi-turn reasoning, multimodal and streaming output |
+| RAG (Knowledge Base) | ✅ | Built-in knowledge-base engine (default Chroma vector store + Rerank re-scoring), pluggable into external knowledge bases like RAGFlow, Dify and FastGPT |
+| MCP | ✅ | Acts as an MCP client into the tool ecosystem; supports Stdio and HTTP |
+| Skills | ✅ | On-demand instruction packs, pulled into context only when matched — zero extra overhead |
+| Code Sandbox | ✅ | Securely isolated code-execution environment with Docker / nsjail / E2B backends |
+
+- **Skills**: package a professional workflow, template or script into an on-demand instruction pack — the agent pulls it into context only when the user's request matches, keeping the System Prompt clean. See the [Skills doc](/en/usage/skills/readme).
+- **Code Sandbox**: gives the agent securely isolated code-execution capability, automatically picking the best of the Docker / nsjail / E2B backends — the runtime foundation for Skills and native tools. See the [Sandbox doc](/en/usage/sandbox/readme).
+
+## System Extensibility
+
+LangBot offers a complete extension surface for secondary development and enterprise integration.
+
+- **HTTP Service API**: access LangBot's entities through HTTP interfaces with API-key authentication, for easy integration with existing systems.
+- **Outgoing Webhook**: push LangBot's internal events to external systems in real time, enabling event-driven automation.
+- **Production-grade Plugin System**: built on cross-process communication and async technology, supporting various component extensions — safe, stable and hot-pluggable; hundreds of community plugins install in one click from the [extension marketplace](https://space.langbot.app).
+- **Web Management Panel**: do all your bot, model, pipeline, knowledge-base and plugin configuration and monitoring visually.
+
+## Deployment Options
+
+LangBot supports everything from a one-line command to a Kubernetes cluster:
+
+- **LangBot Cloud (recommended)**: [a hosted, deploy-free, out-of-the-box version](https://space.langbot.app/cloud).
+- **One-line start**: `uvx langbot`, then open `http://localhost:5300`.
+- **Docker Compose**, **aaPanel**, **Kubernetes**, **one-click cloud deploy on Zeabur / Railway**, and more.
+
+See the [deployment docs](/en/deploy/langbot/kubernetes) and [quick start](/en/insight/guide).
+
+## Case Screenshots
+
+
+
+
+
+
+
+
+
+
+
+
diff --git a/docs/en/insight/guide.mdx b/docs/en/insight/guide.mdx
new file mode 100644
index 000000000..ed2b80b56
--- /dev/null
+++ b/docs/en/insight/guide.mdx
@@ -0,0 +1,35 @@
+---
+title: "Welcome to LangBot Documentation"
+description: "LangBot is an open-source LLM bot platform connecting Discord, Telegram, WeChat, Slack and more to GPT, Claude, Gemini, DeepSeek and Dify. Start here."
+---
+
+LangBot is an **open-source, production-grade**, LLM-native instant messaging bot platform. It connects large language models — OpenAI, Anthropic, Gemini, DeepSeek and more — and Agent platforms like Dify, Coze and n8n to mainstream messaging platforms including Discord, Telegram, Slack, QQ, WeChat, WeCom, Lark and DingTalk. With built-in Agent, RAG knowledge base, MCP, Skills and a code sandbox, plus an out-of-the-box web management panel, you can get your AI bot online in minutes — no hand-written config files required.
+
+
+
+## What You Can Build
+
+- **AI customer service / enterprise assistant**: deploy a knowledge-base-backed AI agent to Slack, Discord, Lark, WeCom or DingTalk to answer customer and employee questions automatically.
+- **Community operations**: provide AI-powered Q&A, content moderation and interaction in Discord, Telegram and QQ groups.
+- **Workflow integration**: plug your existing Dify / n8n / Coze workflows straight into chat platforms — no need to rewrite business logic.
+- **Multi-platform reach**: one bot covers every platform, managed centrally from a unified panel.
+
+## Start Here
+
+Follow this path to get familiar with LangBot, then explore the guides relevant to your needs.
+
+1. **Explore features and platforms**: read the [feature overview](/en/insight/features) and [platform support](/en/insight/platform-features) to see whether LangBot fits your use case.
+2. **Choose how to deploy**: use [LangBot Cloud](https://space.langbot.app/cloud) without managing your own server, or self-host with [Docker](/en/deploy/langbot/docker) or a [package manager](/en/deploy/langbot/package).
+3. **Connect bots and models**: see [bot configuration](/en/usage/platforms/readme), [model configuration](/en/usage/models/readme), and [pipelines](/en/usage/pipelines/readme) to learn how messaging platforms connect to AI capabilities.
+4. **Add more capabilities**: extend your bot with [knowledge bases](/en/usage/knowledge/readme), [plugins](/en/plugin/plugin-intro), [MCP](/en/usage/mcp/readme), and [Skills](/en/usage/skills/readme).
+5. **Explore examples or contribute**: find ideas in [practical articles](/en/articles/index), or read about [plugin development](/en/plugin/dev/tutor) and [core development setup](/en/develop/dev-config).
+
+If you run into problems, check [troubleshooting](/en/insight/troubleshooting) or ask the [community](/en/insight/community).
+
+
+Copy the prompt below into your AI assistant. It starts with the official documentation and adapts its help to your environment and goals.
+
+```text
+Read https://langbot.app/llms.txt first and follow its official guidance to help me deploy and use LangBot, install the LangBot CLI, and configure and manage my instance with the CLI. Adapt to my goals and environment, reuse an existing instance when possible, and verify a real message and reply on my target messaging platform. Respond in English.
+```
+
diff --git a/docs/en/insight/platform-features.mdx b/docs/en/insight/platform-features.mdx
new file mode 100644
index 000000000..7a0fa3a48
--- /dev/null
+++ b/docs/en/insight/platform-features.mdx
@@ -0,0 +1,262 @@
+---
+title: "Platform Feature Support"
+description: "Compare LangBot feature support across messaging platforms: Discord, Telegram, WeChat, Slack, QQ, Lark, DingTalk and more."
+---
+
+The following is a list of features we have implemented and tested for each platform. If you encounter unexpected behavior, please feel free to report it to [GitHub Issues](https://github.com/langbot-app/LangBot/issues) or directly submit a Pull Request to help fix it.
+
+## OneBot v11
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ✅ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ✅ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ✅ | |
+| Reply with file messages | ✅ | |
+| Reply with rich text messages | ✅ | Text and image combined |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## QQ Official Bot
+
+## WeCom (Internal Application)
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ❌ | WeCom internal application does not support adding to groups |
+| Receive group regular messages | ❌ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ✅ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ❌ | |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ❌ | |
+| Get group message event sender name | ❌ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ❌ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ✅ | |
+| Reply with file messages | ✅ | |
+| Reply with rich text messages | ❌ | |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## Satori
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ✅ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ✅ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ✅ | |
+| Reply with file messages | ✅ | |
+| Reply with rich text messages | ✅ | Text and image combined |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## WeCom (Customer Service)
+
+## WeCom Intelligent Bot
+
+## WeChat Official Account
+
+## Lark
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ❌ | Lark only supports receiving messages that mention the bot |
+| Receive image messages | ✅ | |
+| Receive voice messages | ❌ | Lark does not have voice messages |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ❌ | Lark does not support getting user name |
+| Get group message event group name | ❌ | Lark does not support getting group name |
+| Get group message event sender name | ❌ | Lark does not support getting sender name |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ❌ | |
+| Reply with file messages | ❌ | |
+| Reply with rich text messages | ❌ | |
+| Send proactive messages | ✅ | |
+| Send streaming response | ✅ | |
+
+## DingTalk
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ❌ | DingTalk only supports receiving messages that mention the bot |
+| Receive image messages | ✅ | |
+| Receive voice messages | ✅ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ❌ | |
+| Reply with file messages | ❌ | |
+| Reply with rich text messages | ✅ | Text and image combined |
+| Send proactive messages | ✅ | |
+| Send streaming response | ✅ | |
+
+## KOOK
+
+P.S. Sending voice and file messages has errors not fixed yet
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ✅ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ✅ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ❌ | KOOK does not support replying with voice messages |
+| Reply with file messages | ❌ | |
+| Reply with rich text messages | ✅ | Text and image combined |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## Discord
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ✅ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ❌ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | Text and image combined |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | Sent as file attachment |
+| Reply with voice messages | ✅ | Sent as file attachment |
+| Reply with file messages | ✅ | |
+| Reply with rich text messages | ✅ | Text and file combined |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## Telegram
+
+P.S. Not tested
+
+### Receive
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Receive private messages | ✅ | |
+| Receive group mention messages | ✅ | |
+| Receive group regular messages | ✅ | |
+| Receive image messages | ✅ | |
+| Receive voice messages | ❌ | |
+| Receive file messages | ✅ | |
+| Receive rich text messages | ✅ | |
+| Get private message event user name | ✅ | |
+| Get group message event group name | ✅ | |
+| Get group message event sender name | ✅ | |
+
+### Send
+
+| Feature | Status | Remarks |
+| --- | --- | --- |
+| Reply to private messages | ✅ | |
+| Reply to group messages | ✅ | |
+| Reply with image messages | ✅ | |
+| Reply with voice messages | ✅ | |
+| Reply with file messages | ✅ | |
+| Reply with rich text messages | ✅ | |
+| Send proactive messages | ✅ | |
+| Send streaming response | ❌ | |
+
+## Slack
+
+## LINE
diff --git a/docs/en/insight/troubleshooting.mdx b/docs/en/insight/troubleshooting.mdx
new file mode 100644
index 000000000..91d81ceb4
--- /dev/null
+++ b/docs/en/insight/troubleshooting.mdx
@@ -0,0 +1,262 @@
+---
+title: "Troubleshooting"
+description: "Common LangBot local deployment and runtime issues, with symptoms, causes, and fixes. Currently covers Docker deployment issues."
+---
+
+This page collects practical troubleshooting paths for common issues. It currently covers Docker deployment problems. More sections for models, bot adapters, MCP, and Skills can be added later.
+
+The commands below assume you are running them from `LangBot/docker`.
+
+## Docker Deployment
+
+### Preflight Checks
+
+If you need the sandbox, stdio MCP hosting, or Skill add/edit features, start LangBot with the `all` profile:
+
+```bash
+docker compose --profile all up -d
+```
+
+Check service status:
+
+```bash
+docker compose --profile all ps
+```
+
+You should see:
+
+- `langbot`: WebUI and backend service, exposing `5300` and `2280-2285` by default.
+- `langbot_plugin_runtime`: plugin runtime, exposing `5401` by default.
+- `langbot_box`: Box Runtime control plane, used to create sandbox containers.
+
+If you only run `docker compose up`, `langbot_box` is not started. stdio MCP, Skill add/edit, and some sandbox-dependent features will be unavailable.
+
+### Port Conflicts
+
+#### Symptoms
+
+- `docker compose up` fails with a port binding error.
+- The WebUI cannot be opened at `http://127.0.0.1:5300`.
+- Logs contain `port is already allocated` or `bind: address already in use`.
+
+#### Fix
+
+Find the process using the port. Linux/macOS:
+
+```bash
+lsof -i :5300
+lsof -i :5401
+```
+
+Windows PowerShell:
+
+```powershell
+Get-NetTCPConnection -LocalPort 5300,5401 | Select-Object LocalPort,OwningProcess
+Get-Process -Id
+```
+
+If it is an old LangBot, plugin runtime, or test process, stop it and start LangBot again:
+
+```bash
+docker compose --profile all up -d
+```
+
+If the process cannot be stopped, change the matching port mapping in `docker-compose.yaml`.
+
+### Box Runtime Is Not Available
+
+#### Symptoms
+
+- The UI or logs show `No sandbox backend (Docker/nsjail/E2B) is ready`.
+- stdio MCP servers are unavailable.
+- Skills cannot be installed, activated, or edited.
+
+#### Common Causes
+
+- LangBot was not started with `--profile all` or `--profile box`.
+- `langbot_box` is not running.
+- Docker Desktop or the current user cannot access Docker.
+- On Linux, the current user does not have permission to access the Docker socket.
+
+#### Fix
+
+Make sure `langbot_box` is running:
+
+```bash
+docker compose --profile all ps
+docker logs langbot_box --tail 100
+```
+
+Make sure Docker itself works:
+
+```bash
+docker info
+```
+
+On Linux, add the current user to the `docker` group if needed, then log in again:
+
+```bash
+sudo usermod -aG docker $USER
+newgrp docker
+docker info
+```
+
+Then recreate the containers:
+
+```bash
+docker compose --profile all up -d --force-recreate
+```
+
+### Box Root Mount Fails
+
+#### Symptoms
+
+- Logs contain `host_path is outside allowed_mount_roots`.
+- Logs contain `host_path must point to an existing directory on the host`.
+- On Docker Desktop, the Box root is resolved to `/run/desktop/...` and is rejected.
+- stdio MCP or Skill sandbox containers cannot be created.
+
+#### Cause
+
+`langbot_box` creates sandbox containers through the host Docker socket. Those sandbox containers see host paths, so the Box root path must be identical on the host and inside the container, and it must be under `allowed_mount_roots`.
+
+#### Fix
+
+Set an absolute path that Docker can mount and that Box security checks can accept in `LangBot/docker/.env`:
+
+```env
+LANGBOT_BOX_ROOT=/var/lib/langbot/box
+```
+
+On Windows Docker Desktop, use a path visible to the Docker VM, for example:
+
+```env
+LANGBOT_BOX_ROOT=/host_mnt/c/Users//code/projects/langbot/LangBot/docker/data/box
+```
+
+Make sure the directory exists, then recreate the containers:
+
+```bash
+docker compose --profile all up -d --force-recreate
+```
+
+If you previously edited `docker/data/config.yaml` manually, check that it points to the same root:
+
+```yaml
+box:
+ local:
+ host_root: /host_mnt/c/Users//code/projects/langbot/LangBot/docker/data/box
+ allowed_mount_roots:
+ - /host_mnt/c/Users//code/projects/langbot/LangBot/docker/data/box
+```
+
+### Many stdio MCP Servers Fail or Stay Connecting
+
+#### Symptoms
+
+- MCP status stays at `connecting` or becomes `error`.
+- `docker logs langbot_box` contains `Cannot fork`.
+- After installing many stdio MCP servers, previously working MCP servers also fail to start.
+
+#### Cause
+
+stdio MCP servers run inside the Box sandbox. The default Box profile has a relatively small PID limit. Starting many `npx` or `uvx` based MCP servers at the same time can hit that process limit.
+
+#### Fix
+
+Use the larger built-in Box profile in `docker/data/config.yaml`:
+
+```yaml
+box:
+ local:
+ profile: network_extended
+```
+
+Then stop LangBot and Box, remove the old shared sandbox, and recreate the containers.
+
+Linux/macOS:
+
+```bash
+docker compose --profile all stop langbot langbot_box
+docker rm -f $(docker ps -aq --filter "name=langbot-box-mcp-shared")
+docker compose --profile all up -d --force-recreate
+```
+
+Windows PowerShell:
+
+```powershell
+docker compose --profile all stop langbot langbot_box
+docker ps -a --filter "name=langbot-box-mcp-shared" --format "{{.Names}}" | ForEach-Object { docker rm -f $_ }
+docker compose --profile all up -d --force-recreate
+```
+
+After the MCP servers finish cold starting, check the MCP management page. Target servers should show `connected` and a non-zero tool count.
+
+### MCP Is Installed but Has No Tools or Cannot Connect
+
+#### Symptoms
+
+- The MCP server is listed, but its status is `error` or stays at `connecting`.
+- Tool count is `0`.
+- Remote MCP logs show `401 Unauthorized`, connection timeout, or handshake failure.
+
+#### Common Causes
+
+- The remote MCP requires an API key or OAuth authorization that is not configured.
+- The MCP package is cold starting through `npx` or `uvx`, and dependency download takes time.
+- The current Docker network cannot reach the MCP service or package registry.
+- The stdio MCP sandbox does not have enough resources.
+
+#### Fix
+
+Prefer MCP servers from LangBot Space that do not require credentials, or make sure credentials are configured correctly. For credentialed MCP servers, fill in the required environment variables, headers, or URL parameters during installation.
+
+Check runtime logs:
+
+```bash
+docker logs langbot --tail 200
+docker logs langbot_box --tail 200
+```
+
+If a server cannot connect in the current environment, disable or delete it from the MCP management page so it does not confuse later checks.
+
+### Image Tag or Registry Is Inconsistent
+
+#### Symptoms
+
+- `docker compose ps` still shows an old image.
+- Image registry or tag changes do not take effect after restart.
+- `langbot`, `langbot_plugin_runtime`, and `langbot_box` use different image tags.
+
+#### Fix
+
+Keep the three LangBot service image tags consistent, then pull and recreate:
+
+```bash
+docker pull rockchin/langbot:latest
+docker compose --profile all up -d --force-recreate
+```
+
+If you intentionally deploy a non-default tag, update all three image entries in `docker-compose.yaml`: `langbot`, `langbot_plugin_runtime`, and `langbot_box`.
+
+### Post-Fix Verification
+
+After applying a fix, run a full check:
+
+```bash
+docker compose --profile all ps
+docker inspect langbot langbot_plugin_runtime langbot_box --format '{{.Name}} {{.Config.Image}} {{.State.Status}}'
+```
+
+Check the WebUI:
+
+```bash
+curl -I http://127.0.0.1:5300/
+```
+
+Then confirm in the UI:
+
+- Login works.
+- Box / sandbox features are available.
+- Target MCP servers show `connected`.
+- stdio MCP servers show the expected tool count.
diff --git a/docs/en/plugin/certified-plugins.mdx b/docs/en/plugin/certified-plugins.mdx
new file mode 100644
index 000000000..29b174379
--- /dev/null
+++ b/docs/en/plugin/certified-plugins.mdx
@@ -0,0 +1,227 @@
+---
+title: "Certified plugins and shared runtime"
+description: "What certification is, why it exists, when you need it, and the shared-runtime-v1 / stateless-v1 contract."
+---
+
+## What certification is
+
+Certification is a grant LangBot makes for **one exact, immutable plugin artifact**: that artifact is approved to run **shared across tenants** in LangBot Cloud.
+
+- Certification is bound to the artifact itself (a specific published version, identified by digest), not to a plugin name or an author. Publishing a new version does not carry the previous version's certification over.
+- Certification is not a quality score and not a security audit endorsement.
+
+## Why certification exists
+
+LangBot does not place plugins in shared mode by default. The reason is that sharing is keyed by artifact:
+
+- **Dedicated mode**: the plugin does not participate in sharing and runs on its own.
+- **Shared mode**: every installation of the same artifact digest shares one Worker.
+
+Sharing keeps the number of processes and the startup cost from growing linearly with the number of installations. The trade-off is that **one process handles calls from several Workspaces at once** — so a plugin that keeps tenant data on its instances will leak it between tenants.
+
+The platform therefore has to review this exact artifact, confirm it satisfies the stateless contract, and then pin that trust to the artifact with a signature before it may enter shared placement. That is what certification is for.
+
+## When you need certification
+
+**Most plugins do not need certification.** Skipping it does not stop you from publishing to the marketplace, and it does not stop users from installing your plugin — it simply runs in dedicated mode.
+
+| Your situation | Certification needed? |
+| --- | --- |
+| You only want to publish the plugin so users can install it | No |
+| The plugin needs process-local state across calls (for example a long-lived external session process) | No — and it should stay dedicated |
+| The plugin has background tasks, timers, or long-lived tenant caches | No — dedicated mode is the safer choice |
+| You want the Certified Plugin badge | Yes |
+| You want several installations of one artifact to share a process, reducing cost and startup overhead | Yes |
+| The plugin targets Cloud multi-tenant scenarios and you want shared placement | Yes |
+
+The test is a single question: **certification only makes sense if your code genuinely keeps no tenant or installation data on its instances.**
+
+## What certification changes
+
+After review passes:
+
+- The artifact is signed and installed in **shared mode**; multiple installations of the same digest share one Worker.
+- That Worker holds one `BasePlugin` object and one instance per declared component manifest (EventListener, Tool, Command, KnowledgeEngine, Parser, Page, Runner).
+- Each installation adds only a lightweight layer of configuration, authority and lifecycle context; the active one is selected per call.
+- You receive the Certified Plugin badge.
+- Self-hosted OSS ships without a certification issuer public key, so a certified artifact still runs dedicated on self-hosted instances.
+
+You also take on a standing obligation: **every later version must keep satisfying the stateless contract.** After changing code you submit a new version for review; certification does not renew itself.
+
+## What you must adapt
+
+### Declaration
+
+Declare both fields under `execution` in `manifest.yaml`:
+
+```yaml
+apiVersion: v1
+kind: Plugin
+metadata:
+ author: your-name
+ name: YourPlugin
+ version: 0.1.1
+spec:
+ config: []
+ components: {}
+execution:
+ python:
+ path: main.py
+ attr: YourPlugin
+ sharedRuntime: shared-runtime-v1
+ componentModel: stateless-v1
+```
+
+| Field | Accepted value | Notes |
+| --- | --- | --- |
+| `execution.sharedRuntime` | `shared-runtime-v1` | This is the only accepted value; anything else fails manifest validation |
+| `execution.componentModel` | `stateless-v1` | This is the only accepted value |
+
+- Both fields **must be declared together**. A package that declares `sharedRuntime` without `componentModel` is rejected during certification validation.
+- The fields are recognised from **SDK 0.7.0** onwards. Earlier SDKs ignore them, so do not rely on an old SDK to tell you whether the declaration took effect.
+
+
+A declaration is an application, not approval. It grants no badge and does not change how the plugin runs by itself.
+
+
+### Stateless constraints
+
+- `BasePlugin.initialize()` and component `initialize()` are **process-scoped** and run once per Worker. At that point there is no "current installation" and no "current Workspace".
+- Component instances are called concurrently by different Workspaces, so every method must be re-entrant.
+- Read the active installation configuration per call: `self.get_config()` on `BasePlugin`, `self.get_plugin_config()` or `self.plugin.get_config()` in a component, and `ctx.config` in a Runner.
+- Never store configuration, credentials, Workspace or installation identity, or request data in instance fields or module-level globals.
+- Do not read and cache installation configuration in `initialize()`.
+- Reach storage, files, credentials, logs, models and other platform capabilities through the SDK Host APIs. Authority is resolved per call; do not cache it yourself.
+- Durable tenant state belongs in Host services. Runners use `ctx.state_get()` / `ctx.state_set()` and friends (this requires `ctx.context.available_apis.state` to be `true`). In-process caches may hold artifact-level public data only; if you must cache tenant data, the key has to include the complete installation identity and must be cleaned up when the installation is removed.
+- Do not start tenant-bearing background tasks or threads: the SDK does **not** track ownership of work you create. If you must detach work, keep a registry keyed by the installation binding and stop it in `on_installation_revoked()`. Once a handler returns, that invocation's context and run-associated calls are no longer valid.
+
+### One installation, many usages
+
+A Workspace installs each plugin once, but that single installation is reused by **several product objects**:
+
+| Component kind | What reuses it | What isolates it |
+| --- | --- | --- |
+| Runner in an Agent or Pipeline | every processor | `ctx.state.*` is already per-processor (scopes carry `binding_identity`, derived from the Agent UUID) |
+| KnowledgeEngine / Parser behind a knowledge base | every knowledge base | **your plugin must isolate by knowledge-base ID itself** |
+| Tool / Command / EventListener / Page | several processors, conversations or page requests | read per call; never accumulate on the instance |
+
+The platform storage key is `(instance, Workspace, owner type, plugin, key)` and carries **no processor or knowledge-base dimension**. So whenever your plugin persists or caches anything, it must put the product object's identity into the key:
+
+- **Config**: read per call (`ctx.config`, or the task-local `self.get_plugin_config()`); never cache it on the instance.
+- **Persistence**: keys must include the product identity (processor identity / knowledge-base ID / conversation identity).
+- **Process-local caches**: keys must include both the full installation binding **and** the product identity, and must be released when the installation is revoked (below).
+- **Locks and fences**: key them by `(installation, product object)`. **A failure in one processor or knowledge base must not block the others of the same installation.**
+- **Failure grading**: only a dispatched mutation with an unknown outcome should enter a state that needs manual reconciliation; deterministic validation errors and pre-dispatch cancellation must not affect later calls.
+- **Logs and telemetry**: a diagnostic failure must not affect the work, and tenant data must not be written into a process-wide singleton.
+
+### When an installation is revoked
+
+Under shared placement one object graph serves every installation of the artifact, so **revoking one installation does not destroy it**. The plugin must release binding-keyed process-local state itself:
+
+```python
+class MyPlugin(BasePlugin):
+ def __init__(self) -> None:
+ super().__init__()
+ self._caches: dict[str, Cache] = {}
+
+ async def on_installation_revoked(self, binding) -> None:
+ self._caches.pop(binding.installation_uuid, None)
+```
+
+- **Fires for** uninstall, disable, Workspace removal and upgrade (the superseded binding is revoked). It runs only under shared placement; dedicated workers are shut down, so their process-local state disappears with the process.
+- **There is no active invocation**, so Host APIs (storage, config, binding lookups) are unavailable — you can only release process-local state, and the installation is identified by the argument.
+- Exceptions are logged and **never block revocation**.
+- It requires an SDK version that provides `BasePlugin.on_installation_revoked`; on older versions the hook is simply never called.
+
+### Allowed / forbidden
+
+| Concern | Allowed | Forbidden |
+| --- | --- | --- |
+| Reading config | Read per call (`self.get_plugin_config()`, `ctx.config`) | Reading in `initialize()` and keeping it on `self` |
+| Connection pools / HTTP clients | Shared pools without tenant credentials | Baking an installation's endpoint or API key into the instance |
+| Caching | Artifact-level public data; or keys including the full installation identity and supporting cleanup | A module-level `dict` keyed by Workspace or user that persists |
+| Cross-invocation state | Host services (`ctx.state_*` in a Runner) | Instance fields, module globals |
+| Background work | None | Holding an invocation's context or its run-associated calls after the handler returned |
+| Logging | `ctx.log()` or SDK logging APIs | A module-level background thread printing tenant config or credentials |
+
+### Common anti-patterns
+
+**1. Reading installation config during initialization**
+
+```python
+async def initialize(self):
+ self.endpoint = self.plugin.config["endpoint"] # process-scoped init has no active installation
+ self.api_key = self.plugin.config["api_key"]
+```
+
+Shared initialization has no installation configuration, so this reads empty or stale values.
+
+**2. Caching tenant data in a module global**
+
+```python
+_CACHE = {} # keyed by Workspace or user; persists across installations and tenants
+
+async def call(self, params, **kwargs):
+ if params["user"] not in _CACHE:
+ _CACHE[params["user"]] = await fetch(params["user"])
+```
+
+**3. Keeping work alive after the handler returns**
+
+```python
+async def call(self, params, **kwargs):
+ config = self.get_plugin_config()
+ asyncio.create_task(self._upload_later(config)) # handler already returned; context and authority are gone
+ return ok()
+```
+
+**4. Treating instance fields as a config container**
+
+```python
+async def initialize(self):
+ self.default_endpoint = "https://api.example.com" # a public constant is fine
+ self.last_config = {} # writing installation config here is not
+```
+
+The correct shape:
+
+```python
+class LookupTool(Tool):
+ async def initialize(self):
+ # artifact-level objects only, no tenant information
+ self.transport = StatelessHTTPTransport()
+
+ async def call(self, params, **kwargs):
+ config = self.get_plugin_config() # read for the active installation on every call
+ return await self.transport.lookup(config["endpoint"], params)
+```
+
+### Runners in particular
+
+Runners have the most tension with the stateless contract, because a runner naturally tends to keep sessions and context in the process.
+
+- A `RunnerContext` is **valid only for the current run**. Do not keep it, or anything derived from it, on the instance for reuse across calls.
+- Session state a Runner needs across calls belongs in `ctx.state_get()` / `ctx.state_set()` (scopes: `conversation`, `actor`, `subject`, `runner`) or another Host-provided store — not in instance fields.
+- After a handler returns, do not keep using `ctx` in background tasks, and do not keep using run-associated calls made through `self.plugin`.
+- If your Runner fundamentally depends on process-local state across calls (for example a long-lived external session process), **do not declare `stateless-v1`** and stay on a dedicated Worker.
+
+See [Runner context](/en/plugin/dev/apis/agent-run) for the full context API.
+
+## Self-check and submission
+
+Verify each item before submitting:
+
+- [ ] Both fields are declared in `manifest.yaml` with the exact accepted values.
+- [ ] A repository-wide search confirms there are no module-level mutable globals.
+- [ ] `initialize()` performs process-scoped setup only and reads no installation config.
+- [ ] Every piece of installation config is read at call time.
+- [ ] No task or thread keeps running after a handler returns.
+- [ ] Cross-call state goes through Host APIs (`ctx.state_*` in a Runner).
+
+### How to submit
+
+Certification uses the same path as publishing, with no extra process: declare the two fields above in `manifest.yaml`, then submit a **new version** with `lbp publish` as usual (a published version cannot have the declaration added later). LangBot Space checks the exact submitted package, runs an advisory code review, and issues the Certified Plugin badge after human approval; certification is bound to the reviewed version and checksum.
+
+If the review finds that the release cannot meet the requirements, publish it as an unsigned normal plugin first and fix the findings in a later immutable version.
+
+If this check shows your plugin is not a good fit for sharing, just publish it as a normal plugin — certification is optional. See [Publish to the marketplace](/en/plugin/dev/publish/market) for the publishing flow.
diff --git a/docs/en/plugin/compatibility.mdx b/docs/en/plugin/compatibility.mdx
new file mode 100644
index 000000000..b7a73058a
--- /dev/null
+++ b/docs/en/plugin/compatibility.mdx
@@ -0,0 +1,17 @@
+---
+title: "System Compatibility"
+---
+
+LangBot's plugin system utilizes mechanisms such as `Asyncio` and `Subprocess`, which work well on Unix-like systems (such as Linux, macOS), but have some issues on Windows, preventing plugins from running properly.
+
+Python's asynchronous event loop on Windows defaults to using `ProactorEventLoop`, but this event loop lacks support for Stdio, while LangBot in non-Docker environments relies on Stdio to communicate with Plugin Runtime, and Plugin Runtime also depends on Stdio to communicate with plugins.
+
+If we switch to using `SelectorEventLoop`, it would prevent Plugin Runtime and plugins from starting properly, as `SelectorEventLoop` does not support `Subprocess`.
+
+For detailed information about these issues, please refer to: [Python Official Documentation](https://docs.python.org/3.13/library/asyncio-platforms.html)
+
+## Solution
+
+Unlike the tight coupling between subprocess management and Stdio communication on Unix-like systems, LangBot and the Plugin Runtime automatically switch to a hybrid subprocess + WebSocket communication strategy on Windows. LangBot still launches the Plugin Runtime via a subprocess, but communicates with it over WebSocket; similarly, the Plugin Runtime starts each installed plugin via subprocesses while communicating with them through WebSocket.
+
+This behavior is automatically selected based on the OS, so no manual configuration is required.
diff --git a/docs/en/plugin/dev/apis/agent-run.mdx b/docs/en/plugin/dev/apis/agent-run.mdx
new file mode 100644
index 000000000..38c019c29
--- /dev/null
+++ b/docs/en/plugin/dev/apis/agent-run.mdx
@@ -0,0 +1,263 @@
+---
+title: "Context APIs"
+---
+
+A context contains data for one component invocation. Each component receives a different context, so start with the entry point for your component.
+
+| Component | Handler entry point | Context type |
+| --- | --- | --- |
+| EventListener | `handler(event_context)` | `EventContext` |
+| Command | `subcommand(context)` | `ExecuteContext` |
+| Tool | `call(params, session, query_id)` | No separate context object |
+| Runner | `run(ctx)` or `handler(ctx)` | `RunnerContext` |
+| KnowledgeEngine | `ingest(context)`, `retrieve(context)` | `IngestionContext`, `RetrievalContext` |
+| KnowledgeRetriever | `retrieve(context)` | `RetrievalContext` |
+| Parser | `parse(context)` | `ParseContext` |
+| Page | `handle_api(request)` | `PageRequest` |
+
+This page covers the data and methods available through these contexts. Use `self.plugin` for models, knowledge bases, storage, and other LangBot capabilities; see [LangBot API](/en/plugin/dev/apis/common). For platform operations, see [Platform API](/en/plugin/dev/apis/platform).
+
+`EventContext`, `ExecuteContext`, and `Session` also carry `instance_uuid`, `workspace_uuid`, and `placement_generation`. These fields identify the current instance and workspace for execution; plugins must not treat them as authorization data.
+
+See [LLM request configuration](/en/plugin/dev/apis/llm-requests) for retries, timeouts, numeric reasoning budgets, prompt caching, headers and stream cancellation.
+
+## EventListener
+
+EventListener handles Pipeline events. Its event handler receives an `EventContext`:
+
+```python
+event = event_context.event
+sender_id = event.sender_id
+```
+
+### Context data
+
+| Property | Type | Description |
+| --- | --- | --- |
+| `event` | `BaseEventModel` | Current event object; its actual type matches the registered event type |
+| `event_name` | `str` | Current event class name |
+| `query_id` | `int` | Current Pipeline request ID |
+| `query_uuid` | `str \| None` | Stable identifier for the current Pipeline request |
+| `eid` | `int` | Temporary event number inside Plugin Runtime; do not persist it |
+| `is_prevent_default` | `bool` | Whether default handling has been stopped; change it with `prevent_default()` |
+| `is_prevent_postorder` | `bool` | Whether later plugins have been stopped; change it with `prevent_postorder()` |
+
+See [Pipeline Events](/en/plugin/dev/apis/pipeline-events) for event fields and all supported event types.
+
+### Context methods
+
+| Method | Return value | Description |
+| --- | --- | --- |
+| `await event_context.reply(message_chain, quote_origin=False)` | - | Reply in the conversation for the current request |
+| `await event_context.get_bot_uuid()` | `str` | Get the source bot UUID |
+| `await event_context.set_query_var(key, value)` | - | Set a variable on the current request |
+| `await event_context.get_query_var(key)` | `Any` | Get one request variable |
+| `await event_context.get_query_vars()` | `dict[str, Any]` | Get all request variables |
+| `await event_context.create_new_conversation()` | `dict[str, Any]` | Clear the current Pipeline conversation so a later request starts a new one |
+| `await event_context.list_pipeline_knowledge_bases()` | `list[dict[str, Any]]` | List knowledge bases bound to the current Pipeline Local Agent |
+| `await event_context.retrieve_knowledge(kb_id, query_text, top_k=5, filters=None)` | `list[dict[str, Any]]` | Search a knowledge base bound to the current Pipeline |
+| `event_context.prevent_default()` | - | Stop the default handling of the current event |
+| `event_context.prevent_postorder()` | - | Stop later plugins from handling the current event |
+
+`reply()` accepts a [MessageChain](/en/plugin/dev/apis/messages). Request variables, replies, and Pipeline knowledge-base methods require an associated Pipeline request. The `kb_id` passed to `retrieve_knowledge()` must come from `list_pipeline_knowledge_bases()`.
+
+`prevent_default()` only affects Pipeline events whose default flow can be stopped. See [Pipeline Events](/en/plugin/dev/apis/pipeline-events#prevent-default-behavior).
+
+## Command
+
+A Command subcommand handler receives an `ExecuteContext`:
+
+```python
+query = " ".join(context.crt_params)
+session = context.session
+```
+
+### Context data
+
+| Property | Type | Description |
+| --- | --- | --- |
+| `session` | `Session` | Session that contains the current message |
+| `command_text` | `str` | Complete command text without the command prefix |
+| `full_command_text` | `str` | Complete command text including the prefix |
+| `command` | `str` | Root command name |
+| `crt_command` | `str` | Subcommand currently being executed |
+| `params` | `list[str]` | All arguments after the root command |
+| `crt_params` | `list[str]` | Arguments not yet consumed by the current subcommand |
+| `privilege` | `int` | Command privilege level of the current user |
+| `query_id` | `int` | Current Pipeline request ID |
+| `query_uuid` | `str \| None` | Stable identifier for the current Pipeline request |
+
+The SDK calls `context.shift()` before entering the current subcommand. Components do not need to call it directly.
+
+### Context methods
+
+| Method | Return value | Description |
+| --- | --- | --- |
+| `await context.reply(message_chain, quote_origin=False)` | - | Reply in the conversation for the current request |
+| `await context.get_bot_uuid()` | `str` | Get the source bot UUID |
+| `await context.set_query_var(key, value)` | - | Set a variable on the current request |
+| `await context.get_query_var(key)` | `Any` | Get one request variable |
+| `await context.get_query_vars()` | `dict[str, Any]` | Get all request variables |
+| `await context.create_new_conversation()` | `dict[str, Any]` | Clear the current Pipeline conversation so a later request starts a new one |
+| `await context.list_pipeline_knowledge_bases()` | `list[dict[str, Any]]` | List knowledge bases bound to the current Pipeline Local Agent |
+| `await context.retrieve_knowledge(kb_id, query_text, top_k=5, filters=None)` | `list[dict[str, Any]]` | Search a knowledge base bound to the current Pipeline |
+
+These request methods behave the same as their EventListener equivalents. See [Command](/en/plugin/dev/components/command) for registration and return values.
+
+## Tool
+
+Tool has no separate context object. Its `call()` parameters carry the invocation data:
+
+```python
+conversation_type = session.launcher_type.value
+conversation_id = session.launcher_id
+sender_id = session.sender_id
+```
+
+| Parameter | Description |
+| --- | --- |
+| `params` | Arguments generated by the model or caller from the tool JSON Schema |
+| `session` | Current session data |
+| `query_id` | Current Pipeline request ID; pass it unchanged to LangBot APIs that require request context |
+
+Common `Session` properties are:
+
+| Property | Description |
+| --- | --- |
+| `launcher_type` | Conversation type: `person` or `group` |
+| `launcher_id` | Private-chat user or group ID |
+| `sender_id` | Current message sender ID |
+| `bot_uuid` | Current bot UUID |
+| `using_conversation` | Current Pipeline conversation |
+| `conversations` | Pipeline conversations stored in this Session |
+| `use_prompt_name` | Active prompt name |
+| `create_time`, `update_time` | Session creation and update times |
+
+`session` is a data object and has no context methods such as `reply()`. A tool return value goes back to its caller; it is not sent to the chat platform automatically. Use `self.plugin` for LangBot and platform capabilities. If an API requires `session` and `query_id`, pass the values received by the current call.
+
+## Runner
+
+Both custom `run(ctx)` implementations and Runner event handlers receive a `RunnerContext`. It remains valid only while the current invocation is running.
+
+```python
+text = ctx.input.to_text()
+event_type = ctx.event.event_type
+```
+
+### Context data
+
+| Property | Type | Description |
+| --- | --- | --- |
+| `run_id` | `str` | Current run ID |
+| `trigger` | `AgentTrigger` | Trigger type, source, and time |
+| `event` | `AgentEventContext` | Standard event envelope with the event ID, type, source, time, and raw data |
+| `platform_event` | Platform event type | Platform event parsed into its specific event type |
+| `conversation` | `ConversationContext \| None` | Current conversation, thread, bot, and workspace identifiers |
+| `actor` | `ActorContext \| None` | Actor that caused the event |
+| `subject` | `SubjectContext \| None` | Message, group, or other object affected by the event |
+| `input` | `AgentInput` | Current text, structured content, and attachments |
+| `delivery` | `DeliveryContext` | Output target and streaming, editing, and reaction capabilities |
+| `resources` | `AgentResources` | Models, tools, knowledge bases, skills, and storage authorized for this run |
+| `context` | `ContextAccess` | Conversation cursors, inline policy, and available context APIs |
+| `state` | `AgentRunState` | Scope-specific state snapshot loaded at the start of the run |
+| `runtime` | `AgentRuntimeContext` | LangBot version, trace ID, and deadline |
+| `config` | `dict[str, Any]` | Current Agent or plugin-processor configuration |
+| `adapter` | `AdapterContext \| None` | Additional entry-adapter data |
+| `variables` | `dict[str, Any]` | Public request variables for Runner templates |
+| `metadata` | `dict[str, Any]` | Other metadata supplied by the Host |
+
+Prefer the stable properties in this table. `event.data` and `adapter.extra` carry additional data that has not been promoted to stable fields.
+
+### Replies and logs
+
+| Method | Return value | Description |
+| --- | --- | --- |
+| `await ctx.get_bot_uuid()` | `str` | Get the source bot UUID; raises an error when no bot is associated |
+| `await ctx.reply(message_chain, quote_origin=False)` | `Any` | Reply to the current event with a string or `MessageChain` |
+| `ctx.reply_stream()` | Async context manager | Stream full-text updates to one reply |
+| `await ctx.log(text, level="info")` | - | Write to this run's log; levels are `debug`, `info`, `warning`, and `error` |
+
+Each `reply_stream().update(text)` call supplies the complete current text. If the platform does not support streaming, LangBot sends one complete message when the stream finishes. Debug mode only simulates delivery.
+
+### Available tools
+
+| Method | Return value | Description |
+| --- | --- | --- |
+| `await ctx.get_available_tools()` | `list[dict[str, Any]]` | Get context actions, platform APIs, plugin tools, and MCP tools callable in this invocation |
+| `await ctx.call_tool(tool_name, parameters=None)` | `dict[str, Any]` | Call a tool from that list |
+
+Each item returned by `get_available_tools()` contains `name`, `description`, `parameters`, `type`, and `operations`. The result is already filtered by the current Agent or plugin-processor configuration and the event's capabilities. `ctx.call_tool()` cannot call a tool absent from this list.
+
+### Box and attachments
+
+The Runner owns enablement, acquisition, and reuse policy. Use the [LangBot Box APIs](/en/plugin/dev/apis/common#box-sandbox) for resources and these context methods for the current run.
+
+| Method | Returns | Behavior |
+| --- | --- | --- |
+| `await ctx.bind_box(box_id)` | `BoxBinding` | Bind a Workspace Box; returns `box_id`, `outbox`. A run cannot switch Boxes |
+| `await ctx.import_box_attachments(attachment_ids=None)` | `list[BoxFile]` | Import selected input `ref` values, or all inputs; returns sandbox paths |
+| `await ctx.export_box_files()` | `list[BoxFile]` | Export this run's outbox as file handles; sends no message |
+| `await ctx.reply_files(file_ids)` | `Any` | Reply with exported IDs, subject to event reply authorization |
+
+`BoxFile` contains `id`, `name`, `type`, `size`, and optional `path`. Original attachment URLs and content remain available. Files are staged only on explicit import. Output handles belong to this run and cannot be sent twice.
+
+Bind before native sandbox tools or file operations. Runs sharing a Box still have separate attachment directories. `ctx.variables` contains public request variables for computing reuse keys.
+
+`ctx.delivery.automatic_reply` is `True` for Pipeline execution: return files using `RunnerResult.message_completed(ctx.run_id, message, file_ids=[...])`. Agents and plugin processors explicitly call `ctx.reply_files()`.
+
+External runners use the same flow through `AgentRunExternalTools`: `langbot_get_box_status`, `langbot_list_boxes`, `langbot_acquire_box`, `langbot_bind_box`, `langbot_import_box_attachments`, and `langbot_export_box_files`. `langbot_reply_files` is available when the run has event reply permission. All calls retain the current run authorization.
+
+### Prompt, history, and events
+
+| Method | Return value | Availability field |
+| --- | --- | --- |
+| `await ctx.get_prompt()` | `list[dict[str, Any]]` | `prompt_get` |
+| `await ctx.history_page(conversation_id=None, before_cursor=None, after_cursor=None, limit=50, direction="backward", include_attachments=False)` | `HistoryPage` | `history_page` |
+| `await ctx.history_search(query, filters=None, top_k=10)` | `HistorySearchResult` | `history_search` |
+| `await ctx.event_get(event_id)` | `AgentEventRecord` | `event_get` |
+| `await ctx.event_page(conversation_id=None, event_types=None, before_cursor=None, limit=50)` | `EventPage` | `event_page` |
+| `await ctx.steering_pull(mode="all", limit=None)` | `SteeringPullResult` | `steering_pull` |
+
+### State
+
+| Method | Return value | Description |
+| --- | --- | --- |
+| `await ctx.state_get(scope, key)` | `dict[str, Any]` | Read a state value |
+| `await ctx.state_set(scope, key, value)` | `dict[str, Any]` | Store a JSON-serializable state value |
+| `await ctx.state_delete(scope, key)` | `dict[str, Any]` | Delete a state value |
+| `await ctx.state_list(scope, prefix=None, limit=100)` | `dict[str, Any]` | List state keys in a scope |
+
+`scope` can be `conversation`, `actor`, `subject`, or `runner`. These methods require `ctx.context.available_apis.state` to be `true`.
+
+### Run records
+
+| Method | Return value | Availability field |
+| --- | --- | --- |
+| `await ctx.run_get(run_id=None)` | `AgentRun` | `run_get` |
+| `await ctx.run_list(conversation_id=None, statuses=None, before_cursor=None, limit=50)` | `RunPage` | `run_list` |
+| `await ctx.run_events_page(run_id=None, before_cursor=None, after_cursor=None, limit=50, direction="forward")` | `RunEventPage` | `run_events_page` |
+| `await ctx.run_cancel(run_id=None, reason=None)` | `AgentRun` | `run_cancel` |
+| `await ctx.run_append_result(result)` | `AgentRunEvent` | `run_append_result` |
+| `await ctx.run_finalize(run_id=None, status=None, reason=None)` | `AgentRun` | `run_finalize` |
+
+`run_id=None` refers to the current run. The SDK completes a normal event handler automatically. When a custom `run(ctx)` yields `RunnerResult`, do not register the same result again with `run_append_result()`.
+
+### Availability and authorization
+
+Use `ctx.context.available_apis` to check whether prompt, history, event, state, and run-record methods are available. Authorized models, tools, and knowledge bases are in `ctx.resources.models`, `ctx.resources.tools`, and `ctx.resources.knowledge_bases`.
+
+During Runner execution, model, tool, knowledge-base, storage, and platform calls through `self.plugin` are automatically associated with the current run and validated against `ctx.resources`. Do not pass `run_id`. After the handler returns, do not use this context or its run-bound calls from background tasks.
+
+`ctx.api` is the lower-level run-scoped proxy. Normal component code should prefer the `ctx` methods listed on this page and use `self.plugin` for LangBot APIs.
+
+## Data-only contexts
+
+The following components receive task input rather than an EventListener or Runner execution context. Their fields, return values, and complete examples live in the corresponding component guides.
+
+| Component entry point | Main data | Component guide |
+| --- | --- | --- |
+| `KnowledgeEngine.ingest(context: IngestionContext)` | File, target knowledge base, creation settings, and parse result | [KnowledgeEngine](/en/plugin/dev/components/knowledge-engine#document-ingestion) |
+| `KnowledgeEngine.retrieve(context: RetrievalContext)` | Query, target knowledge base, retrieval settings, and filters | [KnowledgeEngine](/en/plugin/dev/components/knowledge-engine#knowledge-retrieval) |
+| `KnowledgeRetriever.retrieve(context: RetrievalContext)` | Query and external knowledge-base settings | [KnowledgeRetriever](/en/plugin/dev/components/knowledge-retriever#retrieval-context) |
+| `Parser.parse(context: ParseContext)` | File content, filename, MIME type, and metadata | [Parser](/en/plugin/dev/components/parser#parse-method) |
+| `Page.handle_api(request: PageRequest)` | Endpoint, HTTP method, body, and headers | [Page](/en/plugin/dev/components/page#pagerequest-fields) |
diff --git a/docs/en/plugin/dev/apis/common.mdx b/docs/en/plugin/dev/apis/common.mdx
new file mode 100644
index 000000000..a335ef016
--- /dev/null
+++ b/docs/en/plugin/dev/apis/common.mdx
@@ -0,0 +1,733 @@
+---
+title: "LangBot API"
+---
+
+Use `self.plugin` for models, tools, knowledge bases, and storage. For the current event, replies, and conversation state, see [Context APIs](/en/plugin/dev/apis/agent-run).
+
+See [LLM request configuration](/en/plugin/dev/apis/llm-requests) for retries, timeouts, numeric reasoning budgets, prompt caching, headers and stream cancellation.
+
+## LangBot API
+
+These APIs can be called in any plugin component. Access methods:
+
+- In the plugin root directory `main.py`: Internal methods of the `self` object, these APIs are all provided by the plugin class parent class `BasePlugin`.
+- In regular plugin component classes: Internal methods of the `self.plugin` object.
+
+### Get Plugin Configuration
+
+Plugin configuration format can be written in `manifest.yaml`, and users need to fill it out according to the plugin configuration format in LangBot's plugin management. Plugin code can then call this API to get plugin configuration information.
+
+```python
+def get_config(self) -> dict[str, typing.Any]:
+ """Get the config of the plugin."""
+
+# Usage example
+config = self.plugin.get_config()
+```
+
+### Get LangBot Version
+
+Get the LangBot version number, returned as a string in format `v..`.
+
+```python
+async def get_langbot_version(self) -> str:
+ """Get the langbot version"""
+
+# Usage example
+langbot_version = await self.plugin.get_langbot_version()
+```
+
+### Get Configured Bot List
+
+Returns a list of all bot UUIDs.
+
+```python
+async def get_bots(self) -> list[str]:
+ """Get all bots"""
+
+# Usage example
+bots = await self.plugin.get_bots()
+```
+
+### Get Bot Information
+
+Get bot information.
+
+```python
+async def get_bot_info(self, bot_uuid: str) -> dict[str, Any]:
+ """Get a bot info"""
+
+# Usage example
+bot_info = await self.plugin.get_bot_info("de639861-be05-4018-859b-c2e2d3e0d603")
+
+# Return example
+{
+ "uuid": "de639861-be05-4018-859b-c2e2d3e0d603",
+ "name": "aiocqhttp",
+ "description": "Migrated from LangBot v3",
+ "adapter": "aiocqhttp",
+ "enable": true,
+ "use_pipeline_name": "ChatPipeline",
+ "use_pipeline_uuid": "c30a1dca-e91c-452b-83ec-84d635a30028",
+ "created_at": "2025-05-10T13:53:08",
+ "updated_at": "2025-08-12T11:27:30",
+ "adapter_runtime_values": { # Present if the bot is currently running
+ "bot_account_id": 960164003 # Bot account ID
+ }
+}
+```
+
+### Send Proactive Message
+
+Send proactive messages through bot UUID and target session ID.
+
+For message chain construction methods, please refer to [Message Platform Entities](/en/plugin/dev/apis/messages).
+
+```python
+async def send_message(
+ self,
+ bot_uuid: str,
+ target_type: str,
+ target_id: str,
+ message_chain: platform_message.MessageChain,
+) -> None:
+ """Send a message to a session"""
+
+# Usage example
+await self.plugin.send_message(
+ bot_uuid="de639861-be05-4018-859b-c2e2d3e0d603",
+ target_type="person",
+ target_id="1010553892",
+ message_chain=platform_message.MessageChain([platform_message.Plain(text="Hello, world!")]),
+)
+```
+
+### Get Configured LLM Model List
+
+Returns a list of UUIDs for all configured LLM models.
+
+```python
+async def get_llm_models(self) -> list[str]:
+ """Get all LLM models"""
+
+# Usage example
+llm_models = await self.plugin.get_llm_models()
+```
+
+### Invoke LLM Model
+
+Invoke an LLM model, returns an LLM message. Non-streaming.
+
+```python
+async def invoke_llm(
+ self,
+ llm_model_uuid: str,
+ messages: list[provider_message.Message],
+ funcs: list[resource_tool.LLMTool] = [],
+ extra_args: dict[str, Any] = {},
+ timeout: float | None = None,
+ *,
+ reasoning_level: ReasoningLevel | None = None,
+) -> provider_message.Message:
+ """Invoke an LLM model"""
+
+# Usage example
+llm_message = await self.plugin.invoke_llm(
+ llm_model_uuid="llm_model_uuid",
+ messages=[provider_message.Message(role="user", content="Hello, world!")],
+ funcs=[],
+ extra_args={},
+)
+```
+
+
+### Reasoning level
+
+All model invocation methods above accept the optional keyword-only `reasoning_level` parameter:
+
+```python
+response = await self.plugin.invoke_llm(
+ llm_model_uuid=model_uuid,
+ messages=[provider_message.Message(role="user", content="Analyze this problem")],
+ reasoning_level="medium",
+)
+```
+
+Values are `provider_default`, `disabled`, `enabled`, `minimal`, `low`, `medium`, `high`, `xhigh`, and `max`. Available levels depend on the model. LangBot validates support and translates the level into provider parameters; unsupported levels raise an error.
+
+- Omitted or `None`: preserves existing model configuration and `extra_args` behavior.
+- `provider_default`: adds no explicit reasoning level.
+- Other levels: apply to this call only. Do not also supply provider-specific reasoning parameters through `extra_args`.
+
+Runners read their own configuration and explicitly pass the appropriate level for each call, including fallback models and tool follow-ups. LangBot does not extract reasoning levels from Runner configuration. Existing plugins require no changes; when an explicit option is used with an unsupported Host, the SDK requests an upgrade before invoking the model.
+
+### Model streaming and usage
+
+| Method | Returns |
+| --- | --- |
+| `invoke_llm_with_usage(llm_model_uuid, messages, funcs=[], extra_args={}, timeout=None, *, reasoning_level=None)` | `LLMInvokeResult` |
+| `invoke_llm_stream(llm_model_uuid, messages, funcs=[], extra_args={}, *, reasoning_level=None)` | Async iterator of `MessageChunk` |
+| `invoke_llm_stream_events(llm_model_uuid, messages, funcs=[], extra_args={}, *, reasoning_level=None)` | Async iterator of `LLMStreamEvent` |
+
+
+Parameters match `invoke_llm`. `timeout` is in seconds; non-streaming calls default to 120 seconds. Use `invoke_llm_with_usage` when token usage is needed:
+
+```python
+from langbot_plugin.api.entities.builtin.provider.message import Message
+
+result = await self.plugin.invoke_llm_with_usage(
+ llm_model_uuid=model_uuid,
+ messages=[Message(role="user", content="Hello!")],
+)
+print(result.message.content)
+if result.usage is not None:
+ print(result.usage.total_tokens)
+```
+
+`usage` may be `None`; `prompt_tokens`, `completion_tokens`, and `total_tokens` may also be absent. Missing values do not mean zero usage. Additional provider fields, such as cache usage, are preserved.
+
+```python
+async for event in self.plugin.invoke_llm_stream_events(
+ llm_model_uuid=model_uuid,
+ messages=[Message(role="user", content="Hello!")],
+):
+ if event.chunk is not None:
+ print(event.chunk.content)
+ if event.usage is not None:
+ print(event.usage.model_dump())
+```
+
+`LLMStreamEvent` has optional `chunk` and `usage`; the final event may contain usage without text. `invoke_llm_stream` yields only message/tool-call chunks. `MessageChunk.content` is the current chunk; `all_content`, when supplied, is accumulated text. Replace with accumulated text and append only deltas; an `is_final` chunk may still carry text. Model streaming does not send platform messages; see [Run Context APIs](/en/plugin/dev/apis/agent-run) for explicit streaming replies.
+
+### List Available Parsers
+
+List Parser plugins currently available on the host, optionally filtered by MIME type.
+
+```python
+async def list_parsers(self, mime_type: str | None = None) -> list[dict[str, Any]]:
+ """List available Parser plugins"""
+
+# Usage example
+parsers = await self.plugin.list_parsers(mime_type="application/pdf")
+# Each item includes plugin_id, plugin_author, plugin_name, name, description, supported_mime_types
+```
+
+### List All Available Tools
+
+List all available tools in the current LangBot instance (including plugin tools and MCP tools).
+
+```python
+async def list_tools(self) -> list[dict[str, Any]]:
+ """List all available tools
+
+ Returns:
+ A list of tool dicts, each containing:
+ - name: Tool name
+ - label: Display label (i18n)
+ - description: Tool description (i18n)
+ - icon: Tool icon
+ - spec: Tool specification (includes llm_prompt and parameters)
+ """
+
+# Example
+tools = await self.plugin.list_tools()
+for tool in tools:
+ print(f"Tool: {tool['name']}")
+```
+
+### Get Tool Detail
+
+Get detailed information about a specific tool.
+
+```python
+async def get_tool_detail(self, tool_name: str) -> dict[str, Any]:
+ """Get detailed information about a specific tool
+
+ Args:
+ tool_name: Tool name (metadata.name, e.g. "get_weather_alerts")
+
+ Returns:
+ Tool detail dict containing name, label, description, spec (with parameters and llm_prompt)
+ """
+
+# Example
+detail = await self.plugin.get_tool_detail("get_weather_alerts")
+print(detail['spec']['parameters'])
+```
+
+### Call Tool
+
+Call a specific tool.
+
+```python
+async def call_tool(
+ self,
+ tool_name: str,
+ parameters: dict[str, Any],
+ session: dict[str, Any],
+ query_id: int,
+) -> dict[str, Any]:
+ """Call a specific tool
+
+ Args:
+ tool_name: Tool name (metadata.name)
+ parameters: Tool parameters
+ session: Session info
+ query_id: Query ID
+
+ Returns:
+ Tool response dict
+ """
+
+# Example
+result = await self.plugin.call_tool(
+ tool_name="get_weather_alerts",
+ parameters={"state": "CA"},
+ session={},
+ query_id=0,
+)
+print(result)
+```
+
+
+Tool names use `metadata.name` (e.g. `echo_tool`, `get_weather_alerts`), without author or plugin name prefix.
+
+
+### Set Plugin Persistent Data
+
+Persistently store plugin data. Data stored through this interface can only be accessed by this plugin. Values need to be converted to bytes manually.
+
+```python
+async def set_plugin_storage(self, key: str, value: bytes) -> None:
+ """Set a plugin storage value"""
+
+# Usage example
+await self.plugin.set_plugin_storage("key", b"value")
+```
+
+### Get Plugin Persistent Data
+
+```python
+async def get_plugin_storage(self, key: str) -> bytes:
+ """Get a plugin storage value"""
+
+# Usage example
+plugin_storage = await self.plugin.get_plugin_storage("key")
+```
+
+### Get All Plugin Persistent Data Keys
+
+```python
+async def get_plugin_storage_keys(self) -> list[str]:
+ """Get all plugin storage keys"""
+
+# Usage example
+plugin_storage_keys = await self.plugin.get_plugin_storage_keys()
+```
+
+### Delete Plugin Persistent Data
+
+```python
+async def delete_plugin_storage(self, key: str) -> None:
+ """Delete a plugin storage value"""
+
+# Usage example
+await self.plugin.delete_plugin_storage("key")
+```
+
+### Get Workspace Persistent Data
+
+Data stored through this interface can be accessed by all plugins. Values need to be converted to bytes manually.
+
+```python
+async def set_workspace_storage(self, key: str, value: bytes) -> None:
+ """Set a workspace storage value"""
+
+# Usage example
+await self.plugin.set_workspace_storage("key", b"value")
+```
+
+### Get Workspace Persistent Data
+
+```python
+async def get_workspace_storage(self, key: str) -> bytes:
+ """Get a workspace storage value"""
+
+# Usage example
+workspace_storage = await self.plugin.get_workspace_storage("key")
+```
+
+### Get All Workspace Persistent Data Keys
+
+```python
+async def get_workspace_storage_keys(self) -> list[str]:
+ """Get all workspace storage keys"""
+
+# Usage example
+workspace_storage_keys = await self.plugin.get_workspace_storage_keys()
+```
+
+### Delete Workspace Persistent Data
+
+```python
+async def delete_workspace_storage(self, key: str) -> None:
+ """Delete a workspace storage value"""
+
+# Usage example
+await self.plugin.delete_workspace_storage("key")
+```
+
+### Get Plugin File-typed Config Field Data
+
+```python
+async def get_config_file(self, file_key: str) -> bytes:
+ """Get a config file value"""
+
+# Usage example
+file_bytes = await self.plugin.get_config_file("key")
+```
+
+Use this in conjunction with configuration fields of type [``file or array[file``](/en/plugin/dev/basic-info.html#type-file).
+
+## Knowledge Base API
+
+These APIs are accessible via `self.plugin` in regular components, allowing you to list and retrieve from all knowledge bases in the LangBot instance without pipeline restrictions.
+
+### List All Knowledge Bases
+
+List all available knowledge bases in the LangBot instance.
+
+```python
+async def list_knowledge_bases(self) -> list[dict[str, Any]]:
+ """List all knowledge bases
+
+ Returns:
+ List of knowledge base dicts, each containing:
+ - uuid: Knowledge base UUID
+ - name: Knowledge base name
+ - description: Knowledge base description
+ """
+
+# Usage example
+knowledge_bases = await self.plugin.list_knowledge_bases()
+for kb in knowledge_bases:
+ print(f"KB: {kb['name']} ({kb['uuid']})")
+```
+
+### Retrieve from Knowledge Base
+
+Retrieve relevant documents from any knowledge base.
+
+```python
+async def retrieve_knowledge(
+ self,
+ kb_id: str,
+ query_text: str,
+ top_k: int = 5,
+ filters: dict[str, Any] | None = None,
+) -> list[dict[str, Any]]:
+ """Retrieve from a knowledge base
+
+ Args:
+ kb_id: Knowledge base UUID (from list_knowledge_bases)
+ query_text: Search query text
+ top_k: Number of results to return (default: 5)
+ filters: Optional metadata filters for retrieval
+
+ Returns:
+ List of retrieval result entries
+ """
+
+# Usage example
+results = await self.plugin.retrieve_knowledge(
+ kb_id="kb-uuid-here",
+ query_text="How to configure the system?",
+ top_k=3,
+)
+for entry in results:
+ print(entry)
+```
+
+
+These APIs do not require a `query_id` and can be used in regular components (including Tool components). They can access all knowledge bases without being restricted to the current pipeline's configuration.
+
+
+## RAG API
+
+These APIs are available for `KnowledgeEngine` components to access the LangBot host's embedding models, vector database, and file storage. Access method:
+
+- In `KnowledgeEngine` component classes: Internal methods of the `self.plugin` object.
+
+### Invoke Embedding Model
+
+Generate text embeddings using the host's configured embedding model.
+
+```python
+async def invoke_embedding(
+ self,
+ embedding_model_uuid: str,
+ texts: list[str],
+) -> list[list[float]]:
+ """Generate embeddings using host's embedding model
+
+ Args:
+ embedding_model_uuid: Embedding model UUID
+ texts: List of texts to embed
+
+ Returns:
+ List of embedding vectors, one per input text
+ """
+
+# Usage example
+vectors = await self.plugin.invoke_embedding("model_uuid", ["Hello", "World"])
+```
+
+### Vector Upsert
+
+Upsert vectors to the host's vector database.
+
+```python
+async def vector_upsert(
+ self,
+ collection_id: str,
+ vectors: list[list[float]],
+ ids: list[str],
+ metadata: list[dict[str, Any]] | None = None,
+ documents: list[str] | None = None,
+) -> None:
+ """Upsert vectors
+
+ Args:
+ collection_id: Target collection ID
+ vectors: List of vectors
+ ids: List of unique IDs for vectors
+ metadata: Optional list of metadata dicts
+ documents: Optional raw text documents. Required for full-text
+ and hybrid search in backends that support them.
+ """
+
+# Usage example
+await self.plugin.vector_upsert(
+ collection_id="kb_uuid",
+ vectors=[[0.1, 0.2, ...], [0.3, 0.4, ...]],
+ ids=["chunk_0", "chunk_1"],
+ metadata=[{"document_id": "doc1"}, {"document_id": "doc1"}],
+ documents=["chunk text 0", "chunk text 1"],
+)
+```
+
+### Vector Search
+
+Search similar vectors in the host's vector database.
+
+```python
+async def vector_search(
+ self,
+ collection_id: str,
+ query_vector: list[float],
+ top_k: int = 5,
+ filters: dict[str, Any] | None = None,
+ search_type: str = "vector",
+ query_text: str = "",
+) -> list[dict[str, Any]]:
+ """Vector search
+
+ Args:
+ collection_id: Target collection ID
+ query_vector: Query vector for similarity search
+ top_k: Number of results to return
+ filters: Optional metadata filters
+ search_type: One of 'vector', 'full_text', 'hybrid'
+ query_text: Raw query text, used for full_text and hybrid search
+
+ Returns:
+ List of search results (dict with id, score, metadata, etc.)
+ """
+
+# Usage example
+results = await self.plugin.vector_search(
+ collection_id="kb_uuid",
+ query_vector=[0.1, 0.2, ...],
+ top_k=5,
+ search_type="hybrid",
+ query_text="search query",
+)
+# Return format: [{"id": "chunk_0", "score": 0.123, "metadata": {"document_id": "doc1", ...}}, ...]
+```
+
+
+Each result returned by `vector_search` is a dict containing `id` (vector ID), `score` (distance score), and `metadata` (metadata provided during upsert). If you need text content in retrieval results, store the text in metadata during ingestion.
+
+
+### Vector Delete
+
+Delete vectors from the host's vector database.
+
+```python
+async def vector_delete(
+ self,
+ collection_id: str,
+ file_ids: list[str] | None = None,
+ filters: dict[str, Any] | None = None,
+) -> int:
+ """Vector delete
+
+ Args:
+ collection_id: Target collection ID
+ file_ids: File IDs whose vectors should be deleted
+ filters: Optional metadata filters for deletion
+
+ Returns:
+ Number of deleted items
+ """
+
+# Usage example
+deleted = await self.plugin.vector_delete(
+ collection_id="kb_uuid",
+ file_ids=["doc_001"],
+)
+```
+
+
+The `filters` parameter supports Chroma-style `where` syntax for metadata filtering. Multiple top-level keys are AND-ed. Supported operators: `$eq`, `$ne`, `$gt`, `$gte`, `$lt`, `$lte`, `$in`, `$nin`.
+
+```python
+# Implicit $eq
+results = await self.plugin.vector_search(
+ collection_id="kb_uuid",
+ query_vector=[0.1, 0.2, ...],
+ filters={"file_id": "abc"},
+)
+
+# Comparison operator
+results = await self.plugin.vector_search(
+ collection_id="kb_uuid",
+ query_vector=[0.1, 0.2, ...],
+ filters={"created_at": {"$gte": 1700000000}},
+)
+
+# In-list operator
+results = await self.plugin.vector_search(
+ collection_id="kb_uuid",
+ query_vector=[0.1, 0.2, ...],
+ filters={"file_type": {"$in": ["pdf", "docx"]}},
+)
+
+# Delete by filter
+deleted = await self.plugin.vector_delete(
+ collection_id="kb_uuid",
+ filters={"file_type": {"$eq": "pdf"}},
+)
+```
+
+**Note:** Chroma, Qdrant, and SeekDB store full metadata and can filter on any field. Milvus and pgvector only store `text`, `file_id`, and `chunk_uuid` — filters on other fields will be silently ignored.
+
+
+Get uploaded file content from the host's storage.
+
+```python
+async def get_knowledge_file_stream(self, storage_path: str) -> bytes:
+ """Get file content
+
+ Args:
+ storage_path: File storage path (from FileObject.storage_path)
+
+ Returns:
+ File content as bytes
+ """
+
+# Usage example
+file_bytes = await self.plugin.get_knowledge_file_stream(context.file_object.storage_path)
+```
+
+
+## Additional resource APIs
+
+These methods are also called through `self.plugin`.
+
+### Invoke a rerank model
+
+```python
+async def invoke_rerank(
+ self, rerank_model_uuid: str, query: str, documents: list[str],
+ top_k: int | None = None, extra_args: dict[str, Any] | None = None,
+ timeout: float = 60.0,
+) -> list[dict[str, Any]]:
+ ...
+
+scores = await self.plugin.invoke_rerank(
+ rerank_model_uuid=rerank_model_uuid,
+ query="How do I configure a bot?",
+ documents=["Bot configuration guide", "Plugin publishing guide"],
+ top_k=1,
+)
+```
+
+Results usually contain the original document `index` and `relevance_score`.
+
+### Invoke a parser
+
+```python
+async def invoke_parser(
+ self, plugin_author: str, plugin_name: str, storage_path: str,
+ mime_type: str, filename: str, metadata: dict[str, Any] | None = None,
+) -> dict[str, Any]:
+ ...
+
+parsers = await self.plugin.list_parsers(mime_type="application/pdf")
+if parsers:
+ parser = parsers[0]
+ parsed = await self.plugin.invoke_parser(
+ plugin_author=parser["plugin_author"],
+ plugin_name=parser["plugin_name"],
+ storage_path=storage_path,
+ mime_type="application/pdf",
+ filename="guide.pdf",
+ )
+```
+
+`storage_path` is a Host storage path, such as `context.file_object.storage_path` during knowledge ingestion, not a plugin-local path. The result dictionary contains `text`, `sections`, and `metadata`.
+
+### List vector records
+
+```python
+async def vector_list(
+ self, collection_id: str, filters: dict[str, Any] | None = None,
+ limit: int = 20, offset: int = 0,
+) -> dict[str, Any]:
+ ...
+
+page = await self.plugin.vector_list(
+ collection_id=collection_id,
+ filters={"file_id": "doc_001"},
+ limit=20,
+ offset=0,
+)
+for item in page["items"]:
+ print(item["id"], item.get("metadata"))
+```
+
+Returns `items` and `total`. Items contain `id`, `document`, and `metadata`; `total` is a best-effort matching count from the storage backend. Filters use the vector API format above.
+
+### List plugins and commands
+
+```python
+manifests = await self.plugin.list_plugins_manifest()
+commands = await self.plugin.list_commands()
+```
+
+Both methods take no arguments and return the Host-provided plugin manifest list and command list respectively.
+
+### Box sandbox
+
+These methods use `self.plugin` and the current Workspace. Runner calls automatically retain invocation authorization.
+
+| Method | Returns | Behavior |
+| --- | --- | --- |
+| `await self.plugin.get_box_status()` | `BoxStatus` | `enabled`, `available`, capacity `limit`, `used`, `remaining`, optional managed `required_reuse_key`, and unavailable `reason` |
+| `await self.plugin.list_boxes()` | `list[BoxSession]` | Box `id` and `status` snapshot (`idle`, `running`, `closing`) |
+| `await self.plugin.acquire_box(reuse_key, options=None)` | `BoxSession` | Reuse the same key or create within capacity; `options` supports `image` |
+
+Unknown capacity fields are `None`. Zero remaining capacity still permits reuse; Runtime checks creation capacity atomically. The Runner computes reuse keys. When `required_reuse_key` is supplied, use it. Equal keys in different Workspaces never share a Box.
+
+Use the [Runner context](/en/plugin/dev/apis/agent-run#runner) to bind the Box before importing attachments or executing tools.
diff --git a/docs/en/plugin/dev/apis/llm-requests.mdx b/docs/en/plugin/dev/apis/llm-requests.mdx
new file mode 100644
index 000000000..800f8610b
--- /dev/null
+++ b/docs/en/plugin/dev/apis/llm-requests.mdx
@@ -0,0 +1,134 @@
+---
+title: "LLM request configuration"
+description: "Retries, deadlines, reasoning budgets, caching and stream cancellation for plugins and Runners"
+---
+
+These options require a Core build containing [Core #2661](https://github.com/langbot-app/LangBot/pull/2661). A merged PR does not imply a published release. Pass them through the existing `extra_args`; plugin and Runner signatures, message types and authorization remain unchanged. See [LangBot API](/en/plugin/dev/apis/common) and [Context APIs](/en/plugin/dev/apis/agent-run).
+
+## Retries and timeouts
+
+The following non-streaming example configures the request and reads complete usage:
+
+```python
+from langbot_plugin.api.entities.builtin.provider.message import Message
+
+result = await self.plugin.invoke_llm_with_usage(
+ llm_model_uuid=model_uuid,
+ messages=[Message(role="user", content="Hello!")],
+ timeout=110,
+ extra_args={
+ "request_policy": {
+ "retries": 1,
+ "total_timeout": 90,
+ "first_event_timeout": 30,
+ "stream_idle_timeout": 30,
+ "connect_timeout": 10,
+ "read_timeout": 60,
+ },
+ },
+)
+print(result.message.content)
+if result.usage is not None:
+ print(result.usage.model_dump())
+```
+
+Runner `ctx.api.invoke_llm*` accepts the same `extra_args`, subject to run authorization and remaining time. Calls through `self.plugin` also inherit these restrictions inside a run context.
+
+`timeout=` is the SDK/RPC waiting limit (120 seconds by default for non-streaming calls). Core's `request_policy` controls the inner request. Keep its total budget within the enclosing RPC/Runner deadline; raising it cannot extend that deadline. Streaming methods have no `timeout=` argument and remain bounded by SDK/Runner waiting limits.
+
+| `request_policy` field | Default | Meaning |
+| --- | --- | --- |
+| `retries` | `0` | Additional attempts after the first, integer 0–5 |
+| `total_timeout` | `300` | Whole invocation budget, including backoff |
+| `first_event_timeout` | `120` | Wait for the first upstream event, not the first visible text |
+| `stream_idle_timeout` | `120` | Idle time between stream events |
+| `connect_timeout` | `10` | Connection timeout |
+| `read_timeout` | `120` | Transport read timeout |
+| `write_timeout` | `30` | Transport write timeout |
+| `pool_timeout` | `10` | Connection pool acquisition timeout |
+| `backoff_base` / `backoff_max` | `0.5` / `8` | Exponential backoff base and cap, with full jitter |
+| `attribution` | `True` | Automatic application attribution headers |
+| `conversation_header` | `None` | Generated session header name, described below |
+
+Times are seconds; timeouts must be finite and positive. Unknown policy fields are rejected. Precedence: instance `llm_request_policy`, model `extra_args`, then call `extra_args`. Within one layer, `request_policy.retries` wins over legacy `num_retries` / `max_retries`. A call-level legacy value still overrides model policy; `0` disables retries. Legacy numeric `extra_args["timeout"]` sets read, first-event and stream-idle limits without extending the total budget.
+
+Authentication, invalid-request and exhausted-quota failures are not retried. Retries stop after any upstream event, including reasoning or usage. `Retry-After` is bounded by the remaining budget. Core disables LiteLLM and provider SDK retries for managed calls; gateways may independently retry. This adds no tool replay, model fallback or embedding/rerank retries. Legacy third-party requesters still own their transport configuration.
+
+## Reasoning budgets
+
+Existing `reasoning_level` behavior is unchanged. For a numeric budget, pass this object as `extra_args` or save it in model advanced parameters. Omitting `level` means `enabled`:
+
+```json
+{
+ "reasoning_config": {"budget_tokens": 2048},
+ "max_tokens": 4096
+}
+```
+
+Do not combine a budget with an effort level such as `medium`, `disabled`, or native reasoning parameters. Direct Anthropic calls require explicit `max_tokens` greater than the budget; Core never raises that limit automatically.
+
+Precedence: persisted model `reasoning_config`, model `extra_args.reasoning_config`, call `extra_args.reasoning_config`, then an explicit Runner level override. Each object replaces the previous one; an effort override clears a lower-priority budget.
+
+Numeric budgets map to native Anthropic, Gemini 2.5, supported Qwen models and OpenRouter routes. Direct OpenAI/Codex and adaptive-only Claude models retain effort control. Check the model's `reasoning_capabilities.budget_tokens` for support and bounds. Unsupported budgets fail before HTTP. Providers/gateways may impose stricter limits; OpenRouter may translate a numeric budget into effort.
+
+## Prompt caching
+
+`extra_args.prompt_caching` is consumed by Core, not forwarded unchanged. Call configuration replaces model configuration. The default `{"mode": "provider_default"}` adds no fields. This is not a local response cache.
+
+| Configuration | Behavior |
+| --- | --- |
+| `{"mode": "openai", "retention": "in_memory"}` | Generates a model-and-conversation-scoped `prompt_cache_key` when conversation context exists; optional `retention` also accepts `24h` if supported by the target |
+| `{"mode": "anthropic", "ttl": "5m"}` | Adds an ephemeral breakpoint to the last text block of the leading system/developer prefix; `ttl` accepts `5m` or `1h` |
+
+OpenAI mode applies to compatible routes and OpenRouter OpenAI models supporting these options. Explicit native `prompt_cache_key`, `prompt_cache_retention` and `prompt_cache_options` win. Anthropic mode supports native Claude and OpenRouter Claude. Existing native cache markers are preserved without adding duplicates. Core does not reorder tools/history or mark user messages, and inserts nothing without an eligible prefix.
+
+Hints do not guarantee hits. Inspect `usage.model_dump()` for provider fields such as `prompt_tokens_details.cached_tokens` or `cache_read_input_tokens`; missing counts are not zero. Minimum prefix lengths, retention eligibility and pricing are provider-controlled. Codex's restricted Responses body does not accept this configuration object; existing server caching remains. General Responses migration and Gemini explicit cache-resource management are outside this change.
+
+## Application and session headers
+
+Direct OpenRouter calls receive `HTTP-Referer: https://langbot.app`, `X-OpenRouter-Title: LangBot`, and, with conversation context, `x-session-id: lb-`. Custom gateway addresses do not automatically inherit these headers. `request_policy.attribution=False` disables only automatic application attribution. Explicit `extra_headers` remain and take precedence case-insensitively.
+
+A gateway can use an explicitly configured session header:
+
+```json
+{
+ "request_policy": {"conversation_header": "x-litellm-session-id"},
+ "extra_headers": {
+ "HTTP-Referer": "https://langbot.app",
+ "X-OpenRouter-Title": "LangBot"
+ }
+}
+```
+
+Supported names: `x-session-id`, `x-litellm-session-id`, `x-langbot-conversation-id`. The last is a custom convention, not a universal provider standard, and provides no automatic routing or caching benefit. Generated identifiers are scoped by workspace/bot/pipeline/session and contain no raw session ID or prompt. They are pseudonymous, not a guarantee of anonymization, and are omitted without context. New API and other gateways may filter or rewrite headers; verify forwarding rules and actual outbound requests.
+
+## Stream cancellation and compatibility
+
+Use `aclosing` when leaving a stream early. Allow task cancellation exceptions to propagate:
+
+```python
+from contextlib import aclosing
+from langbot_plugin.api.entities.builtin.provider.message import Message
+
+async with aclosing(self.plugin.invoke_llm_stream_events(
+ llm_model_uuid=model_uuid,
+ messages=[Message(role="user", content="Hello!")],
+ extra_args={"request_policy": {"retries": 0, "total_timeout": 90}},
+)) as events:
+ async for event in events:
+ if event.usage is not None:
+ print(event.usage.model_dump())
+ if event.chunk is not None and event.chunk.content:
+ print(event.chunk.content)
+ break
+```
+
+This example intentionally stops after the first nonempty content chunk and may miss final usage. For a complete response, remove `break`; a final event can have usage without a chunk. `invoke_llm` still returns `Message`, and `invoke_llm_stream` still yields `MessageChunk`. Choose `invoke_llm_with_usage` or `invoke_llm_stream_events` for accounting. Usage may be `None`; nested cache/reasoning counts and provider-specific fields are preserved.
+
+SDK ≤0.7.11 has a proxy-layer defect that delays upstream cancellation on early close. Deterministic close requires **langbot-plugin ≥0.7.12**, which publishes the fix from [SDK #177](https://github.com/langbot-app/langbot-plugin-sdk/pull/177). A Core dependency pin does not automatically upgrade a separately deployed Runtime or plugin development environment; upgrade those executing environments too. Ordinary signatures, payloads and return types remain compatible. Total deadlines include consumer time, but cannot interrupt a consumer while the generator is suspended at `yield`; expiration is enforced on the next pull.
+
+## Diagnostics
+
+Core monitoring records expose `details.timing`, complete `usage` and structured `error`; legacy SDK exception transport is unchanged. Structured errors include `code`, `status_code`, `retryable`, `retry_after`, `request_id` and `phase`. Do not assume these fields exist on legacy exceptions received by plugins.
+
+Millisecond timings include `preparation_ms`, `transport_setup_ms`, `first_event_ms`, `first_reasoning_ms`, `first_content_ms`, `first_visible_chunk_ms`, `total_ms`, plus `attempts` and `retry_wait_ms`. The first event may be reasoning/control, and the first visible chunk may include reasoning. `request_started_ms` marks the SDK call, not a packet leaving the socket. Missing fields mean unobserved, not zero. Monitoring retains partial usage received before cancellation but cannot reconstruct missing upstream accounting.
diff --git a/docs/en/plugin/dev/apis/messages.mdx b/docs/en/plugin/dev/apis/messages.mdx
new file mode 100644
index 000000000..e4a084016
--- /dev/null
+++ b/docs/en/plugin/dev/apis/messages.mdx
@@ -0,0 +1,65 @@
+---
+title: "Message Platform Entities"
+---
+
+LangBot supports multiple messaging platforms, and each platform has different `message entity` formats. To abstract away these differences, we have implemented a unified standard. Plugin developers only need to master and use the message entities described on this page in plugins, and LangBot's internal message processing logic can automatically handle message parsing and conversion.
+
+## Message Chain
+
+`Messages` on messaging platforms are different from messages used for AI interaction. Messages on messaging platforms are described in the form of `message chains`. Each independent message displayed on QQ is a message chain, which can contain various `message chain components` such as `text`, `images`, `@mentions`, etc. For example:
+
+
+
+This is a message chain containing one Plain component (Hello World) and one Image component (Usagi).
+
+The definitions of message chains and message chain components are located in `langbot_plugin.api.entities.builtin.platform.message`.
+
+### Constructing Message Chains
+
+Please first import the `langbot_plugin.api.entities.builtin.platform.message` package to use the message components within it.
+
+```python
+from langbot_plugin.api.entities.builtin.platform.message import *
+
+# Build a message containing text "Hello LangBot" and an image (from URL)
+msg_chain = MessageChain([
+ Plain(text="Hello LangBot"),
+ Image(url='https://qchatgpt.rockchin.top/langbot-logo.png')
+])
+
+# Build a message containing @everyone and text "Hello LangBot"
+msg_chain = MessageChain([
+ AtAll(),
+ Plain(text="Hello LangBot")
+])
+
+# Build a message containing @specific member and text "Hello LangBot"
+msg_chain = MessageChain([
+ At(target=123456),
+ Plain(text="Hello LangBot")
+])
+```
+
+Currently supported message chain components:
+
+- `Source` - Source message chain information. Messages received from messaging platforms will include this component at the front of the message chain to record message information
+- `Plain` - Plain text message
+- `Quote` - Quote message
+- `Image` - Image message
+- `AtAll` - @everyone message
+- `At` - @specific member message
+- `Voice` - Voice message
+ - Need to check messaging platform support
+- `Forward` - Forward message
+ - Not supported on many platforms, not recommended
+- `File` - File message
+
+When creating components, named parameters must be used. For specific usage, you can check the definitions in the source code `langbot_plugin.api.entities.builtin.platform.message`.
+
+## Other Entities
+
+In addition to the above entities, there are also entities like `Friend` and `Group`. These entities are defined in `langbot_plugin.api.entities.builtin.platform.entities`.
+
+## Platform APIs
+
+Use [Platform APIs](/en/plugin/dev/apis/platform) to query users, manage groups, and call platform-specific actions. Runner uses the same `self.plugin` entrypoint; use `ctx.reply()` for the current conversation.
diff --git a/docs/en/plugin/dev/apis/pipeline-events.mdx b/docs/en/plugin/dev/apis/pipeline-events.mdx
new file mode 100644
index 000000000..50183854f
--- /dev/null
+++ b/docs/en/plugin/dev/apis/pipeline-events.mdx
@@ -0,0 +1,271 @@
+---
+title: "Pipeline Events and APIs"
+---
+
+LangBot plugins can register and handle pipeline events. For usage instructions, see [Component: Event Listener](/en/plugin/dev/components/event-listener).
+
+## List of Events
+
+Some events have `settable attributes`, which can be modified by plugin code and used in subsequent LangBot processing.
+
+### \*MessageReceived
+
+Triggered when any message is received in group chat or private chat.
+
+```python
+class PersonMessageReceived(BaseEventModel):
+ """When any private chat message is received"""
+
+ event_name: str = "PersonMessageReceived"
+
+ launcher_type: str
+ """Launcher object type (person)"""
+
+ launcher_id: typing.Union[int, str]
+ """Sender ID"""
+
+ sender_id: typing.Union[int, str]
+ """Sender ID, same as launcher_id in private chat"""
+
+ message_event: platform_events.PersonMessage
+ """Original message event object. Contains sender information."""
+
+ message_chain: platform_message.MessageChain = pydantic.Field(
+ serialization_alias="message_chain"
+ )
+ """Message chain"""
+
+
+class GroupMessageReceived(BaseEventModel):
+ """When any group chat message is received"""
+
+ event_name: str = "GroupMessageReceived"
+
+ launcher_type: str
+ """Launcher object type (group)"""
+
+ launcher_id: typing.Union[int, str]
+ """Group ID"""
+
+ sender_id: typing.Union[int, str]
+ """Sender ID"""
+
+ message_event: platform_events.GroupMessage
+ """Original message event object. Contains group and sender information."""
+
+ message_chain: platform_message.MessageChain = pydantic.Field(
+ serialization_alias="message_chain"
+ )
+ """Message chain"""
+```
+
+### \*NormalMessageReceived
+
+Triggered when a group chat or private chat message is received and determined to be a message that needs to be processed by LLM (non-command message).
+
+```python
+class PersonNormalMessageReceived(BaseEventModel):
+ """Triggered when a private chat normal message that should be processed is determined"""
+
+ event_name: str = "PersonNormalMessageReceived"
+
+ launcher_type: str
+ """Launcher object type (person)"""
+
+ launcher_id: typing.Union[int, str]
+ """Launcher object ID"""
+
+ sender_id: typing.Union[int, str]
+ """Sender ID, same as launcher_id in private chat"""
+
+ text_message: str
+ """Message text"""
+
+ message_event: platform_events.PersonMessage
+ """Original message event object. Contains sender information."""
+
+ message_chain: platform_message.MessageChain = pydantic.Field(
+ serialization_alias="message_chain"
+ )
+ """Message chain"""
+
+ # ========== Settable Attributes ==========
+
+ user_message_alter: typing.Optional[provider_message.ContentElement] = None
+ """Modified message text, langbot_plugin.api.entities.builtin.provider.message.ContentElement type"""
+
+ reply_message_chain: typing.Optional[platform_message.MessageChain] = None
+ """Direct reply message chain, only effective when preventing default behavior"""
+
+
+class GroupNormalMessageReceived(BaseEventModel):
+ """Triggered when a group chat normal message that should be processed is determined"""
+
+ event_name: str = "GroupNormalMessageReceived"
+
+ launcher_type: str
+ """Launcher object type (group)"""
+
+ launcher_id: typing.Union[int, str]
+ """Group ID"""
+
+ sender_id: typing.Union[int, str]
+ """Sender ID"""
+
+ text_message: str
+ """Message text"""
+
+ message_event: platform_events.GroupMessage
+ """Original message event object. Contains group and sender information."""
+
+ message_chain: platform_message.MessageChain = pydantic.Field(
+ serialization_alias="message_chain"
+ )
+ """Message chain"""
+
+ # ========== Settable Attributes ==========
+
+ user_message_alter: typing.Optional[provider_message.ContentElement] = None
+ """Modified message text, langbot_plugin.api.entities.builtin.provider.message.ContentElement type"""
+
+ reply_message_chain: typing.Optional[platform_message.MessageChain] = None
+ """Direct reply message chain, only effective when preventing default behavior"""
+```
+
+### \*CommandSent
+
+
+ No longer recommended for use, please use [Component: Command](/en/plugin/dev/components/command) instead.
+
+
+Triggered when a group chat or private chat command is received.
+
+```python
+class PersonCommandSent(BaseEventModel):
+ """Triggered when a private chat command that should be processed is determined"""
+
+ event_name: str = "PersonCommandSent"
+
+ launcher_type: str
+
+ launcher_id: typing.Union[int, str]
+
+ sender_id: typing.Union[int, str]
+
+ command: str
+ """Command text"""
+
+ params: list[str]
+ """Command parameters"""
+
+ text_message: str
+ """Message text"""
+
+ is_admin: bool
+ """Whether it's an administrator"""
+
+
+class GroupCommandSent(BaseEventModel):
+ """Triggered when a group chat command that should be processed is determined"""
+
+ event_name: str = "GroupCommandSent"
+
+ launcher_type: str
+
+ launcher_id: typing.Union[int, str]
+
+ sender_id: typing.Union[int, str]
+
+ command: str
+ """Command text"""
+
+ params: list[str]
+ """Command parameters"""
+
+ text_message: str
+ """Message text"""
+
+ is_admin: bool
+ """Whether it's an administrator"""
+```
+
+### NormalMessageResponded
+
+Triggered when a message receives an LLM response.
+
+```python
+class NormalMessageResponded(BaseEventModel):
+ """Triggered when replying to a normal message"""
+
+ event_name: str = "NormalMessageResponded"
+
+ launcher_type: str
+
+ launcher_id: typing.Union[int, str]
+
+ sender_id: typing.Union[int, str]
+
+ session: provider_session.Session
+ """Session object"""
+
+ prefix: str
+ """Reply message prefix"""
+
+ response_text: str
+ """Reply message text"""
+
+ finish_reason: str
+ """Response end reason"""
+
+ funcs_called: list[str]
+ """List of called functions"""
+
+ # ========== Settable Attributes ==========
+
+ reply_message_chain: typing.Optional[platform_message.MessageChain] = None
+ """Reply message component list, only effective when preventing default behavior"""
+```
+
+### PromptPreProcessing
+
+Triggered when building the LLM response context (prompt).
+
+```python
+class PromptPreProcessing(BaseEventModel):
+ """Triggered when preprocessing prompt in session"""
+
+ event_name: str = "PromptPreProcessing"
+
+ session_name: str
+ """Session name, format is person_1234567890 or group_1234567890"""
+
+ # ========== Settable Attributes ==========
+
+ default_prompt: list[typing.Union[provider_message.Message, provider_message.MessageChunk]]
+ """Scenario preset (system prompt) for this conversation, can be modified, langbot_plugin.api.entities.builtin.provider.message.Message or langbot_plugin.api.entities.builtin.provider.message.MessageChunk type"""
+
+ prompt: list[typing.Union[provider_message.Message, provider_message.MessageChunk]]
+ """Existing message records for this conversation, can be modified, langbot_plugin.api.entities.builtin.provider.message.Message or langbot_plugin.api.entities.builtin.provider.message.MessageChunk type"""
+```
+
+## EventListener context
+
+Event handlers read the current event through `event_context.event`. See [Context APIs](/en/plugin/dev/apis/agent-run#eventlistener) for the complete `EventContext` properties and methods.
+
+### Prevent default behavior
+
+Calling `event_context.prevent_default()` stops the default handling of the current event. Only these events support it:
+
+
+Only the following events can prevent default behavior:
+
+ - PersonMessageReceived
+ - GroupMessageReceived
+ - PersonNormalMessageReceived
+ - GroupNormalMessageReceived
+ - PersonCommandSent
+ - GroupCommandSent
+ - NormalMessageResponded
+
+
+Call `event_context.prevent_postorder()` to stop later plugins from handling the current event.
diff --git a/docs/en/plugin/dev/apis/platform.mdx b/docs/en/plugin/dev/apis/platform.mdx
new file mode 100644
index 000000000..40219c03f
--- /dev/null
+++ b/docs/en/plugin/dev/apis/platform.mdx
@@ -0,0 +1,78 @@
+---
+title: "Platform APIs"
+---
+
+Call platform adapter APIs using a bot UUID. Continue using `self.plugin.send_message()` for message chains; use the API below for groups, users, and other platform features.
+
+## Call a platform API
+
+```python
+async def call_platform_api(
+ self,
+ bot_uuid: str,
+ action: str,
+ params: dict[str, Any] | None = None,
+) -> Any:
+ ...
+```
+
+Call through `self.plugin` in Command, EventListener, Tool, and other regular components. Results are serialized dictionaries, lists, scalars, or `None`, depending on the action, rather than platform SDK objects.
+
+```python
+group = await self.plugin.call_platform_api(
+ bot_uuid=bot_uuid,
+ action="get_group_info",
+ params={"group_id": "123456"},
+)
+```
+
+`bot_uuid` comes from `await self.plugin.get_bots()` or `await event_context.get_bot_uuid()` in a Pipeline event. Use platform IDs from real events or platform configuration.
+
+### Common actions
+
+| `action` | `params` |
+| --- | --- |
+| `get_user_info` | `user_id` |
+| `get_friend_list` | `{}` |
+| `get_group_info` | `group_id` |
+| `get_group_list` | `{}` |
+| `get_group_member_list` | `group_id` |
+| `get_group_member_info` | `group_id`, `user_id` |
+| `get_message` / `delete_message` | `chat_type`, `chat_id`, `message_id` |
+| `set_group_name` | `group_id`, `name` |
+| `mute_member` | `group_id`, `user_id`, `duration` |
+| `unmute_member` / `kick_member` | `group_id`, `user_id` |
+| `leave_group` | `group_id` |
+| `approve_friend_request` | `request_id`, `approve`, `remark` |
+| `approve_group_invite` | `request_id`, `approve` |
+| `get_file_url` | `file_id` |
+
+
+Supported actions vary by platform and may require bot administrator permissions. `duration` is in seconds; the meaning of `0` is platform-specific, not a universal permanent mute. Queries may depend on platform caches. Calls raise an exception if the bot is not running, the action is unsupported, or parameters are invalid.
+
+## Platform-specific APIs
+
+Set the outer `action` to `call_platform_api` and put the platform action and parameters inside `params`. For example, read the bot account using OneBot Omni:
+
+```python
+account = await self.plugin.call_platform_api(
+ bot_uuid=bot_uuid,
+ action="call_platform_api",
+ params={"action": "get_login_info", "params": {}},
+)
+```
+
+Only actions declared by the adapter are allowed; this is not unrestricted pass-through to every platform endpoint. Plugins call the Host through the runtime, rather than accessing `ctx.query.adapter` or `adapter.bot`.
+
+## Runner
+
+During Runner execution, model, tool, knowledge-base, storage, and platform calls through `self.plugin` automatically use the current run and its authorization. Do not pass `run_id`. Concurrent runs remain isolated. Do not continue these run-bound calls after the handler returns.
+
+Use `await ctx.get_bot_uuid()` for the current bot. Platform calls must match the tool grants for this invocation. Event-target grants cannot access another target. Ungranted actions, including platform-specific actions, are rejected. These calls also use Mock delivery in debug mode.
+
+```python
+tools = await ctx.get_available_tools()
+if any(tool["name"] == "event_get_actor" for tool in tools):
+ actor = await ctx.call_tool("event_get_actor")
+ await ctx.log(str(actor))
+```
diff --git a/docs/en/plugin/dev/apis/tech-details.mdx b/docs/en/plugin/dev/apis/tech-details.mdx
new file mode 100644
index 000000000..8170205d8
--- /dev/null
+++ b/docs/en/plugin/dev/apis/tech-details.mdx
@@ -0,0 +1,13 @@
+---
+title: "Plugin Technical Details"
+---
+
+## Architecture
+
+
 +
+In version 4.0, we introduced a high-security, high-flexibility production-grade plugin system and provided developers with rich APIs and easy-to-use supporting tools.
+
+Plugin Runtime is used to manage plugin lifecycles and coordinate interactions between LangBot and plugins. It has two operating modes: `stdio` and `websocket`. When LangBot is started directly by users (not running in a container), it uses `stdio` mode, which is common for personal users or lightweight environments. When LangBot runs in a container, it uses `websocket` mode, designed specifically for production environments.
+
+Plugin Runtime automatically starts each installed plugin and interacts through stdio. In plugin development scenarios, developers can use the `lbp` command-line tool to start plugins and connect to the running Runtime via WebSocket for debugging.
diff --git a/docs/en/plugin/dev/basic-info.mdx b/docs/en/plugin/dev/basic-info.mdx
new file mode 100644
index 000000000..baf698641
--- /dev/null
+++ b/docs/en/plugin/dev/basic-info.mdx
@@ -0,0 +1,313 @@
+---
+title: "Completing Plugin Configuration Information"
+---
+
+## Modifying the Manifest File
+
+The `manifest.yaml` file in the plugin directory declares the basic information about the plugin, which will be displayed in the LangBot UI or plugin marketplace interfaces.
+
+```yaml
+apiVersion: v1 # Do not modify
+kind: Plugin # Do not modify
+metadata:
+ author: RockChinQ # Author, must match regex ^[a-zA-Z0-9_-]+$
+ name: HelloPlugin # Plugin name, used to distinguish plugins, must match regex ^[a-zA-Z0-9-]+$
+ repository: 'https://github.com/langbot-app/HelloPlugin' # Plugin repository URL
+ version: 0.1.0 # Plugin version
+ description:
+ en_US: 'Hello LangBot Plugin' # Plugin description, multilingual
+ zh_Hans: 'Hello LangBot Plugin'
+ label:
+ en_US: HelloPlugin # Plugin label, displayed in the interface, multilingual
+ zh_Hans: HelloPlugin
+ icon: assets/icon.svg # Plugin icon, defaults to assets/icon.svg, can be replaced with various image formats
+spec:
+ config: [] # Plugin configuration item format
+ components: {} # Plugin component list, no need to modify manually
+execution:
+ python:
+ path: main.py # Do not modify
+ attr: HelloPlugin # Do not modify
+```
+
+To certify your plugin and let several installations share one runtime, also declare `sharedRuntime` and `componentModel` under `execution`; see [Certified plugins and shared runtime](/en/plugin/certified-plugins).
+
+Plugin multilingual support follows the [RFC 4646](https://datatracker.ietf.org/doc/html/rfc4646) standard. Currently supported languages include:
+
+- `en_US` English (required)
+- `zh_Hans` Simplified Chinese
+- `zh_Hant` Traditional Chinese
+- `ja_JP` Japanese
+- `vi_VN` Vietnamese
+- `th_TH` Thai
+- `es_ES` Spanish
+
+## Plugin Configuration Item Format
+
+In the `manifest.yaml` file, fields declared in `spec.config` will be rendered by LangBot as configuration item forms for users to fill out. Plugins can retrieve user-filled configuration items through APIs provided by the SDK (see later sections).
+
+For example:
+
+```yaml
+spec:
+ config:
+ - name: github_token # Required; configuration item name, used for retrieval in the plugin
+ type: string # Required; configuration item type, supports string, integer, float, boolean, select, prompt-editor, llm-model-selector, bot-selector, tools-selector, etc.
+ label: # Required; configuration item display name, supports multilingual. Language codes follow RFC 4646 standard.
+ en_US: Github Token
+ zh_Hans: Github Token
+ description: # Configuration item description, supports multilingual. Optional.
+ en_US: Image downloading requires a Github token
+ zh_Hans: 如果不填的话,图片可能会下载失败
+ default: '' # Configuration item default value, optional.
+ required: false # Whether the configuration item is required, optional.
+ show_if: # Conditional rendering (shows when conditions are met), optional.
+ field: mode
+ operator: eq
+ value: mode1
+ - name: mode
+ type: select
+ ...
+```
+
+The supported types and fields for configuration items are as follows:
+
+### Conditional Rendering (`show_if`)
+
+All types of configuration items support conditional rendering using the `show_if` field. You can decide whether the current field is rendered based on the value of another field in the same (or an associated) form.
+
+```yaml
+- name: advanced_setting
+ type: string
+ show_if:
+ field: mode # The name of the dependent field
+ operator: eq # The operator, supports 'eq' (equals), 'neq' (not equals), 'in' (in a list)
+ value: advanced # The value to check against
+```
+
+> **Note:** Cross-form cascading relationships (e.g. `creation_schema` values reading from `retrieval_schema` values and vice versa in a Knowledge Engine) are supported in the latest LangBot frontend.
+
+### type: string
+
+String type. Optionally supports `options` for preset values — when provided, a dropdown button appears next to the input allowing users to quickly fill in a preset value. Users can still type freely.
+
+```yaml
+- name: api_key
+ type: string
+ ...
+```
+
+With preset options:
+
+```yaml
+- name: api_url
+ type: string
+ options: # Optional preset values, displayed as a dropdown button next to the input.
+ - name: "https://api.openai.com/v1" # The value to fill in when selected.
+ label: # Display name, supports multilingual.
+ en_US: OpenAI Official
+ zh_Hans: OpenAI 官方
+ - name: "https://api.deepseek.com/v1"
+ label:
+ en_US: DeepSeek
+ zh_Hans: DeepSeek
+ ...
+```
+
+### type: array[string]
+
+String array.
+
+```yaml
+- name: tags
+ type: array[string]
+ ...
+```
+
+### type: integer
+
+Integer type.
+
+```yaml
+- name: progress
+ type: integer
+ ...
+```
+
+### type: float
+
+Float type.
+
+```yaml
+- name: temperature
+ type: float
+ ...
+```
+
+### type: boolean
+
+Boolean type.
+
+```yaml
+- name: is_enabled
+ type: boolean
+ ...
+```
+
+### type: select
+
+Dropdown menu. Requires configuring `options`, which represents the dropdown menu options. Each option displays its `label` as the primary text, with the `name` (value) shown in smaller text below.
+
+```yaml
+- name: mode
+ type: select
+ allow_custom: true
+ options: # Dropdown options, supports multilingual.
+ - name: mode1 # Value, displayed as secondary text in the dropdown.
+ label: # Display name, supports multilingual.
+ en_US: Mode 1
+ zh_Hans: 模式 1
+ - name: mode2
+ label: # Display name, supports multilingual.
+ en_US: Mode 2
+ zh_Hans: 模式 2
+ ...
+```
+
+Set `allow_custom: true` to add a Custom option alongside the presets. A text input appears only when Custom is selected. The saved value is the selected `name` or the custom string, never a Custom marker. This also applies to a runner’s `spec.config`.
+
+### type: prompt-editor
+
+Prompt editor. Displays a prompt editor from the pipeline configuration page, with the final result represented in OpenAI's `messages` format.
+
+```yaml
+- name: prompt
+ type: prompt-editor
+ ...
+```
+
+### type: text
+
+Large text input. Rendered as a textarea in the frontend for user input, and passed to the plugin as a string.
+
+```yaml
+- name: prompt
+ type: text
+ ...
+```
+
+### type: file
+
+File upload. Supports file uploads up to 10MB, passed to the plugin in the format `{"file_key": "xxxxx.xxx", "mimetype": "xxxxx"}`. The plugin can use the `get_config_file` API to retrieve the file content.
+
+```yaml
+- name: config_file
+ type: file
+ accept: 'application/json' # Optional, specify accepted file MIME types
+ ...
+```
+
+Retrieving the file in the plugin:
+
+```python
+# Get file information from config
+file_config = self.get_config()['config_file']
+file_key = file_config['file_key']
+mimetype = file_config['mimetype']
+
+# Example output: {'file_input': {'file_key': 'plugin_config_d2234fd802054faf80babe0679a97fa9.json', 'mimetype': 'application/json'}}
+print(file_config)
+
+# Get file content
+file_bytes = await self.get_config_file(file_key)
+```
+
+
+ Common MIME type and file extension reference: [MDN Documentation](https://developer.mozilla.org/en-US/docs/Web/HTTP/Basics_of_HTTP/MIME_types/Common_types)
+
+
+### type: array[file]
+
+Multiple file upload. Similar to the file type, but supports uploading multiple files, passed to the plugin in the format `[{"file_key": "xxxxx.xxx", "mimetype": "xxxxx"}]`.
+
+```yaml
+- name: resource_files
+ type: array[file]
+ accept: 'image/*' # Optional, specify accepted file MIME types
+ ...
+```
+
+Retrieving files in the plugin:
+
+```python
+# Get file list from config
+files_config = self.get_config()['resource_files']
+
+for file_config in files_config:
+ file_key = file_config['file_key']
+ mimetype = file_config['mimetype']
+
+ # Get file content
+ file_bytes = await self.get_config_file(file_key)
+```
+
+### type: llm-model-selector
+
+LLM model selector. Displays an LLM model selector where you can choose configured LLM models, with the final result represented as the LLM model UUID.
+
+```yaml
+- name: model
+ type: llm-model-selector
+ ...
+```
+
+### type: bot-selector
+
+Bot selector. Displays a Bot selector where you can choose configured Bots, with the final result represented as the Bot UUID.
+
+```yaml
+- name: bot
+ type: bot-selector
+ ...
+```
+
+Using the Bot UUID in the plugin:
+
+```python
+# Get Bot UUID from config
+bot_uuid = self.get_config()['bot']
+print(bot_uuid) # Output: '550e8400-e29b-41d4-a716-446655440000'
+```
+
+### type: tools-selector
+
+Tool selector. Displays a multi-select tool selector where you can choose registered tools (plugin tools and MCP tools), with the final result represented as an array of tool names.
+
+```yaml
+- name: selected_tools
+ type: tools-selector
+ ...
+```
+
+Using the selected tool names in the plugin:
+
+```python
+# Get selected tool names from config
+selected_tools = self.get_config()['selected_tools']
+print(selected_tools) # Output: ['get_weather_alerts', 'web_search']
+
+# Call selected tools
+for tool_name in selected_tools:
+ result = await self.plugin.call_tool(
+ tool_name=tool_name,
+ parameters={"query": "hello"},
+ session={},
+ query_id=0,
+ )
+```
+
+## What's Next
+
+This tutorial will guide you through step-by-step completion of plugin functionality.
+
+- Adding Components: Plugin components are the core functional units of plugins. You can [add components](/en/plugin/dev/components/add) based on your needs.
\ No newline at end of file
diff --git a/docs/en/plugin/dev/components/add.mdx b/docs/en/plugin/dev/components/add.mdx
new file mode 100644
index 000000000..869d1b5f4
--- /dev/null
+++ b/docs/en/plugin/dev/components/add.mdx
@@ -0,0 +1,81 @@
+---
+title: "Adding Components"
+---
+
+Plugins consist of one or more components that provide different functionalities to LangBot. Currently supported component types include:
+
+- Plugin processor (Runner): handles platform events in plugin code after an instance is created and bound. See the [tutorial](/en/plugin/dev/components/runner).
+- Agent runner (Runner): provides execution logic selected in an Agent configuration; it is distinct from a standalone plugin processor.
+- Event Listeners (EventListener): Listen to events during pipeline execution and modify context or pipelines.
+- Commands (Command): Triggered by user command messages starting with `!` (or other configured prefixes).
+- Tools (Tool): Called by LLMs during execution of LangBot's built-in Local Agent.
+- Knowledge Engines (KnowledgeEngine): Provide knowledge base indexing and retrieval capabilities for LangBot, managing document ingestion, retrieval, and deletion.
+- Parsers (Parser): Parse binary files such as PDF, Word, etc. into structured text before document ingestion, for use by Knowledge Engines.
+- Pages (Page): Register custom visual pages in the LangBot WebUI sidebar, providing admin panels, data displays, and interactive interfaces.
+
+## Adding Components
+
+Execute the command in the plugin directory:
+
+```bash
+lbp comp
+```
+
+For example, to add an event listener:
+
+```bash
+lbp comp EventListener
+```
+
+Follow the prompts to enter the component configuration (if any).
+
+```bash
+➜ HelloPlugin > lbp comp EventListener
+Generating component EventListener...
+Component EventListener generated successfully.
+组件 EventListener 生成成功。
+➜ HelloPlugin >
+```
+
+
+The CLI will generate a `components` directory in the plugin directory and create corresponding component directories within it.
+```
+.
+├── assets
+│ └── icon.svg
+├── components
+│ ├── __init__.py
+│ └── event_listener
+│ ├── __init__.py
+│ ├── default.py
+│ └── default.yaml
+├── main.py
+├── manifest.yaml
+├── README.md
+└── requirements.txt
+```
+
+At the same time, component discovery configuration will be added to the plugin's `manifest.yaml`:
+
+```yaml
+...
+components:
+ EventListener:
+ fromDirs:
+ - path: components/event_listener/
+...
+```
+To remove components, you can delete the corresponding information manually.
+
+
+## Component Types
+
+For detailed usage of each component, please refer to:
+
+- [Runner](./runner)
+- [EventListener](./event-listener)
+- [Command](./command)
+- [Tool](./tool)
+- [KnowledgeEngine](./knowledge-engine)
+- [Parser](./parser)
+- [Page](./page)
diff --git a/docs/en/plugin/dev/components/command.mdx b/docs/en/plugin/dev/components/command.mdx
new file mode 100644
index 000000000..f46f5dcfc
--- /dev/null
+++ b/docs/en/plugin/dev/components/command.mdx
@@ -0,0 +1,226 @@
+---
+title: "Component: Command"
+---
+
+Command components are triggered by user command messages starting with `!` (or other configured prefixes). Here's an example of triggering the `!help` command:
+
+
 +
+## Adding Command Components
+
+A single plugin can contain any number of commands. Execute the command `lbp comp Command` in the plugin directory and follow the prompts to enter the command configuration.
+
+```bash
+➜ HelloPlugin > lbp comp Command
+Generating component Command...
+Command name: info
+Command description: Show information of the query
+Component Command generated successfully.
+组件 Command 生成成功。
+```
+
+This will generate `info.yaml` and `info.py` files in the `components/commands/` directory. The `.yaml` file defines the basic information for the `!info` command, and the `.py` file is the command handler:
+
+```bash
+➜ HelloPlugin > tree
+...
+├── components
+│ ├── __init__.py
+│ ├── commands
+│ │ ├── __init__.py
+│ │ ├── info.py
+│ │ └── info.yaml
+...
+```
+
+## Manifest File: Command Component
+
+```yaml
+apiVersion: v1 # Do not modify
+kind: Command # Do not modify
+metadata:
+ name: info # Command name, users will trigger this command with !info
+ label: # Command display name, shown in LangBot UI, supports multilingual
+ en_US: Info
+ zh_Hans: Info
+ description: # Command description, shown in LangBot UI, supports multilingual. Optional.
+ en_US: 'Show information of the query'
+ zh_Hans: '发送此次消息的详细信息'
+spec:
+execution:
+ python:
+ path: info.py # Command handler, do not modify
+ attr: Info # Command handler class name, matches the class name in info.py
+```
+
+## Plugin Processing
+
+The following code is generated by default (`components/command/.py`). You need to register and implement subcommand processing logic in the `initialize` method of the `Info` class.
+
+```python
+# Auto generated by LangBot Plugin SDK.
+# Please refer to https://langbot.app/docs/en/plugin/dev/tutor.html for more details.
+from __future__ import annotations
+
+from typing import Any, AsyncGenerator
+
+from langbot_plugin.api.definition.components.command.command import Command, Subcommand
+from langbot_plugin.api.entities.builtin.command.context import ExecuteContext, CommandReturn
+
+
+class Info(Command):
+
+ async def initialize(self):
+ await super().initialize()
+
+ "Fill with your code here"
+```
+
+Adding subcommands:
+
+```python
+...
+class Info(Command):
+
+ async def initialize(self):
+ await super().initialize()
+
+ @self.subcommand(
+ name="", # Empty string represents root command
+ help="Show information of the query", # Command help information
+ usage="info", # Command usage example, displayed in command help
+ aliases=["i"], # Command aliases
+ )
+ async def send(self, context: ExecuteContext) -> AsyncGenerator[CommandReturn, None]:
+ print(context)
+
+ reply_text = f"Query ID: {context.query_id}\n"
+ reply_text += f"command: {context.command}\n"
+ reply_text += f"command_text: {context.command_text}\n"
+ reply_text += f"params: {context.params}\n"
+ reply_text += f"crt_params: {context.crt_params}\n"
+ reply_text += f"privilege: {context.privilege}\n"
+ reply_text += f"session: {context.session.launcher_type.value}_{context.session.launcher_id}\n"
+
+ yield CommandReturn(
+ text=reply_text,
+ )
+
+ @self.subcommand(
+ name="field",
+ help="Show information of the field",
+ usage="info field",
+ aliases=["f"],
+ )
+ async def field(self, context: ExecuteContext) -> AsyncGenerator[CommandReturn, None]:
+ print(context)
+
+ field_name = context.crt_params[0]
+ field_value = getattr(context, field_name)
+
+ yield CommandReturn(
+ text=f"{field_name}: {field_value}",
+ )
+```
+
+In this code, the `send` function is registered as a subcommand through the `@self.subcommand` decorator, prints the command context (ExecuteContext) information, and concatenates it into a reply message.
+
+### Subcommand Registration
+
+`name` is the subcommand name. Leaving it empty means handling the main command. If not empty, it matches the second parameter as the command. For example:
+
+- `!info` matches the subcommand with name=""
+- `!info field` matches the subcommand with name="field"
+- `!info field value` matches the subcommand with name="field", with `value` as the subcommand parameter
+- Specialy, `name="*"` matches all unmatched first-level subcommands, and passes each section after `info` as parameters, for example `!info 123`, `!info abc`. You can get `['123']` or `['abc']` from `context.crt_params`, depending on the user's input.
+
+In subcommand functions, you can read command parameters through the `context` variable.
+
+The effect of the above command is shown in the image:
+
+
 +
+### Command Context
+
+```python
+
+class ExecuteContext(pydantic.BaseModel):
+ """Single command execution context"""
+
+ query_id: int
+ """Request ID"""
+
+ session: provider_session.Session
+ """Session object for this message"""
+
+ command_text: str
+ """Complete command text"""
+
+ command: str
+ """Command name"""
+
+ crt_command: str
+ """Current command
+
+ In multi-level commands, crt_command is the current command, command is the root command.
+ Example: !plugin on Webwlkr
+ When processing plugin, command is plugin, crt_command is plugin
+ When processing on, command is plugin, crt_command is on
+ """
+
+ params: list[str]
+ """Command parameters
+
+ Parameter list after splitting the entire command by spaces
+ """
+
+ crt_params: list[str]
+ """Current command parameters
+
+ In multi-level commands, crt_params are current command parameters, params are root command parameters.
+ Example: !plugin on Webwlkr
+ When processing plugin, params is ['on', 'Webwlkr'], crt_params is ['on', 'Webwlkr']
+ When processing on, params is ['on', 'Webwlkr'], crt_params is ['Webwlkr']
+ """
+
+ privilege: int
+ """Session privilege level"""
+
+ ...
+```
+
+### Command Return Values
+
+Command return values (CommandReturn) currently support returning text, images (image_url, image links), and errors.
+
+```python
+yield CommandReturn(
+ text=reply_text,
+)
+
+yield CommandReturn(
+ image_url=image_url,
+)
+```
+
+Command processing supports returning multiple messages, so please use `yield` statements to return messages.
+
+For specific return values, please refer to the definition of `CommandReturn`: [langbot_plugin.api.entities.builtin.command.context.CommandReturn](https://github.com/langbot-app/langbot-plugin-sdk/tree/main/src/langbot_plugin/api/entities/builtin/command/context.py)
+
+## One installation, many usages
+
+A single command is triggered **concurrently by several conversations**:
+
+- Read config per call; never read it in `initialize()` and cache it on the instance.
+- Never leave command arguments, return values or conversation data on instance fields or module-level variables; `ExecuteContext` is valid only for the current execution.
+- Concurrent triggering means instance fields get interleaved writes — do not use them to hold "current conversation" style state. Data that must survive calls belongs in Host storage, keyed with the conversation identity.
+- If you keep per-installation process-local caches, release them in `on_installation_revoked(binding)`.
+
+See [Certified plugins and shared runtime](/en/plugin/certified-plugins) for the full specification.
+
+## What's Next
+
+You have learned the basic information about command registration and command execution. Next, you can:
+
+- See the complete [`ExecuteContext` API reference](/en/plugin/dev/apis/agent-run#command).
+- Check out [Plugin Common APIs](/en/plugin/dev/apis/common).
diff --git a/docs/en/plugin/dev/components/event-listener.mdx b/docs/en/plugin/dev/components/event-listener.mdx
new file mode 100644
index 000000000..9fe045ca0
--- /dev/null
+++ b/docs/en/plugin/dev/components/event-listener.mdx
@@ -0,0 +1,119 @@
+---
+title: "Component: Event Listener"
+---
+
+
+This component extends Pipeline processing steps. To handle Bot events such as incoming messages and new group members, see [Event Processor](/en/plugin/dev/components/runner).
+
+
+LangBot's pipeline generates events during runtime for plugins to hook into and process. Each plugin can only have one event listener (components/event_listener/default.yaml), but can register any number of events within it.
+
+## Adding Event Listener Component
+
+Execute the command `lbp comp EventListener` in the plugin directory. Creating an event listener component doesn't require any configuration.
+
+```bash
+➜ HelloPlugin > lbp comp EventListener
+Generating component EventListener...
+Component EventListener generated successfully.
+组件 EventListener 生成成功。
+```
+
+This will generate `default.yaml` and `default.py` files in the `components/event_listener/` directory. The `.yaml` file defines the basic information for the event listener, and the `.py` file is the event listener handler:
+
+```bash
+➜ HelloPlugin > tree
+...
+├── components
+│ ├── __init__.py
+│ └── event_listener
+│ ├── __init__.py
+│ ├── default.py
+│ └── default.yaml
+...
+```
+
+## Manifest File: Event Listener
+
+Since each plugin can only have one event listener, no modifications are needed in the manifest file.
+
+## Plugin Processing
+
+The following code is generated by default (components/event_listener/default.py). You need to register and implement event processing logic in the `initialize` method of the `DefaultEventListener` class.
+
+```python
+# Auto generated by LangBot Plugin SDK.
+# Please refer to https://langbot.app/docs/en/plugin/dev/tutor.html for more details.
+from __future__ import annotations
+
+from langbot_plugin.api.definition.components.common.event_listener import EventListener
+from langbot_plugin.api.entities import events, context
+
+
+class DefaultEventListener(EventListener):
+
+ async def initialize(self):
+ await super().initialize()
+
+ "Fill with your code here"
+```
+
+Adding listeners for specific events:
+
+```python
+...
+class DefaultEventListener(EventListener):
+
+ async def initialize(self):
+ await super().initialize()
+
+ @self.handler(events.PersonMessageReceived)
+ async def handler(event_context: context.EventContext):
+ print("Hello LangBot Plugin!")
+ print(event_context)
+
+ await event_context.reply(
+ platform_message.MessageChain([
+ platform_message.Plain(text=f"Hello from Nahida Plugin!"),
+ ])
+ )
+```
+
+This code registers a listener for the `PersonMessageReceived` (receiving any message from private chat) event, prints the event context (EventContext) information when the event is triggered, and calls the event context API to reply with a message.
+
+EventContext stores common context information for this event trigger, while EventContext.event is an object of PersonMessageReceived (or other corresponding event types), storing detailed information about the event.
+
+```python
+# Summary of EventContext definition
+class EventContext(pydantic.BaseModel):
+ """Event context, stores information for this event execution"""
+ ...
+
+ event: pydantic.SerializeAsAny[BaseEventModel]
+ """Event object, specific type is the type specified when registering the handler, can be found in events.py"""
+
+ ...
+```
+
+## Event Registration
+
+Event registration is implemented through the `@self.handler` decorator, with the decorator parameter being the event type. All monitorable events are defined in `langbot_plugin.api.entities.builtin.events`.
+
+## One installation, many usages
+
+The same event listener is called **concurrently by several Workspaces and several events**:
+
+- Never accumulate state per event on the instance (counters, last event, conversation maps); concurrent callbacks will overwrite each other.
+- A callback takes its data only from the current `EventContext`; never reuse a context or its fields across calls.
+- Data that must survive calls belongs in Host storage, keyed with the installation identity and the event-related identity (Workspace, conversation, and so on).
+- If you keep per-installation process-local state, release it in `on_installation_revoked(binding)`.
+
+See [Certified plugins and shared runtime](/en/plugin/certified-plugins) for the full specification.
+
+## What's Next
+
+You have learned the basic information about event listeners. Next, you can:
+
+- See [Pipeline Events](/en/plugin/dev/apis/pipeline-events) for event types and fields.
+- See the complete [`EventContext` API reference](/en/plugin/dev/apis/agent-run#eventlistener).
+- Check out [Plugin Common APIs](/en/plugin/dev/apis/common)
diff --git a/docs/en/plugin/dev/components/knowledge-engine.mdx b/docs/en/plugin/dev/components/knowledge-engine.mdx
new file mode 100644
index 000000000..901ec2b7b
--- /dev/null
+++ b/docs/en/plugin/dev/components/knowledge-engine.mdx
@@ -0,0 +1,490 @@
+---
+title: "Component: Knowledge Engine"
+---
+
+The Knowledge Engine component allows plugins to provide full knowledge base indexing and retrieval capabilities for LangBot. When users create a knowledge base in LangBot, they can choose a Knowledge Engine provided by a plugin to manage document ingestion, retrieval, and deletion. Plugins can also bridge advanced knowledge base services such as Dify, RAGFlow, FastGPT, and more.
+
+## Adding a Knowledge Engine Component
+
+A single plugin can add any number of Knowledge Engines. Execute the command `lbp comp KnowledgeEngine` in the plugin directory and follow the prompts to enter the Knowledge Engine configuration.
+
+```bash
+➜ MyRAGPlugin > lbp comp KnowledgeEngine
+Generating component KnowledgeEngine...
+Knowledge Engine name: simple_rag
+Knowledge Engine description: A simple Knowledge Engine with built-in chunking and retrieval
+Component KnowledgeEngine generated successfully.
+```
+
+This will generate `simple_rag.yaml` and `simple_rag.py` files in the `components/knowledge_engine/` directory. The `.yaml` file defines the Knowledge Engine's basic information and configuration schemas, and the `.py` file is the handler for this engine:
+
+```bash
+➜ MyRAGPlugin > tree
+...
+├── components
+│ ├── __init__.py
+│ └── knowledge_engine
+│ ├── __init__.py
+│ ├── simple_rag.py
+│ └── simple_rag.yaml
+...
+```
+
+## Manifest File: Knowledge Engine
+
+```yaml
+apiVersion: v1 # Do not modify
+kind: KnowledgeEngine # Do not modify
+metadata:
+ name: simple_rag # Knowledge Engine name, used to identify this engine
+ label:
+ en_US: Simple Knowledge Engine # Engine display name, shown in LangBot's UI, supports multiple languages
+ zh_Hans: 简易 RAG 引擎
+ ja_JP: シンプル RAG エンジン
+ description:
+ en_US: 'A simple Knowledge Engine with built-in chunking and retrieval'
+ zh_Hans: '内置分块和检索能力的简易 RAG 引擎'
+ ja_JP: 'チャンキングと検索を内蔵したシンプルなRAGエンジン'
+spec:
+ creation_schema: # Configuration parameters users fill in when creating a knowledge base
+ - name: chunk_size
+ label:
+ en_US: Chunk Size
+ zh_Hans: 分块大小
+ type: integer
+ required: false
+ default: 500
+ - name: chunk_overlap
+ label:
+ en_US: Chunk Overlap
+ zh_Hans: 分块重叠
+ type: integer
+ required: false
+ default: 50
+ retrieval_schema: # Configurable parameters during retrieval
+ - name: score_threshold
+ label:
+ en_US: Score Threshold
+ zh_Hans: 分数阈值
+ type: float
+ required: false
+ default: 0.5
+execution:
+ python:
+ path: simple_rag.py # Engine handler, do not modify
+ attr: SimpleRag # Class name of the engine handler, consistent with the class name in simple_rag.py
+```
+
+For configuration item format reference, see: [Plugin Manifest Configuration Format](/en/plugin/dev/basic-info)
+
+### creation_schema and retrieval_schema
+
+Unlike the old `KnowledgeRetriever` component which used a single `spec.config`, KnowledgeEngine uses two separate schemas:
+
+- **creation_schema**: Parameters users fill in when creating a knowledge base. These are passed to the plugin via `creation_settings` during ingestion and retrieval.
+- **retrieval_schema**: Parameters users can adjust when querying the knowledge base. These are passed to the plugin via `retrieval_settings`.
+
+## Capability Declaration
+
+KnowledgeEngine can declare its supported capabilities. LangBot uses these capability declarations to determine UI behavior and available operations:
+
+```python
+from langbot_plugin.api.definition.components.knowledge_engine.engine import KnowledgeEngine, KnowledgeEngineCapability
+
+class SimpleRag(KnowledgeEngine):
+
+ @classmethod
+ def get_capabilities(cls) -> list[str]:
+ return [
+ KnowledgeEngineCapability.DOC_INGESTION, # Supports document upload and processing
+ ]
+```
+
+Available capability constants:
+
+| Capability | Description |
+|-----------|-------------|
+| `DOC_INGESTION` | Supports document upload and processing. When declared, LangBot shows a "Documents" tab in the knowledge base details. If the plugin is used to bridge other knowledge base services or does not require users to upload documents, this capability declaration can be omitted. |
+| `DOC_PARSING` | Supports native document parsing (file-to-text extraction). When declared, users can choose to use the Knowledge Engine's built-in parsing when uploading documents, without needing an external [Parser plugin](./parser). If not declared, an external Parser plugin must be installed to upload documents. |
+
+
+Other retrieval behaviors (such as reranking, hybrid search, etc.) are controlled by the plugin's `retrieval_schema` and do not need capability flags.
+
+
+## Plugin Handler
+
+The following code will be generated by default (`components/knowledge_engine/.py`). You need to implement the three core methods: `ingest`, `retrieve`, and `delete_document`. Complete code can be found in the `SimpleKnowledgeEngine` example in [langbot-plugin-demo](https://github.com/langbot-app/langbot-plugin-demo).
+
+```python
+from langbot_plugin.api.definition.components.knowledge_engine.engine import KnowledgeEngine, KnowledgeEngineCapability
+from langbot_plugin.api.entities.builtin.rag.models import (
+ IngestionContext,
+ IngestionResult,
+)
+from langbot_plugin.api.entities.builtin.rag.context import (
+ RetrievalContext,
+ RetrievalResponse,
+ RetrievalResultEntry,
+)
+from langbot_plugin.api.entities.builtin.rag.enums import DocumentStatus
+from langbot_plugin.api.entities.builtin.provider.message import ContentElement
+
+
+class SimpleRag(KnowledgeEngine):
+
+ @classmethod
+ def get_capabilities(cls) -> list[str]:
+ return [KnowledgeEngineCapability.DOC_INGESTION]
+
+ async def on_knowledge_base_create(self, kb_id: str, config: dict) -> None:
+ """Callback when a knowledge base is created, can be used to initialize resources"""
+ pass
+
+ async def on_knowledge_base_delete(self, kb_id: str) -> None:
+ """Callback when a knowledge base is deleted, can be used to clean up resources"""
+ pass
+
+ async def ingest(self, context: IngestionContext) -> IngestionResult:
+ """Ingest a document into the knowledge base"""
+
+ # 1. Get file content
+ file_bytes = await self.plugin.get_knowledge_file_stream(context.file_object.storage_path)
+
+ # 2. Parse document and split into chunks
+ text = file_bytes.decode('utf-8')
+ chunk_size = context.creation_settings.get('chunk_size', 500)
+ chunk_overlap = context.creation_settings.get('chunk_overlap', 50)
+ chunks = self._split_text(text, chunk_size, chunk_overlap)
+
+ # 3. Generate embeddings using host embedding model
+ embedding_model_uuid = context.creation_settings.get('embedding_model_uuid', '')
+ vectors = await self.plugin.invoke_embedding(embedding_model_uuid, chunks)
+
+ # 4. Write to host vector database
+ collection_id = context.get_collection_id()
+ ids = [f"{context.file_object.metadata.document_id}_{i}" for i in range(len(chunks))]
+ metadata = [{"document_id": context.file_object.metadata.document_id, "chunk_index": i, "text": chunks[i]} for i in range(len(chunks))]
+ await self.plugin.vector_upsert(collection_id, vectors, ids, metadata)
+
+ return IngestionResult(
+ document_id=context.file_object.metadata.document_id,
+ status=DocumentStatus.COMPLETED,
+ chunks_created=len(chunks),
+ )
+
+ async def retrieve(self, context: RetrievalContext) -> RetrievalResponse:
+ """Retrieve relevant content from the knowledge base"""
+
+ # 1. Generate query vector
+ embedding_model_uuid = context.creation_settings.get('embedding_model_uuid', '')
+ query_vectors = await self.plugin.invoke_embedding(embedding_model_uuid, [context.query])
+ query_vector = query_vectors[0]
+
+ # 2. Vector search
+ collection_id = context.get_collection_id()
+ results = await self.plugin.vector_search(collection_id, query_vector, top_k=context.retrieval_settings.get('top_k', 5))
+
+ # 3. Convert to retrieval results
+ entries = []
+ for r in results:
+ entry = RetrievalResultEntry(
+ id=r.get('id', ''),
+ content=[ContentElement.from_text(r.get('metadata', {}).get('text', ''))],
+ metadata=r.get('metadata', {}),
+ distance=r.get('score', 0.0),
+ )
+ entries.append(entry)
+
+ return RetrievalResponse(
+ results=entries,
+ total_found=len(entries),
+ metadata={},
+ )
+
+ async def delete_document(self, kb_id: str, document_id: str) -> bool:
+ """Delete a document and its associated data from the knowledge base"""
+ collection_id = kb_id
+ deleted = await self.plugin.vector_delete(collection_id, file_ids=[document_id])
+ return deleted > 0
+```
+
+### Lifecycle Hooks
+
+KnowledgeEngine provides two lifecycle hooks that are called when knowledge bases are created and deleted:
+
+```python
+async def on_knowledge_base_create(self, kb_id: str, config: dict) -> None:
+ """Callback when a knowledge base using this engine is created
+
+ Args:
+ kb_id: Knowledge base UUID
+ config: User-provided configuration (fields from creation_schema)
+ """
+
+async def on_knowledge_base_delete(self, kb_id: str) -> None:
+ """Callback when a knowledge base using this engine is deleted
+
+ Args:
+ kb_id: Knowledge base UUID
+ """
+```
+
+### Document Ingestion
+
+The `ingest` method is called when a user uploads a document to the knowledge base:
+
+```python
+async def ingest(self, context: IngestionContext) -> IngestionResult:
+```
+
+**IngestionContext** contains the following information:
+
+```python
+class IngestionContext(pydantic.BaseModel):
+ file_object: FileObject # File object to ingest
+ knowledge_base_id: str # Target knowledge base ID
+ collection_id: str | None # Vector collection ID (falls back to knowledge_base_id)
+ creation_settings: dict # Configuration from knowledge base creation
+ parsed_content: ParseResult | None # Pre-parsed content from external Parser plugin (if any)
+```
+
+**FileObject** contains file metadata:
+
+```python
+class FileObject(pydantic.BaseModel):
+ metadata: FileMetadata # Contains filename, file_size, mime_type, document_id, knowledge_base_id, etc.
+ storage_path: str # File path in the storage system
+```
+
+**IngestionResult** should return the ingestion result:
+
+```python
+class IngestionResult(pydantic.BaseModel):
+ document_id: str # Document ID
+ status: DocumentStatus # Processing status: COMPLETED / FAILED
+ chunks_created: int = 0 # Number of chunks created
+ error_message: str | None = None # Error message on failure
+ metadata: dict = {} # Additional metadata
+```
+
+### Knowledge Retrieval
+
+The `retrieve` method is called when the knowledge base is queried:
+
+```python
+async def retrieve(self, context: RetrievalContext) -> RetrievalResponse:
+```
+
+**RetrievalContext** contains the following information:
+
+```python
+class RetrievalContext(pydantic.BaseModel):
+ query: str # Query text
+ knowledge_base_id: str | None # Knowledge base ID
+ collection_id: str | None # Vector collection ID
+ retrieval_settings: dict # Retrieval configuration (fields from retrieval_schema)
+ creation_settings: dict # Knowledge base creation configuration
+ filters: dict # Metadata filter conditions (Chroma-style where syntax)
+```
+
+
+The LangBot host automatically injects a default `top_k` value (default 5) into `retrieval_settings` before passing it to the plugin. Plugins can access it via `context.retrieval_settings.get('top_k', 5)`.
+
+The `filters` field contains Chroma-style `where` filter conditions extracted from `retrieval_settings`. When the caller provides `filters` in the retrieval settings (e.g., filtering by time range, file type, or custom metadata fields), the host populates this field so plugins can apply them during retrieval. If no filters are provided, this field is an empty dict.
+
+
+**RetrievalResponse** should return the retrieval results:
+
+```python
+class RetrievalResponse(pydantic.BaseModel):
+ results: list[RetrievalResultEntry] # List of retrieval results
+ total_found: int # Total number of matches
+ metadata: dict # Additional metadata
+```
+
+**RetrievalResultEntry** represents a single retrieval result:
+
+```python
+class RetrievalResultEntry(pydantic.BaseModel):
+ id: str # Result ID
+ content: list[ContentElement] # Content, create using ContentElement.from_text()
+ metadata: dict # Metadata
+ distance: float # Distance score (smaller is more relevant)
+ score: float | None = None # Similarity score (larger is more relevant)
+```
+
+### Document Deletion
+
+The `delete_document` method is called when a user deletes a document from the knowledge base:
+
+```python
+async def delete_document(self, kb_id: str, document_id: str) -> bool:
+ """Delete a document and its associated data
+
+ Args:
+ kb_id: Knowledge base ID
+ document_id: Document ID
+
+ Returns:
+ Whether the deletion was successful
+ """
+```
+
+## Host RAG APIs
+
+KnowledgeEngine components can call LangBot host-provided RAG APIs via `self.plugin`, including embedding model invocation, vector database operations, and file retrieval.
+
+### Invoke Embedding Model
+
+```python
+async def invoke_embedding(
+ self,
+ embedding_model_uuid: str,
+ texts: list[str],
+) -> list[list[float]]:
+ """Generate embeddings using host's embedding model
+
+ Args:
+ embedding_model_uuid: Embedding model UUID
+ texts: List of texts to embed
+
+ Returns:
+ List of embedding vectors, one per input text
+ """
+
+# Usage example
+vectors = await self.plugin.invoke_embedding("model_uuid", ["Hello", "World"])
+```
+
+### Vector Upsert
+
+```python
+async def vector_upsert(
+ self,
+ collection_id: str,
+ vectors: list[list[float]],
+ ids: list[str],
+ metadata: list[dict] | None = None,
+) -> None:
+ """Upsert vectors to host's vector database
+
+ Args:
+ collection_id: Target collection ID
+ vectors: List of vectors
+ ids: List of unique IDs for vectors
+ metadata: Optional list of metadata dicts
+ """
+
+# Usage example
+await self.plugin.vector_upsert(
+ collection_id="kb_uuid",
+ vectors=[[0.1, 0.2, ...], [0.3, 0.4, ...]],
+ ids=["chunk_0", "chunk_1"],
+ metadata=[{"document_id": "doc1"}, {"document_id": "doc1"}],
+)
+```
+
+### Vector Search
+
+```python
+async def vector_search(
+ self,
+ collection_id: str,
+ query_vector: list[float],
+ top_k: int = 5,
+ filters: dict | None = None,
+) -> list[dict]:
+ """Search similar vectors in host's vector database
+
+ Args:
+ collection_id: Target collection ID
+ query_vector: Query vector for similarity search
+ top_k: Number of results to return
+ filters: Optional metadata filters
+
+ Returns:
+ List of search results (dict with id, score, metadata, etc.)
+ """
+
+# Usage example
+results = await self.plugin.vector_search(
+ collection_id="kb_uuid",
+ query_vector=[0.1, 0.2, ...],
+ top_k=5,
+)
+# Return format: [{"id": "chunk_0", "score": 0.123, "metadata": {"document_id": "doc1", ...}}, ...]
+```
+
+
+Each result returned by `vector_search` is a dict containing `id` (vector ID), `score` (distance score), and `metadata` (metadata provided during upsert). If you need text content in retrieval results, store the text in metadata during ingestion.
+
+
+### Vector Delete
+
+```python
+async def vector_delete(
+ self,
+ collection_id: str,
+ file_ids: list[str] | None = None,
+ filters: dict | None = None,
+) -> int:
+ """Delete vectors from host's vector database
+
+ Args:
+ collection_id: Target collection ID
+ file_ids: File IDs whose vectors should be deleted
+ filters: Optional metadata filters for deletion
+
+ Returns:
+ Number of deleted items
+ """
+
+# Usage example
+deleted = await self.plugin.vector_delete(
+ collection_id="kb_uuid",
+ file_ids=["doc_001"],
+)
+```
+
+
+The `filters` parameter supports Chroma-style `where` syntax for metadata filtering. Multiple top-level keys are AND-ed. Supported operators: `$eq`, `$ne`, `$gt`, `$gte`, `$lt`, `$lte`, `$in`, `$nin`. Example: `{"file_id": {"$eq": "abc"}}`.
+
+**Note:** Chroma, Qdrant, and SeekDB store full metadata and can filter on any field. Milvus and pgvector only store `text`, `file_id`, and `chunk_uuid` — filters on other fields will be silently ignored.
+
+
+```python
+async def get_knowledge_file_stream(self, storage_path: str) -> bytes:
+ """Get file content from host storage
+
+ Args:
+ storage_path: File storage path (from FileObject.storage_path)
+
+ Returns:
+ File content as bytes
+ """
+
+# Usage example
+file_bytes = await self.plugin.get_knowledge_file_stream(context.file_object.storage_path)
+```
+
+## One installation, many usages
+
+A single knowledge engine is used by **several knowledge bases** at once, and the platform storage key `(instance, Workspace, owner type, plugin, key)` carries no knowledge-base dimension:
+
+- Persistence and cache keys must include the **knowledge-base ID**, otherwise vectors and document state of different knowledge bases overwrite each other.
+- Locks and reconciliation state must be keyed by `(installation, knowledge base)`; **a failure while ingesting one knowledge base must not block ingestion or retrieval of the others under the same installation**.
+- Only a dispatched mutation with an unknown outcome should enter a state that needs manual reconciliation; deterministic validation errors and pre-dispatch cancellation must not affect later calls.
+- Telemetry and diagnostic failures must not affect the work: never let a log or report failure interrupt ingestion or retrieval, and never write tenant data into a process-wide singleton.
+- If you keep per-installation process-local caches or state, release them in `on_installation_revoked(binding)`.
+
+See [Certified plugins and shared runtime](/en/plugin/certified-plugins) for the full specification.
+
+## Testing the Knowledge Engine
+
+After creation, execute the command `lbp run` in the plugin directory to start debugging. Then in LangBot:
+
+1. Go to the "Knowledge Base" page
+2. Click "Create Knowledge Base"
+3. Select the Knowledge Engine provided by your plugin and fill in the configuration based on the engine's `creation_schema`
+4. After creation, upload documents to test ingestion capabilities (if the engine declares `DOC_INGESTION` capability)
+5. Bind the knowledge base to a pipeline and test retrieval capabilities
diff --git a/docs/en/plugin/dev/components/knowledge-retriever.mdx b/docs/en/plugin/dev/components/knowledge-retriever.mdx
new file mode 100644
index 000000000..4f0c598d6
--- /dev/null
+++ b/docs/en/plugin/dev/components/knowledge-retriever.mdx
@@ -0,0 +1,278 @@
+---
+title: "Component: Knowledge Retriever"
+---
+
+The Knowledge Retriever component allows plugins to provide external knowledge base retrieval capabilities for LangBot. When users create an external knowledge base in LangBot, they can choose a knowledge retriever provided by a plugin to retrieve knowledge.
+
+
 +
+## Adding a Knowledge Retriever Component
+
+A single plugin can add any number of knowledge retrievers. Execute the command `lbp comp KnowledgeRetriever` in the plugin directory and follow the prompts to enter the knowledge retriever configuration.
+
+```bash
+➜ FastGPTRetriever > lbp comp KnowledgeRetriever
+Generating component KnowledgeRetriever...
+KnowledgeRetriever name: fastgpt
+KnowledgeRetriever description: Retrieve knowledge from FastGPT knowledge bases
+Component KnowledgeRetriever generated successfully.
+```
+
+This will generate `fastgpt.yaml` and `fastgpt.py` files in the `components/knowledge_retriever/` directory. The `.yaml` file defines the basic information and configuration parameters of the knowledge retriever, and the `.py` file is the handler for this retriever:
+
+```bash
+➜ FastGPTRetriever > tree
+...
+├── components
+│ ├── __init__.py
+│ └── knowledge_retriever
+│ ├── __init__.py
+│ ├── fastgpt.py
+│ └── fastgpt.yaml
+...
+```
+
+## Manifest File: Knowledge Retriever
+
+```yaml
+apiVersion: v1 # Do not modify
+kind: KnowledgeRetriever # Do not modify
+metadata:
+ name: fastgpt # Knowledge retriever name, used to identify this retriever
+ label:
+ en_US: FastGPT Knowledge Base # Retriever display name, shown in LangBot's UI, supports multiple languages
+ zh_Hans: FastGPT 知识库
+ ja_JP: FastGPT ナレッジベース
+ description:
+ en_US: 'Retrieve knowledge from FastGPT knowledge bases' # Retriever description, shown in LangBot's UI, supports multiple languages. Optional
+ zh_Hans: '从 FastGPT 知识库中检索知识'
+ ja_JP: 'FastGPT ナレッジベースから知識を取得'
+ icon: assets/icon.svg # Retriever icon, displayed on the external knowledge base configuration page
+spec:
+ config: # Retriever configuration parameters, users need to fill in these parameters when creating an external knowledge base
+ - name: api_base_url # Parameter name
+ type: string # Parameter type: string, number, boolean, select
+ label:
+ en_US: API Base URL
+ zh_Hans: API 基础地址
+ ja_JP: API ベース URL
+ description:
+ en_US: 'Base URL for FastGPT API'
+ zh_Hans: 'FastGPT API 基础地址'
+ ja_JP: 'FastGPT API ベース URL'
+ default: 'http://localhost:3000' # Default parameter value
+ required: true # Whether required
+ - name: api_key
+ type: string
+ label:
+ en_US: FastGPT API Key
+ zh_Hans: FastGPT API Key
+ ja_JP: FastGPT API キー
+ description:
+ en_US: 'API key from your FastGPT instance'
+ zh_Hans: '从您的 FastGPT 实例获取的 API Key'
+ ja_JP: 'FastGPT インスタンスから取得した API Key'
+ default: ''
+ required: true
+ - name: search_mode # Example of select type parameter
+ type: select
+ label:
+ en_US: Search Mode
+ zh_Hans: 搜索模式
+ ja_JP: 検索モード
+ description:
+ en_US: 'The search method to use'
+ zh_Hans: '使用的搜索方法'
+ ja_JP: '使用する検索方法'
+ default: 'embedding'
+ options: # Select type parameters need to define an option list
+ - name: 'embedding'
+ label:
+ en_US: 'Embedding Search'
+ zh_Hans: '向量搜索'
+ ja_JP: '埋め込み検索'
+ - name: 'fullTextRecall'
+ label:
+ en_US: 'Full-Text Recall'
+ zh_Hans: '全文检索'
+ ja_JP: '全文検索'
+ - name: using_rerank # Example of boolean type parameter
+ type: boolean
+ label:
+ en_US: Use Re-ranking
+ zh_Hans: 使用重排序
+ ja_JP: リランキングを使用
+ description:
+ en_US: 'Whether to use re-ranking'
+ zh_Hans: '是否使用重排序'
+ ja_JP: 'リランキングを使用するかどうか'
+ default: false
+ required: false
+execution:
+ python:
+ path: fastgpt.py # Retriever handler, do not modify
+ attr: FastGPT # Class name of the retriever handler, consistent with the class name in fastgpt.py
+```
+
+For configuration item format reference, see: [Plugin Manifest Configuration Format](/en/plugin/dev/basic-info)
+
+## Plugin Handler
+
+The following code will be generated by default (`components/knowledge_retriever/.py`). You need to implement the knowledge retrieval logic in the `retrieve` method of the `FastGPT` class. Complete code can be found in [langbot-plugin-demo](https://github.com/langbot-app/langbot-plugin-demo).
+
+```python
+# Auto generated by LangBot Plugin SDK.
+# Please refer to https://langbot.app/docs/en/plugin/dev/tutor.html for more details.
+...
+
+class FastGPT(KnowledgeRetriever):
+
+ async def retrieve(self, context: RetrievalContext) -> list[RetrievalResultEntry]:
+ """Retrieve knowledge from FastGPT knowledge base"""
+
+ # 1. Get configuration parameters
+ api_base_url = self.config.get('api_base_url', 'http://localhost:3000')
+ api_key = self.config.get('api_key')
+ dataset_id = self.config.get('dataset_id')
+ search_mode = self.config.get('search_mode', 'embedding')
+ using_rerank = self.config.get('using_rerank', False)
+
+ # 2. Parameter validation
+ if not api_key or not dataset_id:
+ logger.error("Missing required configuration: api_key or dataset_id")
+ return []
+
+ # 3. Build API request
+ url = f"{api_base_url.rstrip('/')}/api/core/dataset/searchTest"
+ headers = {
+ "Authorization": f"Bearer {api_key}",
+ "Content-Type": "application/json"
+ }
+ payload = {
+ "datasetId": dataset_id,
+ "text": context.query, # Get query text from RetrievalContext
+ "searchMode": search_mode,
+ "usingReRank": using_rerank,
+ }
+
+ try:
+ # 4. Call external API
+ async with httpx.AsyncClient() as client:
+ response = await client.post(url, json=payload, headers=headers, timeout=30.0)
+ response.raise_for_status()
+ result = response.json()
+
+ # 5. Parse response and convert to RetrievalResultEntry
+ results = []
+ for record in result.get('data', []):
+ # Combine main data and auxiliary data as content
+ content_text = '\n'.join([
+ record.get('q', ''),
+ record.get('a', '')
+ ]).strip()
+
+ # Create retrieval result entry
+ entry = RetrievalResultEntry(
+ id=record.get('id', ''),
+ content=[ContentElement.from_text(content_text)],
+ metadata={
+ 'dataset_id': record.get('datasetId', ''),
+ 'source_name': record.get('sourceName', ''),
+ 'score': record.get('score', 0.0),
+ },
+ # Convert similarity score to distance (higher score = smaller distance)
+ distance=1.0 - float(record.get('score', 0.0)),
+ )
+ results.append(entry)
+
+ logger.info(f"Retrieved {len(results)} chunks from FastGPT dataset {dataset_id}")
+ return results
+
+ except httpx.HTTPStatusError as e:
+ logger.error(f"HTTP error from FastGPT API: {e.response.status_code} - {e.response.text}")
+ return []
+ except httpx.RequestError as e:
+ logger.error(f"Request error when calling FastGPT API: {str(e)}")
+ return []
+ except Exception as e:
+ traceback.print_exc()
+ logger.error(f"Unexpected error during retrieval: {str(e)}")
+ return []
+```
+
+### Retrieval Context
+
+`RetrievalContext` contains context information for this retrieval:
+
+```python
+class RetrievalContext(pydantic.BaseModel):
+ """Knowledge retrieval context"""
+
+ query: str
+ """Query text, the user's retrieval question"""
+```
+
+### Retrieval Results
+
+Retrieval results need to be converted to a list of `RetrievalResultEntry` objects, each representing a retrieved knowledge chunk:
+
+```python
+class RetrievalResultEntry(pydantic.BaseModel):
+ """Single retrieval result entry"""
+
+ id: str
+ """Result ID, uniquely identifies this entry"""
+
+ content: list[ContentElement]
+ """Result content, create text content using ContentElement.from_text()"""
+
+ metadata: dict[str, Any]
+ """Result metadata, can contain any key-value pairs, such as source, score, etc."""
+
+ distance: float
+ """Distance score, indicates relevance to the query (smaller is more relevant)
+ Usually calculated as 1.0 - similarity_score"""
+```
+
+### Getting Configuration Parameters
+
+Get user-configured parameter values using `self.config.get(parameter_name, default_value)`:
+
+```python
+# Get string parameter
+api_base_url = self.config.get('api_base_url', 'http://localhost:3000')
+
+# Get number parameters
+limit = self.config.get('limit', 5000)
+similarity = self.config.get('similarity', 0.0)
+
+# Get boolean parameter
+using_rerank = self.config.get('using_rerank', False)
+
+# Get select parameter
+search_mode = self.config.get('search_mode', 'embedding')
+```
+
+## One installation, many usages
+
+A single knowledge retriever is used by **several knowledge bases**, and the platform storage key `(instance, Workspace, owner type, plugin, key)` carries no knowledge-base dimension:
+
+- Any cache, index or intermediate result used for retrieval must be isolated by **knowledge-base ID**, with the ID in the key; never keep it on the instance.
+- Key retrieval locks and reconciliation state by `(installation, knowledge base)`; a retrieval failure in one knowledge base must not make retrieval unavailable for the others under the same installation.
+- `RetrievalContext` is valid only for a single retrieval; never store it or its results on instance fields for reuse across calls.
+- Knowledge-base data that must survive calls belongs in Host storage, with a key that includes both the installation identity and the knowledge-base ID.
+- If you cache connections, indexes or any other process-local state per installation, release them in `on_installation_revoked(binding)`.
+
+See [Certified plugins and shared runtime](/en/plugin/certified-plugins) for the full specification.
+
+## Testing the Retriever
+
+After creation, execute the command `lbp run` in the plugin directory to start debugging. Then in LangBot:
+
+1. Go to the "Knowledge Base" page
+2. Add an external knowledge base
+3. Select the knowledge retriever provided by your plugin and fill in the configuration
+
+
 +
+After saving, you can select this knowledge base in the LangBot pipeline.
diff --git a/docs/en/plugin/dev/components/page.mdx b/docs/en/plugin/dev/components/page.mdx
new file mode 100644
index 000000000..1b1349842
--- /dev/null
+++ b/docs/en/plugin/dev/components/page.mdx
@@ -0,0 +1,255 @@
+---
+title: "Component: Page"
+---
+
+The Page component allows plugins to register custom visual pages in the LangBot WebUI sidebar. Pages run inside an iframe sandbox, communicate with the host via the Page SDK, and can call the plugin's backend API.
+
+## Use Cases
+
+- **Admin panels**: Provide visual configuration and data management interfaces (e.g., FAQ management, analytics dashboards)
+- **Data displays**: Show runtime statistics, logs, charts, etc.
+- **Interactive tools**: Provide forms, editors, and other interactive interfaces
+
+
 +
+## Adding a Page Component
+
+Run the following command in the plugin directory:
+
+```bash
+lbp comp Page
+```
+
+After entering the page name, the CLI will generate page files under `components/pages/`:
+
+```bash
+├── components
+│ └── pages
+│ └── dashboard
+│ ├── dashboard.yaml # Page manifest
+│ ├── dashboard.py # Backend handler
+│ ├── index.html # Page entry point
+│ └── i18n # Translation files (optional)
+│ ├── en_US.json
+│ └── zh_Hans.json
+```
+
+The plugin's `manifest.yaml` will also be updated with the component discovery config:
+
+```yaml
+spec:
+ components:
+ Page:
+ fromDirs:
+ - path: components/pages/
+ maxDepth: 2
+```
+
+## Manifest File: Page
+
+```yaml
+apiVersion: v1 # Do not modify
+kind: Page # Do not modify
+metadata:
+ name: dashboard # Unique page ID within the plugin
+ label:
+ en_US: Dashboard # Display name shown in the WebUI sidebar, supports i18n
+ zh_Hans: 仪表盘
+spec:
+ path: index.html # HTML entry file, relative to this YAML file's directory
+execution:
+ python:
+ path: dashboard.py # Backend handler file
+ attr: DashboardPage # Handler class name
+```
+
+## Backend Handler
+
+The Page component's backend handler extends the `Page` base class and implements `handle_api` to process API requests from the frontend page.
+
+```python
+from langbot_plugin.api.definition.components.page import Page, PageRequest, PageResponse
+
+
+class DashboardPage(Page):
+
+ async def handle_api(self, request: PageRequest) -> PageResponse:
+ # request.endpoint: API endpoint path, e.g. '/stats'
+ # request.method: HTTP method (GET, POST, PUT, DELETE)
+ # request.body: Request body (parsed JSON, or None)
+
+ if request.endpoint == '/stats' and request.method == 'GET':
+ # Read installation-scoped data from a Host storage API.
+ entries = await self.load_entries_for_current_installation()
+ return PageResponse.ok({'total': len(entries)})
+
+ return PageResponse.fail(f'Unknown endpoint: {request.endpoint}')
+```
+
+### PageRequest Fields
+
+| Field | Type | Description |
+|-------|------|-------------|
+| `endpoint` | `str` | API endpoint path (e.g. `'/entries'`) |
+| `method` | `str` | HTTP method (`GET`, `POST`, `PUT`, `DELETE`) |
+| `body` | `Any` | Request body (parsed JSON, or `None`) |
+
+### PageResponse Construction
+
+| Method | Description |
+|--------|-------------|
+| `PageResponse.ok(data)` | Success response. `data` can be any JSON-serializable value |
+| `PageResponse.fail(error)` | Error response. `error` is a human-readable error string |
+
+## Frontend Page Development
+
+Include the Page SDK in your HTML file to communicate with the plugin backend:
+
+```html
+
+
+
+
+
+
+
+
Dashboard
+
+
+
+
+
+
+```
+
+### Page SDK API
+
+| Method | Description |
+|--------|-------------|
+| `langbot.onReady(callback)` | Fires when SDK is ready. `callback` receives `ctx` with `theme` and `language` |
+| `langbot.api(endpoint, body?, method?)` | Calls the plugin's `handle_api`. Returns a Promise |
+| `langbot.t(key, fallback?)` | Gets a translated string |
+| `langbot.onThemeChange(callback)` | Fires when the theme changes |
+| `langbot.onLanguageChange(callback)` | Fires when the language changes |
+| `langbot.applyI18n()` | Manually re-apply `data-i18n` translations |
+
+### Dark Mode
+
+The SDK automatically sets CSS custom properties on the page. Use them directly:
+
+| CSS Variable | Purpose |
+|-------------|---------|
+| `--langbot-bg` | Page background |
+| `--langbot-bg-card` | Card background |
+| `--langbot-text` | Primary text color |
+| `--langbot-text-muted` | Secondary text color |
+| `--langbot-border` | Border color |
+| `--langbot-accent` | Accent color |
+
+### Page i18n
+
+Create an `i18n/` directory inside your page directory with JSON translation files:
+
+```
+pages/dashboard/
+├── index.html
+└── i18n/
+ ├── en_US.json
+ └── zh_Hans.json
+```
+
+Translation files are flat JSON key-value pairs:
+
+```json
+{
+ "title": "Dashboard",
+ "totalEntries": "Total Entries"
+}
+```
+
+Add the `data-i18n` attribute to HTML elements for automatic translation:
+
+```html
+Dashboard
+```
+
+## Full Example: FAQ Manager
+
+Here is a complete Page component example that implements CRUD operations for FAQ entries.
+
+**Backend handler** (`components/pages/manager/manager.py`):
+
+```python
+from langbot_plugin.api.definition.components.page import Page, PageRequest, PageResponse
+
+
+class ManagerPage(Page):
+
+ async def handle_api(self, request: PageRequest) -> PageResponse:
+ if request.endpoint == '/entries' and request.method == 'GET':
+ entries = await self.load_entries_for_current_installation()
+ return PageResponse.ok({'entries': entries})
+
+ if request.endpoint == '/entries' and request.method == 'POST':
+ question = (request.body or {}).get('question', '').strip()
+ answer = (request.body or {}).get('answer', '').strip()
+ if not question or not answer:
+ return PageResponse.fail('question and answer are required')
+ entry = {'question': question, 'answer': answer}
+ await self.save_entry_for_current_installation(entry)
+ return PageResponse.ok({'entry': entry})
+
+ if request.endpoint == '/entries' and request.method == 'DELETE':
+ entry_id = (request.body or {}).get('id', '')
+ if await self.delete_entry_for_current_installation(entry_id):
+ return PageResponse.ok({'deleted': entry_id})
+ return PageResponse.fail('entry not found')
+
+ return PageResponse.fail(f'Unknown: {request.method} {request.endpoint}')
+```
+
+**Frontend page** (`components/pages/manager/index.html`) calls the backend via `langbot.api()`:
+
+```javascript
+// Load entries
+var data = await langbot.api('/entries', null, 'GET');
+
+// Add entry
+await langbot.api('/entries', { question: '...', answer: '...' }, 'POST');
+
+// Delete entry
+await langbot.api('/entries', { id: '...' }, 'DELETE');
+```
+
+Full example code is available at [FAQManager plugin](https://github.com/langbot-app/langbot-plugin-demo/tree/main/FAQManager).
+
+## One installation, many usages
+
+The same Page is called by **many page requests** (different requests and different Workspaces under one installation):
+
+- Never leave the previous request's data on the instance; take the endpoint, method, body and current installation information from the current `PageRequest` / binding every time.
+- Page data always lives in installation-scoped Host storage; `self.plugin` is a process-level shared object and must not hold tenant data.
+- Requests from different Workspaces share the same Page instance, so instance fields get interleaved; data that must survive requests belongs in Host storage.
+- If you keep per-installation process-local caches, release them in `on_installation_revoked(binding)`.
+
+See [Certified plugins and shared runtime](/en/plugin/certified-plugins) for the full specification.
+
+## Notes
+
+- Pages run inside a `sandbox="allow-scripts allow-forms"` iframe and cannot open popups or navigate the parent page
+- Certified Pages must keep tenant data in installation-scoped Host storage. `self.plugin` is process-wide and must not hold tenant entries. The storage helper names above are illustrative; use the current SDK Host storage APIs available to your component.
+- Use `PageResponse.ok()` and `PageResponse.fail()` to construct responses for consistent formatting
+- The Page SDK `
+```
+
+
+The embed code URL defaults to `localhost`. If your LangBot is deployed on a server, replace `localhost:5300` with your actual address.
+
+
+## Anti-Abuse (Optional)
+
+To protect against abuse, you can enable Cloudflare Turnstile:
+
+1. Go to [Cloudflare Turnstile](https://dash.cloudflare.com/) > Add Site
+2. Get the **Site Key** and **Secret Key**
+3. Fill them into the corresponding fields in the LangBot Web Page Bot configuration
+4. Save to take effect
+
+## Local Preview / Demo
+
+Want to try the embed widget before wiring it into your own site? The LangBot
+main repo ships a self-contained single-file demo page `index.html` under
+[`examples/web-page-bot/`](https://github.com/langbot-app/LangBot/tree/master/examples/web-page-bot):
+open it in a browser, fill in your LangBot address and Page Bot UUID, and it
+loads the live embed widget so you can chat with the bot just like a site
+visitor — and generates the exact `
+
+
+